Skip to content · ⁨본문 바로가기⁩

Exploring One-Variable Data · ⁨단변량 데이터 탐색⁩

AP Statistics · ⁨AP 통계학⁩ · Topic 1 · ⁨주제 1⁩

Video lesson for this topic · ⁨이 주제용 영상 수업⁩ Open the video page · ⁨영상 페이지 열기⁩
9:03

단변량 데이터 탐색

같은 것을 20번 측정하면 20번相同的答案을 얻지 못합니다. 20명의 학생들이 같은 탁자를 측정합니다. 값들이 달라집니다. 그것은 …이 아닙니다.

English narration · English + 中文 subtitles burned in · ⁨영어 내레이션 · 영어 + 중국어 자막 burned-in⁩

1.1

Introducing Statistics: What Can We Learn from Data? · ⁨통계 소개: 데이터를 통해 무엇을 알 수 있는가?⁩

Syllabus
English

Enduring Understanding (VAR-1): Given that variation may be random or not, conclusions are uncertain.

Learning Objective VAR-1.A: Identify questions to be answered, based on variation in one-variable data. [Skill 1.A]

  • VAR-1.A.1 Numbers may convey meaningful information, when placed in context.
한국어

지속적 이해 (VAR-1): 변동성이 우연일 수도 있고 그렇지 않을 수도 있으므로, 결론은 불확실할 수 있다.

학습 목표 VAR-1.A: 단변량 데이터의 변동성을 기반으로 답해야 할 질문을 식별하시오. [Skill 1.A]

  • VAR-1.A.1 숫자는 맥락 속에 놓일 때 의미 있는 정보를 전달할 수 있다.
Source: College Board AP Course and Exam Description · ⁨출처: College Board AP Course and Exam Description⁩

English

Statistics 统计学 is the science of learning from data 数据 – numbers or labels collected from the real world. Data vary, so we describe patterns and account for the variation 变异 rather than expecting every value to match. A statistical question anticipates an answer based on data that vary.

Two distinctions run through the whole course. A parameter 参数 is a numerical summary of a whole population; a statistic 统计量 is a numerical summary of a sample - we use the statistic to estimate the parameter we cannot measure directly. And descriptive statistics 描述统计 only summarise the data set in hand, while inferential statistics 推断统计 use a sample to make and test claims about the larger population.

한국어

통계학은 현실 세계에서 수집한 데이터—숫자나 레이블—로부터 지식을 얻는 학문입니다. 데이터는 변동성을 가지므로, 모든 값이 일치하기를 기대하기보다 패턴을 서술하고 변동성을 고려해야 합니다. 통계학적 질문은 변동성을 가진 데이터에 기반하여 답을 예상합니다.

전 과정에 걸쳐 두 가지 구분이 존재합니다. 모수는 전체 집단의 수치적 요약이며, 통계량은 표본의 수치적 요약입니다. 직접 측정할 수 없는 모수를 추정하기 위해 통계량을 사용합니다. 또한 기술 통계는 현재数据处理 dataset만 요약하는 반면, 추론 통계는 표본을 사용하여 더 큰 집단에 대한 주장을 MADE하고 검증합니다.

Vocabulary · ⁨어휘⁩ Train · ⁨연습하기⁩
English 한국어
data/ˈdeɪtə/ 데이터
variation/ˌveərɪˈeɪʃn/ 변화
parameter/pəˈræmɪtə/ 파라미터
1.2

The Language of Variation: Variables · ⁨변동성의 언어: 변수⁩

Syllabus
English

Enduring Understanding (VAR-1): Given that variation may be random or not, conclusions are uncertain.

Learning Objective VAR-1.B: Identify variables in a set of data. [Skill 2.A]

  • VAR-1.B.1 A variable is a characteristic that changes from one individual to another.

Learning Objective VAR-1.C: Classify types of variables. [Skill 2.A]

  • VAR-1.C.1 A categorical variable takes on values that are category names or group labels.
  • VAR-1.C.2 A quantitative variable is one that takes on numerical values for a measured or counted quantity.
    • Illustrative examples for VAR-1.C:
      • Categorical variables:
        • Dominant hand
        • Age group (young or old)
        • Highest degree earned
      • Quantitative variables:
        • Age of a structure
        • Height of a child
        • Concentration of a sample
한국어

지속적 이해 (VAR-1): 변동성이 우연일 수도 있고 그렇지 않을 수도 있으므로, 결론은 불확실할 수 있다.

학습 목표 VAR-1.B: 데이터 세트 내의 변수를 식별하시오. [Skill 2.A]

  • VAR-1.B.1 변수는 한 개인에서 다른 개인으로 달라지는 특성이다.

학습 목표 VAR-1.C: 변수의 유형을 분류하시오. [Skill 2.A]

  • VAR-1.C.1 범주형 변수(categorical variable)는 범주 명칭이나 그룹 라벨을 값으로 가진다.
  • VAR-1.C.2 정량 변수(quantitative variable)는 측정되거나 세어진 양의 수치적 값을 가지는 변수이다.
    • *VAR-1.C에 대한 예시:
      • 범주형 변수:
        • 우향(우손)
        • 연령 그룹 (어른 또는 노인)
        • 취득한 최고 학위
      • 정량 변수:
        • 구조물의 나이나 수명
        • 아이의 키
        • 시료의 농도

Source: College Board AP Course and Exam Description · ⁨출처: College Board AP Course and Exam Description⁩

English

A variable 变量 is a characteristic that can differ between individuals. Two kinds:

  • Categorical 分类 (qualitative): values are labels/groups (eye colour, brand).
  • Quantitative 定量: values are numbers you can do arithmetic on (height, age). Quantitative variables are discrete (countable) or continuous (measured).

Choosing the right graph and summary depends on which kind you have.

한국어

변수는 개인 간에 차이날 수 있는 특성입니다. 두 가지 유형:

  • 분류형(질적): 값은 레이블/그룹입니다(눈 색, 브랜드).
  • 정량형: 값은 산술 연산을 할 수 있는 숫자입니다(신장, 나이). 정량형 변수는 이산형(세어낼 수 있음) 또는 연속형(측정됨)입니다.

올바른 그래프와 요약 방법을 선택하는 것은 어떤 유형의 변수인지에 따라 달라집니다.

Explore · ⁨탐색하기⁩

Categorical or quantitative? · ⁨범주형인지 정량형인지?⁩

Every variable is either categorical (it labels each unit with a group) or quantitative (a measured number you can average). Which kind it is decides the graphs and summaries you are allowed to use. · ⁨모든 변수는 범주형(categorical) (각 단위를 그룹으로 분류함)이거나 정량적(quantitative) (평균을 계산할 수 있는 측정된 숫자)입니다. 이 종류가 어떤 그래프와 요약 통계를 사용할 수 있는지 결정합니다.⁩

1.3

Representing a Categorical Variable with Tables · ⁨표를 이용한 분류형 변수 표현⁩

Syllabus
English

Enduring Understanding (UNC-1): Graphical representations and statistics allow us to identify and represent key features of data.

Learning Objective UNC-1.A: Represent categorical data using frequency or relative frequency tables. [Skill 2.B]

  • UNC-1.A.1 A frequency table gives the number of cases falling into each category. A relative frequency table gives the proportion of cases falling into each category.

Learning Objective UNC-1.B: Describe categorical data represented in frequency or relative tables. [Skill 2.A]

  • UNC-1.B.1 Percentages, relative frequencies, and rates all provide the same information as proportions.
  • UNC-1.B.2 Counts and relative frequencies of categorical data reveal information that can be used to justify claims about the data in context.
한국어

지속적 이해(UNC-1): 그래프와 통계는 데이터의 핵심 특징을 식별하고 표현하는 데 도움을 준다.

학습 목표 UNC-1.A: 빈도표나 상대빈도표를 사용하여 범주형 데이터를 표현한다. [스킬 2.B]

  • UNC-1.A.1 빈도표는 각 범주에 속하는 사례의 수를 나타낸다. 상대빈도표는 각 범주에 속하는 사례의 비율을 나타낸다.

학습 목표 UNC-1.B: 빈도표나 상대빈도표로 표현된 범주형 데이터를 설명한다. [스킬 2.A]

  • UNC-1.B.1 백분율, 상대빈도 및 비율은 모두 비례에 대한 동일한 정보를 제공한다.
  • UNC-1.B.2 범주형 데이터의 빈도와 상대빈도는 해당 데이터에 대한 주장을 정당화하는 데 사용할 수 있는 정보를 드러낸다.

Source: College Board AP Course and Exam Description · ⁨출처: College Board AP Course and Exam Description⁩

English

A frequency table 频数表 lists each category's count (frequency); a relative frequency 相对频率 table lists each category's proportion 比例 (count ÷ total). Relative frequencies let you compare groups of different sizes fairly.

한국어

빈도 표는 각 범주의 개수(빈도)를 나열하며, 상대 빈도 표는 각 범주의 비율(개수 ÷ 총합)을 나열합니다. 상대 빈도는 서로 다른 크기의 그룹을 공평하게 비교할 수 있게 해줍니다.

1.4

Representing a Categorical Variable with Graphs · ⁨그래프를 이용한 분류형 변수 표현⁩

Syllabus
English

Enduring Understanding (UNC-1): Graphical representations and statistics allow us to identify and represent key features of data.

Learning Objective UNC-1.C: Represent categorical data graphically. [Skill 2.B]

  • UNC-1.C.1 Bar charts (or bar graphs) are used to display frequencies (counts) or relative frequencies (proportions) for categorical data.
  • UNC-1.C.2 The height or length of each bar in a bar graph corresponds to either the number or proportion of observations falling within each category.
  • UNC-1.C.3 There are many additional ways to represent frequencies (counts) or relative frequencies (proportions) for categorical data.

Learning Objective UNC-1.D: Describe categorical data represented graphically. [Skill 2.A]

  • UNC-1.D.1 Graphical representations of a categorical variable reveal information that can be used to justify claims about the data in context.

Learning Objective UNC-1.E: Compare multiple sets of categorical data. [Skill 2.D]

  • UNC-1.E.1 Frequency tables, bar graphs, or other representations can be used to compare two or more data sets in terms of the same categorical variable.
한국어

지속적 이해(UNC-1): 그래프와 통계는 데이터의 핵심 특징을 식별하고 표현하는 데 도움을 준다.

학습 목표 UNC-1.C: 범주형 데이터를 그래프로 표현한다. [스킬 2.B]

  • UNC-1.C.1 막대그래프(또는 막대 đồ)는 범주형 데이터의 빈도(개수)나 상대빈도(비율)를 표시하는 데 사용된다.
  • UNC-1.C.2 막대그래프에서 각 막대의 높이 또는 길이는 해당 범주에 속하는 관측값의 개수나 비율에 대응한다.
  • UNC-1.C.3 범주형 데이터의 빈도(개수)나 상대빈도(비율)를 표현하는还有许多 다른 방법이 있다.

학습 목표 UNC-1.D: 그래프로 표현된 범주형 데이터를 설명한다. [스킬 2.A]

  • UNC-1.D.1 범주형 변수의 그래프 표현은 해당 데이터에 대한 주장을 정당화하는 데 사용할 수 있는 정보를 드러낸다.

학습 목표 UNC-1.E: 여러 sets의 범주형 데이터를 비교한다. [스킬 2.D]

  • UNC-1.E.1 빈도표, 막대그래프 또는 다른 표현 방법을 사용하여 같은 범주형 변수에 대해 두 개 이상의 데이터 세트를 비교할 수 있다.

Source: College Board AP Course and Exam Description · ⁨출처: College Board AP Course and Exam Description⁩

English

Bar charts 条形图 show the count or proportion of each category as separated bars; a pie chart shows each category's share of the whole. The bar heights (or slices) let you compare categories at a glance. Bars may be ordered by size or by a natural category order.

한국어

막대그래프는 각 범주의 개수나 비율을 분리된 막대로 보여줍니다; 원그래프는 전체에 대한 각 범주의 비중을 보여줍니다. 막대 높이(또는 조각)를 통해 한눈에 범주를 비교할 수 있습니다. 막대는 크기 순이나 자연스러운 범주 순으로 배열될 수 있습니다.

Explore · ⁨탐색하기⁩

Show a categorical variable as a pie chart · ⁨범주형 변수를 원그래프로 표시하기⁩

A pie chart turns each category's share of the whole into a slice: a bigger share is a bigger slice, and every slice together makes 100%. It is a picture of a relative-frequency table. · ⁨원그래프는 전체에 대한 각 범위의 비중을 조각으로 변환합니다: 비중이 클수록 조각도 크며, 모든 조각을 합하면 100%가 됩니다. 이는 상대 빈도 표의 시각화입니다.⁩

1.5

Representing a Quantitative Variable with Graphs · ⁨그래프를 이용한 정량형 변수 표현⁩

Syllabus
English

Enduring Understanding (UNC-1): Graphical representations and statistics allow us to identify and represent key features of data.

Learning Objective UNC-1.F: Classify types of quantitative variables. [Skill 2.A]

  • UNC-1.F.1 A discrete variable can take on a countable number of values. The number of values may be finite or countably infinite, as with the counting numbers.
  • UNC-1.F.2 A continuous variable can take on infinitely many values, but those values cannot be counted. No matter how small the interval between two values of a continuous variable, it is always possible to determine another value between them.
    • Illustrative examples for UNC-1.F:
      • A discrete variable:
        • Number of students in a class
      • A continuous variable:
        • Height of a child

Learning Objective UNC-1.G: Represent quantitative data graphically. [Skill 2.B]

  • UNC-1.G.1 In a histogram, the height of each bar shows the number or proportion of observations that fall within the interval corresponding to that bar. Altering the interval widths can change the appearance of the histogram.
  • UNC-1.G.2 In a stem and leaf plot, each data value is split into a "stem" (the first digit or digits) and a "leaf" (usually the last digit).
  • UNC-1.G.3 A dotplot represents each observation by a dot, with the position on the horizontal axis corresponding to the data value of that observation, with nearly identical values stacked on top of each other.
  • UNC-1.G.4 A cumulative graph represents the number or proportion of a data set less than or equal to a given number.
  • UNC-1.G.5 There are many additional ways to graphically represent distributions of quantitative data.
한국어

지속적 이해(UNC-1): 그래프와 통계는 데이터의 핵심 특징을 식별하고 표현하는 데 도움을 준다.

학습 목표 UNC-1.F: 정량 변수의 유형을 분류한다. [스킬 2.A]

  • UNC-1.F.1 이산 변수는 세어낼 수 있는 수의 값을 가질 수 있다. 값의 수는 유한하거나 세어낼 수 있는 무한일 수 있으며, 자연수처럼 세는 경우와 같다.
  • UNC-1.F.2 연속 변수는 무한히 많은 값을 가질 수 있지만, 그 값들은 세어낼 수 없다. 연속 변수의 두 값 사이의 간격이 아무리 작더라도 항상 그 사이에 다른 값을 결정할 수 있다.
    • UNC-1.F에 대한 예시:
      • 이산 변수:
        • 한 반의 학생 수
      • 연속 변수:
        • 아이의 키

학습 목표 UNC-1.G: 정량 데이터를 그래프로 표현한다. [스킬 2.B]

  • UNC-1.G.1 히스토그램에서 각 막대의 높이는 해당 막대에 대응하는 구간에falling하는 관측값의 수나 비율을 보여준다. 구간 너비를 변경하면 히스토그램의 외관이 달라질 수 있다.
  • UNC-1.G.2 줄임말 Plot(stem and leaf plot)에서 각 데이터 값은 "줄기"(첫 번째 또는 몇 개의 숫자)와 "잎
  • UNC-1.G.3 도트 플롯(dotplot)은 각 관측치를 점(dot)으로 나타내며, 수평축上の 위치는 해당 관측치의 데이터 값에 대응하며, 거의 동일한 값들은 서로 겹쳐 쌓입니다.
  • UNC-1.G.4 누적 그래프(cumulative graph)는 주어진 숫자 이하인 데이터셋의 수나 비율을 나타냅니다.
  • UNC-1.G.5 정량적 데이터의 분포를 시각적으로 표현하는 다른 많은 방법들이 있습니다.

Source: College Board AP Course and Exam Description · ⁨출처: College Board AP Course and Exam Description⁩

English

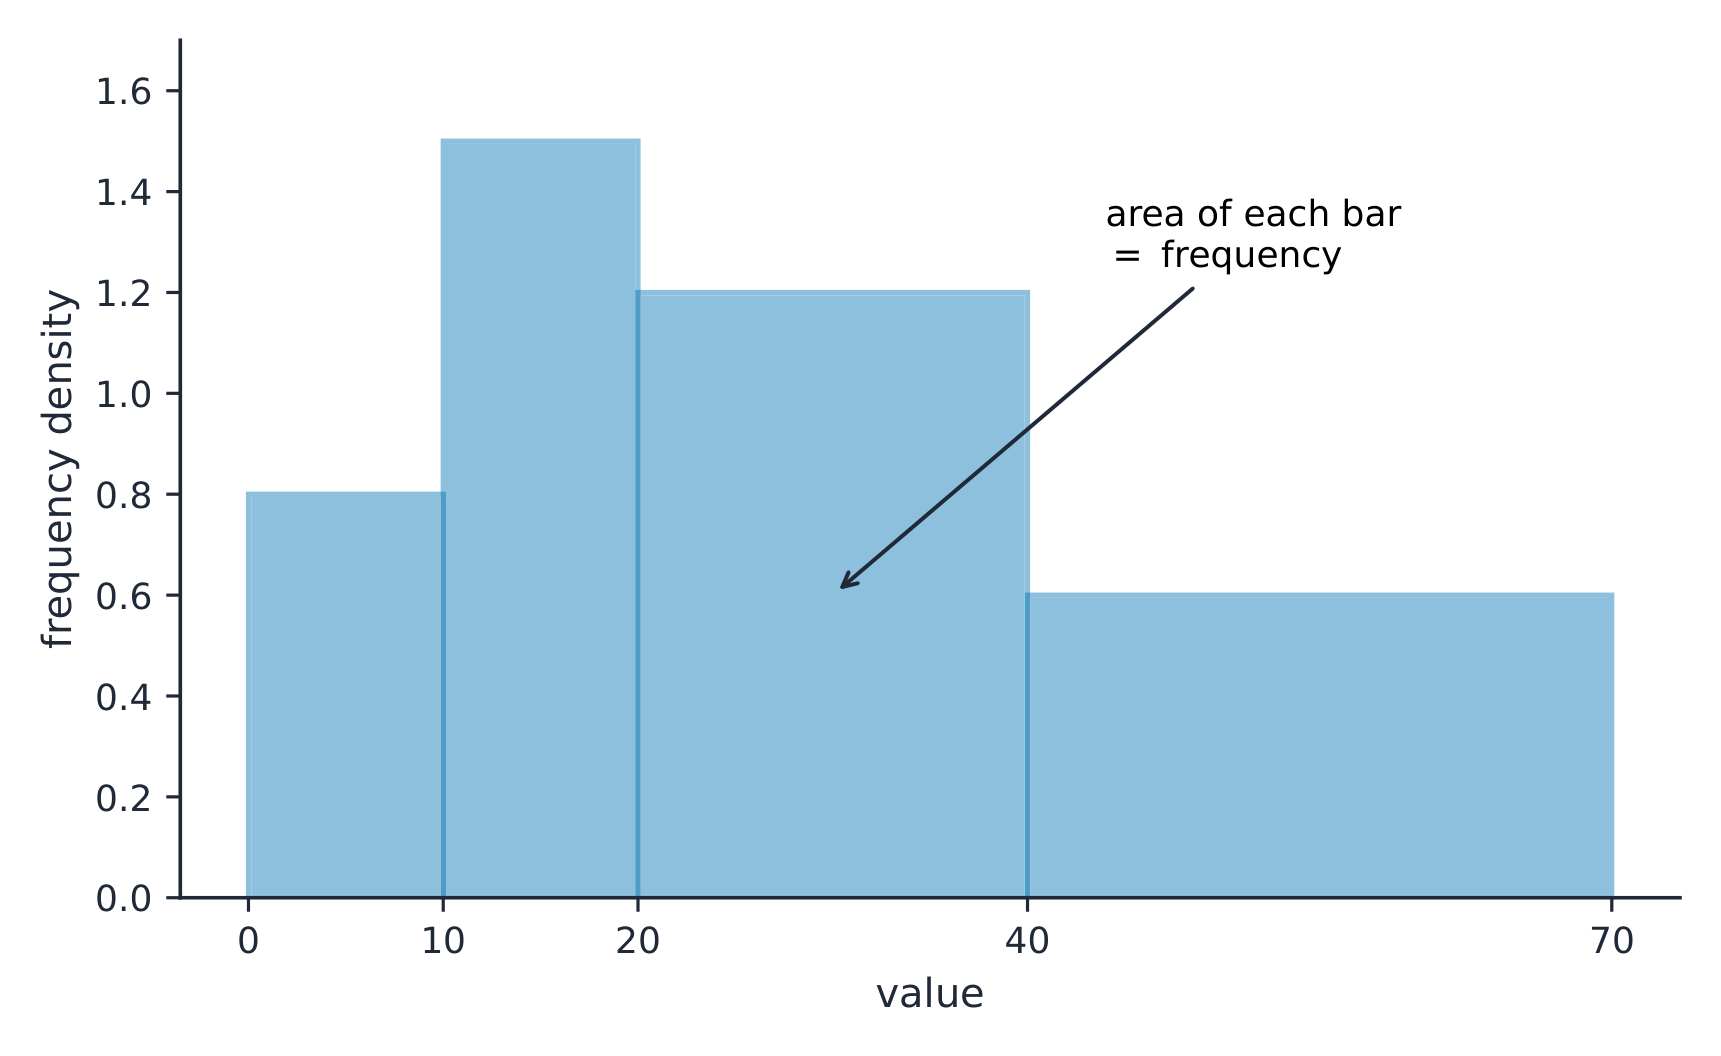
For numbers, use a dotplot 点图, stem-and-leaf plot 茎叶图, or histogram 直方图 (bars over value intervals called bins). These show the distribution 分布 – how the values spread out. A histogram's bin width changes the picture, so choose it to reveal the shape.

한국어

숫자의 경우 점도표, 줄임표, 또는 히스토그램(값 구간인 빈 위에 그은 막대)을 사용하십시오. 이들은 분포—값들이 어떻게 퍼져 있는지—를 보여줍니다. 히스토그램의 빈 폭은 그림을 바꾸므로, 형태를 드러내도록 적절히 선택하십시오.

불균등 계급폭 히스토그램에서 막대 면적은 빈도이다
Explore · ⁨탐색하기⁩

Explore how bin width shapes a histogram · ⁨빈(bin) 너비가 히스토그램 형태를 어떻게 결정하는지 탐구하기⁩

A histogram groups data into equal-width bins and draws a bar over each. Change the bins and notice how the same data can look jagged (too narrow) or smooth (too wide) — the shape is a choice. · ⁨히스토그램은 데이터를 동일한 너비의 빈으로 묶고 각 빈 위에 막대를 그립니다. 빈을 변경하면 같은 데이터가 거칠게(너비 너무窄) 또는 매끄럽게(너비 너무 넓) 보이는 것을 관찰할 수 있습니다—형태는 선택의 결과입니다.⁩

Vocabulary · ⁨어휘⁩ Train · ⁨연습하기⁩
English 한국어
Statistics/stəˈtɪstɪks/ 통계학
statistic/stəˈtɪstɪk/ 통계량
descriptive statistics/dɪˈskrɪptɪv stəˈtɪstɪks/ 기술 통계
inferential statistics/ɪnfəˈrenʃl stəˈtɪstɪks/ 추론 통계(inferential statistics)
variable/ˈveərɪəbl/ 变量
Categorical/ˌkætɪˈɡɒrɪkl/ 범주성(분류적)
Quantitative/ˈkwɒntɪteɪtɪv/ 정량적
frequency table/ˈfriːkwənsi ˈteɪbl/ 빈도표
relative frequency/ˈrelətɪv ˈfriːkwənsi/ 상대 빈도
proportion/prəˈpɔːʃn/ 비율
Bar charts/bɑː tʃɑːts/ 막대그래프(Bar charts)
dotplot/ˈdɒtplɒt/ 점 도표
stem-and-leaf plot/stem ænd liːf plɒt/ 줄기-잎 도표
histogram/ˈhɪstəɡræm/ 히스토그램
1.6

Describing the Distribution of a Quantitative Variable · ⁨정량 변수의 분포 설명하기⁩

Syllabus
English

Enduring Understanding (UNC-1): Graphical representations and statistics allow us to identify and represent key features of data.

Learning Objective UNC-1.H: Describe the characteristics of quantitative data distributions. [Skill 2.A]

  • UNC-1.H.1 Descriptions of the distribution of quantitative data include shape, center, and variability (spread), as well as any unusual features such as outliers, gaps, clusters, or multiple peaks.
  • UNC-1.H.2 Outliers for one-variable data are data points that are unusually small or large relative to the rest of the data.
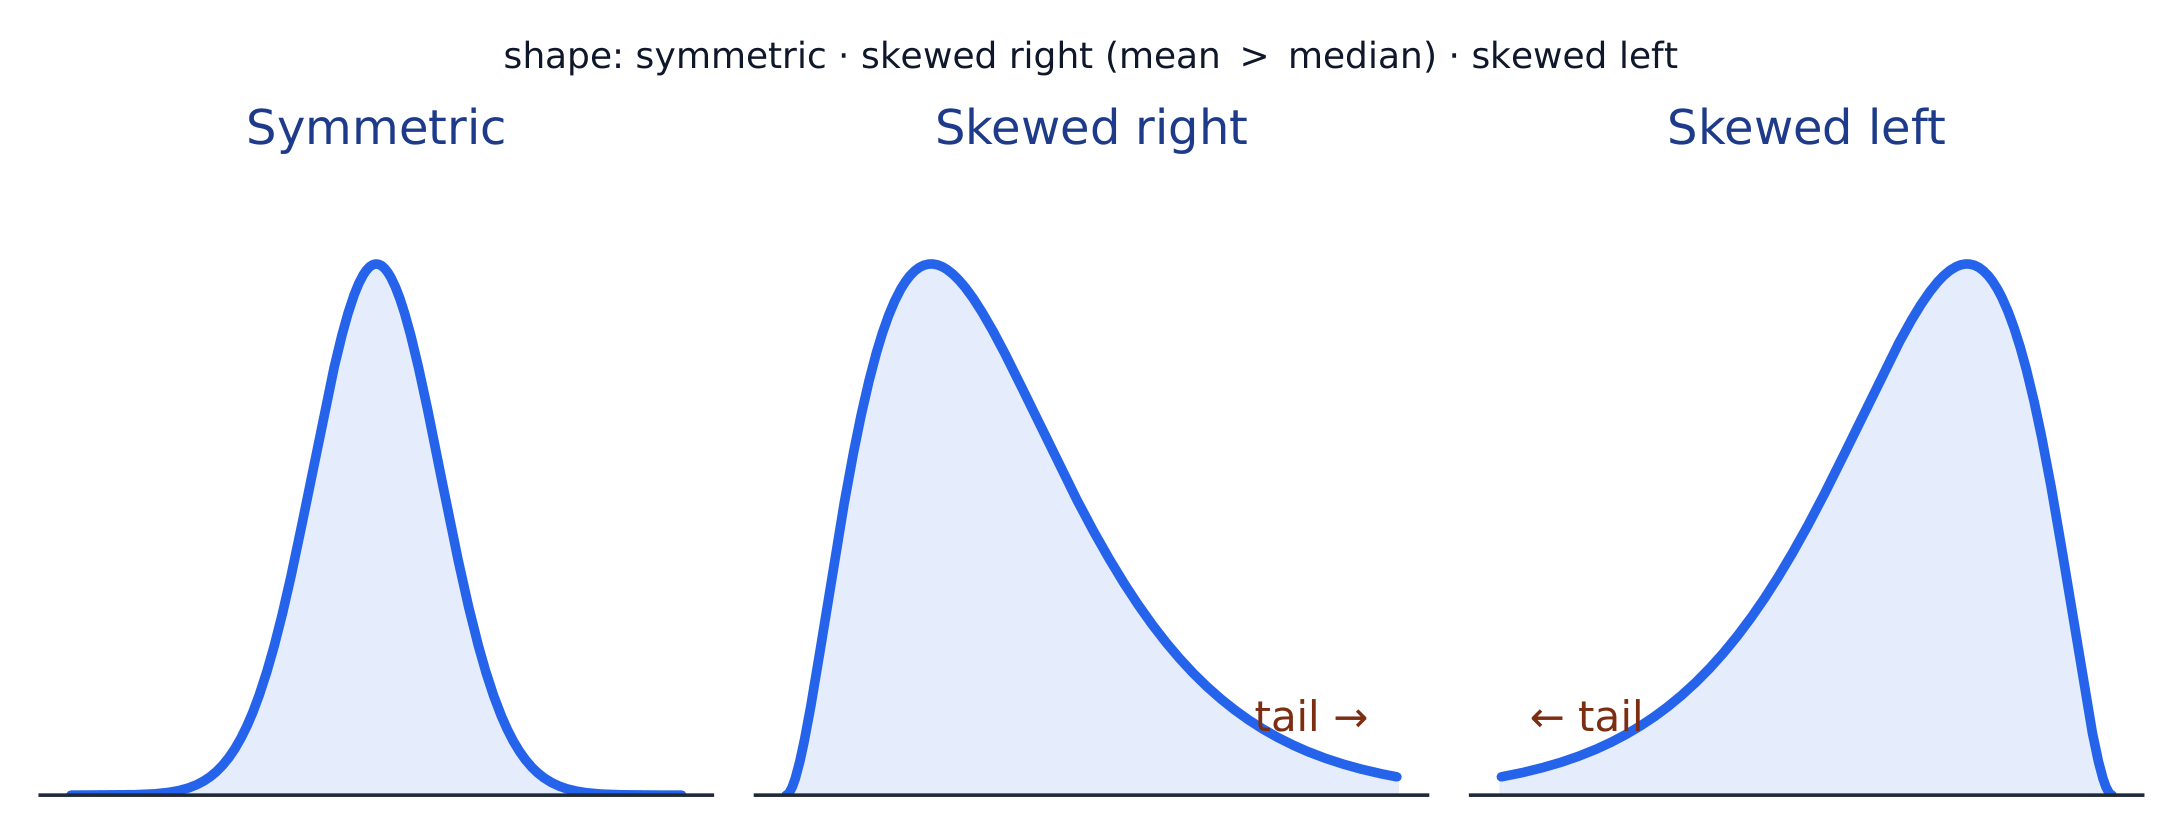
  • UNC-1.H.3 A distribution is skewed to the right (positive skew) if the right tail is longer than the left. A distribution is skewed to the left (negative skew) if the left tail is longer than the right. A distribution is symmetric if the left half is the mirror image of the right half.
  • UNC-1.H.4 Univariate graphs with one main peak are known as unimodal. Graphs with two prominent peaks are bimodal. A graph where each bar height is approximately the same (no prominent peaks) is approximately uniform.
  • UNC-1.H.5 A gap is a region of a distribution between two data values where there are no observed data.
  • UNC-1.H.6 Clusters are concentrations of data usually separated by gaps.
  • UNC-1.H.7 Descriptive statistics does not attribute properties of a data set to a larger population, but may provide the basis for conjectures for subsequent testing.
한국어

지속적 이해(UNC-1): 그래프와 통계는 데이터의 핵심 특징을 식별하고 표현하는 데 도움을 준다.

학습 목표 UNC-1.H: 정량 데이터 분포의 특성을 설명하십시오. [기술 2.A]

  • UNC-1.H.1 정량적 데이터의 분포를 설명하는 요소로는 형태, 중심, 변이도(확산)뿐만 아니라 이상치, 간격, 클러스터 또는 여러 개의 봉우리와 같은 비정상적인 특징이 포함됩니다.
  • UNC-1.H.2 단변량 데이터의 이상치는 다른 데이터와 비교해 비정상적으로 작거나 큰 값입니다.
  • UNC-1.H.3 분포에서 오른쪽 꼬리가 왼쪽 꼬리보다 길면 우편향(양수 치우침)이라고 합니다. 반대로 왼쪽 꼬리가 오른쪽 꼬리보다 길면 좌편향(음수 치우침)이라고 합니다. 양쪽 절반이 서로 거울상 대칭을 이룰 때 분포는 대칭이라고 합니다.
  • UNC-1.H.4 단일 봉우리를 가진 단변량 그래프를 일봉형(unimodal)이라 합니다. 두 개의 뚜렷한 봉우리를 가진 그래프를 이봉형(bimodal)이라 합니다. 각 막대 높이가 거의 동일하여 뚜렷한 봉우리가 없는 그래프는 근사 균일(non-uniformity)합니다.
  • UNC-1.H.5 간격(gap)은 관측된 데이터가 없는 두 데이터 값 사이의 분포 영역입니다.
  • UNC-1.H.6 클러스터(cluster)는 일반적으로 간격에 의해 분리된 데이터의 집중 영역입니다.
  • UNC-1.H.7 서술 통계는 데이터셋의 속성을 더 큰 집단에 귀속시키지 않지만, 후속 검증을 위한 추론의 기초를 제공할 수 있습니다.

Source: College Board AP Course and Exam Description · ⁨출처: College Board AP Course and Exam Description⁩

English

Describe four things (remember SOCS):

  • Shape 形状: symmetric, or skewed 偏斜 left/right (a long tail on that side), and how many peaks - one main peak is unimodal 单峰, two prominent peaks bimodal 双峰, and roughly equal bars uniform 均匀.
  • Outliers 离群值: unusual values far from the rest.
  • Center: a typical value (mean or median).
  • Spread: how much the values vary (range, IQR, standard deviation).

Always describe shape/center/spread in context, with units.

한국어

네 가지 사항(SOCS를 기억하세요)을 서술하십시오:

  • 모양: 대칭이거나 왜도가 왼쪽/오른쪽인 경우(해당 쪽으로 긴 꼬리), 그리고 봉우리가 몇 개인지 – 주요 봉우리가 하나인 것은 단봉, 두 개의 뚜렷한 봉우는 이봉, 막대 높이가 거의 동일한 것은 균일합니다.
  • 외상치: 나머지 값들과 멀리 떨어진 이질적인 값입니다.
  • 중심: 일반적인 값(평균 또는 중앙값).
  • 분산: 값들의 변동 정도 (범위, 사분위율, 표준편차).

항상 단위와 함께 형태/중심/분산을 문맥에서 서술하십시오.

분포의 형태: 대칭, 오른쪽 치우침(오른쪽 꼬리가 긴), 왼쪽 치우침
Vocabulary · ⁨어휘⁩ Train · ⁨연습하기⁩
English 한국어
distribution/ˌdɪstrɪˈbjuːʃn/ 분배
Shape/ʃeɪp/ 형태(Shape)
skewed/skjuːd/ 편향된
unimodal/ˌʌnɪˈmɒdl/ 단일 극(unimodal)
bimodal/baɪˈmɒdl/ 이중 극(bimodal)
uniform/ˈjuːnɪfɔːm/ 균일한(uniform)
Outliers/ˈaʊtlaɪəz/ 이치(Outliers)
mean/miːn/ 평균
median/ˈmiːdiːən/ 중位数Unless median.
interquartile range/ˌɪntəˈkwɔːtaɪl reɪndʒ/ 사분위 범위
1.7

Summary Statistics for a Quantitative Variable · ⁨정량 변수에 대한 요약 통계량⁩

Syllabus
Enduring UnderstandingLearning ObjectiveEssential Knowledge

UNC-1
Graphical representations and statistics allow us to identify and represent key features of data.

UNC-1.I
Calculate measures of center and position for quantitative data. [Skill 2.C]

  • UNC-1.I.1 A statistic is a numerical summary of sample data.
  • UNC-1.I.2 The mean is the sum of all the data values divided by the number of values. For a sample, the mean is denoted by $x$-bar: $\bar{x} = \dfrac{1}{n}\sum_{i=1}^{n} x_i$, where $x_i$ represents the $i^{\text{th}}$ data point in the sample and $n$ represents the number of data values in the sample.
  • UNC-1.I.3 The median of a data set is the middle value when data are ordered. When the number of data points is even, the median can take on any value between the two middle values. In AP Statistics, the most commonly used value for the median of a data set with an even number of values is the average of the two middle values.
  • UNC-1.I.4 The first quartile, Q1, is the median of the half of the ordered data set from the minimum to the position of the median. The third quartile, Q3, is the median of the half of the ordered data set from the position of the median to the maximum. Q1 and Q3 form the boundaries for the middle 50% of values in an ordered data set.
  • UNC-1.I.5 The $p^{\text{th}}$ percentile is interpreted as the value that has $p\%$ of the data less than or equal to it.

UNC-1.J
Calculate measures of variability for quantitative data. [Skill 2.C]

  • UNC-1.J.1 Three commonly used measures of variability (or spread) in a distribution are the range, interquartile range, and standard deviation.
  • UNC-1.J.2 The range is defined as the difference between the maximum data value and the minimum data value. The interquartile range (IQR) is defined as the difference between the third and first quartiles: $Q3 - Q1$. Both the range and the interquartile range are possible ways of measuring variability of the distribution of a quantitative variable.
  • UNC-1.J.3 Standard deviation is a way to measure variability of the distribution of a quantitative variable. For a sample, the standard deviation is denoted by $s$: $s_x = \sqrt{\dfrac{1}{n-1}\sum(x_i - \bar{x})^2}$. The square of the sample standard deviation, $s^2$, is called the sample variance.
  • UNC-1.J.4 Changing units of measurement affects the values of the calculated statistics.

UNC-1.K
Explain the selection of a particular measure of center and/or variability for describing a set of quantitative data. [Skill 4.B]

  • UNC-1.K.1 There are many methods for determining outliers. Two methods frequently used in this course are:
    • UNC-1.K.1.i An outlier is a value greater than $1.5 \times \text{IQR}$ above the third quartile or more than $1.5 \times \text{IQR}$ below the first quartile.
    • UNC-1.K.1.ii An outlier is a value located 2 or more standard deviations above, or below, the mean.
  • UNC-1.K.2 The mean, standard deviation, and range are considered nonresistant (or non-robust) because they are influenced by outliers. The median and IQR are considered resistant (or robust), because outliers do not greatly (if at all) affect their value.

Source: College Board AP Course and Exam Description · ⁨출처: College Board AP Course and Exam Description⁩

English
Standard deviation: spread about the mean
  • Center: the mean 均值 $\bar{x}=\dfrac{\sum x_i}{n}$ (average) and the median 中位数 (middle value). The median resists outliers; the mean is pulled toward a skew.
  • Spread: the range, the interquartile range 四分位距 $\text{IQR}=Q_3-Q_1$ (middle 50%), and the standard deviation 标准差 $s_x=\sqrt{\dfrac{\sum(x_i-\bar{x})^2}{n-1}}$ (typical distance from the mean; its square is the variance 方差).
  • The five-number summary 五数概括: min, $Q_1$, median, $Q_3$, max.

Use resistant measures (median, IQR) for skewed data; mean and standard deviation for roughly symmetric data.

The percentile 百分位数 of a value is the percent of the data at or below it – so the median is the 50th percentile and $Q_1$ the 25th. A cumulative relative frequency graph 累积相对频率图 makes percentiles easy to read: for each value it plots the proportion of the data at or below it, rising from 0 to 1. Go up from a value to the curve and across to its percentile, or reverse the steps to find the value at a given percentile (the same reading works from a cumulative-frequency table).

Worked example. For the data $4, 8, 6, 10, 7$: the mean is $\bar{x}=\dfrac{4+8+6+10+7}{5}=\dfrac{35}{5}=7$. Sorting to $4,6,7,8,10$, the median is the middle value, $7$. The mean and median agree here because the data are roughly symmetric.

한국어
표준편차: 평균 주변의 분산
  • 중심: 평균 $\bar{x}=\dfrac{\sum x_i}{n}$(보통값)과 중位数(가운데 값). 중位数는 이상치에 강하고, 평균은 치우침 쪽으로 끌려갑니다.
  • 분산: 범위, 사분위율(IQR) $\text{IQR}=Q_3-Q_1$(중간 50%), 표준편차 $s_x=\sqrt{\dfrac{\sum(x_i-\bar{x})^2}{n-1}}$(평균으로부터의 typical 거리; 제곱이 분산임).
  • 오수 요약: 최솟값, $Q_1$, 중앙값, $Q_3$, 최댓값.

치우친 데이터에는 강한(resistant) 지표(중位数, IQR)를 사용하고, 대칭에 가까운 데이터에는 평균과 표준편차를 사용하십시오.

value의 백분위수(percentile) 는 해당 값 이하인 데이터의 비율입니다. 따라서 중位数는 50백분위수이고 $Q_1$는 25백분위수입니다. 누적 상대 빈도 그래프는 백분위수를 쉽게 읽을 수 있게 합니다: 각 value에 대해 그 값 이하인 데이터의 비례를 plot하며 0에서 1까지 상승합니다. value에서 위로 올라가 곡선에 도달한 후 백분위수로 이동하거나, 역순으로 진행하여 주어진 백분위수에 해당하는 value를 구할 수 있습니다(누적 빈도 표에서도 동일한 읽기법이 적용됩니다).

해설 예제. 데이터 $4, 8, 6, 10, 7$: 평균은 $\bar{x}=\dfrac{4+8+6+10+7}{5}=\dfrac{35}{5}=7$입니다. 정렬된 데이터 $4,6,7,8,10$에서 중位数는 가운데 값 $7$입니다. 데이터가 대칭에 가까워 평균과 중位数가 일치합니다.

Vocabulary · ⁨어휘⁩ Train · ⁨연습하기⁩
English 한국어
standard deviation/ˈstændəd ˌdiːvɪˈeɪʃn/ 표준편차
variance/ˈveərɪəns/ 편차
five-number summary/faɪv ˈnʌmbə ˈsʌməri/ 5개 수 요약
percentile/pəˈsentaɪl/ 백분위수
cumulative relative frequency graph/ˈkjuːmjʊlətɪv ˈrelətɪv ˈfriːkwənsi ɡræf/ 누적 상대 빈도 그래프(cumulative relative frequency graph)
1.8

Graphical Representations of Summary Statistics · ⁨요약 통계량의 시각적 표현⁩

Syllabus
Enduring UnderstandingLearning ObjectiveEssential Knowledge

UNC-1
Graphical representations and statistics allow us to identify and represent key features of data.

UNC-1.L
Represent summary statistics for quantitative data graphically. [Skill 2.B]

  • UNC-1.L.1 Taken together, the minimum data value, the first quartile (Q1), the median, the third quartile (Q3), and the maximum data value make up the five-number summary.
  • UNC-1.L.2 A boxplot is a graphical representation of the five-number summary (minimum, first quartile, median, third quartile, maximum). The box represents the middle 50% of data, with a line at the median and the ends of the box corresponding to the quartiles. Lines ("whiskers") extend from the quartiles to the most extreme point that is not an outlier, and outliers are indicated by their own symbol beyond this.

UNC-1.M
Describe summary statistics of quantitative data represented graphically. [Skill 2.A]

  • UNC-1.M.1 Summary statistics of quantitative data, or of sets of quantitative data, can be used to justify claims about the data in context.
  • UNC-1.M.2 If a distribution is relatively symmetric, then the mean and median are relatively close to one another. If a distribution is skewed right, then the mean is usually to the right of the median. If the distribution is skewed left, then the mean is usually to the left of the median.

Source: College Board AP Course and Exam Description · ⁨출처: College Board AP Course and Exam Description⁩

English

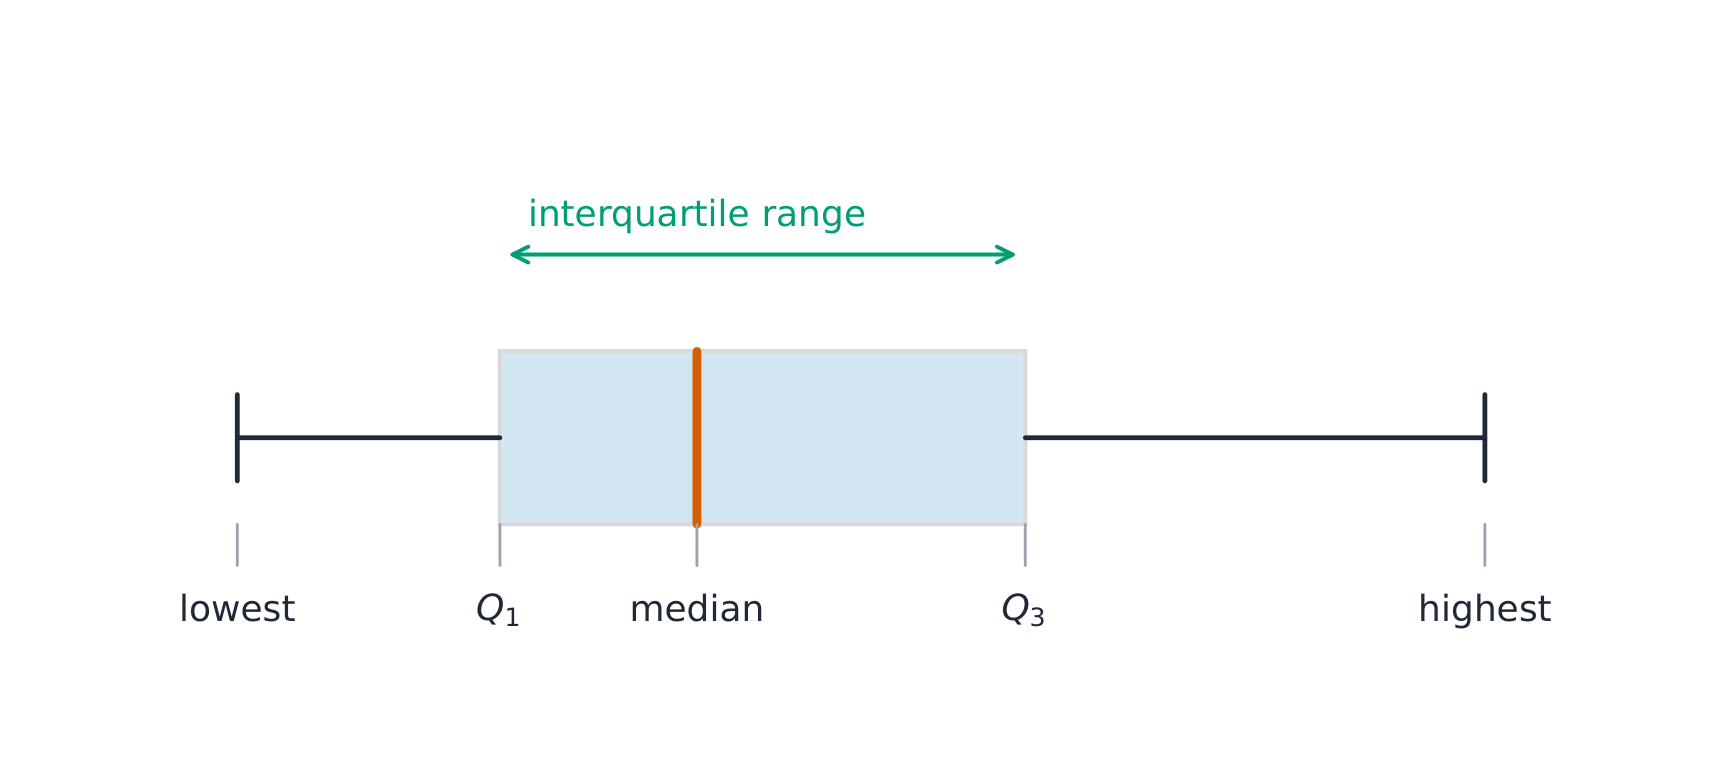
A boxplot 箱线图 draws the five-number summary: a box from $Q_1$ to $Q_3$ with the median inside, and whiskers to the most extreme non-outlier values. A point is an outlier if it lies more than $1.5\times\text{IQR}$ beyond a quartile – a rule you may be asked to apply. Boxplots are ideal for comparing several groups side by side.

Worked example. A dataset has $Q_1=20$ and $Q_3=32$, so $\text{IQR}=12$. The outlier fences are $Q_1-1.5(12)=2$ and $Q_3+1.5(12)=50$. Any value below $2$ or above $50$ is flagged as an outlier.

한국어

상자 whisker 도표는 오수 요약을 그립니다: $Q_1$에서 $Q_3$까지 상자를 그리며 중앙값을 내부에 넣고, 가장 극단적인 비외상치 값까지 whisker를 뻗습니다. 한 사분위로부터 $1.5\times\text{IQR}$ 이상 떨어져 있는 점은 외상치로 간주하며, 이를 적용하라는 요청을 받을 수 있습니다. 상자 whisker 도표는 여러 그룹을 나란히 비교하기에 적합합니다.

해설 예제. 데이터셋에 $Q_1=20$와 $Q_3=32$이 있으므로 $\text{IQR}=12$입니다. 이상치 경계(fences)는 $Q_1-1.5(12)=2$과 $Q_3+1.5(12)=50$입니다. $2$보다 작거나 $50$보다 큰 모든 값은 이상치로 표시됩니다.

상자 whisker 도표는 사분위와 범위를 보여줍니다
상자-수염 도구는 사분위수와 범위를 보여줍니다
상자 whisker 도표는 오수 요약을 그리며, 상자는 IQR 범위를 가집니다
박스플롯은 5개 수 요약을 그리며, 상자는 IQR 범위입니다
Explore · ⁨탐색하기⁩

Explore the five-number summary as a boxplot · ⁨오수분위( Five-number summary )를 상자도형(boxplot)으로 탐구하기⁩

Drag $Q_1$, the median, and $Q_3$ to see the box (its length is the IQR) and how the median's position inside the box reveals skew — a median close to $Q_1$ signals a right-skewed distribution. · ⁨$Q_1$인 **중위수(median)**와 $Q_3$을 드래그하여 상자를 보십시오(상자의 길이는 IQR입니다). 상자 안에서의 중위수 위치가 **편향(skew)**을 나타내는 방식을 확인하십시오—중위수가 $Q_1$에 가까우면 우측 치우친(right-skewed) 분포임을 시사합니다.⁩

Vocabulary · ⁨어휘⁩ Train · ⁨연습하기⁩
English 한국어
boxplot/ˈbɒksplɒt/ 박스플롯
1.9

Comparing Distributions of a Quantitative Variable · ⁨정량 변수의 분포 비교하기⁩

Syllabus
English

Enduring Understanding (UNC-1): Graphical representations and statistics allow us to identify and represent key features of data.

Learning Objective UNC-1.N: Compare graphical representations for multiple sets of quantitative data. [Skill 2.D]

  • UNC-1.N.1 Any of the graphical representations, e.g., histograms, side-by-side boxplots, etc., can be used to compare two or more independent samples on center, variability, clusters, gaps, outliers, and other features.

Learning Objective UNC-1.O: Compare summary statistics for multiple sets of quantitative data. [Skill 2.D]

  • UNC-1.O.1 Any of the numerical summaries (e.g., mean, standard deviation, relative frequency, etc.) can be used to compare two or more independent samples.
한국어

지속적 이해(UNC-1): 그래프와 통계는 데이터의 핵심 특징을 식별하고 표현하는 데 도움을 준다.

학습 목표 UNC-1.N: 여러 정량적 데이터셋에 대한 그래프 표현을 비교하기. [기술 2.D]

  • UNC-1.N.1 히스토그램, 나란히 배치된 상자도 등 어떤 그래프 표현이라도 중심, 변동성, 무리(clusters), 간격(gaps), 이상치 및 기타 특징을 기준으로 두 개 이상의 독립 표본을 비교하는 데 사용할 수 있다.

학습 목표 UNC-1.O: 여러 정량적 데이터셋의 요약 통계량을 비교하기. [기술 2.D]

  • UNC-1.O.1 평균, 표준편차, 상대 빈도 등 어떤 숫자 요약(mathematical summaries)이라도 두 개 이상의 독립 표본을 비교하는 데 사용할 수 있다.

Source: College Board AP Course and Exam Description · ⁨출처: College Board AP Course and Exam Description⁩

English

To compare two or more groups, compare shape, center, and spread, and mention outliers – always with comparative words ("Group A has a higher median than Group B") and in context. Do not just describe each group separately; make the comparison explicit.

한국어

두 개 이상의 그룹을 비교하려면 형태, 중심, 분산을 비교하고 이상치를 언급하십시오. 반드시 비교 용어(예: "그룹 A의 중位数가 그룹 B보다 **높다"")와 문맥을 포함해야 합니다. 각 그룹을 개별적으로 설명하는 데 그치지 말고, 비교를 명시적으로 하십시오.

Explore · ⁨탐색하기⁩

Compare distributions with box plots · ⁨상자 그래프로 분포 비교하기⁩

A box plot draws the five-number summary. Placing two box plots on the same scale compares their centre (median), spread (IQR = box width) and skew at a glance — the fair way to compare groups. · ⁨상자 그래프는 오수 통계를 그립니다. 두 상자 그래프를 동일한 축 위에 배치하면 한눈에 중앙(중位数), 확산(IQR = 상자 너비) 및 편향을 비교할 수 있어, 집단 간 공정한 비교 방법입니다.⁩

1.10

The Normal Distribution · ⁨정규 분포⁩

Syllabus
Enduring UnderstandingLearning ObjectiveEssential Knowledge

VAR-2
The normal distribution can be used to represent some population distributions.

VAR-2.A
Compare a data distribution to the normal distribution model. [Skill 2.D]

  • VAR-2.A.1 A parameter is a numerical summary of a population.
  • VAR-2.A.2 Some sets of data may be described as approximately normally distributed. A normal curve is mound-shaped and symmetric. The parameters of a normal distribution are the population mean, $\mu$, and the population standard deviation, $\sigma$.
  • VAR-2.A.3 For a normal distribution, approximately 68% of the observations are within 1 standard deviation of the mean, approximately 95% of observations are within 2 standard deviations of the mean, and approximately 99.7% of observations are within 3 standard deviations of the mean. This is called the empirical rule.
  • VAR-2.A.4 Many variables can be modeled by a normal distribution.
    • Illustrative examples for VAR-2.A:
      • Variables that can be modeled by a normal distribution:
        • Body temperature
        • Weight of a loaf of bread

VAR-2.B
Determine proportions and percentiles from a normal distribution. [Skill 3.A]

  • VAR-2.B.1 A standardized score for a particular data value is calculated as (data value − mean)/(standard deviation), and measures the number of standard deviations a data value falls above or below the mean.
  • VAR-2.B.2 One example of a standardized score is a $z$-score, which is calculated as $z\text{-score} = \left(\dfrac{x_i - \mu}{\sigma}\right)$. A $z$-score measures how many standard deviations a data value is from the mean.
  • VAR-2.B.3 Technology, such as a calculator, a standard normal table, or computer-generated output, can be used to find the proportion of data values located on a given interval of a normally distributed random variable.
  • VAR-2.B.4 Given the area of a region under the graph of the normal distribution curve, it is possible to use technology, such as a calculator, a standard normal table, or computer-generated output, to estimate parameters for some populations.

VAR-2.C
Compare measures of relative position in data sets. [Skill 2.D]

  • VAR-2.C.1 Percentiles and $z$-scores may be used to compare relative positions of points within a data set or between data sets.

Source: College Board AP Course and Exam Description · ⁨출처: College Board AP Course and Exam Description⁩

English

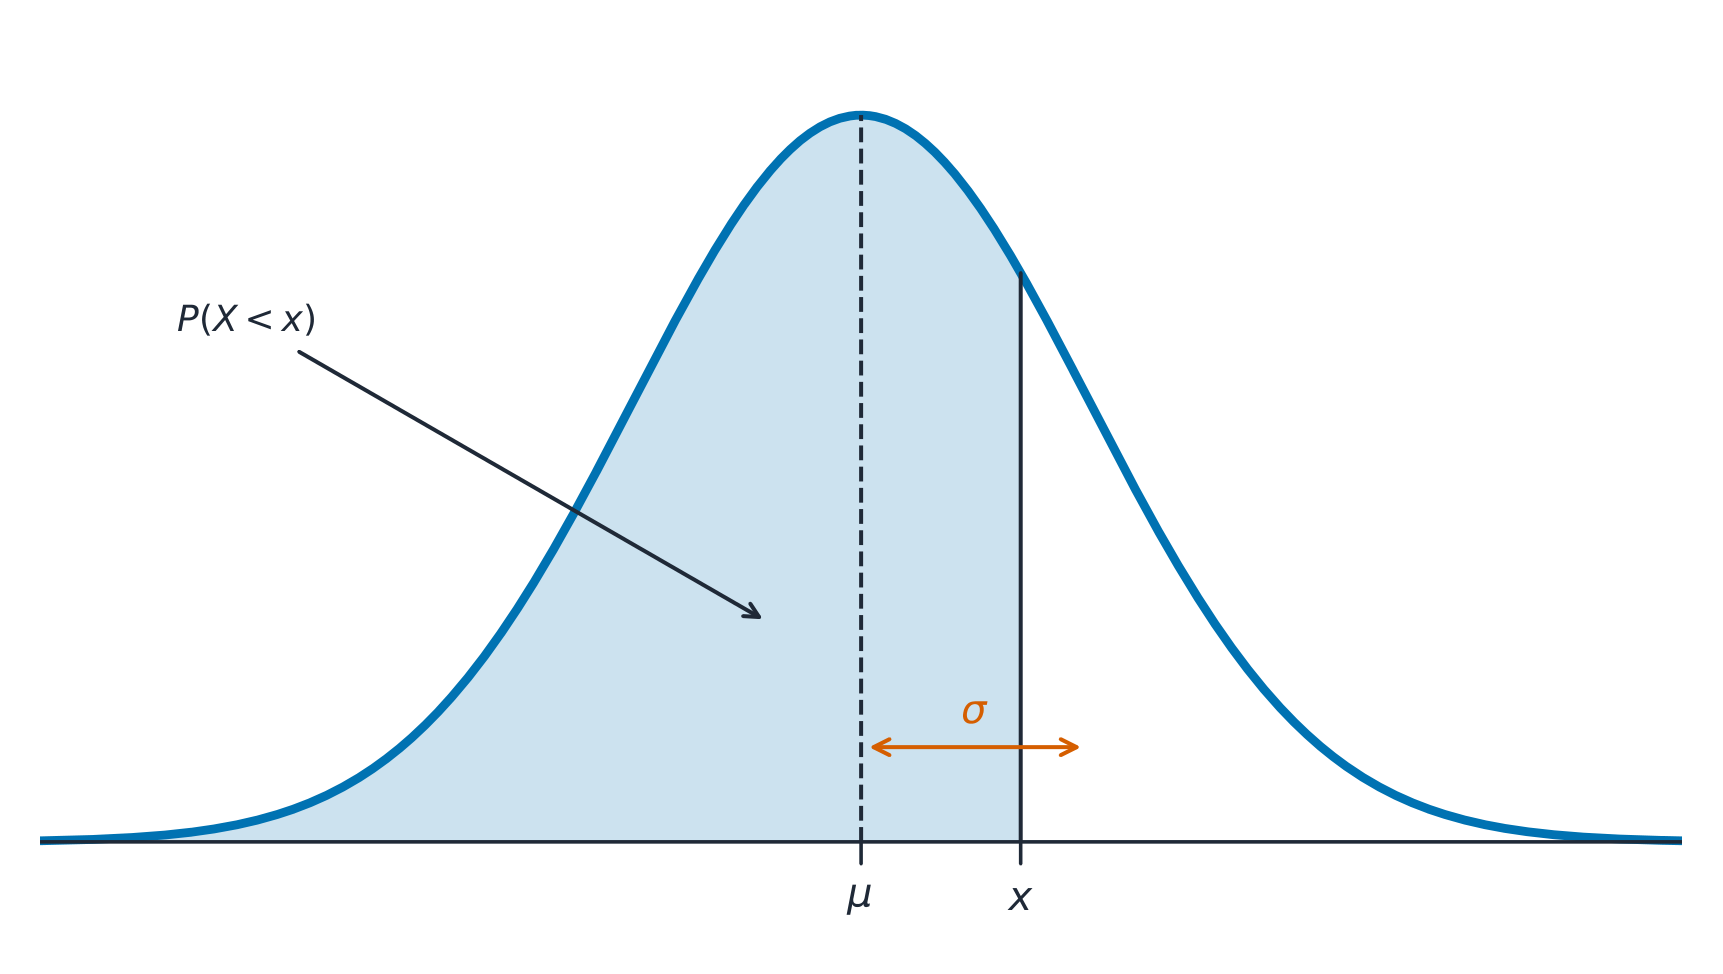
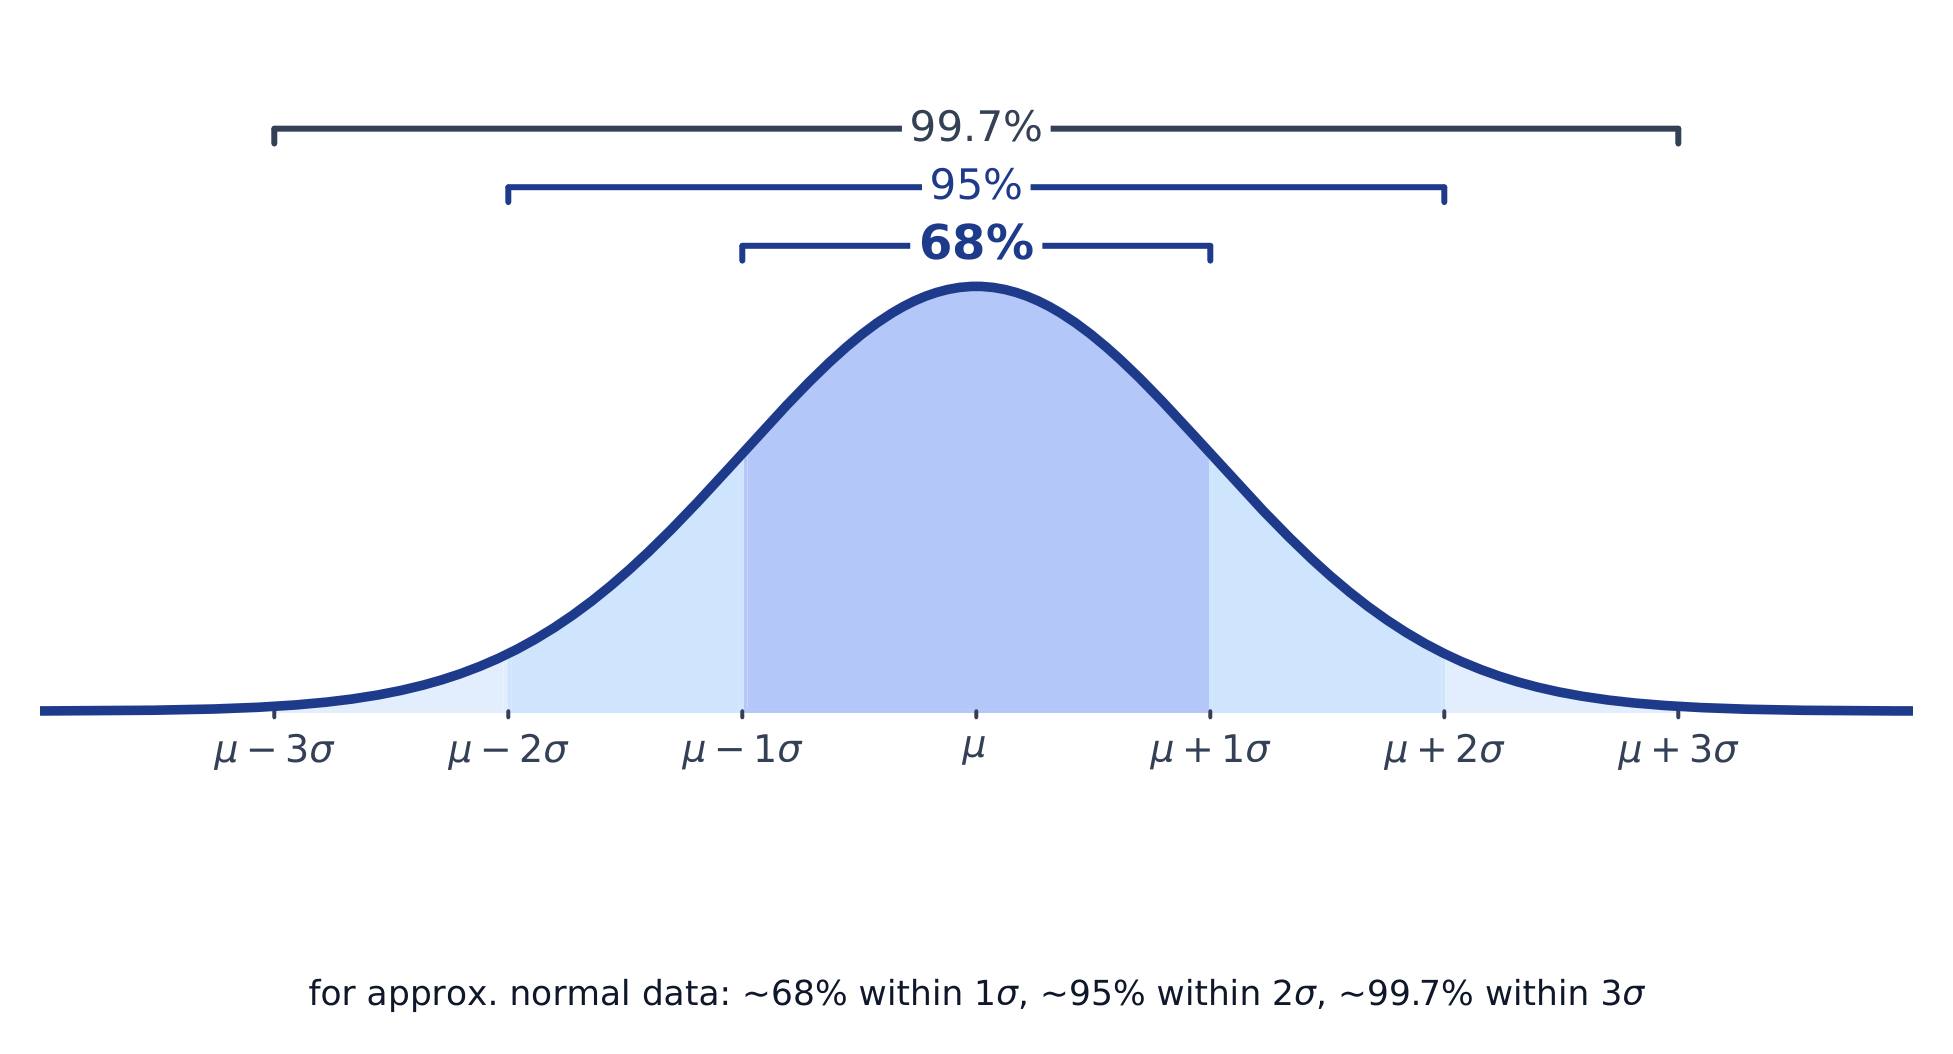
A normal distribution 正态分布 is a symmetric, bell-shaped model described by its mean $\mu$ and standard deviation $\sigma$. The empirical rule 经验法则 (68–95–99.7): about 68% of values lie within $1\sigma$ of the mean, 95% within $2\sigma$, and 99.7% within $3\sigma$.

A $z$-score 标准分数 measures how many standard deviations a value is from the mean:

$$z=\frac{x-\mu}{\sigma}.$$
Convert to a $z$-score, then use the normal table or technology to find the proportion (area) below, above, or between values – and reverse the process to find a value from a given percentile.

Worked example. Test scores are normal with $\mu=500$ and $\sigma=100$. A score of $700$ has $z=\dfrac{700-500}{100}=2$. By the empirical rule, $95\%$ of scores lie within $2\sigma$, so $2.5\%$ lie above $700$ – meaning a $700$ is at about the $97.5$th percentile.

한국어

정규 분포(normal distribution) 는 대칭적이고 종 모양이며, 평균 $\mu$와 표준편차 $\sigma$로 설명되는 모델입니다. 경험則(empirical rule, 68–95–99.7) : 값의 약 68%는 평균으로부터 $1\sigma$ 이내, 95%는 $2\sigma$ 이내, 99.7%는 $3\sigma$ 이내에 위치합니다.

표준 정규 곡선: 평균을 중심으로 한 곡선 아래 면적이 확률

$z$점수는 값이 평균으로부터 표준편차 몇 개나 떨어져 있는지 측정합니다:

$$z=\frac{x-\mu}{\sigma}.$$
$z$점수로 변환한 후, 정규표 또는 기술을 사용하여 값 아래, 위, 혹은 사이의 비율(면적) 을 구하고, 역으로 주어진 백분위수에서 값을 구할 수 있습니다.

연습 문제. 시험 점수가 $\mu=500$과 $\sigma=100$인 정규 분포를 따릅니다. 점수 $700$은 $z=\dfrac{700-500}{100}=2$에 해당합니다. 경험칙에 따라, 점수의 $95\%$가 $2\sigma$ 내에 위치하므로, $2.5\%$은 $700$ 위에 있습니다 – 즉, $700$은 약 $97.5$퍼센타일에 해당합니다.

정규 곡선과 68-95-99.7 경험칙
정규 곡선과 68-95-99.7 경험則
Explore · ⁨탐색하기⁩

Explore area under the normal curve · ⁨표준 정규 곡선 하방의 면적을 탐구하기⁩

The proportion of data below a value equals the area under the curve to its left. Shade a tail or a central band to see the 68–95–99.7 empirical rule and read a $z$-score as an area. · ⁨특정 값보다 작은 데이터의 비율(proportion) 은 해당 값 왼쪽의 곡선 하방 면적과 같습니다. 꼬리(tail)나 중앙 대역을 채색하여 68–95–99.7 경험 법칙을 보고 $z$-점수(z-score) 를 면적으로 읽으십시오.⁩

Vocabulary · ⁨어휘⁩ Train · ⁨연습하기⁩
English 한국어
normal distribution/ˈnɔːml ˌdɪstrɪˈbjuːʃn/ 표준정규분포
empirical rule/emˈpɪrɪkl ruːl/ 경험적 규칙
$z$-score/ˈzed skɔː/ z-점수($z$-score)
1.10

Exam tips · ⁨시험 팁⁩

English
  • Describe a distribution by shape, center, spread, and outliers (SOCS) — always in context.
  • The mean is pulled by outliers; the median resists them, so prefer the median for skewed data.
  • For a normal distribution use the 68–95–99.7 rule and z-scores $z=\tfrac{x-\mu}{\sigma}$.
  • Compare distributions with side-by-side boxplots and comment on center, spread, and shape.
  • Standard deviation measures a typical distance from the mean; the IQR pairs with the median.
한국어
  • 분포를 形态, 중심, 분산, 이상치(SOCS) 로 서술하십시오 – 항상 문맥에서.
  • 평균은 이상치에 의해 끌리고, 중位数는 이를 견디므로 치우친 데이터에는 중位数를 선호하십시오.
  • 정규 분포에는 68–95–99.7 법칙과 z-score $z=\tfrac{x-\mu}{\sigma}$를 사용하십시오.
  • 나란히 배치된 박스플롯으로 분포를 비교하고 중심, 분산, 형태에 대해 논하시오.
  • 표준편차는 평균으로부터의 typical 거리를 측정하며, IQR은 중位数와 쌍을 이룹니다.

Interactive lessons on this topic · ⁨이 주제에 대한 인터랙티브 수업⁩

Work through it step by step, with instant-check exercises. · ⁨즉시 체크 기능 exercises를 통해 단계별로 진행하세요.⁩

Past Papers · ⁨과거 시험지⁩

More topics in AP Statistics · ⁨AP 통계학⁩ · ⁨AP Statistics · ⁨AP 통계학⁩ 내 추가 주제⁩

Log in or create account · ⁨로그인 또는 계정 만들기⁩

IGCSE, A-Level & AP