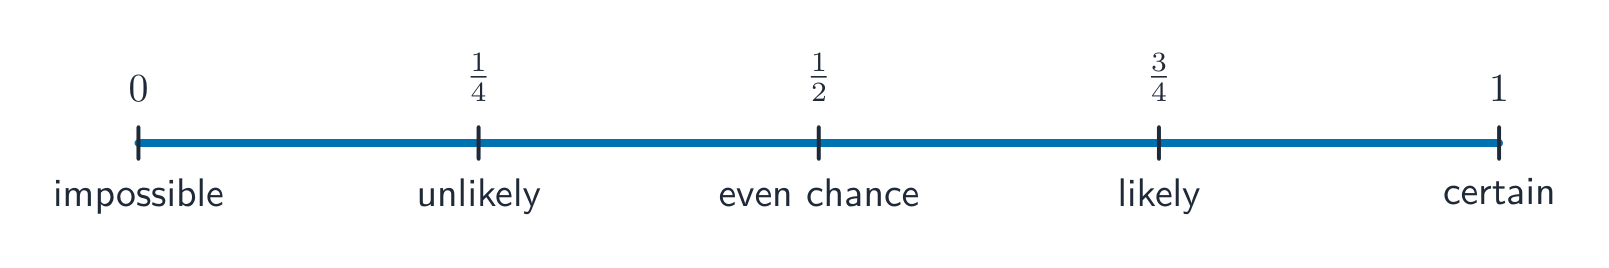Introducing Statistics: What Can We Learn from Data? · 통계 소개: 데이터를 통해 무엇을 알 수 있는가?
Syllabus
English
Enduring Understanding (VAR-1): Given that variation may be random or not, conclusions are uncertain.
Learning Objective VAR-1.A: Identify questions to be answered, based on variation in one-variable data. [Skill 1.A]
VAR-1.A.1 Numbers may convey meaningful information, when placed in context.
한국어
지속적 이해 (VAR-1): 변동성이 우연일 수도 있고 그렇지 않을 수도 있으므로, 결론은 불확실할 수 있다.
학습 목표 VAR-1.A: 단변량 데이터의 변동성을 기반으로 답해야 할 질문을 식별하시오. [Skill 1.A]
VAR-1.A.1 숫자는 맥락 속에 놓일 때 의미 있는 정보를 전달할 수 있다.
Source: College Board AP Course and Exam Description · 출처: College Board AP Course and Exam Description
English
Statistics 统计学 is the science of learning from data 数据 – numbers or labels collected from the real world. Data vary, so we describe patterns and account for the variation 变异 rather than expecting every value to match. A statistical question anticipates an answer based on data that vary.
Two distinctions run through the whole course. A parameter 参数 is a numerical summary of a whole population; a statistic 统计量 is a numerical summary of a sample - we use the statistic to estimate the parameter we cannot measure directly. And descriptive statistics 描述统计 only summarise the data set in hand, while inferential statistics 推断统计 use a sample to make and test claims about the larger population.
한국어
통계학은 현실 세계에서 수집한 데이터—숫자나 레이블—로부터 지식을 얻는 학문입니다. 데이터는 변동성을 가지므로, 모든 값이 일치하기를 기대하기보다 패턴을 서술하고 변동성을 고려해야 합니다. 통계학적 질문은 변동성을 가진 데이터에 기반하여 답을 예상합니다.
전 과정에 걸쳐 두 가지 구분이 존재합니다. 모수는 전체 집단의 수치적 요약이며, 통계량은 표본의 수치적 요약입니다. 직접 측정할 수 없는 모수를 추정하기 위해 통계량을 사용합니다. 또한 기술 통계는 현재数据处理 dataset만 요약하는 반면, 추론 통계는 표본을 사용하여 더 큰 집단에 대한 주장을 MADE하고 검증합니다.
The Language of Variation: Variables · 변동성의 언어: 변수
Syllabus
English
Enduring Understanding (VAR-1): Given that variation may be random or not, conclusions are uncertain.
Learning Objective VAR-1.B: Identify variables in a set of data. [Skill 2.A]
VAR-1.B.1 A variable is a characteristic that changes from one individual to another.
Learning Objective VAR-1.C: Classify types of variables. [Skill 2.A]
VAR-1.C.1 A categorical variable takes on values that are category names or group labels.
VAR-1.C.2 A quantitative variable is one that takes on numerical values for a measured or counted quantity.
Illustrative examples for VAR-1.C:
Categorical variables:
Dominant hand
Age group (young or old)
Highest degree earned
Quantitative variables:
Age of a structure
Height of a child
Concentration of a sample
한국어
지속적 이해 (VAR-1): 변동성이 우연일 수도 있고 그렇지 않을 수도 있으므로, 결론은 불확실할 수 있다.
학습 목표 VAR-1.B: 데이터 세트 내의 변수를 식별하시오. [Skill 2.A]
VAR-1.B.1 변수는 한 개인에서 다른 개인으로 달라지는 특성이다.
학습 목표 VAR-1.C: 변수의 유형을 분류하시오. [Skill 2.A]
VAR-1.C.1 범주형 변수(categorical variable)는 범주 명칭이나 그룹 라벨을 값으로 가진다.
VAR-1.C.2 정량 변수(quantitative variable)는 측정되거나 세어진 양의 수치적 값을 가지는 변수이다.
*VAR-1.C에 대한 예시:
범주형 변수:
우향(우손)
연령 그룹 (어른 또는 노인)
취득한 최고 학위
정량 변수:
구조물의 나이나 수명
아이의 키
시료의 농도
Source: College Board AP Course and Exam Description · 출처: College Board AP Course and Exam Description
English
A variable 变量 is a characteristic that can differ between individuals. Two kinds:
Categorical 分类 (qualitative): values are labels/groups (eye colour, brand).
Quantitative 定量: values are numbers you can do arithmetic on (height, age). Quantitative variables are discrete (countable) or continuous (measured).
Choosing the right graph and summary depends on which kind you have.
한국어
변수는 개인 간에 차이날 수 있는 특성입니다. 두 가지 유형:
분류형(질적): 값은 레이블/그룹입니다(눈 색, 브랜드).
정량형: 값은 산술 연산을 할 수 있는 숫자입니다(신장, 나이). 정량형 변수는 이산형(세어낼 수 있음) 또는 연속형(측정됨)입니다.
올바른 그래프와 요약 방법을 선택하는 것은 어떤 유형의 변수인지에 따라 달라집니다.
Explore · 탐색하기
Categorical or quantitative? · 범주형인지 정량형인지?
Every variable is either categorical (it labels each unit with a group) or quantitative (a measured number you can average). Which kind it is decides the graphs and summaries you are allowed to use. · 모든 변수는 범주형(categorical) (각 단위를 그룹으로 분류함)이거나 정량적(quantitative) (평균을 계산할 수 있는 측정된 숫자)입니다. 이 종류가 어떤 그래프와 요약 통계를 사용할 수 있는지 결정합니다.
1.3
Representing a Categorical Variable with Tables · 표를 이용한 분류형 변수 표현
Syllabus
English
Enduring Understanding (UNC-1): Graphical representations and statistics allow us to identify and represent key features of data.
Learning Objective UNC-1.A: Represent categorical data using frequency or relative frequency tables. [Skill 2.B]
UNC-1.A.1 A frequency table gives the number of cases falling into each category. A relative frequency table gives the proportion of cases falling into each category.
Learning Objective UNC-1.B: Describe categorical data represented in frequency or relative tables. [Skill 2.A]
UNC-1.B.1 Percentages, relative frequencies, and rates all provide the same information as proportions.
UNC-1.B.2 Counts and relative frequencies of categorical data reveal information that can be used to justify claims about the data in context.
한국어
지속적 이해(UNC-1): 그래프와 통계는 데이터의 핵심 특징을 식별하고 표현하는 데 도움을 준다.
학습 목표 UNC-1.A: 빈도표나 상대빈도표를 사용하여 범주형 데이터를 표현한다. [스킬 2.B]
UNC-1.A.1 빈도표는 각 범주에 속하는 사례의 수를 나타낸다. 상대빈도표는 각 범주에 속하는 사례의 비율을 나타낸다.
학습 목표 UNC-1.B: 빈도표나 상대빈도표로 표현된 범주형 데이터를 설명한다. [스킬 2.A]
UNC-1.B.1 백분율, 상대빈도 및 비율은 모두 비례에 대한 동일한 정보를 제공한다.
UNC-1.B.2 범주형 데이터의 빈도와 상대빈도는 해당 데이터에 대한 주장을 정당화하는 데 사용할 수 있는 정보를 드러낸다.
Source: College Board AP Course and Exam Description · 출처: College Board AP Course and Exam Description
English
A frequency table 频数表 lists each category's count (frequency); a relative frequency 相对频率 table lists each category's proportion 比例 (count ÷ total). Relative frequencies let you compare groups of different sizes fairly.
한국어
빈도 표는 각 범주의 개수(빈도)를 나열하며, 상대 빈도 표는 각 범주의 비율(개수 ÷ 총합)을 나열합니다. 상대 빈도는 서로 다른 크기의 그룹을 공평하게 비교할 수 있게 해줍니다.
1.4
Representing a Categorical Variable with Graphs · 그래프를 이용한 분류형 변수 표현
Syllabus
English
Enduring Understanding (UNC-1): Graphical representations and statistics allow us to identify and represent key features of data.
Learning Objective UNC-1.C: Represent categorical data graphically. [Skill 2.B]
UNC-1.C.1 Bar charts (or bar graphs) are used to display frequencies (counts) or relative frequencies (proportions) for categorical data.
UNC-1.C.2 The height or length of each bar in a bar graph corresponds to either the number or proportion of observations falling within each category.
UNC-1.C.3 There are many additional ways to represent frequencies (counts) or relative frequencies (proportions) for categorical data.
Learning Objective UNC-1.D: Describe categorical data represented graphically. [Skill 2.A]
UNC-1.D.1 Graphical representations of a categorical variable reveal information that can be used to justify claims about the data in context.
UNC-1.E.1 Frequency tables, bar graphs, or other representations can be used to compare two or more data sets in terms of the same categorical variable.
한국어
지속적 이해(UNC-1): 그래프와 통계는 데이터의 핵심 특징을 식별하고 표현하는 데 도움을 준다.
학습 목표 UNC-1.C: 범주형 데이터를 그래프로 표현한다. [스킬 2.B]
UNC-1.C.1 막대그래프(또는 막대 đồ)는 범주형 데이터의 빈도(개수)나 상대빈도(비율)를 표시하는 데 사용된다.
UNC-1.C.2 막대그래프에서 각 막대의 높이 또는 길이는 해당 범주에 속하는 관측값의 개수나 비율에 대응한다.
UNC-1.C.3 범주형 데이터의 빈도(개수)나 상대빈도(비율)를 표현하는还有许多 다른 방법이 있다.
학습 목표 UNC-1.D: 그래프로 표현된 범주형 데이터를 설명한다. [스킬 2.A]
UNC-1.D.1 범주형 변수의 그래프 표현은 해당 데이터에 대한 주장을 정당화하는 데 사용할 수 있는 정보를 드러낸다.
학습 목표 UNC-1.E: 여러 sets의 범주형 데이터를 비교한다. [스킬 2.D]
UNC-1.E.1 빈도표, 막대그래프 또는 다른 표현 방법을 사용하여 같은 범주형 변수에 대해 두 개 이상의 데이터 세트를 비교할 수 있다.
Source: College Board AP Course and Exam Description · 출처: College Board AP Course and Exam Description
English
Bar charts 条形图 show the count or proportion of each category as separated bars; a pie chart shows each category's share of the whole. The bar heights (or slices) let you compare categories at a glance. Bars may be ordered by size or by a natural category order.
한국어
막대그래프는 각 범주의 개수나 비율을 분리된 막대로 보여줍니다; 원그래프는 전체에 대한 각 범주의 비중을 보여줍니다. 막대 높이(또는 조각)를 통해 한눈에 범주를 비교할 수 있습니다. 막대는 크기 순이나 자연스러운 범주 순으로 배열될 수 있습니다.
Explore · 탐색하기
Show a categorical variable as a pie chart · 범주형 변수를 원그래프로 표시하기
A pie chart turns each category's share of the whole into a slice: a bigger share is a bigger slice, and every slice together makes 100%. It is a picture of a relative-frequency table. · 원그래프는 전체에 대한 각 범위의 비중을 조각으로 변환합니다: 비중이 클수록 조각도 크며, 모든 조각을 합하면 100%가 됩니다. 이는 상대 빈도 표의 시각화입니다.
1.5
Representing a Quantitative Variable with Graphs · 그래프를 이용한 정량형 변수 표현
Syllabus
English
Enduring Understanding (UNC-1): Graphical representations and statistics allow us to identify and represent key features of data.
Learning Objective UNC-1.F: Classify types of quantitative variables. [Skill 2.A]
UNC-1.F.1 A discrete variable can take on a countable number of values. The number of values may be finite or countably infinite, as with the counting numbers.
UNC-1.F.2 A continuous variable can take on infinitely many values, but those values cannot be counted. No matter how small the interval between two values of a continuous variable, it is always possible to determine another value between them.
Illustrative examples for UNC-1.F:
A discrete variable:
Number of students in a class
A continuous variable:
Height of a child
Learning Objective UNC-1.G: Represent quantitative data graphically. [Skill 2.B]
UNC-1.G.1 In a histogram, the height of each bar shows the number or proportion of observations that fall within the interval corresponding to that bar. Altering the interval widths can change the appearance of the histogram.
UNC-1.G.2 In a stem and leaf plot, each data value is split into a "stem" (the first digit or digits) and a "leaf" (usually the last digit).
UNC-1.G.3 A dotplot represents each observation by a dot, with the position on the horizontal axis corresponding to the data value of that observation, with nearly identical values stacked on top of each other.
UNC-1.G.4 A cumulative graph represents the number or proportion of a data set less than or equal to a given number.
UNC-1.G.5 There are many additional ways to graphically represent distributions of quantitative data.
한국어
지속적 이해(UNC-1): 그래프와 통계는 데이터의 핵심 특징을 식별하고 표현하는 데 도움을 준다.
학습 목표 UNC-1.F: 정량 변수의 유형을 분류한다. [스킬 2.A]
UNC-1.F.1 이산 변수는 세어낼 수 있는 수의 값을 가질 수 있다. 값의 수는 유한하거나 세어낼 수 있는 무한일 수 있으며, 자연수처럼 세는 경우와 같다.
UNC-1.F.2 연속 변수는 무한히 많은 값을 가질 수 있지만, 그 값들은 세어낼 수 없다. 연속 변수의 두 값 사이의 간격이 아무리 작더라도 항상 그 사이에 다른 값을 결정할 수 있다.
UNC-1.F에 대한 예시:
이산 변수:
한 반의 학생 수
연속 변수:
아이의 키
학습 목표 UNC-1.G: 정량 데이터를 그래프로 표현한다. [스킬 2.B]
UNC-1.G.1 히스토그램에서 각 막대의 높이는 해당 막대에 대응하는 구간에falling하는 관측값의 수나 비율을 보여준다. 구간 너비를 변경하면 히스토그램의 외관이 달라질 수 있다.
UNC-1.G.2 줄임말 Plot(stem and leaf plot)에서 각 데이터 값은 "줄기"(첫 번째 또는 몇 개의 숫자)와 "잎
UNC-1.G.3 도트 플롯(dotplot)은 각 관측치를 점(dot)으로 나타내며, 수평축上の 위치는 해당 관측치의 데이터 값에 대응하며, 거의 동일한 값들은 서로 겹쳐 쌓입니다.
UNC-1.G.4 누적 그래프(cumulative graph)는 주어진 숫자 이하인 데이터셋의 수나 비율을 나타냅니다.
UNC-1.G.5 정량적 데이터의 분포를 시각적으로 표현하는 다른 많은 방법들이 있습니다.
Source: College Board AP Course and Exam Description · 출처: College Board AP Course and Exam Description
English
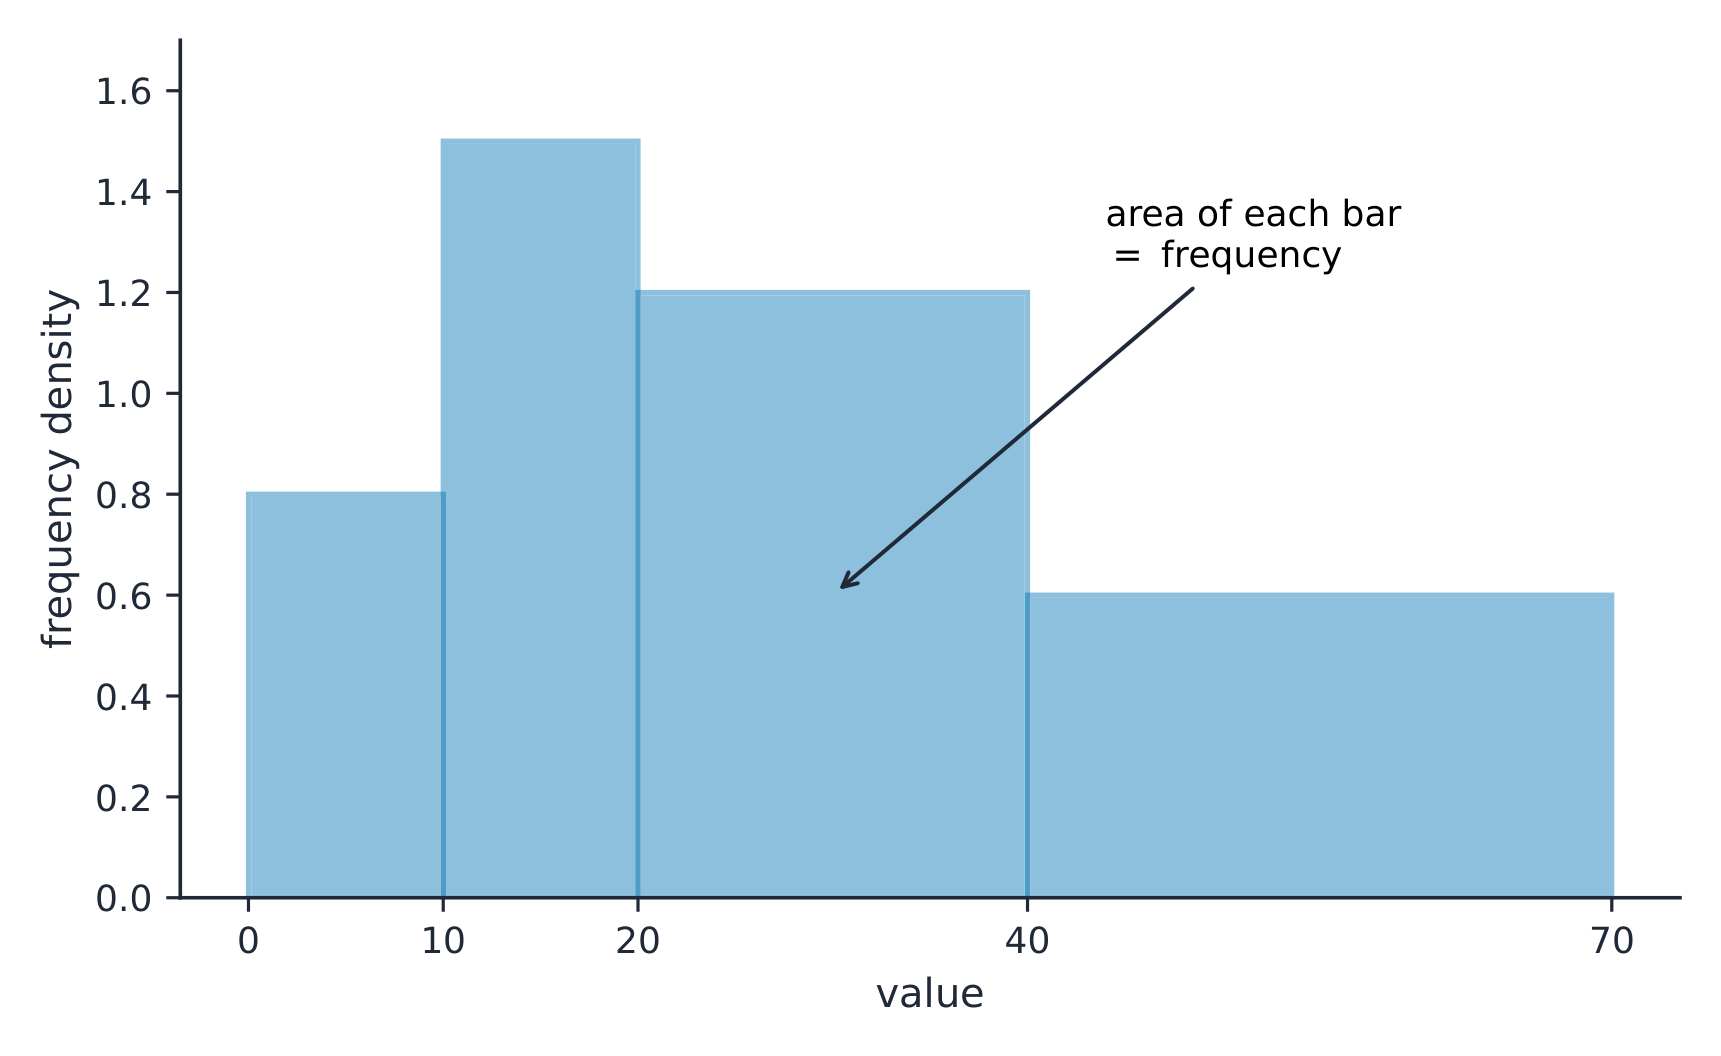
For numbers, use a dotplot 点图, stem-and-leaf plot 茎叶图, or histogram 直方图 (bars over value intervals called bins). These show the distribution 分布 – how the values spread out. A histogram's bin width changes the picture, so choose it to reveal the shape.
한국어
숫자의 경우 점도표, 줄임표, 또는 히스토그램(값 구간인 빈 위에 그은 막대)을 사용하십시오. 이들은 분포—값들이 어떻게 퍼져 있는지—를 보여줍니다. 히스토그램의 빈 폭은 그림을 바꾸므로, 형태를 드러내도록 적절히 선택하십시오.
불균등 계급폭 히스토그램에서 막대 면적은 빈도이다
Explore · 탐색하기
Explore how bin width shapes a histogram · 빈(bin) 너비가 히스토그램 형태를 어떻게 결정하는지 탐구하기
A histogram groups data into equal-width bins and draws a bar over each. Change the bins and notice how the same data can look jagged (too narrow) or smooth (too wide) — the shape is a choice. · 히스토그램은 데이터를 동일한 너비의 빈으로 묶고 각 빈 위에 막대를 그립니다. 빈을 변경하면 같은 데이터가 거칠게(너비 너무窄) 또는 매끄럽게(너비 너무 넓) 보이는 것을 관찰할 수 있습니다—형태는 선택의 결과입니다.
Describing the Distribution of a Quantitative Variable · 정량 변수의 분포 설명하기
Syllabus
English
Enduring Understanding (UNC-1): Graphical representations and statistics allow us to identify and represent key features of data.
Learning Objective UNC-1.H: Describe the characteristics of quantitative data distributions. [Skill 2.A]
UNC-1.H.1 Descriptions of the distribution of quantitative data include shape, center, and variability (spread), as well as any unusual features such as outliers, gaps, clusters, or multiple peaks.
UNC-1.H.2 Outliers for one-variable data are data points that are unusually small or large relative to the rest of the data.
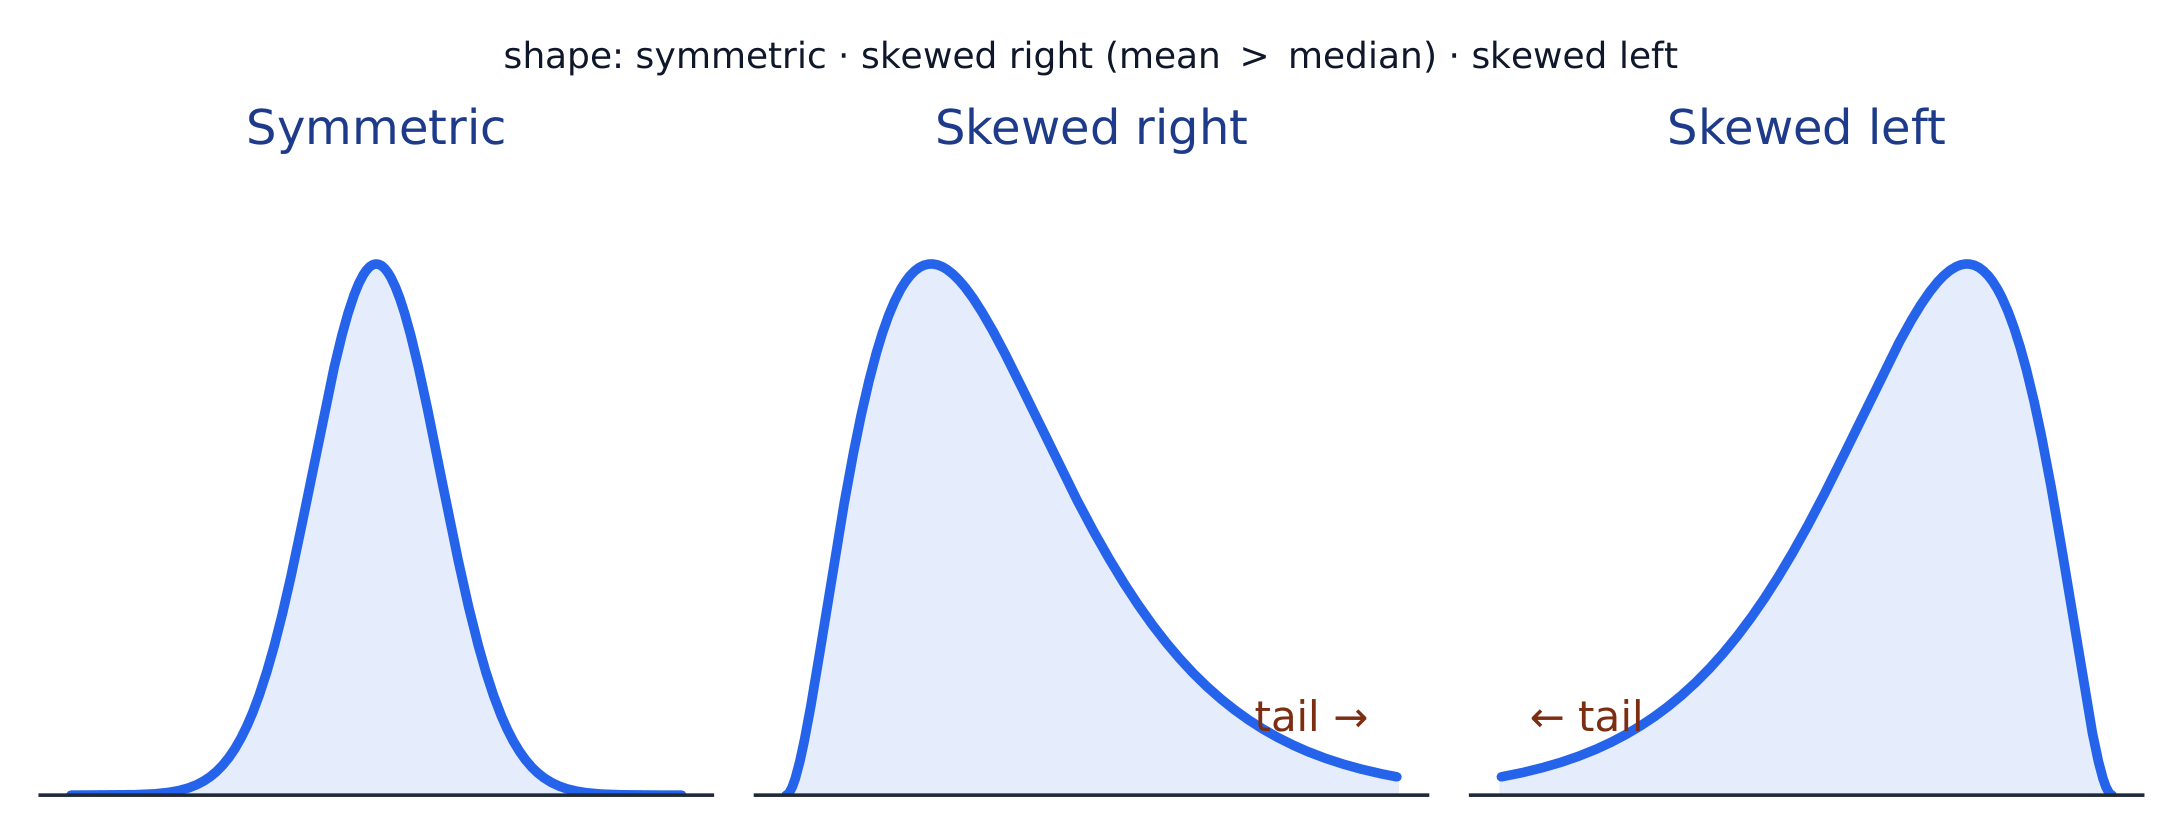
UNC-1.H.3 A distribution is skewed to the right (positive skew) if the right tail is longer than the left. A distribution is skewed to the left (negative skew) if the left tail is longer than the right. A distribution is symmetric if the left half is the mirror image of the right half.
UNC-1.H.4 Univariate graphs with one main peak are known as unimodal. Graphs with two prominent peaks are bimodal. A graph where each bar height is approximately the same (no prominent peaks) is approximately uniform.
UNC-1.H.5 A gap is a region of a distribution between two data values where there are no observed data.
UNC-1.H.6 Clusters are concentrations of data usually separated by gaps.
UNC-1.H.7 Descriptive statistics does not attribute properties of a data set to a larger population, but may provide the basis for conjectures for subsequent testing.
한국어
지속적 이해(UNC-1): 그래프와 통계는 데이터의 핵심 특징을 식별하고 표현하는 데 도움을 준다.
학습 목표 UNC-1.H: 정량 데이터 분포의 특성을 설명하십시오. [기술 2.A]
UNC-1.H.1 정량적 데이터의 분포를 설명하는 요소로는 형태, 중심, 변이도(확산)뿐만 아니라 이상치, 간격, 클러스터 또는 여러 개의 봉우리와 같은 비정상적인 특징이 포함됩니다.
UNC-1.H.2 단변량 데이터의 이상치는 다른 데이터와 비교해 비정상적으로 작거나 큰 값입니다.
UNC-1.H.3 분포에서 오른쪽 꼬리가 왼쪽 꼬리보다 길면 우편향(양수 치우침)이라고 합니다. 반대로 왼쪽 꼬리가 오른쪽 꼬리보다 길면 좌편향(음수 치우침)이라고 합니다. 양쪽 절반이 서로 거울상 대칭을 이룰 때 분포는 대칭이라고 합니다.
UNC-1.H.4 단일 봉우리를 가진 단변량 그래프를 일봉형(unimodal)이라 합니다. 두 개의 뚜렷한 봉우리를 가진 그래프를 이봉형(bimodal)이라 합니다. 각 막대 높이가 거의 동일하여 뚜렷한 봉우리가 없는 그래프는 근사 균일(non-uniformity)합니다.
UNC-1.H.5 간격(gap)은 관측된 데이터가 없는 두 데이터 값 사이의 분포 영역입니다.
UNC-1.H.6 클러스터(cluster)는 일반적으로 간격에 의해 분리된 데이터의 집중 영역입니다.
UNC-1.H.7 서술 통계는 데이터셋의 속성을 더 큰 집단에 귀속시키지 않지만, 후속 검증을 위한 추론의 기초를 제공할 수 있습니다.
Source: College Board AP Course and Exam Description · 출처: College Board AP Course and Exam Description
English
Describe four things (remember SOCS):
Shape 形状: symmetric, or skewed 偏斜 left/right (a long tail on that side), and how many peaks - one main peak is unimodal 单峰, two prominent peaks bimodal 双峰, and roughly equal bars uniform 均匀.
Outliers 离群值: unusual values far from the rest.
Center: a typical value (mean or median).
Spread: how much the values vary (range, IQR, standard deviation).
Always describe shape/center/spread in context, with units.
한국어
네 가지 사항(SOCS를 기억하세요)을 서술하십시오:
모양: 대칭이거나 왜도가 왼쪽/오른쪽인 경우(해당 쪽으로 긴 꼬리), 그리고 봉우리가 몇 개인지 – 주요 봉우리가 하나인 것은 단봉, 두 개의 뚜렷한 봉우는 이봉, 막대 높이가 거의 동일한 것은 균일합니다.
Summary Statistics for a Quantitative Variable · 정량 변수에 대한 요약 통계량
Syllabus
Enduring Understanding
Learning Objective
Essential Knowledge
UNC-1
Graphical representations and statistics allow us to identify and represent key features of data.
UNC-1.I
Calculate measures of center and position for quantitative data. [Skill 2.C]
UNC-1.I.1 A statistic is a numerical summary of sample data.
UNC-1.I.2 The mean is the sum of all the data values divided by the number of values. For a sample, the mean is denoted by $x$-bar: $\bar{x} = \dfrac{1}{n}\sum_{i=1}^{n} x_i$, where $x_i$ represents the $i^{\text{th}}$ data point in the sample and $n$ represents the number of data values in the sample.
UNC-1.I.3 The median of a data set is the middle value when data are ordered. When the number of data points is even, the median can take on any value between the two middle values. In AP Statistics, the most commonly used value for the median of a data set with an even number of values is the average of the two middle values.
UNC-1.I.4 The first quartile, Q1, is the median of the half of the ordered data set from the minimum to the position of the median. The third quartile, Q3, is the median of the half of the ordered data set from the position of the median to the maximum. Q1 and Q3 form the boundaries for the middle 50% of values in an ordered data set.
UNC-1.I.5 The $p^{\text{th}}$ percentile is interpreted as the value that has $p\%$ of the data less than or equal to it.
UNC-1.J
Calculate measures of variability for quantitative data. [Skill 2.C]
UNC-1.J.1 Three commonly used measures of variability (or spread) in a distribution are the range, interquartile range, and standard deviation.
UNC-1.J.2 The range is defined as the difference between the maximum data value and the minimum data value. The interquartile range (IQR) is defined as the difference between the third and first quartiles: $Q3 - Q1$. Both the range and the interquartile range are possible ways of measuring variability of the distribution of a quantitative variable.
UNC-1.J.3 Standard deviation is a way to measure variability of the distribution of a quantitative variable. For a sample, the standard deviation is denoted by $s$: $s_x = \sqrt{\dfrac{1}{n-1}\sum(x_i - \bar{x})^2}$. The square of the sample standard deviation, $s^2$, is called the sample variance.
UNC-1.J.4 Changing units of measurement affects the values of the calculated statistics.
UNC-1.K
Explain the selection of a particular measure of center and/or variability for describing a set of quantitative data. [Skill 4.B]
UNC-1.K.1 There are many methods for determining outliers. Two methods frequently used in this course are:
UNC-1.K.1.i An outlier is a value greater than $1.5 \times \text{IQR}$ above the third quartile or more than $1.5 \times \text{IQR}$ below the first quartile.
UNC-1.K.1.ii An outlier is a value located 2 or more standard deviations above, or below, the mean.
UNC-1.K.2 The mean, standard deviation, and range are considered nonresistant (or non-robust) because they are influenced by outliers. The median and IQR are considered resistant (or robust), because outliers do not greatly (if at all) affect their value.
Source: College Board AP Course and Exam Description · 출처: College Board AP Course and Exam Description
English
Standard deviation: spread about the mean
Center: the mean 均值$\bar{x}=\dfrac{\sum x_i}{n}$ (average) and the median 中位数 (middle value). The median resists outliers; the mean is pulled toward a skew.
Spread: the range, the interquartile range 四分位距$\text{IQR}=Q_3-Q_1$ (middle 50%), and the standard deviation 标准差$s_x=\sqrt{\dfrac{\sum(x_i-\bar{x})^2}{n-1}}$ (typical distance from the mean; its square is the variance 方差).
The five-number summary 五数概括: min, $Q_1$, median, $Q_3$, max.
Use resistant measures (median, IQR) for skewed data; mean and standard deviation for roughly symmetric data.
The percentile 百分位数 of a value is the percent of the data at or below it – so the median is the 50th percentile and $Q_1$ the 25th. A cumulative relative frequency graph 累积相对频率图 makes percentiles easy to read: for each value it plots the proportion of the data at or below it, rising from 0 to 1. Go up from a value to the curve and across to its percentile, or reverse the steps to find the value at a given percentile (the same reading works from a cumulative-frequency table).
Worked example. For the data $4, 8, 6, 10, 7$: the mean is $\bar{x}=\dfrac{4+8+6+10+7}{5}=\dfrac{35}{5}=7$. Sorting to $4,6,7,8,10$, the median is the middle value, $7$. The mean and median agree here because the data are roughly symmetric.
value의 백분위수(percentile) 는 해당 값 이하인 데이터의 비율입니다. 따라서 중位数는 50백분위수이고 $Q_1$는 25백분위수입니다. 누적 상대 빈도 그래프는 백분위수를 쉽게 읽을 수 있게 합니다: 각 value에 대해 그 값 이하인 데이터의 비례를 plot하며 0에서 1까지 상승합니다. value에서 위로 올라가 곡선에 도달한 후 백분위수로 이동하거나, 역순으로 진행하여 주어진 백분위수에 해당하는 value를 구할 수 있습니다(누적 빈도 표에서도 동일한 읽기법이 적용됩니다).
해설 예제. 데이터 $4, 8, 6, 10, 7$: 평균은 $\bar{x}=\dfrac{4+8+6+10+7}{5}=\dfrac{35}{5}=7$입니다. 정렬된 데이터 $4,6,7,8,10$에서 중位数는 가운데 값 $7$입니다. 데이터가 대칭에 가까워 평균과 중位数가 일치합니다.
cumulative relative frequency graph/ˈkjuːmjʊlətɪv ˈrelətɪv ˈfriːkwənsi ɡræf/
누적 상대 빈도 그래프(cumulative relative frequency graph)
1.8
Graphical Representations of Summary Statistics · 요약 통계량의 시각적 표현
Syllabus
Enduring Understanding
Learning Objective
Essential Knowledge
UNC-1
Graphical representations and statistics allow us to identify and represent key features of data.
UNC-1.L
Represent summary statistics for quantitative data graphically. [Skill 2.B]
UNC-1.L.1 Taken together, the minimum data value, the first quartile (Q1), the median, the third quartile (Q3), and the maximum data value make up the five-number summary.
UNC-1.L.2 A boxplot is a graphical representation of the five-number summary (minimum, first quartile, median, third quartile, maximum). The box represents the middle 50% of data, with a line at the median and the ends of the box corresponding to the quartiles. Lines ("whiskers") extend from the quartiles to the most extreme point that is not an outlier, and outliers are indicated by their own symbol beyond this.
UNC-1.M
Describe summary statistics of quantitative data represented graphically. [Skill 2.A]
UNC-1.M.1 Summary statistics of quantitative data, or of sets of quantitative data, can be used to justify claims about the data in context.
UNC-1.M.2 If a distribution is relatively symmetric, then the mean and median are relatively close to one another. If a distribution is skewed right, then the mean is usually to the right of the median. If the distribution is skewed left, then the mean is usually to the left of the median.
Source: College Board AP Course and Exam Description · 출처: College Board AP Course and Exam Description
English
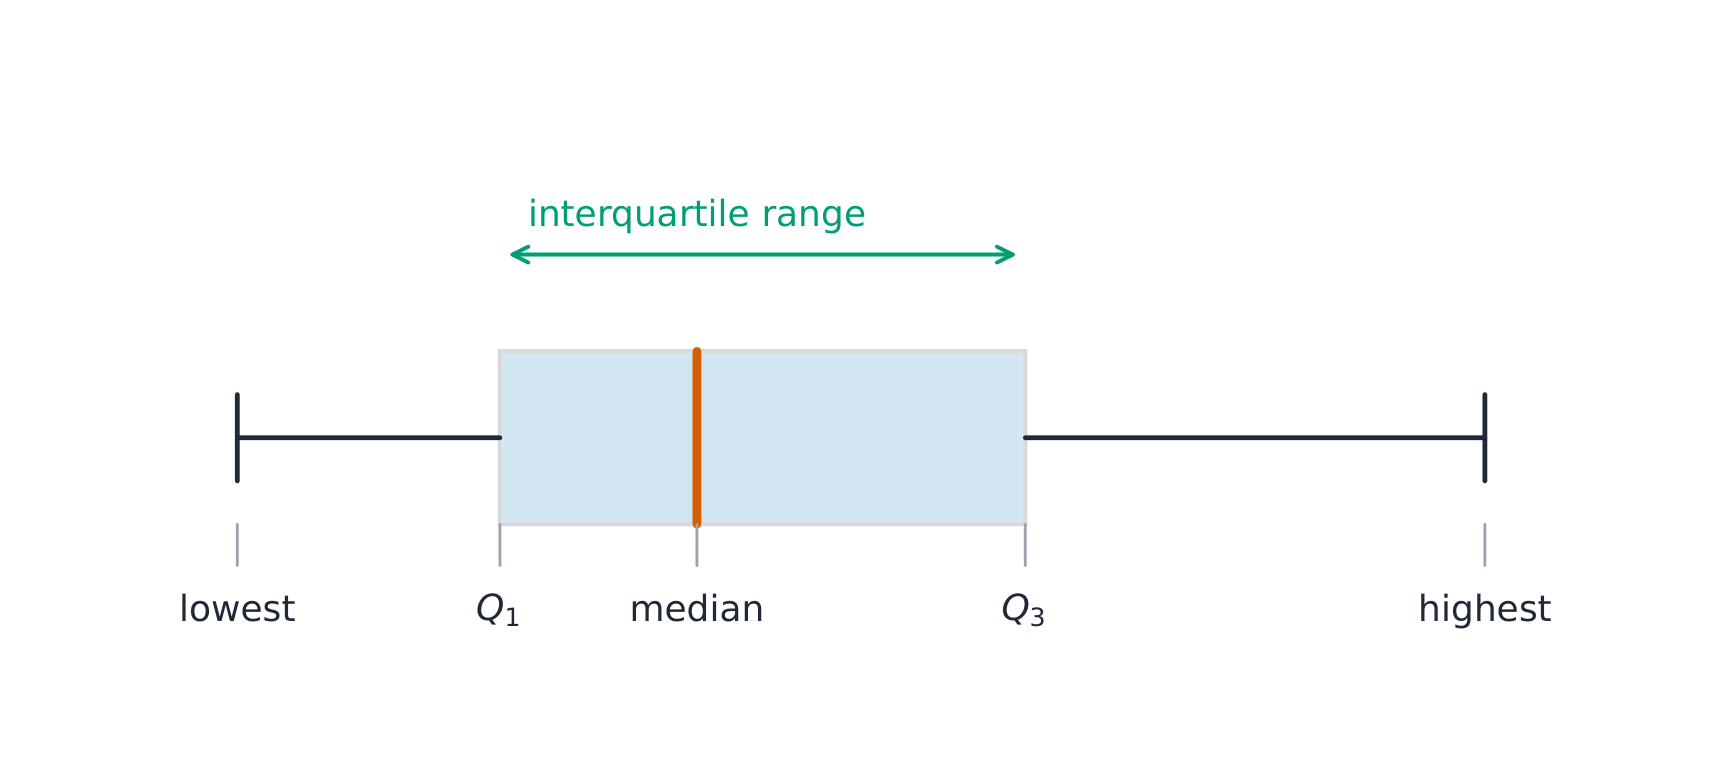
A boxplot 箱线图 draws the five-number summary: a box from $Q_1$ to $Q_3$ with the median inside, and whiskers to the most extreme non-outlier values. A point is an outlier if it lies more than $1.5\times\text{IQR}$ beyond a quartile – a rule you may be asked to apply. Boxplots are ideal for comparing several groups side by side.
Worked example. A dataset has $Q_1=20$ and $Q_3=32$, so $\text{IQR}=12$. The outlier fences are $Q_1-1.5(12)=2$ and $Q_3+1.5(12)=50$. Any value below $2$ or above $50$ is flagged as an outlier.
한국어
상자 whisker 도표는 오수 요약을 그립니다: $Q_1$에서 $Q_3$까지 상자를 그리며 중앙값을 내부에 넣고, 가장 극단적인 비외상치 값까지 whisker를 뻗습니다. 한 사분위로부터 $1.5\times\text{IQR}$ 이상 떨어져 있는 점은 외상치로 간주하며, 이를 적용하라는 요청을 받을 수 있습니다. 상자 whisker 도표는 여러 그룹을 나란히 비교하기에 적합합니다.
해설 예제. 데이터셋에 $Q_1=20$와 $Q_3=32$이 있으므로 $\text{IQR}=12$입니다. 이상치 경계(fences)는 $Q_1-1.5(12)=2$과 $Q_3+1.5(12)=50$입니다. $2$보다 작거나 $50$보다 큰 모든 값은 이상치로 표시됩니다.
상자-수염 도구는 사분위수와 범위를 보여줍니다박스플롯은 5개 수 요약을 그리며, 상자는 IQR 범위입니다
Explore · 탐색하기
Explore the five-number summary as a boxplot · 오수분위( Five-number summary )를 상자도형(boxplot)으로 탐구하기
Drag $Q_1$, the median, and $Q_3$ to see the box (its length is the IQR) and how the median's position inside the box reveals skew — a median close to $Q_1$ signals a right-skewed distribution. · $Q_1$인 **중위수(median)**와 $Q_3$을 드래그하여 상자를 보십시오(상자의 길이는 IQR입니다). 상자 안에서의 중위수 위치가 **편향(skew)**을 나타내는 방식을 확인하십시오—중위수가 $Q_1$에 가까우면 우측 치우친(right-skewed) 분포임을 시사합니다.
Comparing Distributions of a Quantitative Variable · 정량 변수의 분포 비교하기
Syllabus
English
Enduring Understanding (UNC-1): Graphical representations and statistics allow us to identify and represent key features of data.
Learning Objective UNC-1.N: Compare graphical representations for multiple sets of quantitative data. [Skill 2.D]
UNC-1.N.1 Any of the graphical representations, e.g., histograms, side-by-side boxplots, etc., can be used to compare two or more independent samples on center, variability, clusters, gaps, outliers, and other features.
Learning Objective UNC-1.O: Compare summary statistics for multiple sets of quantitative data. [Skill 2.D]
UNC-1.O.1 Any of the numerical summaries (e.g., mean, standard deviation, relative frequency, etc.) can be used to compare two or more independent samples.
한국어
지속적 이해(UNC-1): 그래프와 통계는 데이터의 핵심 특징을 식별하고 표현하는 데 도움을 준다.
학습 목표 UNC-1.N: 여러 정량적 데이터셋에 대한 그래프 표현을 비교하기. [기술 2.D]
UNC-1.N.1 히스토그램, 나란히 배치된 상자도 등 어떤 그래프 표현이라도 중심, 변동성, 무리(clusters), 간격(gaps), 이상치 및 기타 특징을 기준으로 두 개 이상의 독립 표본을 비교하는 데 사용할 수 있다.
학습 목표 UNC-1.O: 여러 정량적 데이터셋의 요약 통계량을 비교하기. [기술 2.D]
UNC-1.O.1 평균, 표준편차, 상대 빈도 등 어떤 숫자 요약(mathematical summaries)이라도 두 개 이상의 독립 표본을 비교하는 데 사용할 수 있다.
Source: College Board AP Course and Exam Description · 출처: College Board AP Course and Exam Description
English
To compare two or more groups, compare shape, center, and spread, and mention outliers – always with comparative words ("Group A has a higher median than Group B") and in context. Do not just describe each group separately; make the comparison explicit.
한국어
두 개 이상의 그룹을 비교하려면 형태, 중심, 분산을 비교하고 이상치를 언급하십시오. 반드시 비교 용어(예: "그룹 A의 중位数가 그룹 B보다 **높다"")와 문맥을 포함해야 합니다. 각 그룹을 개별적으로 설명하는 데 그치지 말고, 비교를 명시적으로 하십시오.
Explore · 탐색하기
Compare distributions with box plots · 상자 그래프로 분포 비교하기
A box plot draws the five-number summary. Placing two box plots on the same scale compares their centre (median), spread (IQR = box width) and skew at a glance — the fair way to compare groups. · 상자 그래프는 오수 통계를 그립니다. 두 상자 그래프를 동일한 축 위에 배치하면 한눈에 중앙(중位数), 확산(IQR = 상자 너비) 및 편향을 비교할 수 있어, 집단 간 공정한 비교 방법입니다.
1.10
The Normal Distribution · 정규 분포
Syllabus
Enduring Understanding
Learning Objective
Essential Knowledge
VAR-2
The normal distribution can be used to represent some population distributions.
VAR-2.A
Compare a data distribution to the normal distribution model. [Skill 2.D]
VAR-2.A.1 A parameter is a numerical summary of a population.
VAR-2.A.2 Some sets of data may be described as approximately normally distributed. A normal curve is mound-shaped and symmetric. The parameters of a normal distribution are the population mean, $\mu$, and the population standard deviation, $\sigma$.
VAR-2.A.3 For a normal distribution, approximately 68% of the observations are within 1 standard deviation of the mean, approximately 95% of observations are within 2 standard deviations of the mean, and approximately 99.7% of observations are within 3 standard deviations of the mean. This is called the empirical rule.
VAR-2.A.4 Many variables can be modeled by a normal distribution.
Illustrative examples for VAR-2.A:
Variables that can be modeled by a normal distribution:
Body temperature
Weight of a loaf of bread
VAR-2.B
Determine proportions and percentiles from a normal distribution. [Skill 3.A]
VAR-2.B.1 A standardized score for a particular data value is calculated as (data value − mean)/(standard deviation), and measures the number of standard deviations a data value falls above or below the mean.
VAR-2.B.2 One example of a standardized score is a $z$-score, which is calculated as $z\text{-score} = \left(\dfrac{x_i - \mu}{\sigma}\right)$. A $z$-score measures how many standard deviations a data value is from the mean.
VAR-2.B.3 Technology, such as a calculator, a standard normal table, or computer-generated output, can be used to find the proportion of data values located on a given interval of a normally distributed random variable.
VAR-2.B.4 Given the area of a region under the graph of the normal distribution curve, it is possible to use technology, such as a calculator, a standard normal table, or computer-generated output, to estimate parameters for some populations.
VAR-2.C
Compare measures of relative position in data sets. [Skill 2.D]
VAR-2.C.1 Percentiles and $z$-scores may be used to compare relative positions of points within a data set or between data sets.
Source: College Board AP Course and Exam Description · 출처: College Board AP Course and Exam Description
English
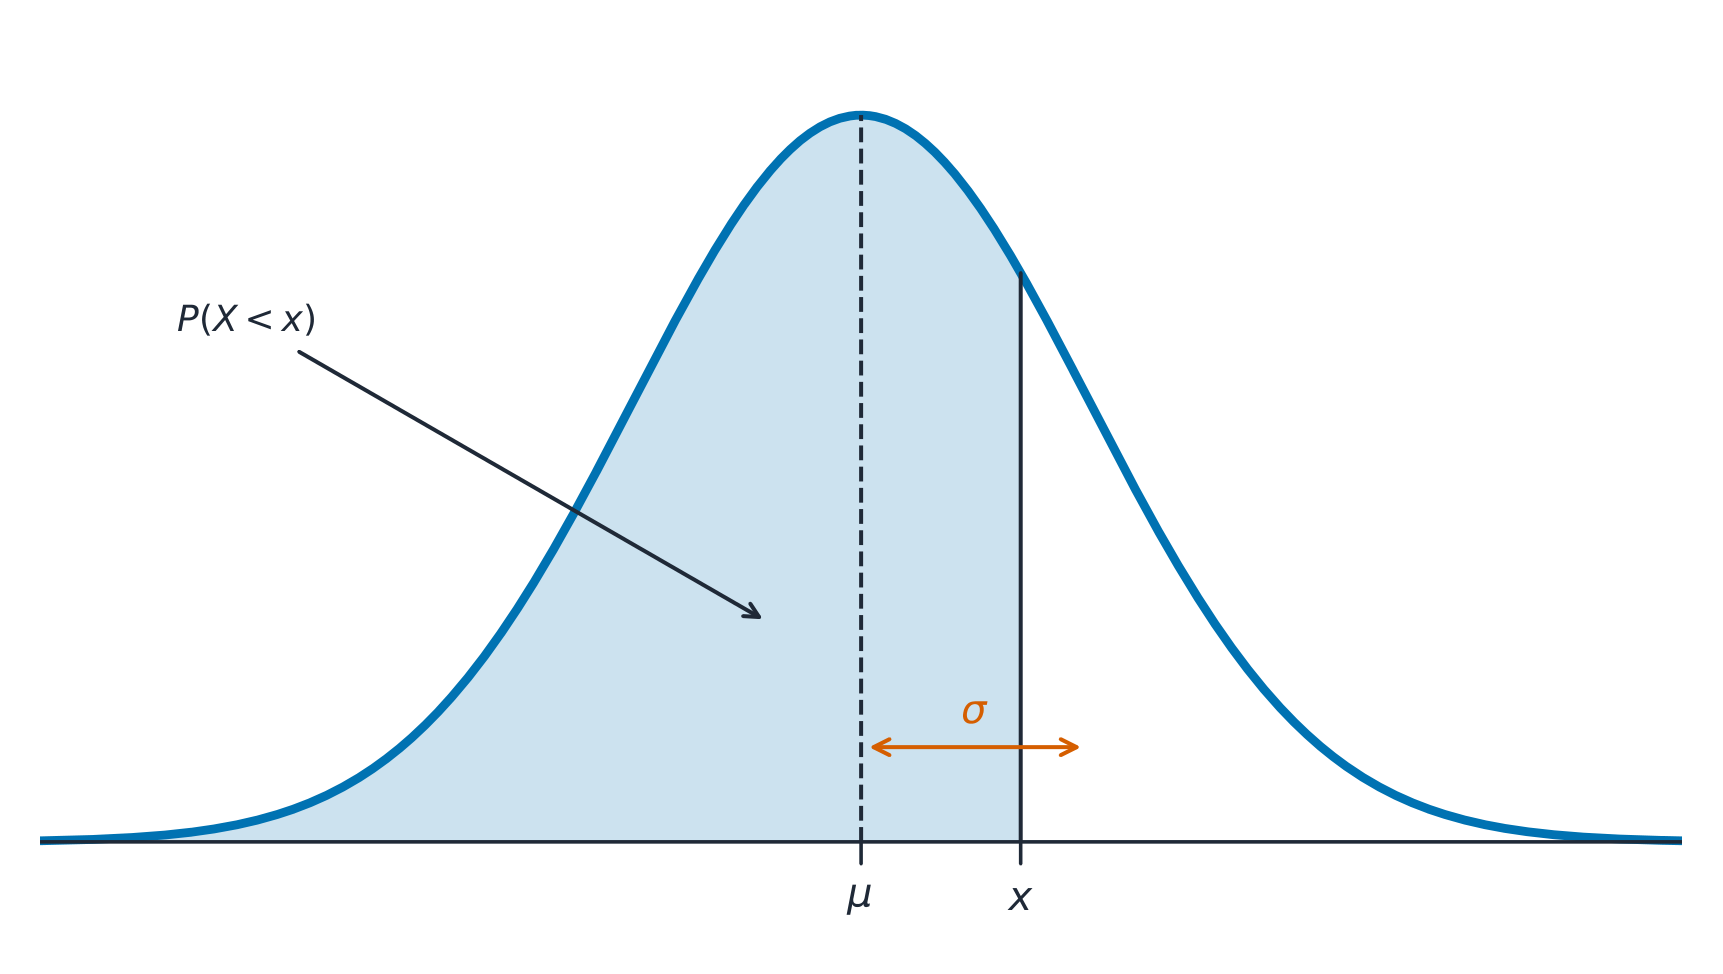
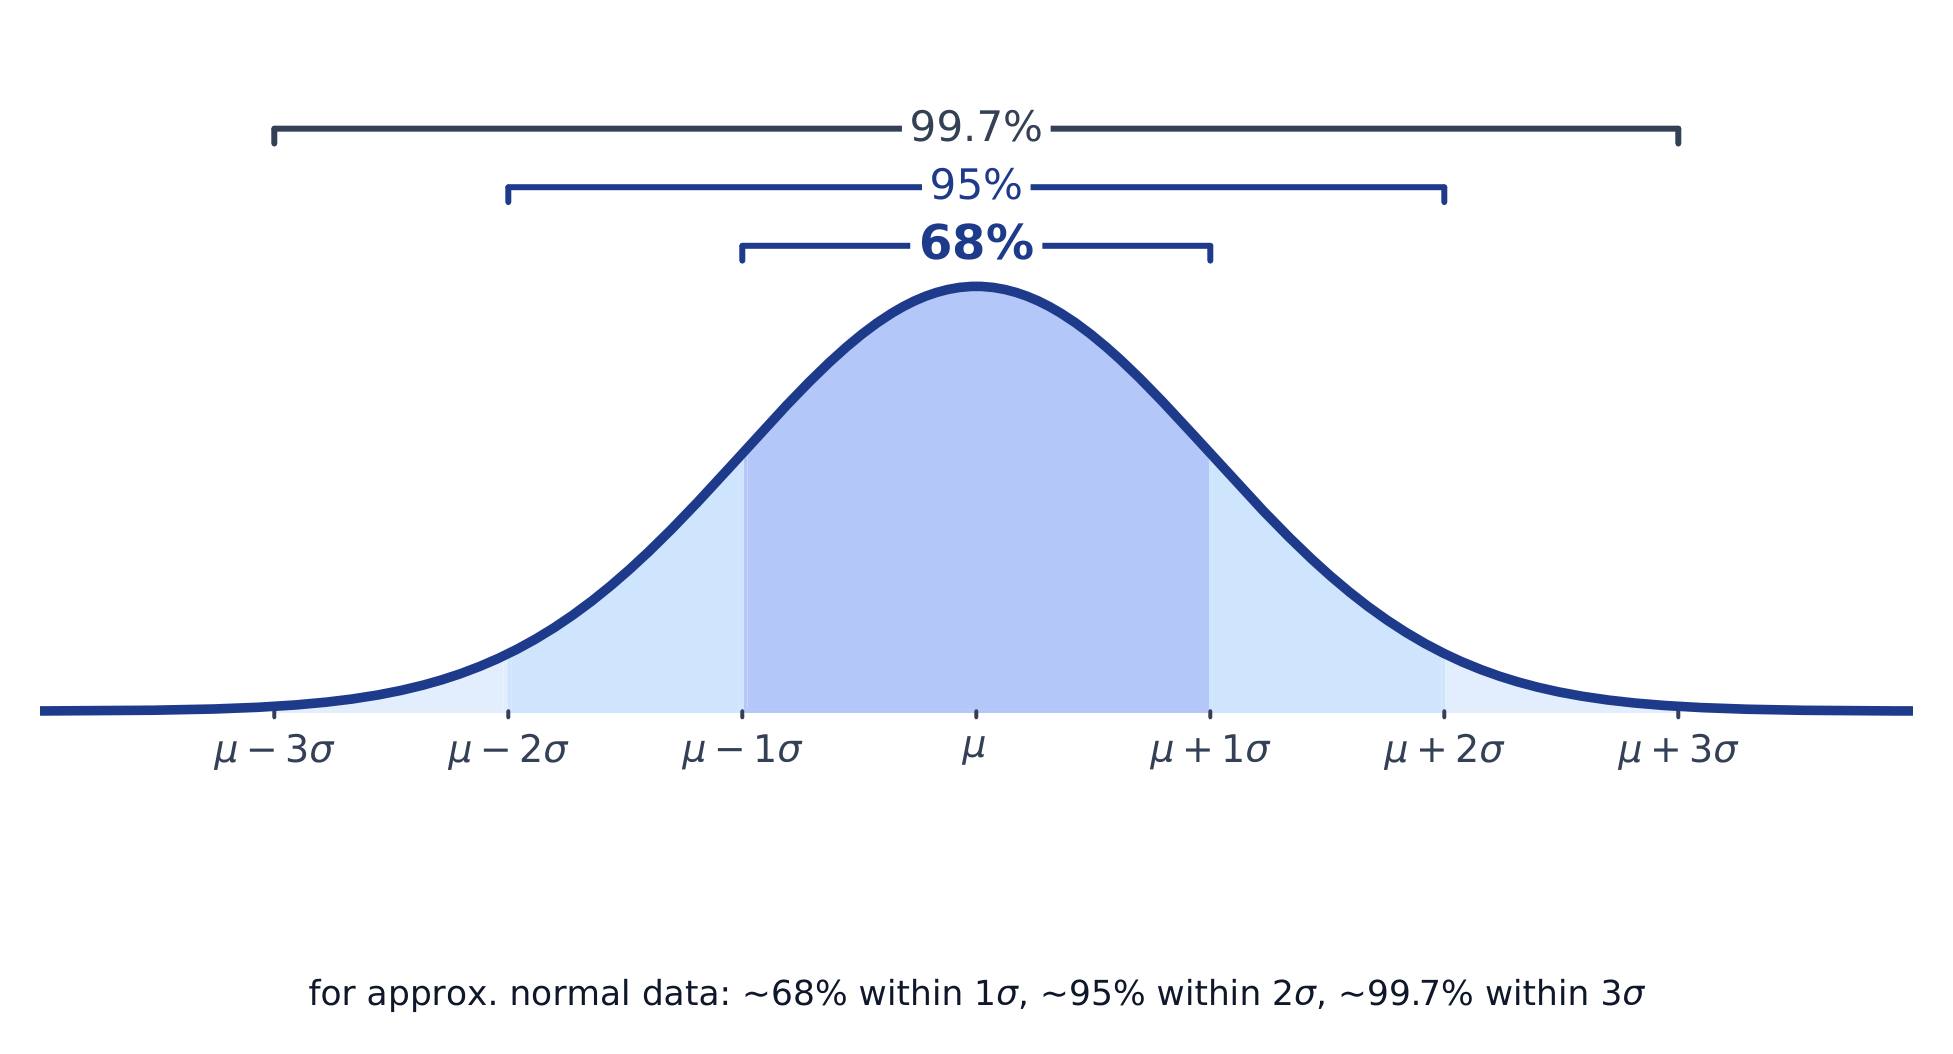
A normal distribution 正态分布 is a symmetric, bell-shaped model described by its mean $\mu$ and standard deviation $\sigma$. The empirical rule 经验法则 (68–95–99.7): about 68% of values lie within $1\sigma$ of the mean, 95% within $2\sigma$, and 99.7% within $3\sigma$.
A $z$-score 标准分数 measures how many standard deviations a value is from the mean:
$$z=\frac{x-\mu}{\sigma}.$$
Convert to a $z$-score, then use the normal table or technology to find the proportion (area) below, above, or between values – and reverse the process to find a value from a given percentile.
Worked example. Test scores are normal with $\mu=500$ and $\sigma=100$. A score of $700$ has $z=\dfrac{700-500}{100}=2$. By the empirical rule, $95\%$ of scores lie within $2\sigma$, so $2.5\%$ lie above $700$ – meaning a $700$ is at about the $97.5$th percentile.
한국어
정규 분포(normal distribution) 는 대칭적이고 종 모양이며, 평균 $\mu$와 표준편차 $\sigma$로 설명되는 모델입니다. 경험則(empirical rule, 68–95–99.7) : 값의 약 68%는 평균으로부터 $1\sigma$ 이내, 95%는 $2\sigma$ 이내, 99.7%는 $3\sigma$ 이내에 위치합니다.
표준 정규 곡선: 평균을 중심으로 한 곡선 아래 면적이 확률
$z$점수는 값이 평균으로부터 표준편차 몇 개나 떨어져 있는지 측정합니다:
$$z=\frac{x-\mu}{\sigma}.$$
$z$점수로 변환한 후, 정규표 또는 기술을 사용하여 값 아래, 위, 혹은 사이의 비율(면적) 을 구하고, 역으로 주어진 백분위수에서 값을 구할 수 있습니다.
연습 문제. 시험 점수가 $\mu=500$과 $\sigma=100$인 정규 분포를 따릅니다. 점수 $700$은 $z=\dfrac{700-500}{100}=2$에 해당합니다. 경험칙에 따라, 점수의 $95\%$가 $2\sigma$ 내에 위치하므로, $2.5\%$은 $700$ 위에 있습니다 – 즉, $700$은 약 $97.5$퍼센타일에 해당합니다.
정규 곡선과 68-95-99.7 경험則
Explore · 탐색하기
Explore area under the normal curve · 표준 정규 곡선 하방의 면적을 탐구하기
The proportion of data below a value equals the area under the curve to its left. Shade a tail or a central band to see the 68–95–99.7 empirical rule and read a $z$-score as an area. · 특정 값보다 작은 데이터의 비율(proportion) 은 해당 값 왼쪽의 곡선 하방 면적과 같습니다. 꼬리(tail)나 중앙 대역을 채색하여 68–95–99.7 경험 법칙을 보고 $z$-점수(z-score) 를 면적으로 읽으십시오.
Enduring Understanding (VAR-1): Given that variation may be random or not, conclusions are uncertain.
Learning Objective VAR-1.D: Identify questions to be answered about possible relationships in data. [Skill 1.A]
VAR-1.D.1 Apparent patterns and associations in data may be random or not.
한국어
지속적 이해 (VAR-1): 변동성이 우연일 수도 있고 그렇지 않을 수도 있으므로, 결론은 불확실할 수 있다.
학습 목표 VAR-1.D: 데이터 내 잠재적 관계에 대해 답해야 할 질문을 식별하기. [기술 1.A]
VAR-1.D.1 데이터에서 관찰되는 패턴과_passociation(상관관계)은 우연일 수도 있고 아닐 수도 있다.
Source: College Board AP Course and Exam Description · 출처: College Board AP Course and Exam Description
Two-variable data let us ask whether two characteristics are associated 关联 – whether knowing one tells you something about the other. An explanatory variable 解释变量 (the "input") may help predict a response variable 响应变量 (the "output"). Association is not the same as causation.
Enduring Understanding (UNC-1): Graphical representations and statistics allow us to identify and represent key features of data.
Learning Objective UNC-1.P: Compare numerical and graphical representations for two categorical variables. [Skill 2.D]
UNC-1.P.1 Side-by-side bar graphs, segmented bar graphs, and mosaic plots are examples of bar graphs for one categorical variable, broken down by categories of another categorical variable.
UNC-1.P.2 Graphical representations of two categorical variables can be used to compare distributions and/or determine if variables are associated.
UNC-1.P.3 A two-way table, also called a contingency table, is used to summarize two categorical variables. The entries in the cells can be frequency counts or relative frequencies.
UNC-1.P.4 A joint relative frequency is a cell frequency divided by the total for the entire table.
한국어
지속적 이해(UNC-1): 그래프와 통계는 데이터의 핵심 특징을 식별하고 표현하는 데 도움을 준다.
학습 목표 UNC-1.P: 두 범주형 변수에 대한 숫자 및 그래프 표현을 비교하기. [기술 2.D]
UNC-1.P.1 나란히 배치된 막대그래프, 분할 막대그래프, 모자이크 플롯(mosaic plots)은 하나의 범주형 변수에 대한 막대그래프 예시이며, 다른 하나의 범주형 변수의 범주로 세분화되어 있다.
UNC-1.P.2 두 범주형 변수의 그래프 표현은 분포를 비교하거나 변수들이_passociated(상관관계가 있음) 여부를 파악하는 데 사용될 수 있다.
UNC-1.P.3 이원 표, 또는 종속 표라고도 하며, 두 범주형 변수를 요약하는 데 사용됩니다. 셀의 값은 빈도 수 또는 상대 빈도가 될 수 있습니다.
UNC-1.P.4 결합 상대 빈도는 특정 셀의 빈도를 전체 표의 총합으로 나눈 값입니다.
Source: College Board AP Course and Exam Description · 출처: College Board AP Course and Exam Description
A two-way table 双向表 (contingency table) counts individuals by two categorical variables at once. A marginal distribution 边缘分布 is a row or column total written as a fraction of the grand total (the totals themselves are just counts). Comparing the inside cells shows whether the variables are related.
Enduring Understanding (UNC-1): Graphical representations and statistics allow us to identify and represent key features of data.
Learning Objective UNC-1.Q: Calculate statistics for two categorical variables. [Skill 2.C]
UNC-1.Q.1 The marginal relative frequencies are the row and column totals in a two-way table divided by the total for the entire table.
UNC-1.Q.2 A conditional relative frequency is a relative frequency for a specific part of the contingency table (e.g., cell frequencies in a row divided by the total for that row).
Learning Objective UNC-1.R: Compare statistics for two categorical variables. [Skill 2.D]
UNC-1.R.1 Summary statistics for two categorical variables can be used to compare distributions and/or determine if variables are associated.
한국어
지속적 이해(UNC-1): 그래프와 통계는 데이터의 핵심 특징을 식별하고 표현하는 데 도움을 준다.
학습 목표 UNC-1.Q: 두 범주형 변수에 대한 통계를 계산한다. [기술 2.C]
UNC-1.Q.1 경계 상대 빈도는 이원 표에서 행 및 열의 합을 전체 표의 총합으로 나눈 값입니다.
UNC-1.Q.2 조건부 상대 빈도는 종속 표의 특정 부분(예: 한 행의 셀 빈도를 해당 행의 총합으로 나눈 값)에 대한 상대 빈도입니다.
학습 목표 UNC-1.R: 두 범주형 변수에 대한 통계를 비교한다. [기술 2.D]
UNC-1.R.1 두 범주형 변수에 대한 요약 통계를 사용하여 분포를 비교하거나 변수 간 관련성이 있는지 판단할 수 있습니다.
Source: College Board AP Course and Exam Description · 출처: College Board AP Course and Exam Description
A conditional distribution 条件分布 is the distribution of one variable within a fixed category of the other (found by dividing each cell by its row or column total). If the conditional distributions differ across groups, the two variables are associated; if they are the same, there is no association. Segmented bar charts 分段条形图 or mosaic plots display them.
Enduring Understanding (UNC-1): Graphical representations and statistics allow us to identify and represent key features of data.
Learning Objective UNC-1.S: Represent bivariate quantitative data using scatterplots. [Skill 2.B]
UNC-1.S.1 A bivariate quantitative data set consists of observations of two different quantitative variables made on individuals in a sample or population.
UNC-1.S.2 A scatterplot shows two numeric values for each observation, one corresponding to the value on the $x$-axis and one corresponding to the value on the $y$-axis.
UNC-1.S.3 An explanatory variable is a variable whose values are used to explain or predict corresponding values for the response variable.
Enduring Understanding (DAT-1): Regression models may allow us to predict responses to changes in an explanatory variable.
Learning Objective DAT-1.A: Describe the characteristics of a scatter plot. [Skill 2.A]
DAT-1.A.1 A description of a scatter plot includes form, direction, strength, and unusual features.
DAT-1.A.2 The direction of the association shown in a scatterplot, if any, can be described as positive or negative.
DAT-1.A.3 A positive association means that as values of one variable increase, the values of the other variable tend to increase. A negative association means that as values of one variable increase, values of the other variable tend to decrease.
DAT-1.A.4 The form of the association shown in a scatterplot, if any, can be described as linear or non-linear to varying degrees.
DAT-1.A.5 The strength of the association is how closely the individual points follow a specific pattern, e.g., linear, and can be shown in a scatterplot. Strength can be described as strong, moderate, or weak.
DAT-1.A.6 Unusual features of a scatter plot include clusters of points or points with relatively large discrepancies between the value of the response variable and a predicted value for the response variable.
한국어
지속적 이해(UNC-1): 그래프와 통계는 데이터의 핵심 특징을 식별하고 표현하는 데 도움을 준다.
학습 목표 UNC-1.S: 산점도를 사용하여 이변량 정량 데이터를 표현한다. [기술 2.B]
UNC-1.S.1 이변량 정량 데이터는 표본이나 모집단의 개체에 대해 두 가지 다른 정량 변수에 대한 관측값으로 구성됩니다.
UNC-1.S.2 산점도는 각 관측값에 대해 두 개의 수치를 나타내며, 하나는 $x$축의 값에 대응하고 다른 하나는 $y$축의 값에 대응합니다.
UNC-1.S.3 설명 변수는 반응 변수의 대응 값을 설명하거나 예측하기 위해 사용되는 변수입니다.
지속적 이해 (DAT-1): 회귀 모델은 설명 변수의 변화에 대한 반응 예측을 가능하게 할 수 있습니다.
학습 목표 DAT-1.A: 산점도의 특징을 서술한다. [기술 2.A]
DAT-1.A.1 산점도의 서술에는 형태, 방향, 강도, 이상적인 특징이 포함됩니다.
DAT-1.A.2 산점도에 표시된 상관관계의 방향(있는 경우)은 양수 또는 음수로 서술할 수 있습니다.
DAT-1.A.3 양의 상관관계란 한 변수의 값이 증가함에 따라 다른 변수의 값도 증가하는 경향이 있음을 의미합니다. 음의 상관관계란 한 변수의 값이 증가함에 따라 다른 변수의 값이 감소하는 경향을 의미합니다.
DAT-1.A.4 산점도에 표시된 상관관계의 형태(있는 경우)는 선형이거나 비선형일 수 있으며, 그 정도가 다양합니다.
DAT-1.A.5 상관관계의 강도는 개별 점들이 특정 패턴(예: 선형)을 얼마나 밀접하게 따르는지를 나타내며 산점도로 확인할 수 있습니다. 강도는 강함, 중등함, 약함으로 서술할 수 있습니다.
DAT-1.A.6 산점도의 이상적인 특징으로는 점들의 클러스터나 반응 변수의 실제 값과 예측 값 사이의 차이가 상대적으로 큰 점 등이 있습니다.
Source: College Board AP Course and Exam Description · 출처: College Board AP Course and Exam Description
A scatterplot 散点图 plots each individual as a point, explanatory variable on the $x$-axis and response on the $y$-axis. Describe it with DUFS: Direction (positive/negative), Unusual features (outliers, clusters), Form (linear or curved), and Strength (how tightly the points follow the pattern) – always in context.
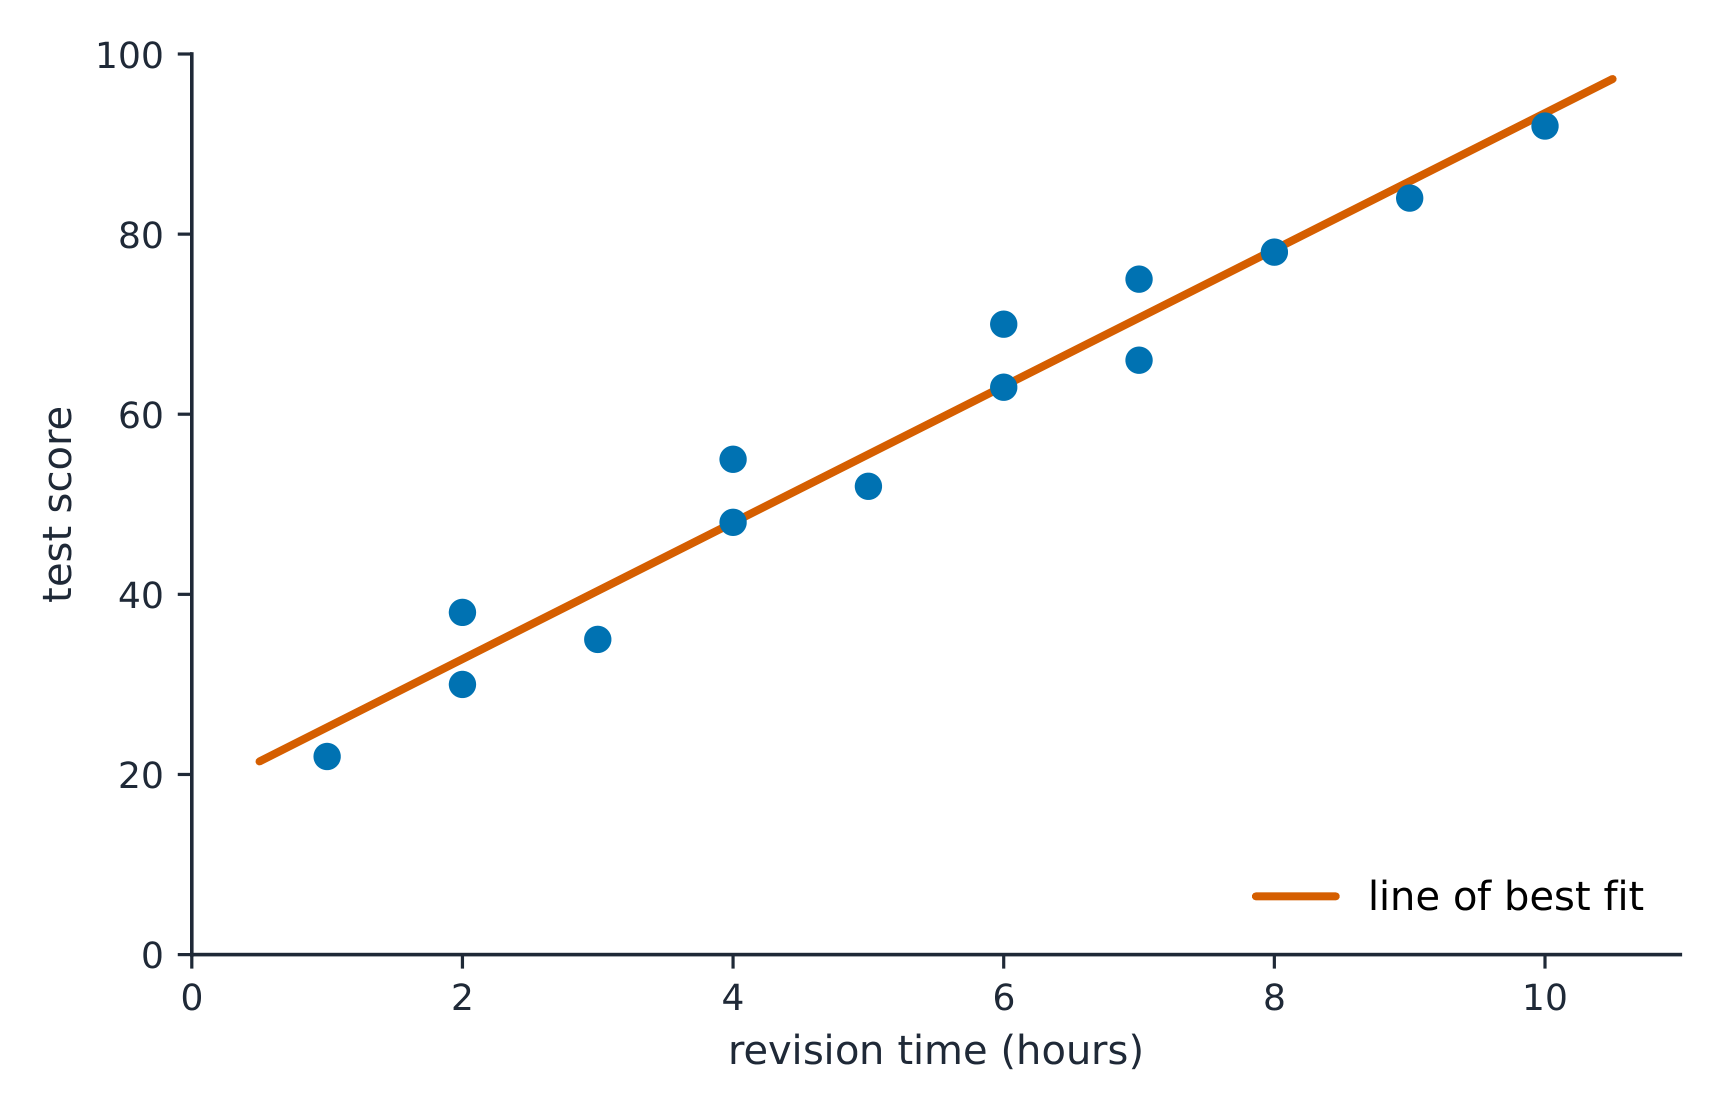
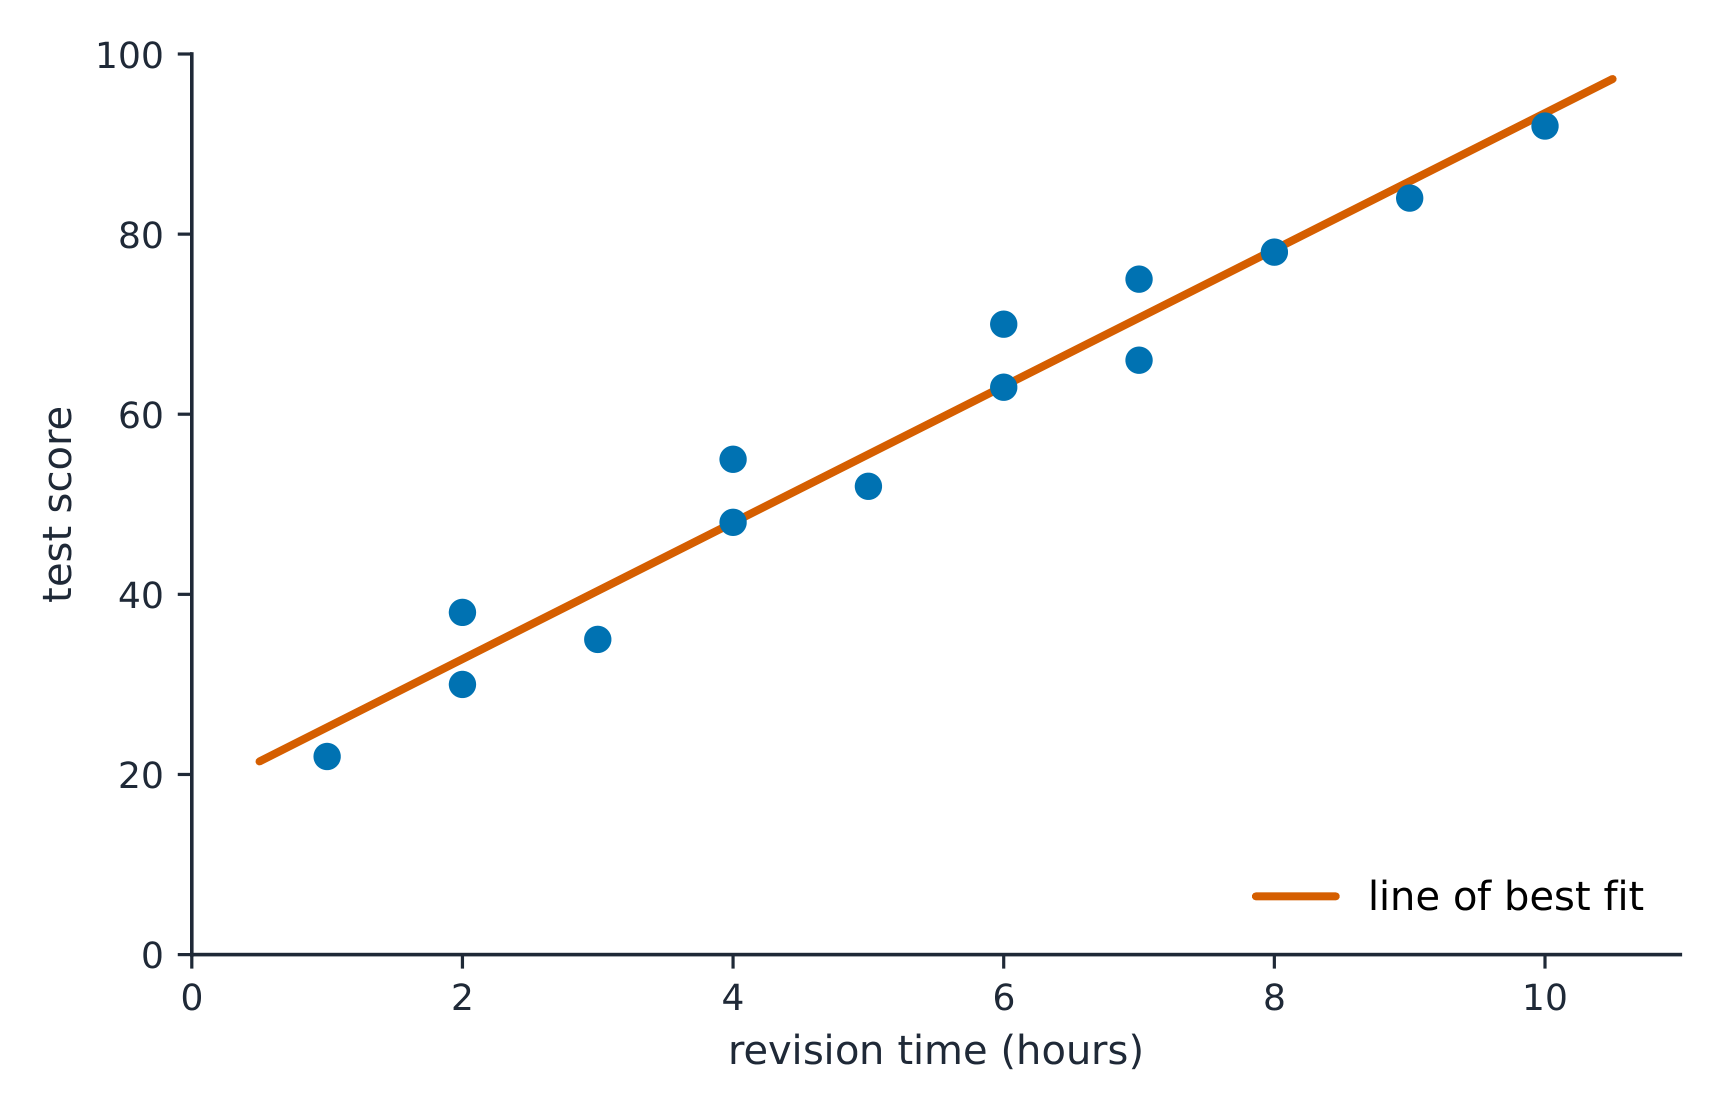
A line of best fit runs through the middle of the scattered points
Enduring Understanding (DAT-1): Regression models may allow us to predict responses to changes in an explanatory variable.
Learning Objective DAT-1.B: Determine the correlation for a linear relationship. [Skill 2.C]
DAT-1.B.1 The correlation, $r$, gives the direction and quantifies the strength of the linear association between two quantitative variables.
DAT-1.B.2 The correlation coefficient can be calculated by: $r = \dfrac{1}{n-1} \sum \left( \dfrac{x_i - \bar{x}}{s_x} \right) \left( \dfrac{y_i - \bar{y}}{s_y} \right)$. However, the most common way to determine $r$ is by using technology.
DAT-1.B.3 A correlation coefficient close to 1 or $-1$ does not necessarily mean that a linear model is appropriate.
Learning Objective DAT-1.C: Interpret the correlation for a linear relationship. [Skill 4.B]
DAT-1.C.1 The correlation, $r$, is unit-free, and always between $-1$ and 1, inclusive. A value of $r = 0$ indicates that there is no linear association. A value of $r = 1$ or $r = -1$ indicates that there is a perfect linear association.
DAT-1.C.2 A perceived or real relationship between two variables does not mean that changes in one variable cause changes in the other. That is, correlation does not necessarily imply causation.
한국어
지속적 이해 (DAT-1): 회귀 모델은 설명 변수의 변화에 대한 반응 예측을 가능하게 할 수 있습니다.
학습 목표 DAT-1.B: 선형 관계에 대한 상관계수를 결정한다. [기술 2.C]
DAT-1.B.1 상관계수 $r$는 두 정량 변수 간의 선형 상관관계의 방향을 나타내고 그 강도를 수치화합니다.
DAT-1.B.2 상관계수는 $r = \dfrac{1}{n-1} \sum \left( \dfrac{x_i - \bar{x}}{s_x} \right) \left( \dfrac{y_i - \bar{y}}{s_y} \right)$로 계산할 수 있습니다. 그러나 $r$를 결정하는 가장 일반적인 방법은 기술(software)을 사용하는 것입니다.
DAT-1.B.3 상관계수가 1 또는 $-1$에 가깝다고 해서 반드시 선형 모델이 적절한 것은 아닙니다.
학습 목표 DAT-1.C: 선형 관계에 대한 상관계수를 해석한다. [기술 4.B]
DAT-1.C.1 상관계수 $r$는 차원이 없으며, 항상 $-1$와 1 사이(포함)에 있습니다. 값이 $r = 0$인 경우 선형 상관관계가 없음을 의미하며, 값이 $r = 1$ 또는 $r = -1$인 경우 완벽한 선형 상관관계를 의미합니다.
DAT-1.C.2 두 변수 사이에 관찰되거나 실제로 존재하는 관계가 한 변수의 변화가 다른 변수의 변화를 유발한다는 것을 의미하지는 않습니다. 즉, 상관계수는 인과성을 반드시 함의하지는 않습니다.
Source: College Board AP Course and Exam Description · 출처: College Board AP Course and Exam Description
What r actually measures
The correlation coefficient 相关系数$r$ measures the strength and direction of a linear relationship. It runs from $-1$ to $1$: near $\pm 1$ is strong linear, near $0$ is weak linear. $r$ has no units and does not change if you swap the variables. Warnings: $r$ only measures linear strength, it is not resistant to outliers, and a strong $r$ does not prove causation.
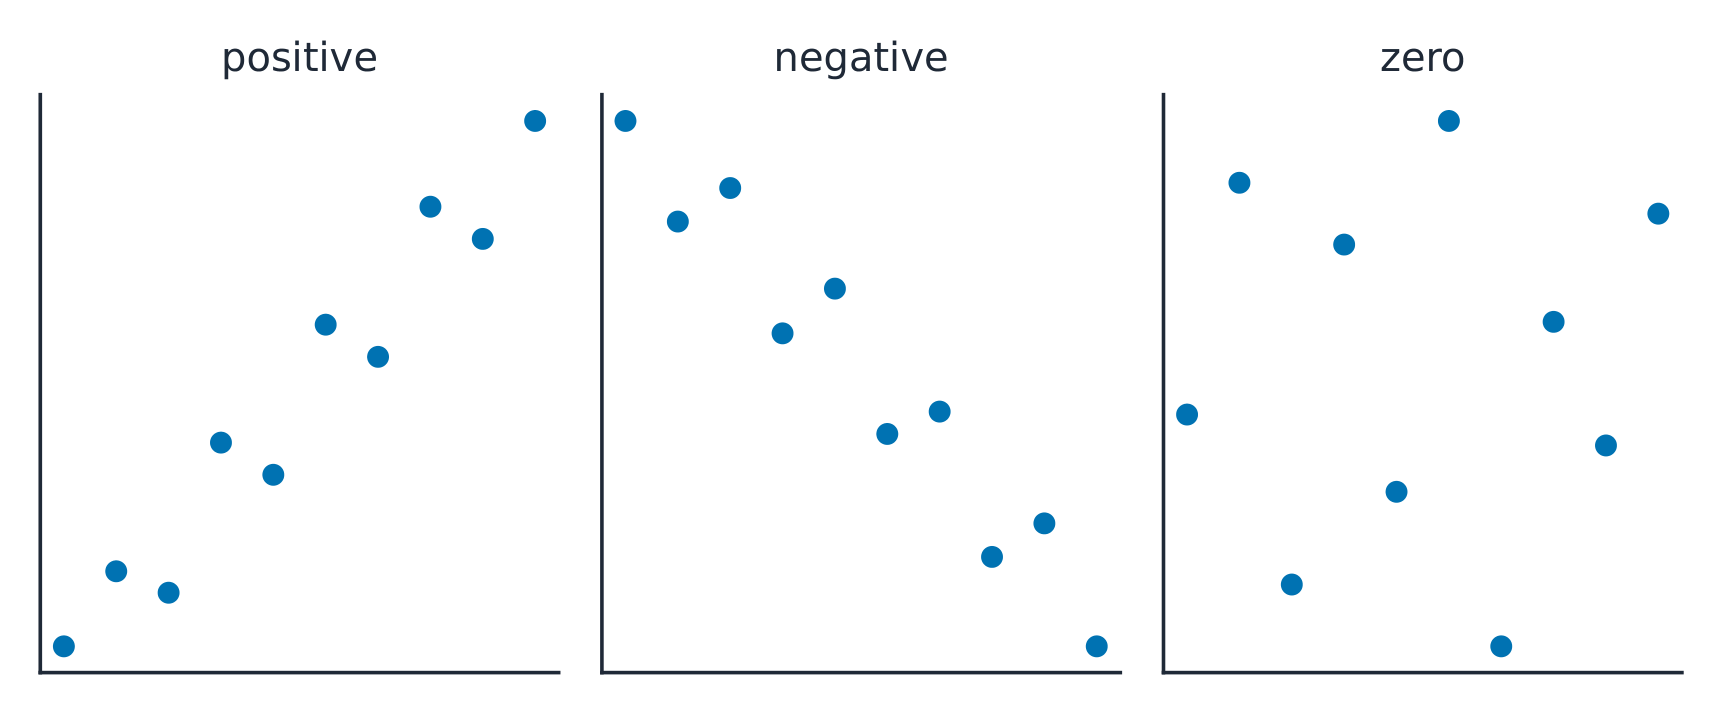
Positive correlation rises together; negative correlation moves in opposite directions
Explore · 탐색하기
Strength of a linear relationship
Correlation$r$ runs from $-1$ to $1$: near $\pm1$ the points hug a line, near 0 they scatter. Change it and watch the cloud tighten or spread.
DAT-1
Regression models may allow us to predict responses to changes in an explanatory variable.
DAT-1.D
Calculate a predicted response value using a linear regression model. [Skill 2.C]
DAT-1.D.1 A simple linear regression model is an equation that uses an explanatory variable, $x$, to predict the response variable, $y$.
DAT-1.D.2 The predicted response value, denoted by $\hat{y}$, is calculated as $\hat{y} = a + bx$, where $a$ is the $y$-intercept and $b$ is the slope of the regression line, and $x$ is the value of the explanatory variable.
DAT-1.D.3 Extrapolation is predicting a response value using a value for the explanatory variable that is beyond the interval of $x$-values used to determine the regression line. The predicted value is less reliable as an estimate the further we extrapolate.
Source: College Board AP Course and Exam Description · 출처: College Board AP Course and Exam Description
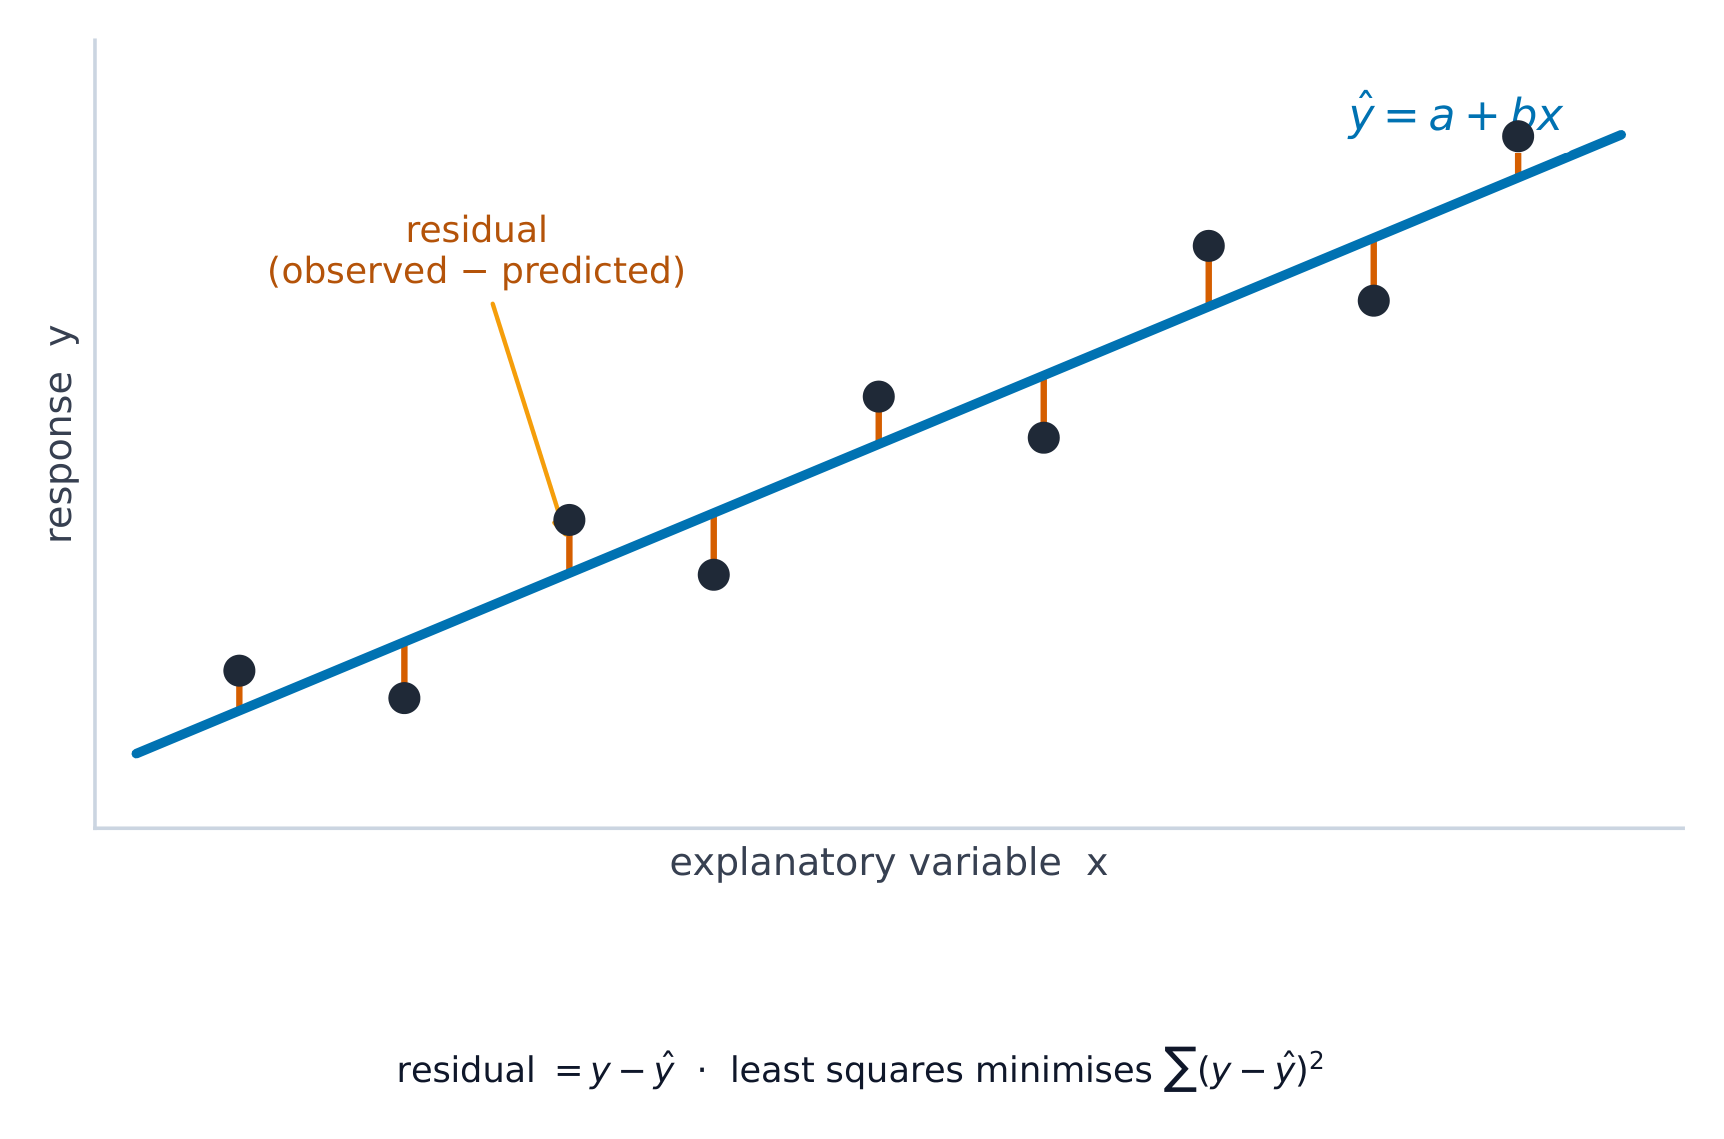
The least-squares regression line 最小二乘回归线 predicts the response: $\hat{y}=a+bx$, where $\hat{y}$ is the predicted response. The slope 斜率$b$ is the predicted change in $y$ per one-unit increase in $x$; the $y$-intercept 截距$a$ is the predicted $y$ when $x=0$. Interpret both in context and with units – a graded skill. Avoid extrapolation 外推 (predicting far outside the data).
Worked example. A study of hours studied ($x$) and test score ($y$) gives $\hat{y}=20+3x$. The slope means each extra hour of study is associated with a predicted $3$-point increase. A student who studies $5$ hours is predicted to score $\hat{y}=20+3(5)=35$.
Explore · 탐색하기
Fit a least-squares line
A regression line is the best straight-line fit, minimising the squared vertical distances. Its slope predicts how $y$ changes per unit of $x$.
Enduring Understanding (DAT-1): Regression models may allow us to predict responses to changes in an explanatory variable.
Learning Objective DAT-1.E: Represent differences between measured and predicted responses using residual plots. [Skill 2.B]
DAT-1.E.1 The residual is the difference between the actual value and the predicted value: $\text{residual} = y - \hat{y}$.
DAT-1.E.2 A residual plot is a plot of residuals versus explanatory variable values or predicted response values.
Learning Objective DAT-1.F: Describe the form of association of bivariate data using residual plots. [Skill 2.A]
DAT-1.F.1 Apparent randomness in a residual plot for a linear model is evidence of a linear form to the association between the variables.
DAT-1.F.2 Residual plots can be used to investigate the appropriateness of a selected model.
한국어
지속적 이해 (DAT-1): 회귀 모델은 설명 변수의 변화에 대한 반응 예측을 가능하게 할 수 있습니다.
학습 목표 DAT-1.E: 잔차 도표를 사용하여 측정된 값과 예측된 값 사이의 차이를 표현한다. [기술 2.B]
DAT-1.E.1 잔차는 실제 값과 예측된 값의 차이입니다: $\text{residual} = y - \hat{y}$.
DAT-1.E.2 잔차 도표는 잔차를 설명 변수의 값이나 예측된 반응 값에 대해 나타낸 그래프입니다.
학습 목표 DAT-1.F: 잔차 도표를 사용하여 이변량 데이터의 상관관계 형태를 서술한다. [기술 2.A]
DAT-1.F.1 선형 모델의 잔차 도표에서 보편적으로 보이는 무작위성은 변수 간의 상관관계가 선형 형태임을 시사합니다.
DAT-1.F.2 잔차 도표를 사용하여 선택한 모델이 적절한지 조사할 수 있습니다.
Source: College Board AP Course and Exam Description · 출처: College Board AP Course and Exam Description
Least-squares regression
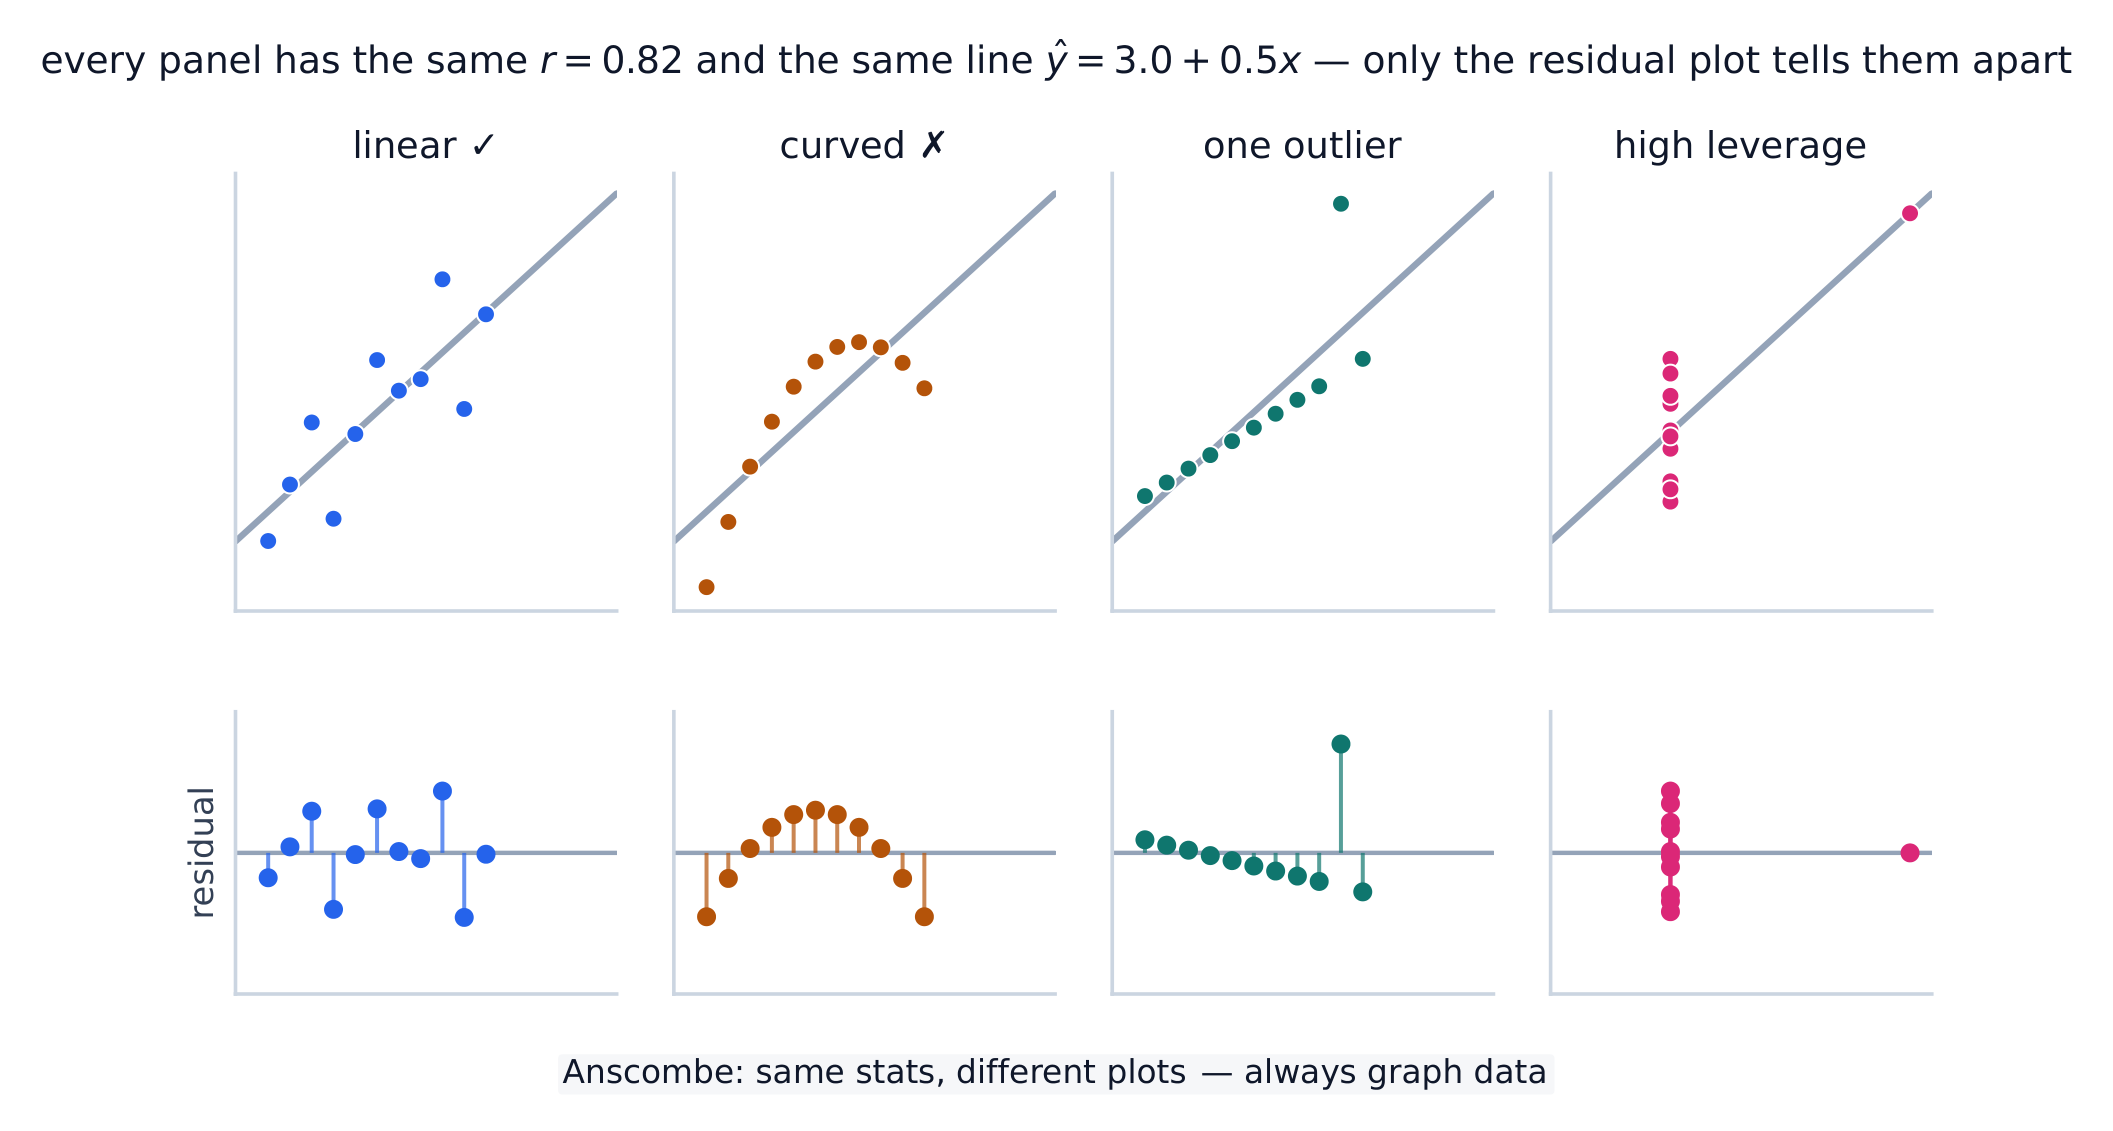
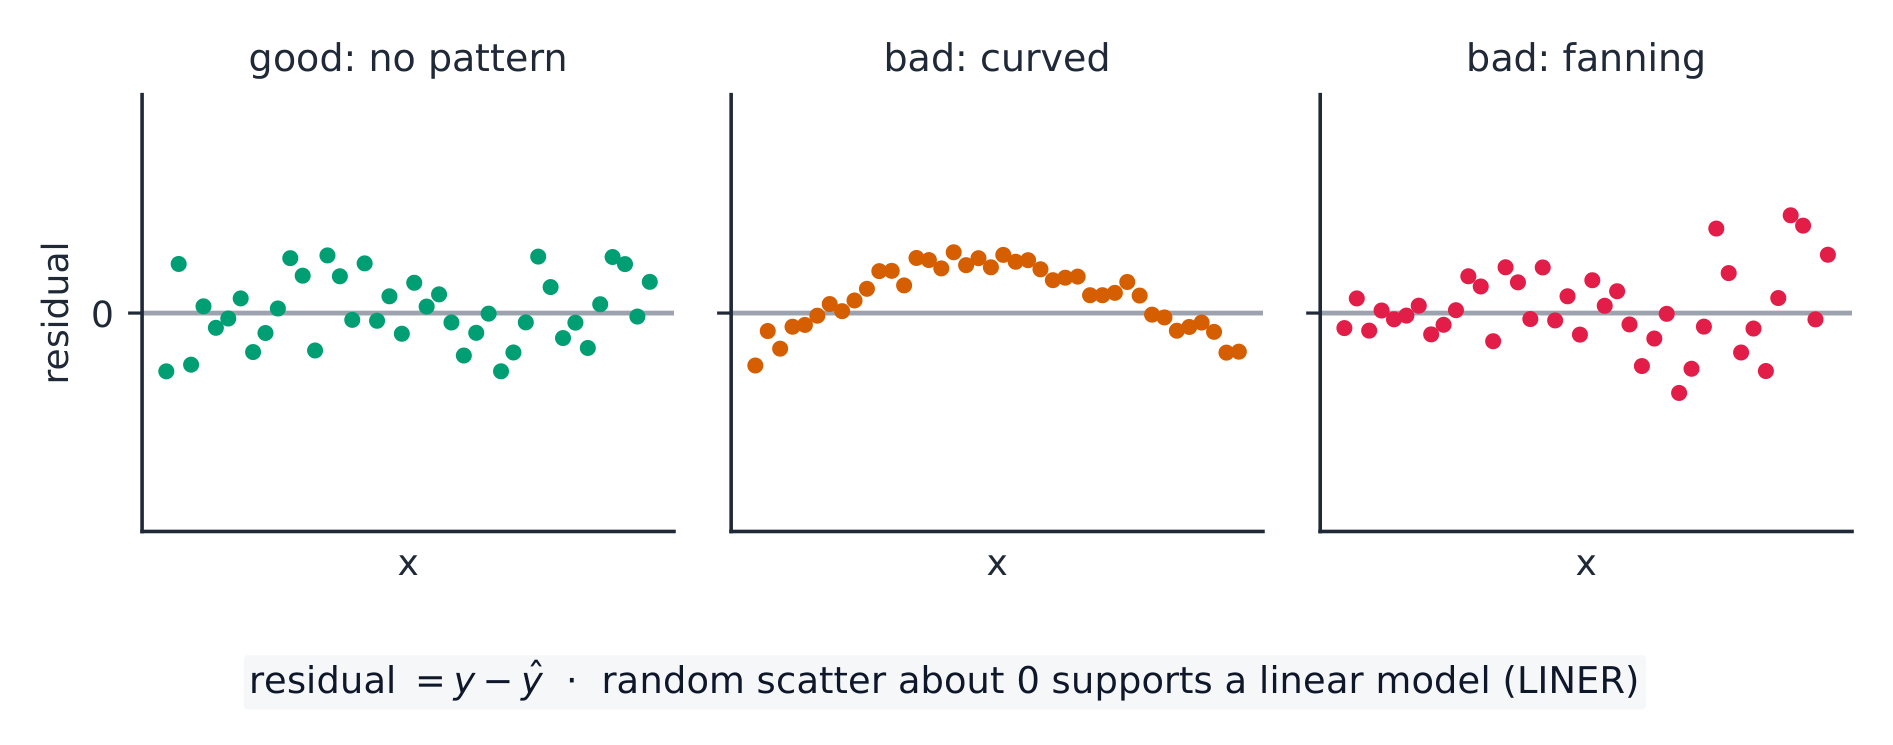
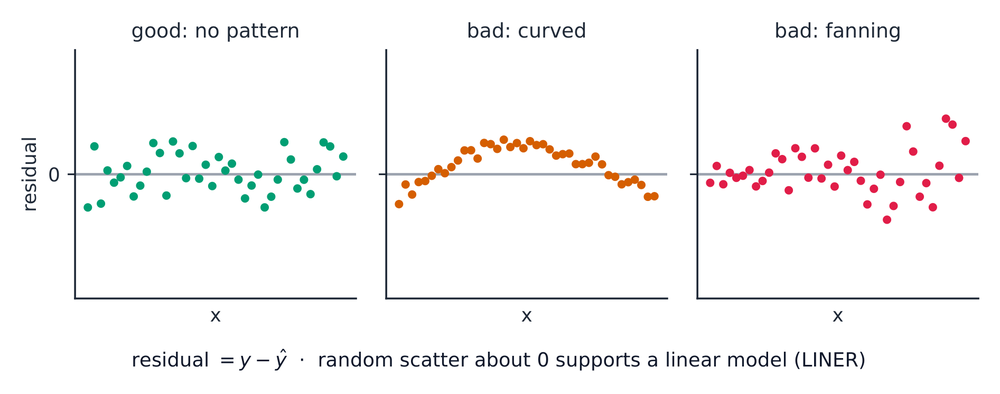
A residual 残差 is actual minus predicted, $y-\hat{y}$: how far a point sits above (+) or below (−) the line. A residual plot 残差图 graphs residuals against $x$. If it shows no pattern (random scatter), a linear model is appropriate; a curved or fanning pattern means the linear model is a poor fit.
Worked example. Continuing the study above, a student who studied $5$ hours actually scored $40$. The residual is $y-\hat{y}=40-35=+5$: the line under-predicted by $5$ points, so this point sits above the line.
A caution about $r$ and the line: all four datasets have the same $r=0.82$ and the same $\hat{y}=3.0+0.5x$, yet only the first is genuinely linear. The scatterplots barely differ — the residual plot below each is what exposes the curve, the outlier, and the high-leverage point.
DAT-1
Regression models may allow us to predict responses to changes in an explanatory variable.
DAT-1.G
Estimate parameters for the least-squares regression line model. [Skill 2.C]
DAT-1.G.1 The least-squares regression model minimizes the sum of the squares of the residuals and contains the point $(\bar{x}, \bar{y})$.
DAT-1.G.2 The slope, $b$, of the regression line can be calculated as $b = r \left( \dfrac{s_y}{s_x} \right)$ where $r$ is the correlation between $x$ and $y$, $s_y$ is the sample standard deviation of the response variable, $y$, and $s_x$ is the sample standard deviation of the explanatory variable, $x$.
DAT-1.G.3 Sometimes, the $y$-intercept of the line does not have a logical interpretation in context.
DAT-1.G.4 In simple linear regression, $r^2$ is the square of the correlation, $r$. It is also called the coefficient of determination. $r^2$ is the proportion of variation in the response variable that is explained by the explanatory variable in the model.
DAT-1.H
Interpret coefficients for the least-squares regression line model. [Skill 4.B]
DAT-1.H.1 The coefficients of the least-squares regression model are the estimated slope and $y$-intercept.
DAT-1.H.2 The slope is the amount that the predicted $y$-value changes for every unit increase in $x$.
DAT-1.H.3 The $y$-intercept value is the predicted value of the response variable when the explanatory variable is equal to $0$. The formula for the $y$-intercept, $a$, is $a = \bar{y} - b\bar{x}$.
Source: College Board AP Course and Exam Description · 출처: College Board AP Course and Exam Description
The least-squares line minimizes the sum of squared residuals
The line minimizes the sum of squared residuals. Its fit is measured by:
$s$, the standard deviation of the residuals – the typical prediction error, in the response's units.
$r^2$, the coefficient of determination 决定系数 – the proportion of the variation in $y$ that the linear model explains (a value between $0$ and $1$; multiply by $100$ to state it as a percent). Report it in context: "$r^2 = 0.81$ means 81% of the variation in $y$ is explained by the linear relationship with $x$."
coefficient of determination/ˌkəʊɪˈfɪʃənt ɒv dɪˌtɜːmɪˈneɪʃn/
결정 계수
2.9
Departures from Linearity
Syllabus
English
Enduring Understanding (DAT-1): Regression models may allow us to predict responses to changes in an explanatory variable.
Learning Objective DAT-1.I: Identify influential points in regression. [Skill 2.A]
DAT-1.I.1 An outlier in regression is a point that does not follow the general trend shown in the rest of the data and has a large residual when the Least Squares Regression Line (LSRL) is calculated.
DAT-1.I.2 A high-leverage point in regression has a substantially larger or smaller $x$-value than the other observations have.
DAT-1.I.3 An influential point in regression is any point that, if removed, changes the relationship substantially. Examples include much different slope, $y$-intercept, and/or correlation. Outliers and high leverage points are often influential.
Learning Objective DAT-1.J: Calculate a predicted response using a least-squares regression line for a transformed data set. [Skill 2.C]
DAT-1.J.1 Transformations of variables, such as evaluating the natural logarithm of each value of the response variable or squaring each value of the explanatory variable, can be used to create transformed data sets, which may be more linear in form than the untransformed data.
DAT-1.J.2 Increased randomness in residual plots after transformation of data and/or movement of $r^2$ to a value closer to 1 offers evidence that the least-squares regression line for the transformed data is a more appropriate model to use to predict responses to the explanatory variable than the regression line for the untransformed data.
한국어
지속적 이해 (DAT-1): 회귀 모델은 설명 변수의 변화에 대한 반응 예측을 가능하게 할 수 있습니다.
학습 목표 DAT-1.I: 회귀 분석에서 영향력 있는 점을 식별하기. [기술 2.A]
DAT-1.I.1 회귀 분석에서의 이상치는 전체 데이터에서 보이는 일반적인 경향과 다르며, 최소제곱회귀선(LSRL)을 계산했을 때 큰 잔차를 갖는 점이다.
DAT-1.I.2 회귀분석에서 높은 영향력 점수(high-leverage point)는 다른 관측치들과 비교해 $x$값이 현저히 크거나 작은 점을 의미합니다.
DAT-1.I.3 회귀 분석에서 영향력 있는 점은 제거했을 때 관계가 현저히 변하는 모든 점을 의미한다. 예로 기울기가 크게 다르거나, $y$절편 및/또는 상관계수가 달라지는 점이 포함된다. 이상치와 고지수 점은 주로 영향력이 크다.
학습 목표 DAT-1.J: 변환된 데이터셋에 대해 최소제곱회귀선을 사용하여 예측 반응을 계산하기. [기술 2.C]
DAT-1.J.1 반응변수의 각 값에 대해 자연로그를 취하거나 설명변수의 각 값을 제곱하는 등 변수 변환은 변환된 데이터셋을 생성하는 데 사용될 수 있으며, 이는 원시 데이터보다 형태상 더 선형적일 수 있다.
DAT-1.J.2 데이터 변환 및/또는 $r^2$을 1에 더 가까운 값으로 이동시킨 후 잔차 도표의 무작위성이 증가하면, 변환된 데이터에 대한 최소제곱회귀선이 미변환 데이터에 대한 회귀선보다 설명 변수에 대한 반응 예측에 더 적절한 모델임을 시사하는 증거가 된다.
Source: College Board AP Course and Exam Description · 출처: College Board AP Course and Exam Description
Some points strongly affect the line. A high-leverage 高杠杆 point has an extreme $x$-value; an influential 有影响的 point noticeably changes the slope or $r$ when removed; an outlier here is a point with a large residual. When the pattern is curved, transform a variable (e.g. take a log) to straighten it, then fit a line to the transformed data.
Can We Trust the Data We Collected? · 우리가 수집한 데이터를 신뢰할 수 있을까요?
Syllabus
English
Enduring Understanding (VAR-1): Given that variation may be random or not, conclusions are uncertain.
Learning Objective VAR-1.E: Identify questions to be answered about data collection methods. [Skill 1.A]
VAR-1.E.1 Methods for data collection that do not rely on chance result in untrustworthy conclusions.
한국어
지속적 이해 (VAR-1): 변동성이 우연일 수도 있고 그렇지 않을 수도 있으므로, 결론은 불확실할 수 있다.
학습 목표 VAR-1.E: 데이터 수집 방법에 대해 답해야 할 질문을 식별하기. [기술 1.A]
VAR-1.E.1 확률에 의존하지 않는 데이터 수집 방법은 신뢰할 수 없는 결론을 초래한다.
Source: College Board AP Course and Exam Description · 출처: College Board AP Course and Exam Description
English
A conclusion is only as good as the data behind it. How data are collected decides what you may conclude – whether you can generalize to a population 总体, and whether you can claim cause and effect. Poorly collected data can be worse than none.
한국어
결론은 그에 기반한 데이터의 품질만큼이나 좋습니다. 데이터 수집 방법이 결론의 범위(보편 집단(population)에 일반화 가능한지, 인과관계를 주장할 수 있는지를 결정합니다. 잘못 수집된 데이터는 아예 없는 것보다 나쁠 수 있습니다.
Observational Studies and Experiments · 관찰 연구와 실험
Syllabus
English
Enduring Understanding (DAT-2): The way we collect data influences what we can and cannot say about a population.
Learning Objective DAT-2.A: Identify the type of a study. [Skill 1.C]
DAT-2.A.1 A population consists of all items or subjects of interest.
DAT-2.A.2 A sample selected for study is a subset of the population.
DAT-2.A.3 In an observational study, treatments are not imposed. Investigators examine data for a sample of individuals (retrospective) or follow a sample of individuals into the future collecting data (prospective) in order to investigate a topic of interest about the population. A sample survey is a type of observational study that collects data from a sample in an attempt to learn about the population from which the sample was taken.
DAT-2.A.4 In an experiment, different conditions (treatments) are assigned to experimental units (participants or subjects).
Learning Objective DAT-2.B: Identify appropriate generalizations and determinations based on observational studies. [Skill 4.A]
DAT-2.B.1 It is only appropriate to make generalizations about a population based on samples that are randomly selected or otherwise representative of that population.
DAT-2.B.2 A sample is only generalizable to the population from which the sample was selected.
DAT-2.B.3 It is not possible to determine causal relationships between variables using data collected in an observational study.
한국어
영구적 이해 (DAT-2): 데이터를 수집하는 방식은 우리가 집단에 대해 말할 수 있고 말할 수 없는 것을 결정한다.
학습 목표 DAT-2.A: 연구의 유형을 식별하기. [기술 1.C]
DAT-2.A.1 집단은 관심 있는 모든 항목이나 주체로 구성된다.
DAT-2.A.2 연구에 선택된 표본은 집단의 하집합이다.
DAT-2.A.3 관찰 연구에서는 처리가 가해지지 않는다. 연구자는 집단에 대한 관심 있는 주제에 대해 조사하기 위해 개인 표본의 데이터를 검토(후향적)하거나 개인 표본을 미래로 추적하여 데이터를 수집(전향적)한다. 표본 조사는 표본이 추출된 집단에 대해 알기 위해 표본으로부터 데이터를 수집하려는 관찰 연구의 일종이다.
DAT-2.A.4 실험에서는 서로 다른 조건(처리)이 실험 단위(참여자 또는 피험자)에 배정된다.
학습 목표 DAT-2.B: 관찰 연구를 기반으로 한 적절한 일반화 및 판단을 식별하기. [기술 4.A]
DAT-2.B.1 집단에 대한 일반화는 랜덤하게 선택되었거나 해당 집단을 대표하는 표본에 대해서만 적절하다.
DAT-2.B.2 표본은 그 표본이 선택된 집단에서만 일반화 가능하다.
DAT-2.B.3 관찰研究中에서 수집된 데이터를 사용하여 변수 간의 인과 관계를 결정하는 것은 불가능하다.
Source: College Board AP Course and Exam Description · 출처: College Board AP Course and Exam Description
English
In an observational study 观察性研究 you measure individuals without trying to influence them. It can show association, but not causation, because lurking variables may explain the link.
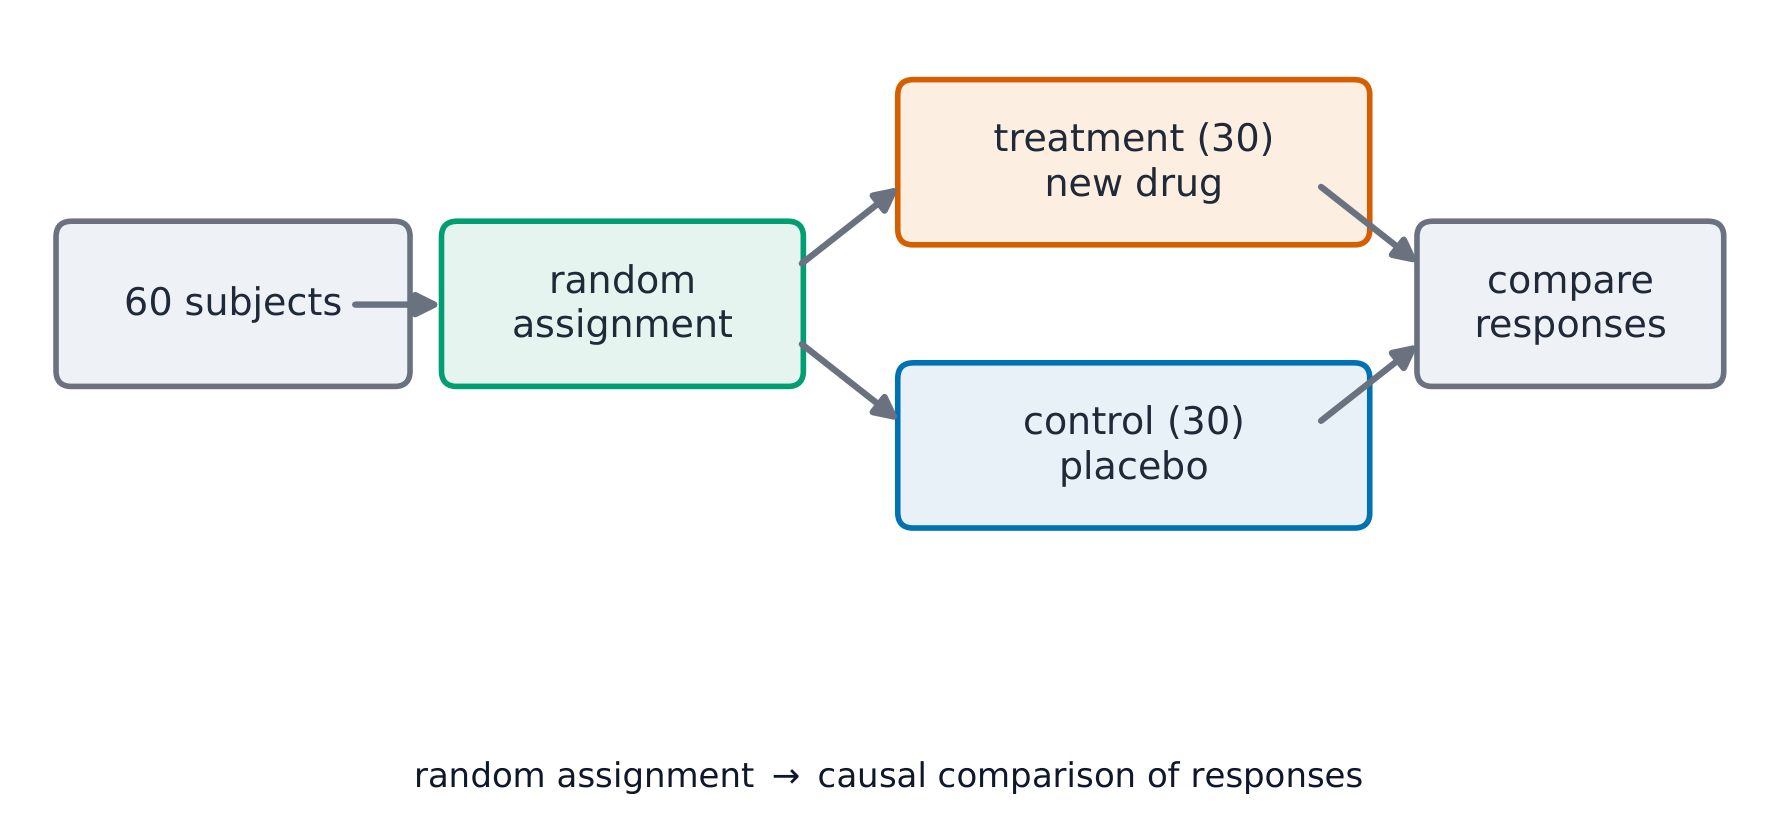
In an experiment 实验 you deliberately impose a treatment 处理 and compare responses. A well-designed experiment can establish cause and effect.
한국어
**관찰 연구(observational study)**에서는 개인을 측정하되 영향을 주지 않습니다. **연관성(association)**을 보일 수는 있으나, 숨겨진 변수가 연결을 설명할 수 있으므로 인과관계는 알 수 없습니다.
**실험(experiment)**에서는 의도적으로 **처치(treatment)**를 가하고 반응을 비교합니다. 잘 설계된 실험은 인과관계를 확립할 수 있습니다.
Explore · 탐색하기
Observational study or experiment? · 관찰 연구인지 실험인가?
In an experiment the researcher imposes a treatment (and can show cause); an observational study only records what already happens (and can show association, not cause). · 실험에서 연구자는 처방을 가하여 인과관계를 증명할 수 있으며, 관찰 연구는 이미 발생하는 현상을 기록할 뿐이며(인과관계가 아닌 상관관계만 보여줍니다).
Enduring Understanding (DAT-2): The way we collect data influences what we can and cannot say about a population.
Learning Objective DAT-2.C: Identify a sampling method, given a description of a study. [Skill 1.C]
DAT-2.C.1 When an item from a population can be selected only once, this is called sampling without replacement. When an item from the population can be selected more than once, this is called sampling with replacement.
DAT-2.C.2 A simple random sample (SRS) is a sample in which every group of a given size has an equal chance of being chosen. This method is the basis for many types of sampling mechanisms. A few examples of mechanisms used to obtain SRSs include numbering individuals and using a random number generator to select which ones to include in the sample, ignoring repeats, using a table of random numbers, or drawing a card from a deck without replacement.
DAT-2.C.3 A stratified random sample involves the division of a population into separate groups, called strata, based on shared attributes or characteristics (homogeneous grouping). Within each stratum a simple random sample is selected, and the selected units are combined to form the sample.
DAT-2.C.4 A cluster sample involves the division of a population into smaller groups, called clusters. Ideally, there is heterogeneity within each cluster, and clusters are similar to one another in their composition. A simple random sample of clusters is selected from the population to form the sample of clusters. Data are collected from all observations in the selected clusters.
DAT-2.C.5 A systematic random sample is a method in which sample members from a population are selected according to a random starting point and a fixed, periodic interval.
DAT-2.C.6 A census selects all items/subjects in a population.
Learning Objective DAT-2.D: Explain why a particular sampling method is or is not appropriate for a given situation. [Skill 1.C]
DAT-2.D.1 There are advantages and disadvantages for each sampling method depending upon the question that is to be answered and the population from which the sample will be drawn.
한국어
영구적 이해 (DAT-2): 데이터를 수집하는 방식은 우리가 집단에 대해 말할 수 있고 말할 수 없는 것을 결정한다.
학습 목표 DAT-2.C: 연구 설명을 바탕으로 샘플링 방법을 식별하기. [기술 1.C]
DAT-2.C.1 집단의 항목이 한 번만 선택될 수 있을 때는 이를 복원/sample without replacement이라고 한다. 집단의 항목이 여러 번 선택될 수 있을 때는 이를 부복원/sample with replacement이라고 한다.
DAT-2.C.2 단순랜덤표본(SRS)은 특정 크기의 모든 그룹이 선택될 동일한 확률을 가지는 표본이다. 이 방법은 다양한 샘플링 메커니즘의 기초가 된다. SRS를 얻기 위해 사용되는 몇몇 메커니즘의 예로는 개인에게 번호를 매겨 랜덤넘버생성기를 사용하여 표본에 포함시킬 것들을 선택(중복 무시), 랜덤넘버표 사용, 또는 부복원으로 카드를 뽑는 등이 있다.
DAT-2.C.3 층화 무작위 표본(stratified random sample)은 공통된 속성이나 특징(동질적 그룹화)에 따라 모집단을 개별적인 그룹인 층(strata)으로 나누는 것이다. 각 층 내부에서 단순 무작위 표본이 선택되며, 선택된 단위들이 결합되어 최종 표본을 구성한다.
DAT-2.C.4 클러스터 표본(cluster sample)은 모집단을 작은 그룹인 클러스터(clusters)로 나누는 방법이다. 이상적으로는 각 클러스터 내부에 이질성이 존재하며, 클러스터끼리 구성 면에서 유사해야 한다. 클러스터의 단순 무작위 표본을 모집단에서 선택하여 클러스터 표본을 형성한다. 선택된 클러스터 내의 모든 관측치로부터 데이터를 수집한다.
DAT-2.C.5 체계적 무작위 표본(systematic random sample)은 무작위 시작점과 고정된 주기적 간격을 사용하여 모집단의 표본 구성원을 선택하는 방법이다.
DAT-2.C.6 전수 조사(census)는 모집단에 있는 모든 항목/대상을 선정한다.
학습 목표 DAT-2.D: 특정 situations에 대한 sampling method가 적절한지 아닌지를 설명할 수 있다. [Skill 1.C]
DAT-2.D.1Sampling method마다 답하고자 하는 질문과 표본을 추출할 모집단에 따라 장단점이 다르다.
Source: College Board AP Course and Exam Description · 출처: College Board AP Course and Exam Description
English
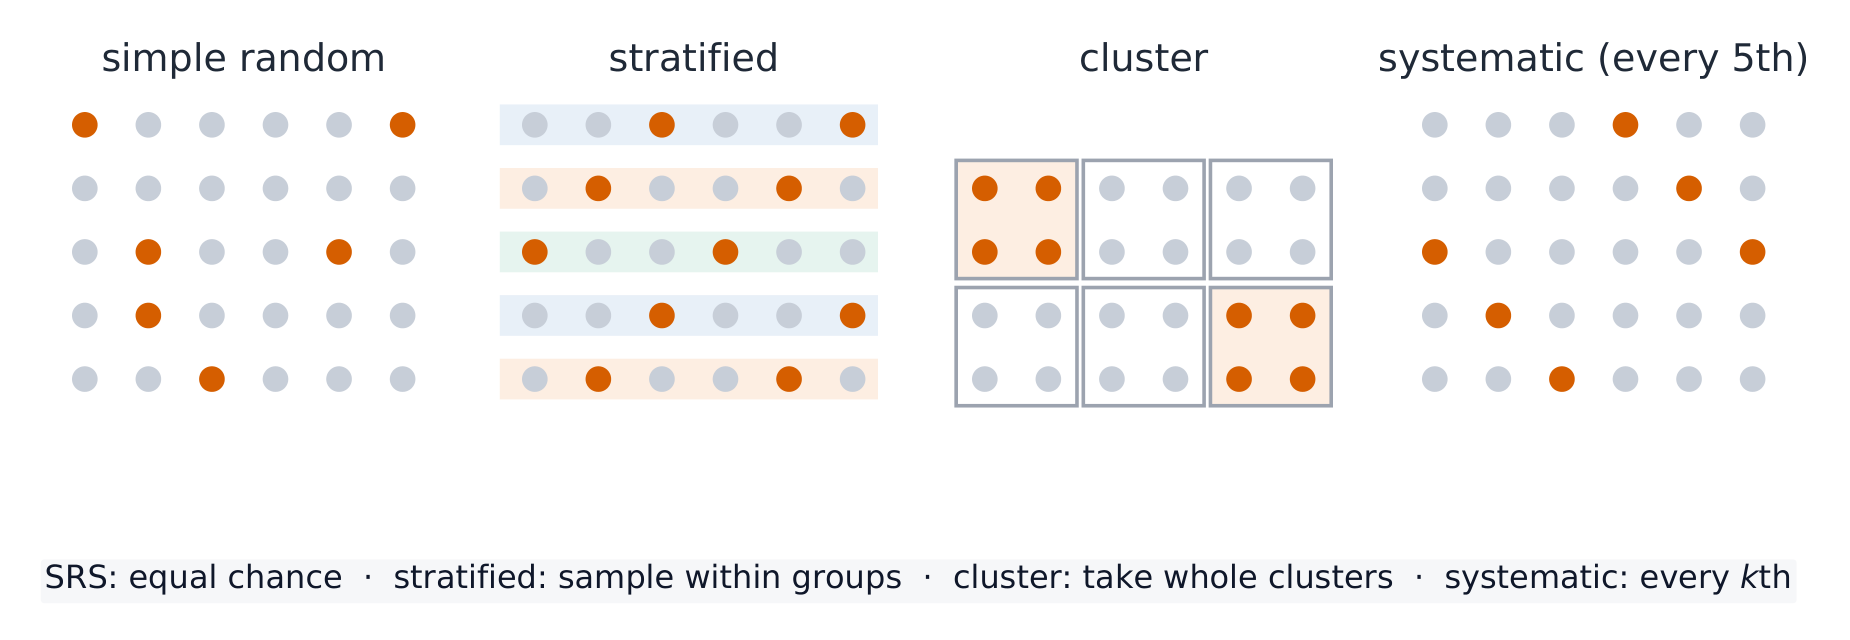
To learn about a population you take a sample 样本. Random sampling 随机抽样 protects against selection bias 偏差 and lets you generalize (it cannot fix undercoverage, nonresponse, or response bias — see below). Common designs:
Simple random sample (SRS) 简单随机样本: every group of the chosen size is equally likely.
Stratified 分层: split the population into similar strata, then sample within each.
Cluster 整群: split into clusters, randomly choose whole clusters.
Systematic 系统: pick every $k$th individual from a random start.
A convenience sample 方便样本 or voluntary response sample is not random and is biased.
Worked example. To survey a school, an administrator lists all students by grade and randomly selects $20$ from each grade. This is a stratified sample – the grades are the strata – which guarantees every grade is represented, unlike an SRS that might by chance draw few from one grade.
한국어
보편 집단에 대해 배우려면 **표본(sample)**을 취합니다. **무작위 표본 추출(random sampling)**은 선택 **편향(bias)**을 방지하고 일반화를 가능하게 합니다(아래에서 설명할 저면_coverage, 비응답, 응답 편향을 해결하지는 못함). 일반적인 설계:
简单随机样本 (SRS): 선택한 크기의 모든 그룹이 동일한 확률로 선택됩니다.
층화(stratified): 집단을 유사한 층(strata)으로 나누어 각 층 내에서 표본을 취합니다.
군집(cluster): 클러스터로 나누어 전체 클러스터를 무작위로 선택합니다.
체계적(systematic): 무작위 시작점에서 매 $k$번째 개인을 선택합니다.
네 가지 무작위 표본 설계: 누가 선정되며, 어떻게
편의 표본 또는 자발적 응답 표본은 무작위가 아니며, 편향되어 있습니다.
해설 예시. 학교를 조사하기 위해 관리자가 학년별students을 나열하고 각 학년에서 $20$명을 무작위로 선택합니다. 이는 층화 표본입니다 – 학년이 층(strata)이며 – 모든 학년이 반드시 포함됨을 보장합니다. 이는 우연히 한 학년부터 소수의 표본이 추출될 수 있는 SRS와 다릅니다.
Enduring Understanding (DAT-2): The way we collect data influences what we can and cannot say about a population.
Learning Objective DAT-2.E: Identify potential sources of bias in sampling methods. [Skill 1.C]
DAT-2.E.1 Bias occurs when certain responses are systematically favored over others.
DAT-2.E.2 When a sample is comprised entirely of volunteers or people who choose to participate, the sample will typically not be representative of the population (voluntary response bias).
DAT-2.E.3 When part of the population has a reduced chance of being included in the sample, the sample will typically not be representative of the population (undercoverage bias).
DAT-2.E.4 Individuals chosen for the sample for whom data cannot be obtained (or who refuse to respond) may differ from those for whom data can be obtained (nonresponse bias).
DAT-2.E.5 Problems in the data gathering instrument or process result in response bias. Examples include questions that are confusing or leading (question wording bias) and self-reported responses.
DAT-2.E.6 Non-random sampling methods (for example, samples chosen by convenience or voluntary response) introduce potential for bias because they do not use chance to select the individuals.
한국어
영구적 이해 (DAT-2): 데이터를 수집하는 방식은 우리가 집단에 대해 말할 수 있고 말할 수 없는 것을 결정한다.
학습 목표 DAT-2.E: Sampling methods에서 발생할 수 있는 bias의 잠재적 원인을 식별할 수 있다. [Skill 1.C]
DAT-2.E.1 bias는 특정 응답이 다른 응답보다 체계적으로 선호될 때 발생한다.
DAT-2.E.2 표본이 전적으로 자발적으로 참여하거나 참여를 선택한 사람들로만 구성되어 있을 경우, 그 표본은 일반적으로 모집단을 대표하지 못한다(자발 응답 편향, voluntary response bias).
DAT-2.E.3 모집단의 일부가 표본에 포함될 확률이 낮아졌을 경우, 그 표본은 일반적으로 모집단을 대표하지 못한다(미포함 편향, undercoverage bias).
DAT-2.E.4 데이터 확보가 불가능하거나(또는 응답을 거부한) 표본에 선정한 개인들은 데이터 확보가 가능한 개인들과 다를 수 있다(비응답 편향, nonresponse bias).
DAT-2.E.5 데이터 수집 도구나 과정의 문제가 반응 편향(response bias)을 유발한다. 예로는 혼란스럽거나 유도적인 질문(질문 문구 편향, question wording bias), 자기 보고식 응답 등이 포함된다.
DAT-2.E.6 비무작위 sampling methods(예: 편의抽样或自愿响应抽样)는 chances를 사용하여 individual들을 선택하지 않기 때문에 bias가 발생할 가능성이 있다.
Source: College Board AP Course and Exam Description · 출처: College Board AP Course and Exam Description
English
Bias makes estimates systematically miss the truth:
Undercoverage 覆盖不足: some groups are left out of the sampling frame.
Nonresponse 无回应: selected people do not answer.
Response bias 回应偏差: people answer inaccurately (bad wording, sensitive topics).
Bias is about a consistent error in one direction – increasing the sample size does not fix it.
한국어
**편향(bias)**은 추정이 진리에 체계적으로 어긋나게 만듭니다:
불완전 커버리지(undercoverage): 일부 집단이 표본 프레임에서 제외됩니다.
비응답(nonresponse): 선정된 사람들이 응답하지 않습니다.
응답 편향(response bias): 사람들이 부정확하게 답합니다 (나쁜 문구, 민감한 주제).
Enduring Understanding (VAR-3): Well-designed experiments can establish evidence of causal relationships.
Learning Objective VAR-3.A: Identify the components of an experiment. [Skill 1.C]
VAR-3.A.1 The experimental units are the individuals (which may be people or other objects of study) that are assigned treatments. When experimental units consist of people, they are sometimes referred to as participants or subjects.
VAR-3.A.2 An explanatory variable (or factor) in an experiment is a variable whose levels are manipulated intentionally. The levels or combination of levels of the explanatory variable(s) are called treatments.
VAR-3.A.3 A response variable in an experiment is an outcome from the experimental units that is measured after the treatments have been administered.
VAR-3.A.4 A confounding variable in an experiment is a variable that is related to the explanatory variable and influences the response variable and may create a false perception of association between the two.
Learning Objective VAR-3.B: Describe elements of a well-designed experiment. [Skill 1.B]
VAR-3.B.1 A well-designed experiment should include the following:
a. Comparisons of at least two treatment groups, one of which could be a control group.
b. Random assignment/allocation of treatments to experimental units.
c. Replication (more than one experimental unit in each treatment group).
d. Control of potential confounding variables where appropriate.
Learning Objective VAR-3.C: Compare experimental designs and methods. [Skill 1.C]
VAR-3.C.1 In a completely randomized design, treatments are assigned to experimental units completely at random. Random assignment tends to balance the effects of uncontrolled (confounding) variables so that differences in responses can be attributed to the treatments.
VAR-3.C.2 Methods for randomly assigning treatments to experimental units in a completely randomized design include using a random number generator, a table of random values, drawing chips without replacement, etc.
VAR-3.C.3 In a single-blind experiment, subjects do not know which treatment they are receiving, but members of the research team do, or vice versa.
VAR-3.C.4 In a double-blind experiment neither the subjects nor the members of the research team who interact with them know which treatment a subject is receiving.
VAR-3.C.5 A control group is a collection of experimental units either not given a treatment of interest or given a treatment with an inactive substance (placebo) in order to determine if the treatment of interest has an effect.
VAR-3.C.6 The placebo effect occurs when experimental units have a response to a placebo.
VAR-3.C.7 For randomized complete block designs, treatments are assigned completely at random within each block.
VAR-3.C.8 Blocking ensures that at the beginning of the experiment the units within each block are similar to each other with respect to at least one blocking variable. A randomized block design helps to separate natural variability from differences due to the blocking variable.
VAR-3.C.9 A matched pairs design is a special case of a randomized block design. Using a blocking variable, subjects (whether they are people or not) are arranged in pairs matched on relevant factors. Matched pairs may be formed naturally or by the experimenter. Every pair receives both treatments by randomly assigning one treatment to one member of the pair and subsequently assigning the remaining treatment to the second member of the pair. Alternately, each subject may get both treatments.
한국어
지속적 이해(VAR-3): 잘 설계된 실험은 인과관계(causal relationships)에 대한 증거를確立할 수 있다.
학습 목표 VAR-3.A: 실험의 구성 요소를 식별할 수 있다. [Skill 1.C]
VAR-3.A.1 실험 단위(experimental units)는 treatment을 배정받는 개인들(사람 또는 기타 연구 대상 물체)이다. 실험 단위가 사람일 경우, 이들은 때때로 참여자(participants) 또는 피험자(subjects)라고 불리기도 한다.
VAR-3.A.2 실험에서의 설명 변수(explanatory variable) 또는 요인(factor)은 수준(levels)이 의도적으로 조작되는 변수이다. 설명 변수의 수준 또는 수준의 조합은 treatment이라고 부른다.
VAR-3.A.3 실험에서의 반응 변수(response variable)는 treatment이 적용된 후에 실험 단위로 부터 측정되는 결과(output)이다.
VAR-3.A.4 실험에서의 교란 변수(confounding variable)는 설명 변수와 관련이 있으며 반응 변수에 영향을 미칠 수 있어 두 변수 사이에 가짜 연관성을 creation할 수 있는 변수이다.
학습 목표 VAR-3.B: 잘 설계된 experiment의 요소들을 설명할 수 있다. [Skill 1.B]
VAR-3.B.1 잘 설계된 experiment는 다음을 포함해야 한다:
a. 최소 두 개의 treatment 그룹 간의 비교, 그 중 하나는 control group일 수 있다.
b. 실험 단위에 대한 treatment의 무작위 배정/allocation.
c. 반복(replication)(각 treatment 그룹당 하나 이상의 실험 단위).
d. 필요한 경우潜在的 confounding variables에 대한 통제(control).
학습 목표 VAR-3.C: 실험 설계와 방법을 비교할 수 있다. [Skill 1.C]
VAR-3.C.1 완전 무작위 설계(completely randomized design)에서는 treatments가 실험 단위에 완전히 무작위로 배정된다. 무작위 배정은 통제되지 않은(교란) 변수의 효과를 balancing하는 경향이 있어, 반응의 차이를 treatments로 귀결할 수 있게 한다.
VAR-3.C.2 완전 무작위 설계에서 treatments를 실험 단위에 무작위로 배정하는 방법으로는 무작위 번호 생성기(random number generator) 사용, 무작위 값 표(table of random values) 사용, 치프(chips)를 교체 없이 뽑기 등 있다.
VAR-3.C.3 단일 맹검 실험(single-blind experiment)에서는 피험자들이 어떤 treatment을 받고 있는지 모르고, 연구진(R&D team)은 알거나, 반대로 연구진은 모르고 피험자는 아는 상태이다.
VAR-3.C.4 이중 맹검 실험(double-blind experiment)에서는 피험자와 피험자를 interacts하는 연구진 구성원 모두 피험자가 어떤 treatment을 받고 있는지 모른다.
VAR-3.C.5 control group은 관심 있는 treatment의 효과가 있는지 확인하기 위해,感兴趣的treatment을 받지 않거나 무효 물질(placebo)이 포함된 treatment을 받는 실험 단위의 집합이다.
VAR-3.C.6 위약 효과(placebo effect)는 실험 단위가 placebo에 반응할 때 발생한다.
VAR-3.C.7 무작위 완전 블록 설계(randomized complete block designs)에서는 treatments가 각 블록(block) 내에서 완전히 무작위로 배정된다.
VAR-3.C.8 blocking은 실험 시작 시점에 각 블록 내부의 단위들이 적어도 하나의 blocking 변수에 대해 서로 유사하도록 보장한다. 무작위 블록 설계는 자연적 변이(natural variability)와 blocking 변수에 의한 차이(differences due to the blocking variable)를 분리하는 데 도움이 된다.
VAR-3.C.9 매칭된 쌍 설계는 무작위 블록 설계의 특수한 경우입니다. 차단 변수를 사용하여 연구 대상(사람일 수도 있고 그렇지 않을 수도 있음)이 관련 요인에 따라 쌍으로 매칭됩니다. 매칭된 쌍은 자연적으로 형성되거나 실험자가 직접 구성할 수 있습니다. 모든 쌍은 두 가지 처리 조건을 모두 받으며, 한 쌍의 구성원 중 한 명에게 무작위로 첫 번째 처리 조건을 배정하고 나머지 구성원에게는 두 번째 처리 조건을 배정합니다. 대안적으로 각 연구 대상이 두 가지 처리 조건을 모두 받을 수도 있습니다.
Source: College Board AP Course and Exam Description · 출처: College Board AP Course and Exam Description
English
Good experiments follow three principles:
Comparison with a control group 对照组 (often a placebo 安慰剂).
Random assignment 随机分配 of subjects to treatments, to balance out other variables.
Replication 重复: enough subjects per treatment to see a real effect.
Confounding 混杂 occurs when another variable is tied to the treatment so their effects cannot be separated; random assignment guards against it. Blinding 盲法 hides who is getting which treatment to prevent expectation effects: in a single-blind 单盲 study only one side is kept unaware (usually the subjects, or only the people assessing the result), while in a double-blind 双盲 study neither the subjects nor the researchers who interact with them know, blocking both the placebo effect and biased assessment. Blocking 区组 groups similar subjects and randomizes within each block to reduce variability.
한국어
좋은 실험은 세 가지 원칙을 따릅니다:
**대조군(control group)**과의 비교 (종종 위약 placebo임).
다른 변수들을 균형 있게 만들기 위한 처리에 대한 무작위 배정(random assignment).
반복(replication): 실제 효과를 확인할 수 있도록 처리당 충분한 수의 대상자.
완전 무작위 실험은 처리군과 대조군을 비교함
**혼란(confounding)**은 다른 변수가 처리와 연관되어 있어 그 영향을 분리할 수 없을 때 발생합니다; 무작위 배정은 이를 방지합니다. **블라인딩(blinding)**은 누가 어떤 처리를 받는지를 숨겨 기대 효과를 방지합니다: 단일 블라인드(single-blind) 연구에서는 한쪽만 모르게 합니다 (보통 대상자이거나, 결과를 평가하는 사람만), 이중 블라인드(double-blind) 연구에서는 두 사람 모두 대상자와 상호작용하는 연구원이 모르게 하여 위약 효과와 편향된 평가를 모두 차단합니다. **블로킹(blocking)**은 유사한 대상자들을 그룹으로 나누고 각 블록 내에서 무작위 배정을 하여 변이를 줄입니다.
Enduring Understanding (VAR-3): Well-designed experiments can establish evidence of causal relationships.
Learning Objective VAR-3.D: Explain why a particular experimental design is appropriate. [Skill 1.C]
VAR-3.D.1 There are advantages and disadvantages for each experimental design depending on the question of interest, the resources available, and the nature of the experimental units.
한국어
지속적 이해(VAR-3): 잘 설계된 실험은 인과관계(causal relationships)에 대한 증거를確立할 수 있다.
학습 목표 VAR-3.D: 특정 실험 설계가 적절한 이유를 설명하시오. [기술 1.C]
VAR-3.D.1 각 실험 설계에는 관심 있는 질문,可利用한 자원, 실험 단위의 성격에 따라 장단점이 존재합니다.
Source: College Board AP Course and Exam Description · 출처: College Board AP Course and Exam Description
English
Match the design to the goal: use a completely randomized design for uniform subjects; a randomized block design when a known variable (sex, age) affects the response; a matched-pairs design when each subject can serve as its own control. State how you would carry out the randomization.
한국어
목표에 맞춰 설계를 선택하십시오: 균일한 대상자에게는 **완전 무작위 설계(completely randomized design)**를,已知된 변수(성별, 연령 등)가 반응에 영향을 미칠 때는 **무작위 블록 설계(randomized block design)**를, 각 대상자가 자신의 대조군이 될 수 있을 때는 매칭 페어즈(matched-pairs) 설계를 사용하십시오. 무작위 배정을 어떻게 수행할지 명시하십시오.
3.7
What an Experiment Lets You Conclude · 실험으로 도출할 수 있는 결론
Syllabus
English
Enduring Understanding (VAR-3): Well-designed experiments can establish evidence of causal relationships.
Learning Objective VAR-3.E: Interpret the results of a well-designed experiment. [Skill 4.B]
VAR-3.E.1 Statistical inference attributes conclusions based on data to the distribution from which the data were collected.
VAR-3.E.2 Random assignment of treatments to experimental units allows researchers to conclude that some observed changes are so large as to be unlikely to have occurred by chance. Such changes are said to be statistically significant.
VAR-3.E.3 Statistically significant differences between or among experimental treatment groups are evidence that the treatments caused the effect.
VAR-3.E.4 If the experimental units used in an experiment are representative of some larger group of units, the results of an experiment can be generalized to the larger group. Random selection of experimental units gives a better chance that the units will be representative.
한국어
지속적 이해(VAR-3): 잘 설계된 실험은 인과관계(causal relationships)에 대한 증거를確立할 수 있다.
학습 목표 VAR-3.E: 잘 설계된 실험의 결과를 해석하시오. [기술 4.B]
VAR-3.E.1 통계적 추론은 수집된 데이터가 도출된 분포에 기반하여 도출된 결론을 귀인합니다.
VAR-3.E.2 처리 조건의 무작위 배정은 연구자가 관측된 일부 변화가 우연히 일어날 가능성이 매우 낮다는 것을 결론지을 수 있게 합니다. 이러한 변화는 통계적으로 유의미하다고 합니다.
VAR-3.E.3 실험 처리 그룹 간 또는 내의 통계적으로 유의미한 차이는 처리 조건이 결과에 원인이 되었다는 증거입니다.
VAR-3.E.4 실험에 사용된 실험 단위가 더 큰 집단의 일부를 대표한다면, 실험 결과를 그 더 큰 집단에 일반화할 수 있습니다. 실험 단위의 무작위 선택은 단위가 대표성을 갖게 될 확률을 높여줍니다.
Source: College Board AP Course and Exam Description · 출처: College Board AP Course and Exam Description
English
Two questions decide the scope of a conclusion:
Random assignment used? Then a significant difference can be attributed to the treatment (causation) – for these subjects.
Random sampling from a population? Then results generalize to that population.
Only an experiment with random assignment supports a cause-and-effect claim; only random sampling supports generalization. Say exactly which you have.
Worked example. Researchers randomly assign $100$volunteers to a new drug or a placebo, and the drug group improves significantly more. Because of the random assignment, the improvement can be attributed to the drug (causation) – but because the subjects were not randomly sampled, the conclusion applies only to these volunteers and does not automatically generalize to everyone.
한국어
결론의 범위를 결정하는 두 가지 질문이 있습니다:
무작위 배정을 사용했는가? 그렇다면 유의미한 차이는 처리에 기인할 수 있다 (인과관계 causation) – 이 대상자에 한하여.
모집단으로부터 무작위 표본을 추출했는가? 그렇다면 결과가 **해당 모집단에 일반화(generalize)**됩니다.
무작위 배정을 가진 실험만이 인과관계 주장을 지지하며, 무작위 표본만이 일반화를 지지합니다. 당신이 정확히 무엇을 가졌는지 명시하십시오.
해설 예시. 연구진들이 $100$ **지원자(volunteers)**를 새로운 약물이나 위약에 무작위로 배정하고, 약물 군이 유의미하게 더 개선되었습니다. 무작위 배정 때문에 개선은 약물에 기인할 수 있습니다 (인과관계) – 하지만 대상자들이 무작위 표본이 아니었으므로, 결론은 이 지원자들에게만 적용되며 자동으로 모든 사람에게 일반화되지는 않습니다.
3.7
Exam tips · 시험 팁
English
Distinguish an observational study (finds association) from an experiment (can show causation).
Good sampling is random (SRS, stratified, cluster) — beware bias (voluntary response, undercoverage, nonresponse).
Good experiments use control, randomization, and replication; blocking handles a known nuisance variable.
Only a randomized experiment supports a cause-and-effect conclusion.
Name the population, sample, and any confounding clearly.
Enduring Understanding (VAR-1): Given that variation may be random or not, conclusions are uncertain.
Learning Objective VAR-1.F: Identify questions suggested by patterns in data. [Skill 1.A]
VAR-1.F.1 Patterns in data do not necessarily mean that variation is not random.
한국어
지속적 이해 (VAR-1): 변동성이 우연일 수도 있고 그렇지 않을 수도 있으므로, 결론은 불확실할 수 있다.
학습 목표 VAR-1.F: 데이터의 패턴에서 제기되는 질문을 식별하시오. [기술 1.A]
VAR-1.F.1 데이터의 패턴이 반드시 변동성이 무작위가 아니라는 것을 의미하지는 않습니다.
Source: College Board AP Course and Exam Description · 출처: College Board AP Course and Exam Description
Something is random 随机 if individual outcomes are uncertain but a regular pattern emerges over many repetitions. Short-run results look erratic; long-run relative frequencies settle down. This long-run stability is what makes probability useful.
Enduring Understanding (UNC-2): Simulation allows us to anticipate patterns in data.
Learning Objective UNC-2.A: Estimate probabilities using simulation. [Skill 3.A]
UNC-2.A.1 A random process generates results that are determined by chance.
UNC-2.A.2 An outcome is the result of a trial of a random process.
UNC-2.A.3 An event is a collection of outcomes.
UNC-2.A.4 Simulation is a way to model random events, such that simulated outcomes closely match real-world outcomes. All possible outcomes are associated with a value to be determined by chance. Record the counts of simulated outcomes and the count total.
UNC-2.A.5 The relative frequency of an outcome or event in simulated or empirical data can be used to estimate the probability of that outcome or event.
UNC-2.A.6 The law of large numbers states that simulated (empirical) probabilities tend to get closer to the true probability as the number of trials increases.
Illustrative examples for UNC-2.A:
An outcome: Rolling a particular value on a six-sided number cube is one of six possible outcomes.
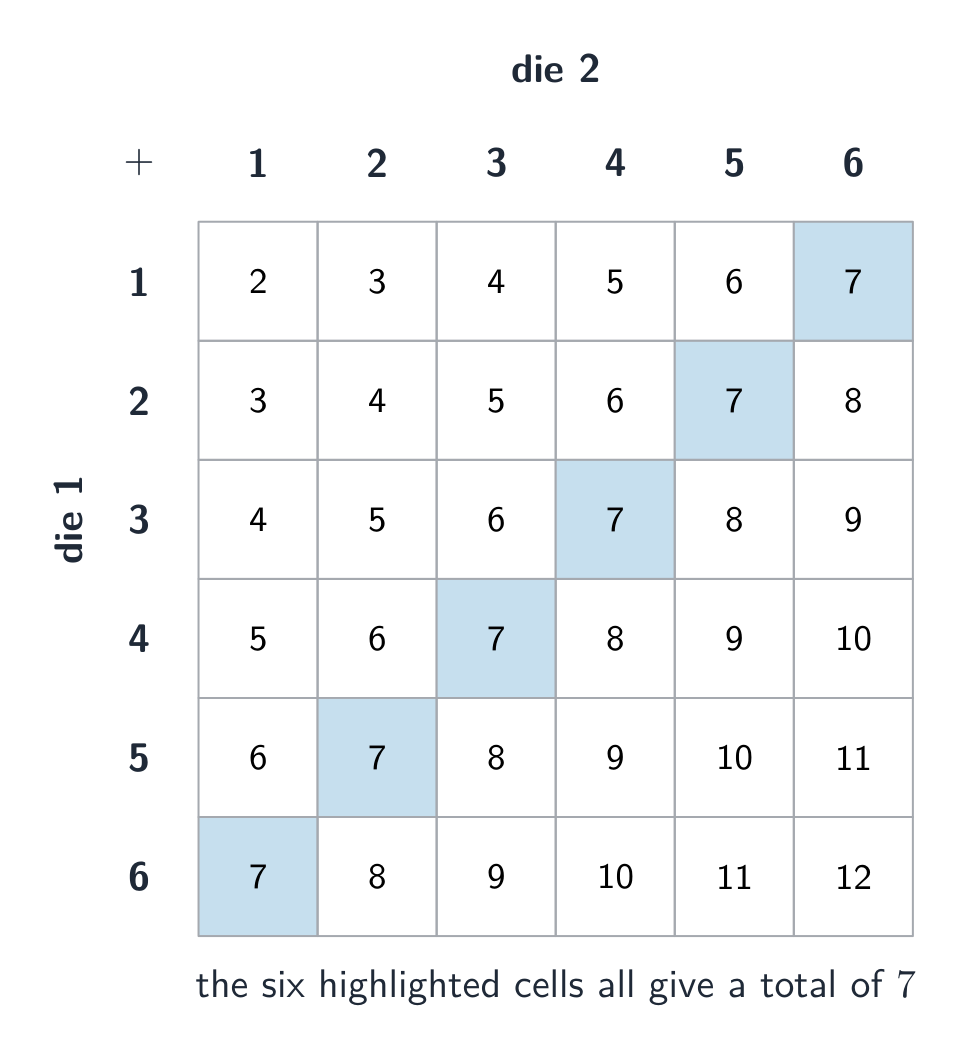
An event: When rolling two six-sided number cubes, an event would be a sum of seven. The corresponding collection of outcomes would be $(1, 6)$, $(2, 5)$, $(3, 4)$, $(4, 3)$, $(5, 2)$, and $(6, 1)$, where the ordered pairs indicate (face value on one cube, face value on the other cube).
한국어
지속적 이해 (UNC-2): 시뮬레이션을 통해 데이터의 패턴을 예측할 수 있습니다.
학습 목표 UNC-2.A: 시뮬레이션을 사용하여 확률을 추정하시오. [기술 3.A]
UNC-2.A.1 무작위 과정은 우연에 의해 결정되는 결과를 산출합니다.
UNC-2.A.2 결과(outcome)는 무작위 과정의 시도(trial)에 따른 결과입니다.
UNC-2.A.3 사건(event)은 결과들의 모임입니다.
UNC-2.A.4 시뮬레이션은 실세계의 결과와 closely matching하는 way로 무작위 사건을 모델링하는 방법입니다. 모든 가능한 결과에는 우연에 의해 결정될 값을 부여합니다. 시뮬레이션된 결과의 빈도와 총 빈도를 기록하십시오.
UNC-2.A.5 시뮬레이션이나 경험적 데이터에서 결과 또는 사건의 상대 빈도는 해당 결과 또는 사건의 확률을 추정하는 데 사용할 수 있다.
UNC-2.A.6 대수의 법칙은 시뮬레이션(경험적) 확률이 시도의 횟수가 증가함에 따라 실제 확률에 가까워진다는 것을 명시한다.
*UNC-2.A에 대한 예시:
결과: 육면체 주사위를 던져 특정 값을 얻는 것은 여섯 가지 가능한 결과 중 하나이다.
사건: 육면체 주사위 두 개를 던질 때, 합이 7이 되는 것이 한 사건이다. 이에 대응하는 결과의 집합은 $(1, 6)$, $(2, 5)$, $(3, 4)$, $(4, 3)$, $(5, 2)$, 그리고 $(6, 1)$이며, 여기서 순서쌍은 (한 주사위의 눈값, 다른 주사위의 눈값)를 나타낸다.
Source: College Board AP Course and Exam Description · 출처: College Board AP Course and Exam Description
A simulation 模拟 imitates a chance process using random digits or technology. Steps: state the model, assign digits to outcomes, run many trials, and record the proportion of trials meeting the condition. The resulting proportion estimates the probability – more trials give a better estimate.
VAR-4
The likelihood of a random event can be quantified.
VAR-4.A
Calculate probabilities for events and their complements. [Skill 3.A]
VAR-4.A.1 The sample space of a random process is the set of all possible non-overlapping outcomes.
VAR-4.A.2 If all outcomes in the sample space are equally likely, then the probability an event E will occur is defined as the fraction: $\dfrac{\text{number of outcomes in event E}}{\text{total number of outcomes in sample space}}$
VAR-4.A.3 The probability of an event is a number between 0 and 1, inclusive.
VAR-4.A.4 The probability of the complement of an event E, $E'$ or $E^{C}$, (i.e., not E) is equal to $1 - P(E)$.
VAR-4.B
Interpret probabilities for events. [Skill 4.B]
VAR-4.B.1 Probabilities of events in repeatable situations can be interpreted as the relative frequency with which the event will occur in the long run.
한국어
Enduring Understanding
Learning Objective
Essential Knowledge
VAR-4
무작위 사건의 발생 가능성을 정량화할 수 있다.
VAR-4.A
사건 및 그 보사의 확률을 계산한다. [Skill 3.A]
VAR-4.A.1 무작위 과정의 표본 공간은 모든 가능한 겹치지 않는 결과들의 집합이다.
VAR-4.A.2 표본 공간의 모든 결과가 동등하게 발생할 가능성이 있다면, 사건 E가 발생할 확률은 다음 분수로 정의된다: $\dfrac{\text{number of outcomes in event E}}{\text{total number of outcomes in sample space}}$
VAR-4.A.3 사건의 확률은 0과 1 사이의 수이며, 양 끝을 포함한다.
VAR-4.A.4 사건 E의 보사건, 즉 $E'$ 또는 $E^{C}$(E가 아닌 경우)의 확률은 $1 - P(E)$과 같다.
VAR-4.B
사건의 확률을 해석한다. [Skill 4.B]
VAR-4.B.1 반복 가능한 상황에서의 사건의 확률은 장기적으로 해당 사건이 발생할 상대 빈도로 해석할 수 있다.
Source: College Board AP Course and Exam Description · 출처: College Board AP Course and Exam Description
The probability 概率 of an event is a number from $0$ to $1$ giving its long-run relative frequency. The sample space 样本空间 is the set of all outcomes. For an event $A$, the complement 补 rule: $P(A^c)=1-P(A)$. Probabilities of all outcomes sum to $1$.
Probability runs from 0 (impossible) to 1 (certain)A deck of cards is a classic source of probability: 52 equally likely outcomes make the chances easy to count
Explore · 탐색하기
Explore probability with dice
Probability is the long-run fraction of times an outcome happens. Roll the dice many times and watch the experimental proportions settle toward the theoretical values.
VAR-4
The likelihood of a random event can be quantified.
VAR-4.C
Explain why two events are (or are not) mutually exclusive. [Skill 4.B]
VAR-4.C.1 The probability that events $A$ and $B$ both will occur, sometimes called the joint probability, is the probability of the intersection of $A$ and $B$, denoted $P(A \cap B)$.
VAR-4.C.2 Two events are mutually exclusive or disjoint if they cannot occur at the same time. So $P(A \cap B) = 0$.
한국어
Enduring Understanding
Learning Objective
Essential Knowledge
VAR-4
무작위 사건의 발생 가능성을 정량화할 수 있다.
VAR-4.C
두 사건이 (또는 하지 않는) 상호 배타적인지 설명한다. [Skill 4.B]
VAR-4.C.1 사건 $A$과 $B$가 모두 발생할 확률, 이를Joint probability라고 하기도 한다. 이는 $A$와 $B$의 교집합의 확률이며, 기호로 $P(A \cap B)$로 표시한다.
VAR-4.C.2 두 사건이 동시에 발생할 수 없으면 상호 배타적이거나 불교차(disjoint)인 것이다. 따라서 $P(A \cap B) = 0$.
Source: College Board AP Course and Exam Description · 출처: College Board AP Course and Exam Description
Two events are mutually exclusive 互斥 (disjoint) if they cannot both happen. Then the addition rule simplifies:
$$P(A\text{ or }B)=P(A)+P(B)\quad(\text{if mutually exclusive}).$$
In general, $P(A\text{ or }B)=P(A)+P(B)-P(A\text{ and }B)$ – subtract the overlap so it is not counted twice.
A Venn diagram: the overlap is the intersection of two events
VAR-4.D.1 The probability that event $A$ will occur given that event $B$ has occurred is called a conditional probability and denoted $P(A \mid B) = \dfrac{P(A \cap B)}{P(B)}$.
VAR-4.D.2 The multiplication rule states that the probability that events $A$ and $B$ both will occur is equal to the probability that event $A$ will occur multiplied by the probability that event $B$ will occur, given that $A$ has occurred. This is denoted $P(A \cap B) = P(A) \cdot P(B \mid A)$.
Source: College Board AP Course and Exam Description · 출처: College Board AP Course and Exam Description
Conditional probability
The conditional probability 条件概率 of $A$ given $B$ is
$$P(A\mid B)=\frac{P(A\text{ and }B)}{P(B)}.$$
It is the chance of $A$ once you know $B$ happened. Two-way tables make these easy: restrict to the row/column for $B$, then find $A$'s share.
On a tree diagram, multiply the probabilities along the branches
Explore · 탐색하기
Update a probability on new information
Conditional probability$P(B\mid A)$ is the chance of $B$ once you know $A$ happened. Change the branch probabilities and watch how conditioning reshapes the outcome.
VAR-4
The likelihood of a random event can be quantified.
VAR-4.E
Calculate probabilities for independent events and for the union of two events. [Skill 3.A]
VAR-4.E.1 Events $A$ and $B$ are independent if, and only if, knowing whether event $A$ has occurred (or will occur) does not change the probability that event $B$ will occur.
VAR-4.E.2 If, and only if, events $A$ and $B$ are independent, then $P(A \mid B) = P(A)$, $P(B \mid A) = P(B)$, and $P(A \cap B) = P(A) \cdot P(B)$.
VAR-4.E.3 The probability that event $A$ or event $B$ (or both) will occur is the probability of the union of $A$ and $B$, denoted $P(A \cup B)$.
VAR-4.E.4 The addition rule states that the probability that event $A$ or event $B$ or both will occur is equal to the probability that event $A$ will occur plus the probability that event $B$ will occur minus the probability that both events $A$ and $B$ will occur. This is denoted $P(A \cup B) = P(A) + P(B) - P(A \cap B)$.
한국어
Enduring Understanding
Learning Objective
Essential Knowledge
VAR-4
무작위 사건의 발생 가능성을 정량화할 수 있다.
VAR-4.E
독립 사건의 확률과 두 사건의 합집합에 대한 확률을 계산한다. [Skill 3.A]
VAR-4.E.1 사건 $A$과 $B$는 사건 $A$이 발생했는지(또는 발생할 것인지를) 알고 있더라도 사건 $B$이 발생할 확률이 변하지 않는다면, 그리고 오직 그러한 경우에만 서로 독립이다.
VAR-4.E.2 사건 $A$과 $B$가 독립일 때, 그리고 오직 그럴 때만 $P(A \mid B) = P(A)$, $P(B \mid A) = P(B)$, 그리고 $P(A \cap B) = P(A) \cdot P(B)$이다.
VAR-4.E.3 사건 $A$ 또는 사건 $B$(또는 두 사건 모두)가 발생할 확률은 $A$과 $B$의 합집합 확률이며, 이를 $P(A \cup B)$로 표기한다.
VAR-4.E.4 덧의 법칙은 사건 $A$ 또는 사건 $B$ 또는 둘 다 발생할 확률이 사건 $A$가 발생할 확률에 사건 $B$이 발생할 확률을 더하고, 사건 $A$과 $B$가 모두 발생할 확률을 뺀 값과 같다는 것을 명시한다. 이를 기호로 $P(A \cup B) = P(A) + P(B) - P(A \cap B)$로 표시한다.
Source: College Board AP Course and Exam Description · 출처: College Board AP Course and Exam Description
Events are independent 独立 if knowing one does not change the other's probability: $P(A\mid B)=P(A)$. Then the multiplication rule simplifies:
$$P(A\text{ and }B)=P(A)\,P(B)\quad(\text{if independent}).$$
Independent is not the same as mutually exclusive – mutually exclusive events with nonzero probability are actually dependent (if one happens, the other cannot).
A sample space diagram lists every equally likely outcome
Explore · 탐색하기
Combine events with a Venn diagram
For a union$P(A\cup B)=P(A)+P(B)-P(A\cap B)$ — you subtract the overlap so it isn't counted twice. Switch the operation to see each region light up.
VAR-5
Probability distributions may be used to model variation in populations.
VAR-5.A
Represent the probability distribution for a discrete random variable. [Skill 2.B]
VAR-5.A.1 The values of a random variable are the numerical outcomes of random behavior.
VAR-5.A.2 A discrete random variable is a variable that can only take a countable number of values. Each value has a probability associated with it. The sum of the probabilities over all of the possible values must be 1.
VAR-5.A.3 A probability distribution can be represented as a graph, table, or function showing the probabilities associated with values of a random variable.
VAR-5.A.4 A cumulative probability distribution can be represented as a table or function showing the probability of being less than or equal to each value of the random variable.
Illustrative examples for VAR-5.A: Outcomes of trials of a random process:
The sum of the outcomes for rolling two dice
The number of puppies in a randomly selected litter for a certain breed of dog
VAR-5.B
Interpret a probability distribution. [Skill 4.B]
VAR-5.B.1 An interpretation of a probability distribution provides information about the shape, center, and spread of a population and allows one to make conclusions about the population of interest.
한국어
Enduring Understanding
Learning Objective
Essential Knowledge
VAR-5
확률 분포는 집단 내 변동성을 모델링하는 데 사용될 수 있다.
VAR-5.A
이산 무작위 변수에 대한 확률 분포를 표현한다. [Skill 2.B]
VAR-5.A.1 무작위 변수의 값은 무작위 행위의 수치적 결과물이다.
VAR-5.A.2 이산 무작위 변수는 세어낼 수 있는 유한하거나 가산 무한개의 값만을 취할 수 있는 변수이다. 각 값에는 확률이 할당되어 있으며, 모든 가능한 값에 대한 확률의 합은 1이어야 한다.
VAR-5.A.3 확률 분포는 무작위 변수의 값에 associated된 확률을 보여주는 그래프, 표, 또는 함수로 표현될 수 있다.
VAR-5.A.4 누적 확률 분포는 무작위 변수의 각 값 이하의 확률을 보여주는 표나 함수로 표현될 수 있다.
*VAR-5.A에 대한 예시: 무작위 과정의 시뮬레이션 결과:
육面体 주사위 두 개를 던졌을 때의 눈의 합
특정 품종의 개에서 랜덤하게 선택된 한 마리의 새끼 수
VAR-5.B
확률 분포를 해석한다. [Skill 4.B]
VAR-5.B.1 확률 분포의 해석은 집단의 형태, 중심, 산포에 대한 정보를 제공하며, 관심 있는 집단에 대한 결론을 도출할 수 있게 한다.
Source: College Board AP Course and Exam Description · 출처: College Board AP Course and Exam Description
A random variable 随机变量 assigns a number to each outcome of a chance process. A probability distribution 概率分布 lists each possible value with its probability (they sum to $1$). A distribution can be discrete (a table of values) or continuous (an area-under-a-curve model like the normal).
probability distribution/ˌprɒbəˈbɪlɪti ˌdɪstrɪˈbjuːʃn/
확률 분포
4.8
Mean and Standard Deviation of Random Variables
Syllabus
English
Enduring Understanding
Learning Objective
Essential Knowledge
VAR-5
Probability distributions may be used to model variation in populations.
VAR-5.C
Calculate parameters for a discrete random variable. [Skill 3.B]
VAR-5.C.1 A numerical value measuring a characteristic of a population or the distribution of a random variable is known as a parameter, which is a single, fixed value.
VAR-5.C.2 The mean, or expected value, for a discrete random variable $X$ is $\mu_X = \sum x_i \cdot P(x_i)$.
VAR-5.C.3 The standard deviation for a discrete random variable $X$ is $\sigma_X = \sqrt{\sum (x_i - \mu_x)^2 \cdot P(x_i)}$.
VAR-5.D
Interpret parameters for a discrete random variable. [Skill 4.B]
VAR-5.D.1 Parameters for a discrete random variable should be interpreted using appropriate units and within the context of a specific population.
한국어
Enduring Understanding
Learning Objective
Essential Knowledge
VAR-5
확률 분포는 집단 내 변동성을 모델링하는 데 사용될 수 있다.
VAR-5.C
이산 무작위 변수에 대한 매개변수를 계산한다. [Skill 3.B]
VAR-5.C.1 집단의 특성이나 무작위 변수의 분포를 측정하는 수치적 값을 매개변수 parameter라 하며, 이는 단일且 고정된 값이다.
VAR-5.C.2 이산 무작위 변수 $X$의 평균, 즉 기대값 expected value은 $\mu_X = \sum x_i \cdot P(x_i)$이다.
VAR-5.D.1 이산 확률변수의 모는 적절한 단위와 특정 집단의 맥락 내에서 해석되어야 합니다.
Source: College Board AP Course and Exam Description · 출처: College Board AP Course and Exam Description
The mean (expected value) 期望值 of a discrete random variable is the probability-weighted average:
$$\mu_X=E(X)=\sum x_i\,P(x_i).$$
The standard deviation$\sigma_X=\sqrt{\sum (x_i-\mu_X)^2\,P(x_i)}$ measures typical spread from the mean. The expected value is the long-run average outcome, not a value you expect on any single trial.
Worked example. A game pays $\$5$ with probability $0.2$ and costs you $\$1$ (a $-1$ outcome) with probability $0.8$. The expected value is
$$E(X)=5(0.2)+(-1)(0.8)=1-0.8=\$0.20,$$
so over many plays you gain about $20$ cents per play on average, even though no single play gives exactly that.
VAR-5
Probability distributions may be used to model variation in populations.
VAR-5.E
Calculate parameters for linear combinations of random variables. [Skill 3.B]
VAR-5.E.1 For random variables $X$ and $Y$ and real numbers $a$ and $b$, the mean of $aX + bY$ is $a\mu_x + b\mu_y$.
VAR-5.E.2 Two random variables are independent if knowing information about one of them does not change the probability distribution of the other.
VAR-5.E.3 For independent random variables $X$ and $Y$ and real numbers $a$ and $b$, the mean of $aX + bY$ is $a\mu_x + b\mu_y$, and the variance of $aX + bY$ is $a^2\sigma^2_x + b^2\sigma^2_y$.
VAR-5.F
Describe the effects of linear transformations of parameters of random variables. [Skill 3.C]
VAR-5.F.1 For $Y = a + bX$, the probability distribution of the transformed random variable, $Y$, has the same shape as the probability distribution for $X$, so long as $a > 0$ and $b > 0$. The mean of $Y$ is $\mu_y = a + b\mu_x$. The standard deviation of $Y$ is $\sigma_y = |b|\sigma_x$.
Source: College Board AP Course and Exam Description · 출처: College Board AP Course and Exam Description
When you add or subtract random variables, means add: $\mu_{X\pm Y}=\mu_X\pm\mu_Y$. If $X$ and $Y$ are independent, variances add (even when subtracting):
$$\sigma^2_{X\pm Y}=\sigma^2_X+\sigma^2_Y.$$
Take the square root for the standard deviation. Also, scaling: $\mu_{aX+b}=a\mu_X+b$ and $\sigma_{aX+b}=|a|\sigma_X$.
4.10
Introduction to the Binomial Distribution
Syllabus
Enduring Understanding
Learning Objective
Essential Knowledge
UNC-3
Probabilistic reasoning allows us to anticipate patterns in data.
UNC-3.A
Estimate probabilities of binomial random variables using data from a simulation. [Skill 3.A]
UNC-3.A.1 A probability distribution can be constructed using the rules of probability or estimated with a simulation using random number generators.
UNC-3.A.2 A binomial random variable, $X$, counts the number of successes in $n$ repeated independent trials, each trial having two possible outcomes (success or failure), with the probability of success $p$ and the probability of failure $1 - p$.
UNC-3.B
Calculate probabilities for a binomial distribution. [Skill 3.A]
UNC-3.B.1 The probability that a binomial random variable, $X$, has exactly $x$ successes for $n$ independent trials, when the probability of success is $p$, is calculated as $P(X = x) = \binom{n}{x} p^x (1 - p)^{n-x}, x = 0, 1, 2, \ldots, n$. This is the binomial probability function.
Source: College Board AP Course and Exam Description · 출처: College Board AP Course and Exam Description
The binomial distribution
A binomial 二项 setting (BINS): a fixed number $n$ of Independent trials, each with two outcomes (success/failure) and the same success probability $p$. The random variable $X=$ number of successes. Its probability:
$$P(X=k)=\binom{n}{k}p^k(1-p)^{n-k}.$$
The binomial distribution, with mean n times p
Explore · 탐색하기
Shape a binomial distribution
A binomial distribution counts successes in $n$ independent trials each with probability $p$. Change $n$ and $p$ and watch the bars shift and spread.
Enduring Understanding (UNC-3): Probabilistic reasoning allows us to anticipate patterns in data.
Learning Objective UNC-3.C: Calculate parameters for a binomial distribution. [Skill 3.B]
UNC-3.C.1 If a random variable is binomial, its mean, $\mu_x$, is $np$ and its standard deviation, $\sigma_x$, is $\sqrt{np(1 - p)}$.
Learning Objective UNC-3.D: Interpret probabilities and parameters for a binomial distribution. [Skill 4.B]
UNC-3.D.1 Probabilities and parameters for a binomial distribution should be interpreted using appropriate units and within the context of a specific population or situation.
한국어
지속적 이해 (UNC-3): 확률적 추론을 통해 데이터의 패턴을 예측할 수 있습니다.
학습 목표 UNC-3.C: 이항 분포의 모수를 계산하시오. [기술 3.B]
UNC-3.C.1 무작변수가 이항 분포를 따를 때, 평균 $\mu_x$는 $np$이고 표준편차 $\sigma_x$는 $\sqrt{np(1 - p)}$입니다.
학습 목표 UNC-3.D: 이항 분포에 대한 확률과 모수를 해석하시오. [기술 4.B]
UNC-3.D.1 이항 분포의 확률과 모수는 적절한 단위와 특정 집단이나 상황의 맥락 내에서 해석되어야 합니다.
Source: College Board AP Course and Exam Description · 출처: College Board AP Course and Exam Description
For a binomial $X$ with $n$ trials and success probability $p$:
$$\mu_X=np,\qquad \sigma_X=\sqrt{np(1-p)}.$$
Use these for "how many successes do we expect, and how much do they vary" questions.
Worked example. A player makes $70\%$ of free throws. In $n=10$ shots, the probability of exactly $8$ makes is
and the expected number of makes is $\mu=np=10(0.7)=7$, with $\sigma=\sqrt{10(0.7)(0.3)}\approx1.45$.
4.12
The Geometric Distribution
Syllabus
English
Enduring Understanding (UNC-3): Probabilistic reasoning allows us to anticipate patterns in data.
Learning Objective UNC-3.E: Calculate probabilities for geometric random variables. [Skill 3.A]
UNC-3.E.1 For a sequence of independent trials, a geometric random variable, $X$, gives the number of the trial on which the first success occurs. Each trial has two possible outcomes (success or failure) with the probability of success $p$ and the probability of failure $1 - p$.
UNC-3.E.2 The probability that the first success for repeated independent trials with probability of success $p$ occurs on trial $x$ is calculated as $P(X = x) = (1 - p)^{x-1} p, x = 1, 2, 3, \ldots$. This is the geometric probability function.
Learning Objective UNC-3.F: Calculate parameters of a geometric distribution. [Skill 3.B]
UNC-3.F.1 If a random variable is geometric, its mean, $\mu_x$, is $\dfrac{1}{p}$ and its standard deviation, $\sigma_x$, is $\dfrac{\sqrt{(1 - p)}}{p}$.
Learning Objective UNC-3.G: Interpret probabilities and parameters for a geometric distribution. [Skill 4.B]
UNC-3.G.1 Probabilities and parameters for a geometric distribution should be interpreted using appropriate units and within the context of a specific population or situation.
한국어
지속적 이해 (UNC-3): 확률적 추론을 통해 데이터의 패턴을 예측할 수 있습니다.
학습 목표 UNC-3.E: 기하 무작변수에 대한 확률을 계산하시오. [기술 3.A]
UNC-3.E.1 독립 시도의 연쇄에서, 기하 무작변수 $X$는 첫 성공이 발생하는 시도의 순위를 나타냅니다. 각 시도는 두 가지 가능한 결과(성공 또는 실패)를 가지며 성공 확률이 $p$, 실패 확률이 $1 - p$입니다.
UNC-3.E.2 성공 확률이 $p$인 반복된 독립 시도에서 첫 성공이 $x$번째 시도에서 발생할 확률은 $P(X = x) = (1 - p)^{x-1} p, x = 1, 2, 3, \ldots$로 계산됩니다. 이것이 기하 확률 함수입니다.
학습 목표 UNC-3.F: 기하 분포의 모수를 계산하시오. [기술 3.B]
UNC-3.F.1 확률변수가 기하 분포를 따를 경우, 그 평균 $\mu_x$은 $\dfrac{1}{p}$이고 표준편차 $\sigma_x$은 $\dfrac{\sqrt{(1 - p)}}{p}$이다.
학습 목표 UNC-3.G: 기하 분포에 대한 확률과 모수를 해석하시오. [기술 4.B]
UNC-3.G.1 기하 분포의 확률과 모수는 적절한 단위와 특정 집단이나 상황의 맥락 내에서 해석되어야 합니다.
Source: College Board AP Course and Exam Description · 출처: College Board AP Course and Exam Description
A geometric 几何 setting is the same as binomial but with no fixed $n$: you keep trying until the first success. The random variable $Y=$ the trial of the first success:
Enduring Understanding (VAR-1): Given that variation may be random or not, conclusions are uncertain.
Learning Objective VAR-1.G: Identify questions suggested by variation in statistics for samples collected from the same population. [Skill 1.A]
VAR-1.G.1 Variation in statistics for samples taken from the same population may be random or not.
한국어
지속적 이해 (VAR-1): 변동성이 우연일 수도 있고 그렇지 않을 수도 있으므로, 결론은 불확실할 수 있다.
학습목표 VAR-1.G: 동일한 집단에서 수집된 표본의 통계적 변동성으로 인해 제기되는 질문을 식별하기. [기술 1.A]
VAR-1.G.1 동일한 집단에서 추출한 표본의 통계적 변동성은 무작위일 수도 있고 그렇지 않을 수도 있습니다.
Source: College Board AP Course and Exam Description · 출처: College Board AP Course and Exam Description
A statistic 统计量 (like a sample mean $\bar{x}$ or sample proportion $\hat{p}$) is computed from a sample and varies from sample to sample – this is sampling variability 抽样变异. A parameter 参数 ($\mu$ or $p$) is the fixed truth about the population. The sampling distribution 抽样分布 is the distribution of a statistic over all possible samples of a given size – it is the bridge from one sample to inference.
VAR-6
The normal distribution may be used to model variation.
VAR-6.A
Calculate the probability that a particular value lies in a given interval of a normal distribution. [Skill 3.A]
VAR-6.A.1 A continuous random variable is a variable that can take on any value within a specified domain. Every interval within the domain has a probability associated with it.
VAR-6.A.2 A continuous random variable with a normal distribution is commonly used to describe populations. The distribution of a normal random variable can be described by a normal, or "bell-shaped," curve.
VAR-6.A.3 The area under a normal curve over a given interval represents the probability that a particular value lies in that interval.
Illustrative examples for VAR-6.A: Continuous random variable: If one looks at a clock at a random time, the probability that the minute hand is between the 3 and the 6 is one fourth.
VAR-6.B
Determine the interval associated with a given area in a normal distribution. [Skill 3.A]
VAR-6.B.1 The boundaries of an interval associated with a given area in a normal distribution can be determined using $z$-scores or technology, such as a calculator, a standard normal table, or computer-generated output.
VAR-6.B.2 Intervals associated with a given area in a normal distribution can be determined by assigning appropriate inequalities to the boundaries of the intervals:
a. $P(X < x_a) = \dfrac{p}{100}$ means that the lowest $p\%$ of values lie to the left of $x_a$.
b. $P(x_a < X < x_b) = \dfrac{p}{100}$ means that $p\%$ of values lie between $x_a$ and $x_b$.
c. $P(X > x_b) = \dfrac{p}{100}$ means that the highest $p\%$ of values lie to the right of $x_b$.
d. To determine the most extreme $p\%$ of values requires dividing the area associated with $p\%$ into two equal areas on either extreme of the distribution: $P(X < x_a) = \dfrac{1}{2}\dfrac{p}{100}$ and $P(X > x_b) = \dfrac{1}{2}\dfrac{p}{100}$ means that half of the $p\%$ most extreme values lie to the left of $x_a$ and half of the $p\%$ most extreme values lie to the right of $x_b$.
VAR-6.C
Determine the appropriateness of using the normal distribution to approximate probabilities for unknown distributions. [Skill 3.C]
VAR-6.C.1 Normal distributions are symmetrical and "bell-shaped." As a result, normal distributions can be used to approximate distributions with similar characteristics.
Source: College Board AP Course and Exam Description · 출처: College Board AP Course and Exam Description
The normal distribution
For large enough samples, many sampling distributions are approximately normal. That lets us describe a statistic by a center (its mean), a spread (its standard error 标准误), and a normal shape – and then compute how likely a given sample result is.
Explore · 탐색하기
Use the normal curve to find a proportion · 정규 곡선을 사용하여 비율 구하기
A normal model turns a range of values into an area = a proportion. Shade a band to read off the fraction of samples falling within it (the 68-95-99.7 rule). · 표준(정규) 모델은 값의 범위를 면적 = 비율로 변환합니다. 영역을 채워 해당 구간에 포함되는 표본의 분율을 읽으세요 (68-95-99.7 법칙).
Enduring Understanding (UNC-3): Probabilistic reasoning allows us to anticipate patterns in data.
Learning Objective UNC-3.H: Estimate sampling distributions using simulation. [Skill 3.C]
UNC-3.H.1 A sampling distribution of a statistic is the distribution of values for the statistic for all possible samples of a given size from a given population.
UNC-3.H.2 The central limit theorem (CLT) states that when the sample size is sufficiently large, a sampling distribution of the mean of a random variable will be approximately normally distributed.
UNC-3.H.3 The central limit theorem requires that the sample values are independent of each other and that $n$ is sufficiently large.
UNC-3.H.4 A randomization distribution is a collection of statistics generated by simulation assuming known values for the parameters. For a randomized experiment, this means repeatedly randomly reallocating/reassigning the response values to treatment groups.
UNC-3.H.5 The sampling distribution of a statistic can be simulated by generating repeated random samples from a population.
한국어
지속적 이해 (UNC-3): 확률적 추론을 통해 데이터의 패턴을 예측할 수 있습니다.
학습목표 UNC-3.H: 시뮬레이션을 통해 추론분포를 추정하기. [기술 3.C]
UNC-3.H.1 통계량의 추론분포는 주어진 집단에서 주어진 크기의 모든 가능한 표본에 대한 해당 통계값들의 분포입니다.
UNC-3.H.2 중심극한정리(CLT)는 표본 크기가 충분히 클 때, 확률변수의 평균에 대한 추론분포가 대략적으로 정규분포를 따른다고 명시합니다.
UNC-3.H.3 중심극한정리는 표본 값들이 서로 독립적이어야 하며, $n$이 충분히 커야 함을 요구합니다.
UNC-3.H.4 무작위화 분포는 모에 대한 알려진 값을 가정하여 시뮬레이션으로 생성된 통계량의 모음입니다. 무작위 실험의 경우 이는 반응값을 treatment 그룹에 반복적으로 무작위로 재배분/재할당하는 것을 의미합니다.
UNC-3.H.5 통계량의 추론분포는 집단으로부터 반복된 무작위 표본을 생성함으로써 시뮬레이션할 수 있습니다.
Source: College Board AP Course and Exam Description · 출처: College Board AP Course and Exam Description
The Central Limit Theorem
The Central Limit Theorem 中心极限定理 (CLT): for a sample mean, if the sample size $n$ is large enough (a common rule is $n\ge 30$), the sampling distribution of $\bar{x}$ is approximately normal, regardless of the population's shape. The larger $n$, the more normal and the tighter the distribution.
The sample mean is nearly normal whatever the shape of the population
Explore · 탐색하기
Watch a sampling distribution turn normal · 표본 분포가 정규 분포로 변하는 과정 보기
The Central Limit Theorem: for a large enough sample, the distribution of the sample mean is approximately normal — whatever the shape of the population. · 중심극한정리: 표본 크기가 충분히 크면, 모집단의 형태와 상관없이 표본 평균의 분포는 근사적으로 ** 정규분포**를 따릅니다.
Enduring Understanding (UNC-3): Probabilistic reasoning allows us to anticipate patterns in data.
Learning Objective UNC-3.I: Explain why an estimator is or is not unbiased. [Skill 4.B]
UNC-3.I.1 When estimating a population parameter, an estimator is unbiased if, on average, the value of the estimator is equal to the population parameter.
Learning Objective UNC-3.J: Calculate estimates for a population parameter. [Skill 3.B]
UNC-3.J.1 When estimating a population parameter, an estimator exhibits variability that can be modeled using probability.
UNC-3.J.2 A sample statistic is a point estimator of the corresponding population parameter.
한국어
지속적 이해 (UNC-3): 확률적 추론을 통해 데이터의 패턴을 예측할 수 있습니다.
학습목표 UNC-3.I: 추정치가 편향되거나 편향되지 않은 이유를 설명하기. [기술 4.B]
UNC-3.I.1 집단의 모를 추정할 때, 추정치의 평균값이 집단의 모와 같다면 그 추정치는 편향되지 않습니다(unbiased).
학습목표 UNC-3.J: 집단의 모에 대한 추정치를 계산하기. [기술 3.B]
UNC-3.J.1 모수 추정을 위해 사용된 추정량이 확률로 모델링할 수 있는 변이성을 나타낼 때, 이를 sampling distribution으로 설명할 수 있다.
UNC-3.J.2 표본 통계량은 해당 모수 point estimator이다.
Source: College Board AP Course and Exam Description · 출처: College Board AP Course and Exam Description
A statistic is unbiased 无偏 if the mean of its sampling distribution equals the parameter – it is correct on average. Bias is about the center being off; variability is about the spread. A good estimator is both unbiased (centered right) and low-variability (precise); larger samples reduce variability but do not fix bias from bad sampling.
Bias and variability are separate faults. Only the top-left estimator is both centered on $\theta$ and tight; the bottom-left one is precise but consistently wrong, which no amount of extra data will fix.
Enduring Understanding (UNC-3): Probabilistic reasoning allows us to anticipate patterns in data.
Learning Objective UNC-3.K: Determine parameters of a sampling distribution for sample proportions. [Skill 3.B]
UNC-3.K.1 For independent samples (sampling with replacement) of a categorical variable from a population with population proportion, $p$, the sampling distribution of the sample proportion, $\hat{p}$, has a mean, $\mu_{\hat{p}} = p$ and a standard deviation, $\sigma_{\hat{p}} = \sqrt{\dfrac{p(1-p)}{n}}$.
UNC-3.K.2 If sampling without replacement, the standard deviation of the sample proportion is smaller than what is given by the formula above. If the sample size is less than 10% of the population size, the difference is negligible.
Learning Objective UNC-3.L: Determine whether a sampling distribution for a sample proportion can be described as approximately normal. [Skill 3.C]
UNC-3.L.1 For a categorical variable, the sampling distribution of the sample proportion, $\hat{p}$, will have an approximate normal distribution, provided the sample size is large enough: $np \geq 10$ and $n(1-p) \geq 10$
Learning Objective UNC-3.M: Interpret probabilities and parameters for a sampling distribution for a sample proportion. [Skill 4.B]
UNC-3.M.1 Probabilities and parameters for a sampling distribution for a sample proportion should be interpreted using appropriate units and within the context of a specific population.
한국어
지속적 이해 (UNC-3): 확률적 추론을 통해 데이터의 패턴을 예측할 수 있습니다.
학습 목표 UNC-3.K: 표본 비율의 표본 분포의 모수를 결정한다. [기술 3.B]
UNC-3.K.1 모비율이 $p$인 모집단에서 범주형 변수에 대해 독립 표본(교체抽样)을 취할 때, 표본 비율 $\hat{p}$의 표본 분포는 평균 $\mu_{\hat{p}} = p$과 표준편차 $\sigma_{\hat{p}} = \sqrt{\dfrac{p(1-p)}{n}}$을 가진다.
UNC-3.K.2 교체가 없는sampling을 할 경우, 표본 비율의 표준편차는 위 공식으로 계산된 값보다 작다. 단, 표본 크기가 모집단의 10% 미만일 경우 그 차이는 무시할 수 있다.
학습 목표 UNC-3.L: 표본 비율의 표본 분포가 근사 정규분포로 기술될 수 있는지 판단한다. [기술 3.C]
UNC-3.L.1 범주형 변수에 대해 표본 비율 $\hat{p}$의 표본 분포는 표본 크기가 충분히 클 때 근사 정규분포를 따르며, 이 조건은 $np \geq 10$ 및 $n(1-p) \geq 10$이다.
학습 목표 UNC-3.M: 표본 비율의 표본 분포에 대한 확률과 모수를 해석한다. [기술 4.B]
UNC-3.M.1 표본 비율의 표본 분포에 대한 확률과 모수는 적절한 단위와 특정 모집단의 맥락 내에서 해석되어야 한다.
Source: College Board AP Course and Exam Description · 출처: College Board AP Course and Exam Description
For a sample proportion $\hat{p}$ from an SRS: the mean is $p$ (unbiased), and the standard deviation is
$$\sigma_{\hat p}=\sqrt{\frac{p(1-p)}{n}}.$$
This spread has two names: it is the standard deviation of the sampling distribution, and it is called the standard error once you must estimate it from the sample (replacing $p$ by $\hat p$) — which is exactly what the later inference units do.
It is approximately normal when $np\ge 10$ and $n(1-p)\ge 10$ (the Large Counts condition), and the $10\%$ condition ($n\le 0.10N$) keeps the observations near-independent.
Worked example. Suppose $40\%$ of voters favor a measure ($p=0.4$) and you sample $n=100$. The standard error is $\sigma_{\hat p}=\sqrt{\dfrac{0.4(0.6)}{100}}=0.049$. The chance a sample gives $\hat{p}>0.5$ is $z=\dfrac{0.5-0.4}{0.049}=2.04$, so $P(\hat p>0.5)\approx0.02$ – a majority in the sample would be surprising.
5.6
Comparing Two Groups: Difference of Sample Proportions
Syllabus
English
Enduring Understanding (UNC-3): Probabilistic reasoning allows us to anticipate patterns in data.
Learning Objective UNC-3.N: Determine parameters of a sampling distribution for a difference in sample proportions. [Skill 3.B]
UNC-3.N.1 For a categorical variable, when randomly sampling with replacement from two independent populations with population proportions $p_1$ and $p_2$, the sampling distribution of the difference in sample proportions $\hat{p}_1 - \hat{p}_2$ has mean, $\mu_{\hat{p}_1 - \hat{p}_2} = p_1 - p_2$ and standard deviation, $\sigma_{\hat{p}_1 - \hat{p}_2} = \sqrt{\dfrac{p_1(1-p_1)}{n_1} + \dfrac{p_2(1-p_2)}{n_2}}$.
UNC-3.N.2 If sampling without replacement, the standard deviation of the difference in sample proportions is smaller than what is given by the formula above. If the sample sizes are less than 10% of the population sizes, the difference is negligible.
Learning Objective UNC-3.O: Determine whether a sampling distribution for a difference of sample proportions can be described as approximately normal. [Skill 3.C]
UNC-3.O.1 The sampling distribution of the difference in sample proportions $\hat{p}_1 - \hat{p}_2$ will have an approximate normal distribution provided the sample sizes are large enough: $n_1 p_1 \geq 10, n_1(1-p_1) \geq 10, n_2 p_2 \geq 10, n_2(1-p_2) \geq 10$.
Learning Objective UNC-3.P: Interpret probabilities and parameters for a sampling distribution for a difference in proportions. [Skill 4.B]
UNC-3.P.1 Parameters for a sampling distribution for a difference of proportions should be interpreted using appropriate units and within the context of a specific populations.
한국어
지속적 이해 (UNC-3): 확률적 추론을 통해 데이터의 패턴을 예측할 수 있습니다.
학습 목표 UNC-3.N: 표본 비율 차이의 표본 분포의 모수를 결정한다. [기술 3.B]
UNC-3.N.1 범주형 변수에 대해 모비율이 각각 $p_1$과 $p_2$인 두 독립적인 모집단에서 교체抽样을 통해 무작위로 표본을 취할 때, 표본 비율 차이 $\hat{p}_1 - \hat{p}_2$의 표본 분포는 평균 $\mu_{\hat{p}_1 - \hat{p}_2} = p_1 - p_2$과 표준편차 $\sigma_{\hat{p}_1 - \hat{p}_2} = \sqrt{\dfrac{p_1(1-p_1)}{n_1} + \dfrac{p_2(1-p_2)}{n_2}}$을 가진다.
UNC-3.N.2 교체가 없는sampling을 할 경우, 표본 비율 차이의 표준편차는 위 공식으로 계산된 값보다 작다. 단, 각 표본 크기가 해당 모집단의 10% 미만일 경우 그 차이는 무시할 수 있다.
학습 목표 UNC-3.O: 표본 비율 차이의 표본 분포가 근사 정규분포로 기술될 수 있는지 판단한다. [기술 3.C]
It is approximately normal when the Large Counts condition holds in both samples.
5.7
The Sampling Distribution of a Sample Mean
Syllabus
English
Enduring Understanding (UNC-3): Probabilistic reasoning allows us to anticipate patterns in data.
Learning Objective UNC-3.Q: Determine parameters for a sampling distribution for sample means. [Skill 3.B]
UNC-3.Q.1 For a numerical variable, when random sampling with replacement from a population with mean $\mu$ and standard deviation, $\sigma$, the sampling distribution of the sample mean has mean $\mu_{\bar{x}} = \mu$ and standard deviation $\sigma_{\bar{x}} = \dfrac{\sigma}{\sqrt{n}}$.
UNC-3.Q.2 If sampling without replacement, the standard deviation of the sample mean is smaller than what is given by the formula above. If the sample size is less than 10% of the population size, the difference is negligible.
Learning Objective UNC-3.R: Determine whether a sampling distribution of a sample mean can be described as approximately normal. [Skill 3.C]
UNC-3.R.1 For a numerical variable, if the population distribution can be modeled with a normal distribution, the sampling distribution of the sample mean, $\bar{x}$, can be modeled with a normal distribution.
UNC-3.R.2 For a numerical variable, if the population distribution cannot be modeled with a normal distribution, the sampling distribution of the sample mean, $\bar{x}$, can be modeled approximately by a normal distribution, provided the sample size is large enough, e.g., greater than or equal to 30.
Learning Objective UNC-3.S: Interpret probabilities and parameters for a sampling distribution for a sample mean. [Skill 4.B]
UNC-3.S.1 Probabilities and parameters for a sampling distribution for a sample mean should be interpreted using appropriate units and within the context of a specific population.
한국어
지속적 이해 (UNC-3): 확률적 추론을 통해 데이터의 패턴을 예측할 수 있습니다.
학습 목표 UNC-3.Q: 표본 평균의 표본 분포에 대한 모수를 결정한다. [기술 3.B]
UNC-3.Q.1 평균이 $\mu$이고 표준편차가 $\sigma$인 모집단에서 수치형 변수에 대해 교체抽样을 통해 무작위로 표본을 취할 때, 표본 평균의 표본 분포는 평균 $\mu_{\bar{x}} = \mu$과 표준편차 $\sigma_{\bar{x}} = \dfrac{\sigma}{\sqrt{n}}$을 가진다.
UNC-3.Q.2 교체가 없는sampling을 할 경우, 표본 평균의 표준편차는 위 공식으로 계산된 값보다 작다. 단, 표본 크기가 모집단의 10% 미만일 경우 그 차이는 무시할 수 있다.
학습 목표 UNC-3.R: 표본 평균의 표본 분포가 근사 정규분포로 기술될 수 있는지 판단한다. [기술 3.C]
UNC-3.R.1 수치형 변수에 대해 모집단 분포가 정규분포로 모델링될 수 있다면, 표본 평균 $\bar{x}$의 표본 분포 역시 정규분포로 모델링할 수 있다.
UNC-3.R.2 수치형 변수에 대해 모집단 분포가 정규분포로 모델링되지 않는다면, 표본 평균 $\bar{x}$의 표본 분포는 표본 크기가 충분히 클 때(예: 30 이상) 근사 정규분포로 모델링할 수 있다.
학습 목표 UNC-3.S: 표본 평균의 표본 분포에 대한 확률과 모수를 해석한다. [기술 4.B]
UNC-3.S.1 표본 평균의 표본 분포에 대한 확률과 모수는 적절한 단위와 특정 모집단의 맥락 내에서 해석되어야 한다.
Source: College Board AP Course and Exam Description · 출처: College Board AP Course and Exam Description
For a sample mean $\bar{x}$ from an SRS: the mean is $\mu$ (unbiased), and the standard deviation is
$$\sigma_{\bar x}=\frac{\sigma}{\sqrt{n}}.$$
Its shape is normal if the population is normal, or approximately normal for large $n$ by the CLT. Note the spread shrinks like $\sqrt{n}$ – quadrupling the sample halves the standard error.
Worked example. A population has $\mu=70$ and $\sigma=12$. For samples of $n=36$, the sampling distribution of $\bar{x}$ is centered at $70$ with standard error $\dfrac{12}{\sqrt{36}}=2$. The chance a sample mean exceeds $73$ is $z=\dfrac{73-70}{2}=1.5$, so $P(\bar x>73)\approx0.067$.
The population on the left is strongly skewed, yet every sampling distribution of $\bar{x}$ is centered at $\mu$. A larger $n$ shrinks the standard error $\sigma/\sqrt{n}$, so the curve gets taller and narrower – and it also straightens: still clearly skewed at $n=2$, almost exactly normal (dashed) by $n=30$.
5.8
Comparing Two Groups: Difference of Sample Means
Syllabus
English
Enduring Understanding (UNC-3): Probabilistic reasoning allows us to anticipate patterns in data.
Learning Objective UNC-3.T: Determine parameters of a sampling distribution for a difference in sample means. [Skill 3.B]
UNC-3.T.1 For a numerical variable, when randomly sampling with replacement from two independent populations with population means $\mu_1$ and $\mu_2$ and population standard deviations $\sigma_1$ and $\sigma_2$, the sampling distribution of the difference in sample means $\bar{x}_1 - \bar{x}_2$ has mean $\mu_{(\bar{x}_1 - \bar{x}_2)} = \mu_1 - \mu_2$ and standard deviation, $\sigma_{(\bar{x}_1 - \bar{x}_2)} = \sqrt{\dfrac{\sigma_1^2}{n_1} + \dfrac{\sigma_2^2}{n_2}}$.
UNC-3.T.2 If sampling without replacement, the standard deviation of the difference in sample means is smaller than what is given by the formula above. If the sample sizes are less than 10% of the population sizes, the difference is negligible.
Learning Objective UNC-3.U: Determine whether a sampling distribution of a difference in sample means can be described as approximately normal. [Skill 3.C]
UNC-3.U.1 The sampling distribution of the difference in sample means $\bar{x}_1 - \bar{x}_2$ can be modeled with a normal distribution if the two population distributions can be modeled with a normal distribution.
UNC-3.U.2 The sampling distribution of the difference in sample means $\bar{x}_1 - \bar{x}_2$ can be modeled approximately by a normal distribution if the two population distributions cannot be modeled with a normal distribution but both sample sizes are greater than or equal to 30.
Learning Objective UNC-3.V: Interpret probabilities and parameters for a sampling distribution for a difference in sample means. [Skill 4.B]
UNC-3.V.1 Probabilities and parameters for a sampling distribution for a difference of sample means should be interpreted using appropriate units and within the context of a specific populations.
한국어
지속적 이해 (UNC-3): 확률적 추론을 통해 데이터의 패턴을 예측할 수 있습니다.
학습 목표 UNC-3.T: 표본 평균 차이의 표본 분포의 모수를 결정한다. [기술 3.B]
UNC-3.T.1 수치형 변수에 대해 모평균이 각각 $\mu_1$과 $\mu_2$이며 모표준편차가 각각 $\sigma_1$과 $\sigma_2$인 두 독립적인 모집단에서 교체抽样을 통해 무작위로 표본을 취할 때, 표본 평균 차이 $\bar{x}_1 - \bar{x}_2$의 표본 분포는 평균 $\mu_{(\bar{x}_1 - \bar{x}_2)} = \mu_1 - \mu_2$과 표준편차 $\sigma_{(\bar{x}_1 - \bar{x}_2)} = \sqrt{\dfrac{\sigma_1^2}{n_1} + \dfrac{\sigma_2^2}{n_2}}$을 가진다.
UNC-3.T.2 교체가 없는sampling을 할 경우, 표본 평균 차이의 표준편차는 위 공식으로 계산된 값보다 작다. 단, 각 표본 크기가 해당 모집단의 10% 미만일 경우 그 차이는 무시할 수 있다.
학습 목표 UNC-3.U: 표본 평균 차이의 표본 분포가 근사 정규분포로 기술될 수 있는지 판단한다. [기술 3.C]
UNC-3.U.1 두 모집단 분포가 정규분포로 모델링될 수 있는 경우, 표본 평균의 차이에 대한 표본분포 $\bar{x}_1 - \bar{x}_2$는 정규분포로 모델링할 수 있다.
UNC-3.U.2 두 모집단 분포가 정규분포로 모델링되지 않더라도 표본 크기가 모두 30 이상인 경우, 표본 평균의 차이에 대한 표본분포 $\bar{x}_1 - \bar{x}_2$는 대략적으로 정규분포로 모델링할 수 있다.
학습 목표 UNC-3.V: 표본 평균의 차이에 대한 표본분포에 대한 확률과 모수를 해석한다. [기술 4.B]
UNC-3.V.1 표본 평균의 차이에 대한 표본분포에 대한 확률과 모수는 적절한 단위와 특정 모집단의 맥락 내에서 해석되어야 한다.
Source: College Board AP Course and Exam Description · 출처: College Board AP Course and Exam Description
For $\bar{x}_1-\bar{x}_2$ from two independent samples: the mean is $\mu_1-\mu_2$, and (independent, so variances add)
Enduring Understanding (VAR-1): Given that variation may be random or not, conclusions are uncertain.
Learning Objective VAR-1.H: Identify questions suggested by variation in the shapes of distributions of samples taken from the same population. [Skill 1.A]
VAR-1.H.1 Variation in shapes of data distributions may be random or not.
한국어
지속적 이해 (VAR-1): 변동성이 우연일 수도 있고 그렇지 않을 수도 있으므로, 결론은 불확실할 수 있다.
학습 목표 VAR-1.H: 동일한 모집단에서 추출된 표본의 분포 형태에 나타나는 변동성이 시사하는 질문을 식별한다. [기술 1.A]
VAR-1.H.1 데이터 분포의 형태에 나타나는 변동성은 우연일 수도 있고 우연이 아닐 수도 있다.
Source: College Board AP Course and Exam Description · 출처: College Board AP Course and Exam Description
Because a sample proportion $\hat{p}$ is approximately normally distributed (when the conditions hold), we can measure how far a sample result is from a claimed value in standard errors, and turn that into a probability. This is what makes inference 推断 – drawing conclusions about a population from a sample – possible.
Enduring Understanding (UNC-4): An interval of values should be used to estimate parameters, in order to account for uncertainty.
Learning Objective UNC-4.A: Identify an appropriate confidence interval procedure for a population proportion. [Skill 1.D]
UNC-4.A.1 The appropriate confidence interval procedure for a one-sample proportion for one categorical variable is a one sample $z$-interval for a proportion.
Learning Objective UNC-4.B: Verify the conditions for calculating confidence intervals for a population proportion. [Skill 4.C]
UNC-4.B.1 In order to make assumptions necessary for inference on population proportions, means, and slopes, we must check for independence in data collection methods and for selection of the appropriate sampling distribution.
UNC-4.B.2 In order to calculate a confidence interval to estimate a population proportion, $p$, we must check for independence and that the sampling distribution is approximately normal.
a. To check for independence:
i. Data should be collected using a random sample or a randomized experiment.
ii. When sampling without replacement, check that $n \leq 10\%N$, where $N$ is the size of the population.
b. To check that the sampling distribution of $\hat{p}$ is approximately normal (shape):
i. For categorical variables, check that both the number of successes, $n\hat{p}$, and the number of failures, $n(1-\hat{p})$ are at least 10 so that the sample size is large enough to support an assumption of normality.
Learning Objective UNC-4.C: Determine the margin of error for a given sample size and an estimate for the sample size that will result in a given margin of error for a population proportion. [Skill 3.D]
UNC-4.C.1 Based on sample data, the standard error of a statistic is an estimate for the standard deviation for the statistic. The standard error of $\hat{p}$ is $SE_{\hat{p}} = \sqrt{\dfrac{\hat{p}(1-\hat{p})}{n}}$.
UNC-4.C.2 A margin of error gives how much a value of a sample statistic is likely to vary from the value of the corresponding population parameter.
UNC-4.C.3 For categorical variables, the margin of error is the critical value ($z^*$) times the standard error (SE) of the relevant statistic, which equals $z^* \sqrt{\dfrac{\hat{p}(1-\hat{p})}{n}}$ for a one sample proportion.
UNC-4.C.4 The formula for margin of error can be rearranged to solve for $n$, the minimum sample size needed to achieve a given margin of error. For this purpose, use a guess for $\hat{p}$ or use $\hat{p} = 0.5$ in order to find an upper bound for the sample size that will result in a given margin of error.
Learning Objective UNC-4.D: Calculate an appropriate confidence interval for a population proportion. [Skill 3.D]
UNC-4.D.1 In general, an interval estimate can be constructed as point estimate ± (margin of error). For a one-sample proportion, the interval estimate is $\hat{p} \pm z^* \sqrt{\dfrac{\hat{p}(1-\hat{p})}{n}}$.
Clarifying statement: Formulas for interval estimates do not appear explicitly on the AP Statistics Formula Sheet provided with the AP Statistics Exam. However, these formulas do not need to be memorized, as they can be constructed based on the general test statistic formula and the relevant standard error formulas that are provided on the formula sheet.
UNC-4.D.2 Critical values represent the boundaries encompassing the middle C% of the standard normal distribution, where C% is an approximate confidence level for a proportion.
Learning Objective UNC-4.E: Calculate an interval estimate based on a confidence interval for a population proportion. [Skill 3.D]
UNC-4.E.1 Confidence intervals for population proportions can be used to calculate interval estimates with specified units.
한국어
지속적 이해 (UNC-4): 불확실성을 고려하기 위해 모수를 추정하기 위해 값의 구간을 사용해야 한다.
학습 목표 UNC-4.A: 모집단 비율에 대한 적절한 신뢰구간 절차를 식별한다. [기술 1.D]
UNC-4.A.1 단일 범주형 변수에 대한 단일 표본 비율에 대한 적절한 신뢰구간 절차는 비율에 대한 단일 표본 $z$-구간이다.
학습 목표 UNC-4.B: 모집단 비율에 대한 신뢰구간을 계산하기 위한 조건을 확인한다. [기술 4.C]
UNC-4.B.1 모집단의 비율, 평균 및 기울기에 대한 추론을 위해 필요한 가정의 타당성을 검토하기 위해서는 데이터 수집 방법에서의 독립성 확인과 적절한 표본 분포의 선택 여부를 점검해야 합니다.
UNC-4.B.2 모집단 비율 $p$를 추정하기 위한 신뢰구間을 계산하기 위해서는 독립성과 표본 분포가 근사적으로 정규분포임을 확인해야 합니다.
a. 독립성 확인:
i. 데이터는 무작위 표본 또는 무작위 배정 실험을 통해 수집되어야 합니다.
ii. 재보환 sampling(재복구抽样) 없이 샘플링할 때, $n \leq 10\%N$인지 확인해야 하며, 여기서 $N$은 모집단의 크기를 의미합니다.
b. $\hat{p}$의 표본분포가 대략적으로 정규분포임을 확인하기 위해 (모양):
i. 범주형 변수에 대해서는 성공 횟수 $n\hat{p}$와 실패 횟수 $n(1-\hat{p})$이 모두 10 이상이어야 하며, 이는 표본 크기가 정규성 가정을 지지하기에 충분함을 보장하기 위함입니다.
학습 목표 UNC-4.C: 주어진 표본 크기에 대한 오차 한계와 주어진 오차 한계를 달성하기 위한 표본 크기의 추정치를 결정하기. [기술 3.D]
UNC-4.C.1 표본 데이터를 기반으로 통계량의 표준오차는 해당 통계량의 표준편차에 대한 추정치입니다. 비율 $\hat{p}$의 표준오차는 $SE_{\hat{p}} = \sqrt{\dfrac{\hat{p}(1-\hat{p})}{n}}$입니다.
UNC-4.C.2 오차 한계는 표본 통계량의 값이 대응되는 모집단 매개변수의 값에서 얼마나 변동할 수 있는지를 나타냅니다.
UNC-4.C.3 범주형 변수에 대해 오차 한계는 임계값($z^*$)에 해당 통계량의 표준오차(SE)를 곱한 값으로, 일-sample 비율에서는 이 값이 $z^* \sqrt{\dfrac{\hat{p}(1-\hat{p})}{n}}$에 해당합니다.
UNC-4.C.4 오차 한계의 공식을 변형하여 주어진 오차 한계를 달성하기 위해 필요한 최소 표본 크기 $n$를 구할 수 있습니다. 이를 위해 $\hat{p}$에 대한 추측값을 사용하거나, 상한값을 구하기 위해 $\hat{p} = 0.5$을 사용하여 주어진 오차 한계를 Achieve하는 표본 크기의 상한값을 찾아야 합니다.
학습 목표 UNC-4.D: 모집단 비율에 대한 적절한 신뢰구间을 계산하기. [기술 3.D]
UNC-4.D.1 일반적으로 구간 추정은 점추정 ± (오차 한계)로 구성할 수 있습니다. 일-sample 비율의 경우 구간 추정은 $\hat{p} \pm z^* \sqrt{\dfrac{\hat{p}(1-\hat{p})}{n}}$입니다.
*해설:*区间 추정 공식은 AP 통계 Exam에 제공되는 공식표에 명시되어 있지 않습니다. 그러나 공식표에 제시된 일반 검정통계량 공식과 관련 표준오차 공식을 기반으로 공식들을 구성할 수 있으므로NONE, 이 공식들은 암기할 필요가 없습니다.
UNC-4.D.2 임계값은 표준정규분포의 중앙 C%를 포함하는 경계선을 나타내며, 여기서 C%는 비율에 대한 근사적인 신뢰수준입니다.
학습 목표 UNC-4.E: 모집단 비율에 대한 신뢰구간을 기반으로 구간추정치를 계산하기. [기술 3.D]
UNC-4.E.1 모집단 비율의 신뢰구간은 특정 단위의 구간추정치를 계산하는 데 사용할 수 있습니다.
Source: College Board AP Course and Exam Description · 출처: College Board AP Course and Exam Description
What a confidence interval means
A confidence interval 置信区间 estimates the parameter as a range: statistic $\pm$margin of error 误差幅度.
$z^{*}$ is the critical value for the confidence level 置信水平 (e.g. $1.96$ for 95%). Conditions: random sample, Large Counts ($n\hat p\ge 10$ and $n(1-\hat p)\ge 10$), and the 10% condition. Interpret it: "We are 95% confident the true proportion of... is between... and...". Interpret the level: "In 95% of samples, this method produces an interval that captures the true proportion."
Over many samples, about 95% of 95% confidence intervals capture the true proportion
Worked example. In a random sample of $200$ people, $120$ support a policy, so $\hat{p}=0.60$. A $95\%$ interval uses $z^*=1.96$:
We are $95\%$ confident the true proportion of supporters is between $53.2\%$ and $66.8\%$.
A 95% confidence interval reaches 1.96 standard errors each side of the estimate
Choosing the sample size. To keep the margin of error no larger than a target $m$, set $z^{*}\sqrt{\dfrac{\hat p(1-\hat p)}{n}}\le m$ and solve for $n$. When you have no estimate of $\hat p$, use $\hat p=0.5$: it makes $\hat p(1-\hat p)$ as large as possible, giving the safe (largest) required sample size. Always round the result up to the next whole person.
Worked example. How many people must you survey for a $95\%$ interval with margin of error at most $0.03$? Using $\hat p=0.5$ and $z^*=1.96$:
UNC-4
An interval of values should be used to estimate parameters, in order to account for uncertainty.
UNC-4.F
Interpret a confidence interval for a population proportion. [Skill 4.B]
UNC-4.F.1 A confidence interval for a population proportion either contains the population proportion or it does not, because each interval is based on random sample data, which varies from sample to sample.
UNC-4.F.2 We are C% confident that the confidence interval for a population proportion captures the population proportion.
UNC-4.F.3 In repeated random sampling with the same sample size, approximately C% of confidence intervals created will capture the population proportion.
UNC-4.F.4 Interpreting a confidence interval for a one-sample proportion should include a reference to the sample taken and details about the population it represents.
Illustrative examples for UNC-4.F.4: For interpreting a 99% confidence interval of (0.268, 0.292), based on the proportion of a nationally representative sample of twelfth-grade students who answered a particular multiple choice question correctly: "We are 99 percent confident that the interval from 0.268 to 0.292 contains the population proportion of all United States twelfth-grade students who would answer this question correctly" (2011 FRQ 6(a)).
UNC-4.G
Justify a claim based on a confidence interval for a population proportion. [Skill 4.D]
UNC-4.G.1 A confidence interval for a population proportion provides an interval of values that may provide sufficient evidence to support a particular claim in context.
UNC-4.H
Identify the relationships between sample size, width of a confidence interval, confidence level, and margin of error for a population proportion. [Skill 4.A]
UNC-4.H.1 When all other things remain the same, the width of the confidence interval for a population proportion tends to decrease as the sample size increases. For a population proportion, the width of the interval is proportional to $\dfrac{1}{\sqrt{n}}$.
UNC-4.H.2 For a given sample, the width of the confidence interval for a population proportion increases as the confidence level increases.
UNC-4.H.3 The width of a confidence interval for a population proportion is exactly twice the margin of error.
Source: College Board AP Course and Exam Description · 출처: College Board AP Course and Exam Description
To judge a claimed value: if it lies inside the interval, the data are consistent with it; if it lies outside, the data give evidence against it. Base the conclusion on whether the plausible values include the claim, in context.
6.4
Setting Up a Test for a Proportion
Syllabus
English
Enduring Understanding (VAR-6): The normal distribution may be used to model variation.
Learning Objective VAR-6.D: Identify the null and alternative hypotheses for a population proportion. [Skill 1.F]
VAR-6.D.1 The null hypothesis is the situation that is assumed to be correct unless evidence suggests otherwise, and the alternative hypothesis is the situation for which evidence is being collected.
VAR-6.D.2 For hypotheses about parameters, the null hypothesis contains an equality reference (=, ≥, or ≤), while the alternative hypothesis contains a strict inequality (<, >, or ≠). The type of inequality in the alternative hypothesis is based on the question of interest. Alternative hypotheses with < or > are called one-sided, and alternative hypotheses with ≠ are called two-sided. Although the null hypothesis for a one-sided test may include an inequality symbol, it is still tested at the boundary of equality.
VAR-6.D.3 The null hypothesis for a population proportion is: $H_0 : p = p_0$, where $p_0$ is the null hypothesized value for the population proportion.
VAR-6.D.4 A one-sided alternative hypothesis for a proportion is either $H_a : p < p_0$ or $H_a : p > p_0$. A two-sided alternate hypothesis is $H_a : p_1 \neq p_2$.
VAR-6.D.5 For a one-sample $z$-test for a population proportion, the null hypothesis specifies a value for the population proportion, usually one indicating no difference or effect.
Learning Objective VAR-6.E: Identify an appropriate testing method for a population proportion. [Skill 1.E]
VAR-6.E.1 For a single categorical variable, the appropriate testing method for a population proportion is a one-sample $z$-test for a population proportion.
Learning Objective VAR-6.F: Verify the conditions for making statistical inferences when testing a population proportion. [Skill 4.C]
VAR-6.F.1 In order to make statistical inferences when testing a population proportion, we must check for independence and that the sampling distribution is approximately normal:
a. To check for independence:
i. Data should be collected using a random sample or a randomized experiment.
ii. When sampling without replacement, check that $n \leq 10\%N$.
b. To check that the sampling distribution of $\hat{p}$ is approximately normal (shape):
i. Assuming that $H_0$ is true $(p = p_0)$, verify that both the number of successes, $np_0$, and the number of failures, $n(1-p_0)$ are at least 10 so that that the sample size is large enough to support an assumption of normality.
한국어
지속적 이해 (VAR-6): 정규분포를 변동성을 모델링하는 데 사용할 수 있습니다.
학습 목표 VAR-6.D: 모집단 비율에 대한 영가설 및 대안가설을 식별하기. [기술 1.F]
VAR-6.D.1 영가설은 증거가 반대로 나타날 때까지 참이라고 가정되는 상황이며, 대안가설은 증거를 수집하려는 상황입니다.
VAR-6.D.2 모수에 대한 가설에서 영가설은 등호 기준(=, ≥, 또는 ≤)을 포함하고, 대안가설은 엄격한 부등호(<, >, 또는 ≠)를 포함합니다. 대안가설의 부등호 유형은 관심 있는 질문에 따라 결정됩니다. < or >를 포함하는 대안가설은 한쪽 단변 검정(H), ≠를 포함하는 대안가설은 양측 검정(H)이라고 합니다. 한쪽 단변 검정의 영가설에는 부등호 기호가 포함되어 있을 수 있으나, 여전히 등호 경계에서 검정합니다.
VAR-6.D.3 모비율에 대한 영가설은: $H_0 : p = p_0$이며, 여기서 $p_0$는 모비율에 대한 영가설값입니다.
VAR-6.D.4 비율에 대한 한쪽 단변 대안가설은 either $H_a : p < p_0$ or $H_a : p > p_0$입니다. 양측 대안가설은 $H_a : p_1 \neq p_2$입니다.
VAR-6.D.5 모비율에 대한 일표본 $z$-검정에서는 영가설이 모비율에 대한 값을 명시하며, 보통 차이나 효과가 없음을 나타내는 값으로 설정합니다.
학습목표 VAR-6.E: 모비율에 적합한 검정 방법을 식별한다. [기술 1.E]
VAR-6.E.1 단일 범주 변수에 대해 모비율에 적합한 검정 방법은 모비율에 대한 일표본 $z$-검정입니다.
학습목표 VAR-6.F: 모비율을 검정할 때 통계적 추론을 위해 필요한 조건을 확인한다. [기술 4.C]
VAR-6.F.1 모비율을 검정하여 통계적 추론을 하기 위해서는 독립성 및 표본 분포가 근사적으로 정규분포임을 확인해야 합니다:
a. 독립성 확인:
i. 데이터는 무작위 표본 또는 무작위 배정 실험을 통해 수집되어야 합니다.
ii. 무반복 표본 추출 시, $n \leq 10\%N$인지 확인합니다.
b. $\hat{p}$의 표본분포가 대략적으로 정규분포임을 확인하기 위해 (모양):
i. $H_0$가 참이라는 가정 하에 $(p = p_0)$, 성공 횟수 $np_0$와 실패 횟수 $n(1-p_0)$가 모두 적어도 10 이상인지 확인하여 표본 크기가 정규성을 가정하기에 충분함을 검증하십시오.
Source: College Board AP Course and Exam Description · 출처: College Board AP Course and Exam Description
A significance test 显著性检验 weighs evidence against a claim. State a null hypothesis 原假设$H_0$ and an alternative hypothesis 备择假设$H_a$ about the parameter $p$:
Check the same conditions (random, Large Counts using $p_0$, 10%). The test statistic 检验统计量 counts standard errors from $p_0$:
$$z=\frac{\hat p-p_0}{\sqrt{p_0(1-p_0)/n}}.$$
Worked example. A company claims $90\%$ satisfaction ($p_0=0.90$); a sample of $100$ finds $84$ satisfied ($\hat{p}=0.84$). Test $H_0:p=0.90$ vs $H_a:p\neq0.90$ at $\alpha=0.05$:
giving a two-tailed $p$-value of about $2(0.023)=0.046$. Since $0.046<0.05$, reject $H_0$ – there is evidence the true satisfaction rate differs from (is below) $90\%$.
A two-tailed 5% test rejects the null hypothesis in the shaded tails
VAR-6
The normal distribution may be used to model variation.
VAR-6.G
Calculate an appropriate test statistic and $p$-value for a population proportion. [Skill 3.E]
VAR-6.G.1 The distribution of the test statistic assuming the null hypothesis is true (null distribution) can be either a randomization distribution or when a probability model is assumed to be true, a theoretical distribution ($z$).
VAR-6.G.2 When using a $z$-test, the standardized test statistic can be written: $\text{test statistic} = \dfrac{\text{sample statistic} - \text{null value of the parameter}}{\text{standard deviation of the statistic}}$. This is called a $z$-statistic for proportions.
VAR-6.G.3 The test statistic for a population proportion is: $z = \dfrac{\hat{p} - p_0}{\sqrt{\dfrac{p_0(1-p_0)}{n}}}$.
Clarifying statement: The formulas for test statistics do not appear explicitly on the AP Statistics Formula Sheet provided with the AP Statistics Exam. However, these formulas do not need to be memorized, as they can be constructed based on the general test statistic formula and the relevant standard error formulas that are provided on the formula sheet.
VAR-6.G.4 A $p$-value is the probability of obtaining a test statistic as extreme or more extreme than the observed test statistic when the null hypothesis and probability model are assumed to be true. The significance level may be given or determined by the researcher.
DAT-3
Significance testing allows us to make decisions about hypotheses within a particular context.
DAT-3.A
Interpret the $p$-value of a significance test for a population proportion. [Skill 4.B]
DAT-3.A.1 The $p$-value is the proportion of values for the null distribution that are as extreme or more extreme than the observed value of the test statistic. This is:
a. The proportion at or above the observed value of the test statistic, if the alternative is >.
b. The proportion at or below the observed value of the test statistic, if the alternative is <.
c. The proportion less than or equal to the negative of the absolute value of the test statistic plus the proportion greater than or equal to the absolute value of the test statistic, if the alternative is ≠.
DAT-3.A.2 An interpretation of the $p$-value of a significance test for a one-sample proportion should recognize that the $p$-value is computed by assuming that the probability model and null hypothesis are true, i.e., by assuming that the true population proportion is equal to the particular value stated in the null hypothesis.
Source: College Board AP Course and Exam Description · 출처: College Board AP Course and Exam Description
What a p-value means
The $p$-value P值 is the probability of getting a sample result as extreme or more extreme than the observed one, assuming $H_0$ is true. A small $p$-value means the data would be surprising if $H_0$ held – evidence against $H_0$. It is not the probability that $H_0$ is true.
Explore · 탐색하기
A p-value as a tail area · 꼬리 면적으로 해석하는 p-value
A p-value is the probability, if the null hypothesis were true, of a result at least this extreme — the shaded tail area. Small p-values cast doubt on the null. · p-값은 귀무가설이 참일 경우, 이보다 더 극단적인 결과가 나올 확률입니다. 이는 그림자 칠해진 꼬리 면적에 해당하며, 작은 p-값은 귀무가설을 의심하게 만듭니다.
Enduring Understanding (DAT-3): Significance testing allows us to make decisions about hypotheses within a particular context.
Learning Objective DAT-3.B: Justify a claim about the population based on the results of a significance test for a population proportion. [Skill 4.E]
DAT-3.B.1 The significance level, $\alpha$, is the predetermined probability of rejecting the null hypothesis given that it is true.
DAT-3.B.2 A formal decision explicitly compares the $p$-value to the significance level, $\alpha$. If the $p$-value $\leq \alpha$, reject the null hypothesis. If the $p$-value $> \alpha$, fail to reject the null hypothesis.
DAT-3.B.3 Rejecting the null hypothesis means there is sufficient statistical evidence to support the alternative hypothesis. Failing to reject the null means there is insufficient statistical evidence to support the alternative hypothesis.
DAT-3.B.4 The conclusion about the alternative hypothesis must be stated in context.
DAT-3.B.5 A significance test can lead to rejecting or not rejecting the null hypothesis, but can never lead to concluding or proving that the null hypothesis is true. Lack of statistical evidence for the alternative hypothesis is not the same as evidence for the null hypothesis.
DAT-3.B.6 Small $p$-values indicate that the observed value of the test statistic would be unusual if the null hypothesis and probability model were true, and so provide evidence for the alternative. The lower the $p$-value, the more convincing the statistical evidence for the alternative hypothesis.
DAT-3.B.7$p$-values that are not small indicate that the observed value of the test statistic would not be unusual if the null hypothesis and probability model were true, so do not provide convincing statistical evidence for the alternative hypothesis nor do they provide evidence that the null hypothesis is true.
DAT-3.B.8 A formal decision explicitly compares the $p$-value to the significance $\alpha$. If the $p$-value $\leq \alpha$, then reject the null hypothesis, $H_0 : p = p_0$. If the $p$-value $> \alpha$, then fail to reject the null hypothesis.
DAT-3.B.9 The results of a significance test for a population proportion can serve as the statistical reasoning to support the answer to a research question about the population that was sampled.
한국어
지속적 이해 (DAT-3): 유의성 검정은 특정 맥락 내에서의 가설에 대한 의사결정을 가능하게 한다.
학습목표 DAT-3.B: 모비율에 대한 유의검정 결과를 바탕으로 모에 대한 주장을 정당화한다. [기술 4.E]
DAT-3.B.1 유의수준 $\alpha$는 영가설이 참일 때 이를 기각할 사전에 정해진 확률입니다.
UNC-5
Probabilities of Type I and Type II errors influence inference.
UNC-5.A
Identify Type I and Type II errors. [Skill 1.B]
UNC-5.A.1 A Type I error occurs when the null hypothesis is true and is rejected (false positive).
UNC-5.A.2 A Type II error occurs when the null hypothesis is false and is not rejected (false negative).
Table of Errors: With Actual Population Value across the top ($H_0$ true; $H_a$ true) and Decision down the side (Reject $H_0$; Fail to Reject $H_0$): Reject $H_0$ when $H_0$ true = Type I Error; Reject $H_0$ when $H_a$ true = Correct Decision; Fail to Reject $H_0$ when $H_0$ true = Correct Decision; Fail to Reject $H_0$ when $H_a$ true = Type II Error.
UNC-5.B
Calculate the probability of a Type I and Type II errors. [Skill 3.A]
UNC-5.B.1 The significance level, $\alpha$, is the probability of making a Type I error, if the null hypothesis is true.
UNC-5.B.2 The power of a test is the probability that a test will correctly reject a false null hypothesis.
UNC-5.B.3 The probability of making a Type II error $= 1 - power$.
UNC-5.C
Identify factors that affect the probability of errors in significance testing. [Skill 4.A]
UNC-5.C.1 The probability of a Type II error decreases when any of the following occurs, provided the others do not change:
i. Sample size(s) increases.
ii. Significance level ($\alpha$) of a test increases.
iii. Standard error decreases.
iv. True parameter value is farther from the null.
UNC-5.D
Interpret Type I and Type II errors. [Skill 4.B]
UNC-5.D.1 Whether a Type I or a Type II error is more consequential depends upon the situation.
UNC-5.D.2 Since the significance level, $\alpha$, is the probability of a Type I error, the consequences of a Type I error influence decisions about a significance level.
Source: College Board AP Course and Exam Description · 출처: College Board AP Course and Exam Description
Type I and Type II errors
A Type I error 第一类错误: rejecting a true$H_0$ (a false alarm). Its probability is $\alpha$.
A Type II error 第二类错误: failing to reject a false$H_0$ (a missed detection). Its probability is $\beta$.
The power 检验效能$=1-\beta$ is the chance of correctly detecting a real effect. Power rises with a larger sample, a larger effect, or a larger $\alpha$.
Describe each error and its consequence in the problem's context.
Explore · 탐색하기
Two ways a test can be wrong · 검정이 틀릴 수 있는 두 가지 경우
A Type I error rejects a true null (false alarm); a Type II error keeps a false null (a miss). Lowering one usually raises the other. · Type I 오류는 참인 귀무가설을 기각하는 것(거짓 경보)이며, Type II 오류는 거짓인 귀무가설을 유지하는 것입니다(미스). 하나를 낮추면 보통 다른 하나는 높아집니다.
Confidence Interval for a Difference of Proportions
Syllabus
English
Enduring Understanding (UNC-4): An interval of values should be used to estimate parameters, in order to account for uncertainty.
Learning Objective UNC-4.I: Identify an appropriate confidence interval procedure for a comparison of population proportions. [Skill 1.D]
UNC-4.I.1 The appropriate confidence interval procedure for a two-sample comparison of proportions for one categorical variable is a two-sample $z$-interval for a difference between population proportions.
Learning Objective UNC-4.J: Verify the conditions for calculating confidence intervals for a difference between population proportions. [Skill 4.C]
UNC-4.J.1 In order to calculate confidence intervals to estimate a difference between proportions, we must check for independence and that the sampling distribution is approximately normal:
a. To check for independence:
i. Data should be collected using two independent, random samples or a randomized experiment.
ii. When sampling without replacement, check that $n_1 \leq 10\%N_1$ and $n_2 \leq 10\%N_2$.
b. To check that sampling distribution of $\hat{p}_1 - \hat{p}_2$ is approximately normal (shape).
i. For categorical variables, check that $n_1\hat{p}_1$, $n_1(1-\hat{p}_1)$, $n_2\hat{p}_2$, and $n_2\left(1-\hat{p}_2\right)$ are all greater than or equal to some predetermined value, typically either 5 or 10.
Learning Objective UNC-4.K: Calculate an appropriate confidence interval for a comparison of population proportions. [Skill 3.D]
UNC-4.K.1 For a comparison of proportions, the interval estimate is $(\hat{p}_1 - \hat{p}_2) \pm z^* \sqrt{\dfrac{\hat{p}_1(1-\hat{p}_1)}{n_1} + \dfrac{\hat{p}_2(1-\hat{p}_2)}{n_2}}$.
Clarifying statement: Formulas for interval estimates do not appear explicitly on the AP Statistics Formula Sheet provided with the AP Statistics Exam. However, these formulas do not need to be memorized, as they can be constructed based on the general test statistic formula and the relevant standard error formulas that are provided on the formula sheet.
Learning Objective UNC-4.L: Calculate an interval estimate based on a confidence interval for a difference of proportions. [Skill 3.D]
UNC-4.L.1 Confidence intervals for a difference in proportions can be used to calculate interval estimates with specified units.
한국어
지속적 이해 (UNC-4): 불확실성을 고려하기 위해 모수를 추정하기 위해 값의 구간을 사용해야 한다.
학습목표 UNC-4.I: 모의 비율 비교에 적절한 신뢰구간 절차를 식별함. [기술 1.D]
UNC-4.I.1 한 categorical 변수에 대한 두 표본 비율 비교에 적절한 신뢰구간 절차는 모의 비율 차이(차이)에 대한 두 표본 $z$-신뢰구간입니다.
학습목표 UNC-4.J: 모의 비율 차이에 대한 신뢰구간 계산 시 확인해야 할 조건을 검증함. [기술 4.C]
UNC-4.J.1 비율 차이를 추정하기 위한 신뢰구간을 계산하려면 독립성을 확인하고 표본 분포가 근사적으로 정규분포를 따르는지 확인해야 합니다:
a. 독립성 확인:
i. 두 개의 독립적인 무작위 표본이나 무작위 배정 실험을 사용하여 데이터를 수집해야 한다.
ii. 교차추출 시, $n_1 \leq 10\%N_1$이고 $n_2 \leq 10\%N_2$인지 확인한다.
Conditions must hold in both samples, and the samples must be independent.
6.9
Justifying a Claim About Two Proportions
Syllabus
English
Enduring Understanding (UNC-4): An interval of values should be used to estimate parameters, in order to account for uncertainty.
Learning Objective UNC-4.M: Interpret a confidence interval for a difference of proportions. [Skill 4.B]
UNC-4.M.1 In repeated random sampling with the same sample size, approximately C% of confidence intervals created will capture the difference in population proportions.
UNC-4.M.2 Interpreting a confidence interval for difference between population proportions should include a reference to the sample taken and details about the population it represents.
Learning Objective UNC-4.N: Justify a claim based on a confidence interval for a difference of proportions. [Skill 4.D]
UNC-4.N.1 A confidence interval for difference in population proportions provides an interval of values that may provide sufficient evidence to support a particular claim in context.
한국어
지속적 이해 (UNC-4): 불확실성을 고려하기 위해 모수를 추정하기 위해 값의 구간을 사용해야 한다.
학습목표 UNC-4.M: 비율 차이에 대한 신뢰구간을 해석함. [기술 4.B]
UNC-4.M.1 동일한 표본 크기로 반복 무작위 표본을 취할 때, 생성된 신뢰구간의 약 C%가 모의 비율 차이를 포함할 것입니다.
UNC-4.M.2 모의 비율 차이에 대한 신뢰구간을 해석할 때는 표본 채취 과정과 그것이 대표하는 모에 대한 세부 사항을 언급해야 합니다.
학습목표 UNC-4.N: 비율 차이에 대한 신뢰구간에 근거하여 주장을 정당화함. [기술 4.D]
UNC-4.N.1 모의 비율 차이에 대한 신뢰구간은 특정 문맥에서의 particular 주장을 지지할 충분한 증거를 제공할 수 있는 값들의 구간을 제공합니다.
Source: College Board AP Course and Exam Description · 출처: College Board AP Course and Exam Description
If the interval for $p_1-p_2$ contains $0$, the data are consistent with no difference; if it lies entirely above or below $0$, there is evidence of a difference (in that direction). State the direction and context.
6.10
Setting Up a Test for a Difference
Syllabus
English
Enduring Understanding (VAR-6): The normal distribution may be used to model variation.
Learning Objective VAR-6.H: Identify the null and alternative hypotheses for a difference of two population proportions. [Skill 1.F]
VAR-6.H.1 For a two-sample test for a difference of two proportions, the null hypothesis specifies a value of $0$ for the difference in population proportions, indicating no difference or effect.
VAR-6.H.2 The null hypothesis for a difference in proportions is: $H_0 : p_1 = p_2$, or $H_0 : p_1 - p_2 = 0$.
VAR-6.H.3 A one-sided alternative hypothesis for a difference in proportions is $H_a : p_1 < p_2$, or, $H_a : p_1 > p_2$. A two-sided alternative hypothesis for a difference of proportions is $H_a : p_1 \neq p_2$.
Learning Objective VAR-6.I: Identify an appropriate testing method for the difference of two population proportions. [Skill 1.E]
VAR-6.I.1 For a single categorical variable, the appropriate testing method for the difference of two population proportions is a two-sample $z$-test for a difference between two population proportions.
Learning Objective VAR-6.J: Verify the conditions for making statistical inferences when testing a difference of two population proportions. [Skill 4.C]
VAR-6.J.1 In order to make statistical inferences when testing a difference between population proportions, we must check for independence and that the sampling distribution is approximately normal:
a. To check for independence:
i. Data should be collected using two independent, random samples or a randomized experiment.
ii. When sampling without replacement, check that $n_1 \leq 10\%N_1$ and $n_2 \leq 10\%N_2$.
b. To check that the sampling distribution of $\hat{p}_1 - \hat{p}_2$ is approximately normal (shape):
i. For the combined sample, define the combined (or pooled) proportion, $\hat{p}_c = \dfrac{n_1\hat{p}_1 + n_2\hat{p}_2}{n_1 + n_2}$. Assuming that $H_0$ is true $(p_1 - p_2 = 0$ or $p_1 = p_2)$, check that $n_1\hat{p}_c$, $n_1\left(1-\hat{p}_c\right)$, $n_2\hat{p}_c$, and $n_2\left(1-\hat{p}_c\right)$ are all greater than or equal to some predetermined value, typically either 5 or 10.
한국어
지속적 이해 (VAR-6): 정규분포를 변동성을 모델링하는 데 사용할 수 있습니다.
학습 목표 VAR-6.H: 두 모집단 비율의 차이에 대한 영가설과 대안가설을 식별한다. [기술 1.F]
VAR-6.H.1 두 비율의 차이에 대한 두 표본 검정에서 영가설은 모비율의 차이가 $0$인 값을 명시하며, 이는 차이나 효과가 없음을 의미한다.
VAR-6.H.2 비율의 차이에 대한 영가설은: $H_0 : p_1 = p_2$ 또는 $H_0 : p_1 - p_2 = 0$이다.
VAR-6.H.3 비율의 차이에 대한 일측면 대안가설은 $H_a : p_1 < p_2$ 또는 $H_a : p_1 > p_2$이다. 비율의 차이에 대한 양측면 대안가설은 $H_a : p_1 \neq p_2$이다.
학습 목표 VAR-6.I: 두 모집단 비율의 차이에 대한 적절한 검정 방법을 식별한다. [기술 1.E]
VAR-6.I.1 단일 범주형 변수에 대해 두 모집단 비율의 차이에 대한 적절한 검정 방법은 두 모집단 비율의 차이에 대한 두 표본 $z$-검정이다.
학습 목표 VAR-6.J: 두 모집단 비율의 차이를 검정할 때 통계적 추론을 수행하기 위한 조건을 확인한다. [기술 4.C]
i. 두 개의 독립적인 무작위 표본이나 무작위 배정 실험을 사용하여 데이터를 수집해야 한다.
ii. 교차추출 시, $n_1 \leq 10\%N_1$이고 $n_2 \leq 10\%N_2$인지 확인한다.
b. $\hat{p}_1 - \hat{p}_2$의 표본분포가 대략적으로 정규분포임을 확인하기 위해 (모양):
i. 결합 표본에 대해 결합(혼합) 비율 $\hat{p}_c = \dfrac{n_1\hat{p}_1 + n_2\hat{p}_2}{n_1 + n_2}$를 정의한다. $H_0$이 참이라고 가정할 때 $(p_1 - p_2 = 0$ 또는 $p_1 = p_2)$이며, $n_1\hat{p}_c$, $n_1\left(1-\hat{p}_c\right)$, $n_2\hat{p}_c$, $n_2\left(1-\hat{p}_c\right)$가 모두 사전에 결정된 값(일반적으로 5 또는 10) 이상인지 확인한다.
Source: College Board AP Course and Exam Description · 출처: College Board AP Course and Exam Description
Hypotheses compare the two proportions: $H_0: p_1=p_2$ versus $H_a: p_1\neq p_2$ (or $<,>$). Because $H_0$ says the proportions are equal, use a combined (pooled) 合并 sample proportion $\hat p_c=\dfrac{\text{total successes}}{\text{total sample size}}$ to estimate the common $p$.
Enduring Understanding (VAR-6): The normal distribution may be used to model variation.
Learning Objective VAR-6.K: Calculate an appropriate test statistic for the difference of two population proportions. [Skill 3.E]
VAR-6.K.1 The test statistic for a difference in proportions is: $z = \dfrac{(\hat{p}_1 - \hat{p}_2) - 0}{\sqrt{\hat{p}_c(1-\hat{p}_c)}\sqrt{\dfrac{1}{n_1} + \dfrac{1}{n_2}}}$, where $\hat{p}_c = \dfrac{n_1\hat{p}_1 + n_2\hat{p}_2}{n_1 + n_2}$.
Clarifying statement: The formulas for test statistics do not appear explicitly on the AP Statistics Formula Sheet provided with the AP Statistics Exam. However, these formulas do not need to be memorized, as they can be constructed based on the general test statistic formula and the standard error formulas for each of the relevant test statistics that are provided on the formula sheet.
Enduring Understanding (DAT-3): Significance testing allows us to make decisions about hypotheses within a particular context.
Learning Objective DAT-3.C: Interpret the $p$-value of a significance test for a difference of population proportions. [Skill 4.B]
DAT-3.C.1 An interpretation of the $p$-value of a significance test for a difference of two population proportions should recognize that the $p$-value is computed by assuming that the null hypothesis is true, i.e., by assuming that the true population proportions are equal to each other.
Learning Objective DAT-3.D: Justify a claim about the population based on the results of a significance test for a difference of population proportions. [Skill 4.E]
DAT-3.D.1 A formal decision explicitly compares the $p$-value to the significance $\alpha$. If the $p\text{-value} \leq \alpha$, then reject the null hypothesis, $H_0 : p_1 = p_2$, or $H_0 : p_1 - p_2 = 0$. If the $p$-value $> \alpha$, then fail to reject the null hypothesis.
DAT-3.D.2 The results of a significance test for a difference of two population proportions can serve as the statistical reasoning to support the answer to a research question about the two populations that were sampled.
한국어
지속적 이해 (VAR-6): 정규분포를 변동성을 모델링하는 데 사용할 수 있습니다.
학습 목표 VAR-6.K: 두 모집단 비율의 차이에 대한 적절한 검정 통계를 계산한다. [기술 3.E]
보충 설명: 검정 통계식에 대한 공식은 AP 통계학 시험에 제공되는 AP 통계학 공식표에 명시되어 있지 않다. 그러나 이 공식들은 기억할 필요가 없다. 공식표에 제시된 각 관련 검정 통계식에 대한 표준오차 공식과 일반적인 검정 통계식 공식을 기반으로 이러한 공식들을 구성할 수 있기 때문이다.
지속적 이해 (DAT-3): 유의성 검정은 특정 맥락 내에서의 가설에 대한 의사결정을 가능하게 한다.
학습 목표 DAT-3.C: 모집단 비율의 차이에 대한 유의성 검정의 $p$-값을 해석한다. [기술 4.B]
DAT-3.C.1 두 모집단 비율의 차이에 대한 유의성 검정의 $p$-값을 해석할 때는, 영가설이 참이라고 가정하여 즉, 실제 모비율이 서로 같다고 가정하여 계산된 $p$-값임을 인지해야 한다.
학습 목표 DAT-3.D: 모집단 비율의 차이에 대한 유의성 검정 결과를 바탕으로 모집단에 대한 주장을 타당화한다. [기술 4.E]
Enduring Understanding (VAR-1): Given that variation may be random or not, conclusions are uncertain.
Learning Objective VAR-1.I: Identify questions suggested by probabilities of errors in statistical inference. [Skill 1.A]
VAR-1.I.1 Random variation may result in errors in statistical inference.
한국어
지속적 이해 (VAR-1): 변동성이 우연일 수도 있고 그렇지 않을 수도 있으므로, 결론은 불확실할 수 있다.
학습 목표 VAR-1.I: 통계적 추론의 오차 확률에 의해 제시되는 문제를 식별한다. [스킬 1.A]
VAR-1.I.1 무작위 변이는 통계적 추론에서 오류를 초래할 수 있다.
Source: College Board AP Course and Exam Description · 출처: College Board AP Course and Exam Description
Type I and Type II errors
Inference for a mean works like inference for a proportion, with one change: we rarely know the population standard deviation $\sigma$, so we estimate it with the sample $s$. That extra uncertainty means we use the $t$-distribution instead of the normal – a distribution 分布 that is bell-shaped but with heavier tails, and it depends on the degrees of freedom 自由度$df=n-1$; as $n$ grows it approaches the normal.
VAR-7
The $t$-distribution may be used to model variation.
VAR-7.A
Describe $t$-distributions. [Skill 3.C]
VAR-7.A.1 When $s$ is used instead of $\sigma$ to calculate a test statistic, the corresponding distribution, known as the $t$-distribution, varies from the normal distribution in shape, in that more of the area is allocated to the tails of the density curve than in a normal distribution.
VAR-7.A.2 As the degrees of freedom increase, the area in the tails of a $t$-distribution decreases.
UNC-4
An interval of values should be used to estimate parameters, in order to account for uncertainty.
UNC-4.O
Identify an appropriate confidence interval procedure for a population mean, including the mean difference between values in matched pairs. [Skill 1.D]
UNC-4.O.1 Because $\sigma$ is typically not known for distributions of quantitative variables, the appropriate confidence interval procedure for estimating the population mean of one quantitative variable for one sample is a one-sample $t$-interval for a mean.
UNC-4.O.2 For one quantitative variable, $X$, that is normally distributed, the distribution of $t = \dfrac{(\overline{x} - \mu)}{\frac{s}{\sqrt{n}}}$ is a $t$-distribution with $n-1$ degrees of freedom.
UNC-4.O.3 Matched pairs can be thought of as one sample of pairs. Once differences between pairs of values are found, inference for confidence intervals proceeds as for a population mean.
UNC-4.P
Verify the conditions for calculating confidence intervals for a population mean, including the mean difference between values in matched pairs. [Skill 4.C]
UNC-4.P.1 In order to calculate confidence intervals to estimate a population mean, we must check for independence and that the sampling distribution is approximately normal:
a. To check for independence:
i. Data should be collected using a random sample or a randomized experiment.
ii. When sampling without replacement, check that $n \leq 10\%N$, where $N$ is the size of the population.
b. To check that the sampling distribution of $\overline{x}$ is approximately normal (shape):
i. If the observed distribution is skewed, $n$ should be greater than 30.
ii. If the sample size is less than 30, the distribution of the sample data should be free from strong skewness and outliers.
UNC-4.Q
Determine the margin of error for a given sample size for a one-sample $t$-interval. [Skill 3.D]
UNC-4.Q.1 The critical value $t^*$ with $n-1$ degrees of freedom can be found using a table or computer-generated output.
UNC-4.Q.2 The standard error for a sample mean is given by $SE = \dfrac{s}{\sqrt{n}}$, where $s$ is the sample standard deviation.
UNC-4.Q.3 For a one-sample $t$-interval for a mean, the margin of error is the critical value ($t^*$) times the standard error ($SE$), which equals $t^*\left(\dfrac{s}{\sqrt{n}}\right)$.
UNC-4.R
Calculate an appropriate confidence interval for a population mean, including the mean difference between values in matched pairs. [Skill 3.D]
UNC-4.R.1 The point estimate for a population mean is the sample mean, $\overline{x}$.
UNC-4.R.2 For the population mean for one sample with unknown population standard deviation, the confidence interval is $\overline{x} \pm t^* \dfrac{s}{\sqrt{n}}$.
Boundary statement: Formulas for interval estimates do not appear explicitly on the AP Statistics Formula Sheet provided with the AP Statistics Exam. However, these formulas do not need to be memorized, as they can be constructed based on the general test statistic formula and the relevant standard error formulas that are provided on the formula sheet.
Source: College Board AP Course and Exam Description · 출처: College Board AP Course and Exam Description
What a confidence interval means
A one-sample $t$ interval for $\mu$:
$$\bar{x}\pm t^{*}\frac{s}{\sqrt{n}}.$$
$t^{*}$ is the critical value with $df=n-1$. Conditions: random sample, Normal/Large Sample (population normal, or $n\ge 30$ by the CLT, or a roughly symmetric sample with no outliers), and the 10% condition. Interpret the interval and the confidence level in context.
Worked example. A random sample of $n=25$ has $\bar{x}=50$ and $s=8$. For a $95\%$ interval, $df=24$ gives $t^*=2.064$:
The t-distribution has a lower peak and heavier tails than the normal"95% confident" describes the method, not one interval: over many samples about 95% of the intervals contain $\mu$ and about 5% miss it.
Explore · 탐색하기
Why a t interval is wider than a z interval
A mean interval uses $t^*$, not $1.96$, because $\sigma$ is estimated by $s$. Drag df down and watch $t^*$ grow — at $df=10$ it is $2.228$, and the interval is wider for it. Drag df up and $t^*$ falls back toward $1.96$, which is why large samples may use $z$.
7.3
Justifying a Claim About a Mean
Syllabus
English
Enduring Understanding (UNC-4): An interval of values should be used to estimate parameters, in order to account for uncertainty.
Learning Objective UNC-4.S: Interpret a confidence interval for a population mean, including the mean difference between values in matched pairs. [Skill 4.B]
UNC-4.S.1 A confidence interval for a population mean either contains the population mean or it does not, because each interval is based on data from a random sample, which varies from sample to sample.
UNC-4.S.2 We are C% confident that the confidence interval for a population mean captures the population mean.
UNC-4.S.3 An interpretation of a confidence interval for a population mean includes a reference to the sample taken and details about the population it represents.
Illustrative examples for UNC-4.S.3: For interpreting a 96% confidence interval for mean foot length for all footprints found in a cave based on a particular randomly selected sample of footprints in the cave: "We are 96% confident that the mean foot length for all footprints found in the cave falls within the confidence interval" (based on 2000 FRQ 2).
Learning Objective UNC-4.T: Justify a claim based on a confidence interval for a population mean, including the mean difference between values in matched pairs. [Skill 4.D]
UNC-4.T.1 A confidence interval for a population mean provides an interval of values that may provide sufficient evidence to support a particular claim in context.
Learning Objective UNC-4.U: Identify the relationships between sample size, width of a confidence interval, confidence level, and margin of error for a population mean. [Skill 4.A]
UNC-4.U.1 When all other things remain the same, the width of a confidence interval for a population mean tends to decrease as the sample size increases.
UNC-4.U.2 For a single mean, the width of the interval is proportional to $\dfrac{1}{\sqrt{n}}$.
UNC-4.U.3 For a given sample, the width of the confidence interval for a population mean increases as the confidence level increases.
한국어
지속적 이해 (UNC-4): 불확실성을 고려하기 위해 모수를 추정하기 위해 값의 구간을 사용해야 한다.
학습 목표 UNC-4.S: 매칭 페어(value) 간의 평균 차이까지 포함하여 모평균에 대한 신뢰구간을 해석한다. [스킬 4.B]
UNC-4.S.1 각 신뢰구간은 랜덤 샘플에서 얻은 데이터를 기반으로 하므로 샘플마다 변이하며, 따라서 모평균에 대한 신뢰구간은 모평균을 포함하거나 포함하지 않는다.
UNC-4.S.2 우리는 C%의 확신으로 모평균에 대한 신뢰구간이 모평균을 포착한다고 믿는다.
UNC-4.S.3 모평균에 대한 신뢰구간의 해석에는 취한 샘플에 대한 언급과 그것이 대표하는_CPulation에 대한 세부 사항이 포함되어야 한다.
UNC-4.S.3의 예시: 특정 랜덤 샘플을 기준으로 동굴에서 발견된 모든 발자국에 대한 평균 발 길이 96% 신뢰구간을 해석할 때: "우리는 96%의 확신으로 동굴에서 발견된 모든 발자국의 평균 발 길이가 신뢰구간 내에 있음을 믿는다" (2000 FRQ 2 기준).
학습 목표 UNC-4.T: 매칭 페어(value) 간의 평균 차이까지 포함하여 모평균에 대한 신뢰구간에 기반한 주장을 정당화한다. [스킬 4.D]
UNC-4.T.1 모평균에 대한 신뢰구간은 맥락 내에서 특정 주장을 지지할 충분한 증거를 제공할 수 있는 값의 구간을 제공한다.
학습 목표 UNC-4.U: 모평균에 대한 표본 크기, 신뢰구간의 폭, 신뢰수준 및 오차 한계 사이의 관계를 식별한다. [스킬 4.A]
UNC-4.U.1 다른 모든 조건이 동일할 때, 모평균에 대한 신뢰구간의 폭은 표본 크기가 증가함에 따라 감소하는 경향이 있다.
UNC-4.U.2 단일 평균의 경우, 구간의 폭은 $\dfrac{1}{\sqrt{n}}$에 비례한다.
UNC-4.U.3 주어진 표본에서 모평균에 대한 신뢰구간의 폭은 신뢰 수준이 높아질수록 커진다.
Source: College Board AP Course and Exam Description · 출처: College Board AP Course and Exam Description
As with proportions: a claimed mean inside the interval is plausible; outside the interval, the data give evidence against it. Answer in context using the plausible range.
7.4
Setting Up a Test for a Mean
Syllabus
English
Enduring Understanding (VAR-7): The $t$-distribution may be used to model variation.
Learning Objective VAR-7.B: Identify an appropriate testing method for a population mean with unknown $\sigma$, including the mean difference between values in matched pairs. [Skill 1.E]
VAR-7.B.1 The appropriate test for a population mean with unknown $\sigma$ is a one-sample $t$-test for a population mean.
VAR-7.B.2 Matched pairs can be thought of as one sample of pairs. Once differences between pairs of values are found, inference for significance testing proceeds as for a population mean.
Learning Objective VAR-7.C: Identify the null and alternative hypotheses for a population mean with unknown $\sigma$, including the mean difference between values in matched pairs. [Skill 1.F]
VAR-7.C.1 The null hypothesis for a one-sample $t$-test for a population mean is $H_0 : \mu = \mu_0$, where $\mu_0$ is the hypothesized value. Depending upon the situation, the alternative hypothesis is $H_a : \mu < \mu_0$, or $H_a : \mu > \mu_0$, or $H_a : \mu \neq \mu_0$.
VAR-7.C.2 When finding the mean difference, $\mu_d$, between values in a matched pair, it is important to define the order of subtraction.
Learning Objective VAR-7.D: Verify the conditions for the test for a population mean, including the mean difference between values in matched pairs. [Skill 4.C]
VAR-7.D.1 In order to make statistical inferences when testing a population mean, we must check for independence and that the sampling distribution is approximately normal:
a. To check for independence:
i. Data should be collected using a random sample or a randomized experiment.
ii. When sampling without replacement, check that $n \leq 10\%N$.
b. To check that the sampling distribution of $\overline{x}$ is approximately normal (shape):
i. If the observed distribution is skewed, $n$ should be greater than 30.
ii. If the sample size is less than 30, the distribution of the sample data should be free from strong skewness and outliers.
한국어
지속적 이해 (VAR-7):$t$ 분포는 변이를 모델링하는 데 사용될 수 있다.
학습 목표 VAR-7.B: unknown $\sigma$인 모평균에 대한 적절한 검정 방법을 식별하고, 매칭된 쌍의 값 간 평균 차이를 포함한다. [기술 1.E]
VAR-7.B.1 unknown $\sigma$인 모평균에 대한 적절한 검정은 모평균에 대한 일표본 $t$-검정이다.
VAR-7.B.2 매칭된 쌍은 한 쌍의 표본으로 간주할 수 있다. 쌍 간의 차이를 구한 후, 유의성 검정에 대한 추론은 모평균에 대해 진행하는 것과 같다.
학습 목표 VAR-7.C: unknown $\sigma$인 모평균에 대한 영가설과 대립가설을 식별하고, 매칭된 쌍의 값 간 평균 차이를 포함한다. [기술 1.F]
VAR-7.C.1 모평균에 대한 일표본 $t$-검정의 영가설은 $H_0 : \mu = \mu_0$이며, 여기서 $\mu_0$는 가설값이다. 상황에 따라 대립가설은 $H_a : \mu < \mu_0$, 또는 $H_a : \mu > \mu_0$, 또는 $H_a : \mu \neq \mu_0$일 수 있다.
VAR-7.C.2 매칭된 쌍의 값 간 평균 차이 $\mu_d$를 구할 때는 뺄셈 순서를 명시하는 것이 중요하다.
학습 목표 VAR-7.D: 모평균에 대한 검정 조건을 확인하고, 매칭된 쌍의 값 간 평균 차이를 포함한다. [기술 4.C]
VAR-7.D.1 모평균에 대한 검정 시 통계적 추론을 하려면 독립성과 표본 분포가 근사적으로 정규분포임을 확인해야 한다:
a. 독립성 확인:
i. 데이터는 무작위 표본 또는 무작위 배정 실험을 통해 수집되어야 합니다.
ii. 무반복 표본 추출 시, $n \leq 10\%N$인지 확인합니다.
b. $\overline{x}$의 표본분포가 대략적으로 정규분포임을 확인하기 위해 (모양):
i. 관측된 분포가 치우쳐 있다면, $n$은 30보다 커야 한다.
ii. 표본 크기가 30 미만이면, 표본 데이터의 분포는 강한 치우침과 이단치(outlier)가 없어야 한다.
Source: College Board AP Course and Exam Description · 출처: College Board AP Course and Exam Description
What a p-value means
State hypotheses about $\mu$: $H_0:\mu=\mu_0$ versus $H_a:\mu\neq\mu_0$ (or $<,>$). Check the same conditions. The one-sample $t$ statistic:
This $t$ is far out in the tail (two-tailed $p<0.01$), so reject $H_0$ – strong evidence the mean is not $45$. Notice $45$ also falls outside the $95\%$ interval $(46.7,53.3)$, the same conclusion by two routes.
7.5
Carrying Out a Test for a Mean
Syllabus
Enduring Understanding
Learning Objective
Essential Knowledge
VAR-7
The $t$-distribution may be used to model variation.
VAR-7.E
Calculate an appropriate test statistic for a population mean, including the mean difference between values in matched pairs. [Skill 3.E]
VAR-7.E.1 For a single quantitative variable when random sampling with replacement from a population that can be modeled with a normal distribution with mean $\mu$ and standard deviation $\sigma$, the sampling distribution of $t = \dfrac{\overline{x} - \mu}{\frac{s}{\sqrt{n}}}$ has a $t$-distribution with $n - 1$ degrees of freedom.
Boundary statement: The formulas for test statistics do not appear explicitly on the AP Statistics Formula Sheet provided with the AP Statistics Exam. However, these formulas do not need to be memorized, as they can be constructed based on the general test statistic formula and the relevant standard error formulas that are provided on the formula sheet.
DAT-3
Significance testing allows us to make decisions about hypotheses within a particular context.
DAT-3.E
Interpret the $p$-value of a significance test for a population mean, including the mean difference between values in matched pairs. [Skill 4.B]
DAT-3.E.1 An interpretation of the $p$-value of a significance test for a population mean should recognize that the $p$-value is computed by assuming that the null hypothesis is true, i.e., by assuming that the true population mean is equal to the particular value stated in the null hypothesis.
DAT-3.F
Justify a claim about the population based on the results of a significance test for a population mean. [Skill 4.E]
DAT-3.F.1 A formal decision explicitly compares the $p$-value to the significance $\alpha$. If the $p$-value $\leq \alpha$, then reject the null hypothesis, $H_0 : \mu = \mu_0$. If the $p$-value $> \alpha$, then fail to reject the null hypothesis.
DAT-3.F.2 The results of a significance test for a population mean can serve as the statistical reasoning to support the answer to a research question about the population that was sampled.
Source: College Board AP Course and Exam Description · 출처: College Board AP Course and Exam Description
Find the $p$-value from the $t$-distribution with $df=n-1$, compare to $\alpha$, and conclude in context – reject or fail to reject $H_0$, then state what that means for the claim. Show the test name, statistic, $df$, and $p$-value.
Explore · 탐색하기
Read a p-value off the t curve
The p-value is the shaded tail area beyond your $t$ statistic — both tails for a two-tailed $H_a$. The dashed normal curve behind $t$ shows what you would have got by wrongly using $z$: at small df the $t$ tail is visibly fatter, so the true p-value is larger than the normal would suggest.
7.6
Confidence Interval for a Difference of Two Means
Syllabus
Enduring Understanding
Learning Objective
Essential Knowledge
UNC-4
An interval of values should be used to estimate parameters, in order to account for uncertainty.
UNC-4.V
Identify an appropriate confidence interval procedure for a difference of two population means. [Skill 1.D]
UNC-4.V.1 Consider a simple random sample from population 1 of size $n_1$, mean $\mu_1$, and standard deviation $\sigma_1$ and a second simple random sample from population 2 of size $n_2$, mean $\mu_2$, and standard deviation $\sigma_2$. If the distributions of populations 1 and 2 are normal or if both $n_1$ and $n_2$ are greater than 30, then the sampling distribution of the difference of means, $\overline{x}_1 - \overline{x}_2$ is also normal. The mean for the sampling distribution of $\overline{x}_1 - \overline{x}_2$ is $\mu_1 - \mu_2$. The standard deviation of $\overline{x}_1 - \overline{x}_2$ is $\sqrt{\dfrac{(\sigma_1)^2}{n_1} + \dfrac{(\sigma_2)^2}{n_2}}$.
UNC-4.V.2 The appropriate confidence interval procedure for one quantitative variable for two independent samples is a two-sample $t$-interval for a difference between population means.
UNC-4.W
Verify the conditions to calculate confidence intervals for the difference of two population means. [Skill 4.C]
UNC-4.W.1 In order to calculate confidence intervals to estimate a difference of population means, we must check for independence and that the sampling distribution is approximately normal:
a. To check for independence:
i. Data should be collected using two independent, random samples or a randomized experiment.
ii. When sampling without replacement, check that $n_1 \leq 10\%N_1$ and $n_2 \leq 10\%N_2$.
b. To check that the sampling distribution of $(\overline{x}_1 - \overline{x}_2)$ should be approximately normal (shape):
i. If the observed distributions are skewed, both $n_1$ and $n_2$ should be greater than 30.
UNC-4.X
Determine the margin of error for the difference of two population means. [Skill 3.D]
UNC-4.X.1 For the difference of two sample means, the margin of error is the critical value ($t^*$) times the standard error ($SE$) of the difference of two means.
UNC-4.X.2 The standard error for the difference in two sample means with sample standard deviations, $s_1$ and $s_2$, is $\sqrt{\dfrac{(s_1)^2}{n_1} + \dfrac{(s_2)^2}{n_2}}$.
UNC-4.Y
Calculate an appropriate confidence interval for a difference of two population means. [Skill 3.D]
UNC-4.Y.1 The point estimate for the difference of two population means is the difference in sample means, $\overline{x}_1 - \overline{x}_2$.
UNC-4.Y.2 For a difference of two population means where the population standard deviations are not known, the confidence interval is $(\overline{x}_1 - \overline{x}_2) \pm t^* \sqrt{\dfrac{s_1^2}{n_1} + \dfrac{s_2^2}{n_2}}$ where $\pm t^*$ are the critical values for the central C% of a $t$-distribution with appropriate degrees of freedom that can be found using technology.
Boundary statement: Formulas for interval estimates do not appear explicitly on the AP Statistics Formula Sheet provided with the AP Statistics Exam. However, these formulas do not need to be memorized, as they can be constructed based on the general test statistic formula and the relevant standard error formulas that are provided on the formula sheet.
Source: College Board AP Course and Exam Description · 출처: College Board AP Course and Exam Description
Conditions must hold in both samples. (Use technology for the $df$; do not pool the variances on the AP exam.)
Randomisation underpins fair comparison of two groups in a mean difference test
7.7
Justifying a Claim About Two Means
Syllabus
Enduring Understanding
Learning Objective
Essential Knowledge
UNC-4
An interval of values should be used to estimate parameters, in order to account for uncertainty.
UNC-4.Z
Interpret a confidence interval for a difference of population means. [Skill 4.B]
UNC-4.Z.1 In repeated random sampling with the same sample size, approximately C% of confidence intervals created will capture the difference of population means.
UNC-4.Z.2 An interpretation for a confidence interval for the difference of two population means should include a reference to the samples taken and details about the populations they represent.
Illustrative examples for UNC-4.Z.2: For interpreting a confidence interval for a difference between mean response times for two fire stations (northern - southern): "Based on these samples, one can be 95 percent confident that the difference in the population mean response times (northern - southern) is between -2.37 minutes and 0.37 minutes" (2009 FRQ 4).
UNC-4.AA
Justify a claim based on a confidence interval for a difference of population means. [Skill 4.D]
UNC-4.AA.1 A confidence interval for a difference of population means provides an interval of values that may provide sufficient evidence to support a particular claim in context.
UNC-4.AB
Identify the effects of sample size on the width of a confidence interval for the difference of two means. [Skill 4.A]
UNC-4.AB.1 When all other things remain the same, the width of the confidence interval for the difference of two means tends to decrease as the sample sizes increase.
Source: College Board AP Course and Exam Description · 출처: College Board AP Course and Exam Description
If the interval for $\mu_1-\mu_2$ contains $0$, the data are consistent with equal means; if it excludes $0$, there is evidence of a difference in that direction. Interpret in context.
7.8
Setting Up a Test for a Difference of Means
Syllabus
Enduring Understanding
Learning Objective
Essential Knowledge
VAR-7
The $t$-distribution may be used to model variation.
VAR-7.F
Identify an appropriate selection of a testing method for a difference of two population means. [Skill 1.E]
VAR-7.F.1 For a quantitative variable, the appropriate test for a difference of two population means is a two-sample $t$-test for a difference of two population means.
VAR-7.G
Identify the null and alternative hypotheses for a difference of two population means. [Skill 1.F]
VAR-7.G.1 The null hypothesis for a two-sample $t$-test for a difference of two population means, $\mu_1$ and $\mu_2$, is: $H_0 : \mu_1 - \mu_2 = 0$, or $H_0 : \mu_1 = \mu_2$. The alternative hypothesis is $H_a : \mu_1 - \mu_2 < 0$, or $H_a : \mu_1 - \mu_2 > 0$, or $H_a : \mu_1 - \mu_2 \neq 0$, or $H_a : \mu_1 > \mu_2$, or $H_a : \mu_1 < \mu_2$, or $H_a : \mu_1 \neq \mu_2$.
VAR-7.H
Verify the conditions for the significance test for the difference of two population means. [Skill 4.C]
VAR-7.H.1 In order to make statistical inferences when testing a difference between population means, we must check for independence and that the sampling distribution is approximately normal:
a. Individual observations should be independent:
i. Data should be collected using simple random samples or a randomized experiment.
ii. When sampling without replacement, check that $n_1 \leq 10\%N_1$ and $n_2 \leq 10\%N_2$.
b. The sampling distribution of $\overline{x}_1 - \overline{x}_2$ should be approximately normal (shape).
i. If the observed distribution is skewed, both $n_1$ and $n_2$ should be greater than 30.
ii. If the sample size is less than 30, the distribution of the sample data should be free from strong skewness and outliers. This should be checked for BOTH samples.
Source: College Board AP Course and Exam Description · 출처: College Board AP Course and Exam Description
Hypotheses: $H_0:\mu_1=\mu_2$ versus $H_a:\mu_1\neq\mu_2$ (or $<,>$). Distinguish two independent samples from paired data 配对数据 – for paired data (before/after, matched subjects), first take the differences and run a one-sample$t$ procedure on them.
VAR-7
The $t$-distribution may be used to model variation.
VAR-7.I
Calculate an appropriate test statistic for a difference of two means. [Skill 3.E]
VAR-7.I.1 For a single quantitative variable, data collected using independent random samples or a randomized experiment from two populations, each of which can be modeled with a normal distribution, the sampling distribution of $t = \dfrac{(\overline{x}_1 - \overline{x}_2) - (\mu_1 - \mu_2)}{\sqrt{\dfrac{s_1^2}{n_1} + \dfrac{s_2^2}{n_2}}}$ is an approximate $t$-distribution with degrees of freedom that can be found using technology. The degrees of freedom fall between the smaller of $n_1 - 1$ and $n_2 - 1$ and $n_1 + n_2 - 2$.
Illustrative examples for VAR-7.I.1: In a study comparing mean recovery times for two surgical procedures to repair a torn anterior cruciate ligament (ACL), the group receiving one procedure had a sample size of 110, while the group receiving the other procedure had a sample size of 100. The degrees of freedom fall between 100 (the smaller of 110 and 100) and 208 (110 + 100 - 2). The degrees of freedom may be determined using technology. If the test statistic for this study is $t \approx 7.13$, then the $p$-value is the area greater than 7.13 for a $t$-distribution with $df = 207.18$ (2018 FRQ 4).
Boundary statement: The formulas for test statistics do not appear explicitly on the AP Statistics Formula Sheet provided with the AP Statistics Exam. However, these formulas do not need to be memorized, as they can be constructed based on the general test statistic formula and the standard error formulas for each of the relevant test statistics that are provided on the formula sheet.
DAT-3
Significance testing allows us to make decisions about hypotheses within a particular context.
DAT-3.G
Interpret the $p$-value of a significance test for a difference of population means. [Skill 4.B]
DAT-3.G.1 An interpretation of the $p$-value of a significance test for a two-sample difference of population means should recognize that the $p$-value is computed by assuming that the null hypothesis is true, i.e., by assuming that the true population means are equal to each other.
DAT-3.H
Justify a claim about the population based on the results of a significance test for a difference of two population means in context. [Skill 4.E]
DAT-3.H.1 A formal decision explicitly compares the $p$-value to the significance $\alpha$. If the $p$-value $\leq \alpha$, then reject the null hypothesis, $H_0 : \mu_1 - \mu_2 = 0$, or $H_0 : \mu_1 = \mu_2$. If the $p$-value $> \alpha$, then fail to reject the null hypothesis.
DAT-3.H.2 The results of a significance test for a two-sample test for a difference between two population means can serve as the statistical reasoning to support the answer to a research question about the populations that were sampled.
Source: College Board AP Course and Exam Description · 출처: College Board AP Course and Exam Description
Get the $p$-value (technology for $df$), compare to $\alpha$, conclude in context.
7.10
Selecting and Communicating a Procedure
Syllabus
English
This topic is intended to focus on the skill of selecting an appropriate inference procedure, now that students have a range of options. Students should be given opportunities to practice when and how to apply all learning objectives relating to inference involving proportions or means.
한국어
이 주제는 학생들이 다양한 선택지를拥有了now, 적절한 추론 절차를 선택하는 스킬에 집중하기 위한 것이다. 학생들에게 비율 또는 평균을 포함하는 모든 학습 목표와 관련된 추론을 언제 및 어떻게 적용할지 연습할 기회를 제공해야 한다.
Source: College Board AP Course and Exam Description · 출처: College Board AP Course and Exam Description
The hardest exam skill is choosing the right procedure: one or two samples? proportion or mean? paired or independent? confidence interval or test? Read the question for what is being estimated or claimed, then name the procedure, check its conditions, carry it out, and communicate the conclusion clearly with numbers and context.
7.10
Exam tips
Use t-procedures for means (population $\sigma$ unknown) — the t-distribution has heavier tails than normal.
Check conditions: random, independent, and roughly normal (or large $n$).
Interpret an interval and a test in context, always tied to the parameter (the true mean).
Match the right procedure: one-sample, two-sample, or paired (look for a natural pairing).
State the degrees of freedom; for a two-sample $t$-test use technology's value (or, by hand, the conservative smaller $n-1$).
8
Inference for Categorical Data: Chi-Square · 범주형 데이터에 대한 추론: 카이제곱
Enduring Understanding (VAR-1): Given that variation may be random or not, conclusions are uncertain.
Learning Objective VAR-1.J: Identify questions suggested by variation between observed and expected counts in categorical data. [Skill 1.A]
VAR-1.J.1 Variation between what we find and what we expect to find may be random or not.
한국어
지속적 이해 (VAR-1): 변동성이 우연일 수도 있고 그렇지 않을 수도 있으므로, 결론은 불확실할 수 있다.
학습 목표 VAR-1.J: 범주형 데이터에서 관측값과 기대값 사이의 변동성으로 인해 제기되는 질문을 식별한다. [스킬 1.A]
VAR-1.J.1 우리가 찾아낸 것과 우리가预期한 것 사이의 변동성은 우연일 수도 있고 그렇지 않을 수도 있다.
Source: College Board AP Course and Exam Description · 출처: College Board AP Course and Exam Description
English
When data are counts spread across several categories, we test whether the observed counts differ from what a claim predicts. The tool is the chi-square 卡方 ($\chi^2$) statistic, which adds up the standardized gaps between observed and expected counts:
A large $\chi^2$ means the observed counts are far from expected – evidence against the claim. The chi-square distribution is right-skewed and depends on its degrees of freedom 自由度.
한국어
데이터가 여러 범위에 걸친 **빈도(counts)**로 나타날 때, 관측된 빈도가 주장은 예측한 것과 다른지를 검정합니다. 도구는 카이제곱(χ²$\chi^2$) 통계량으로, 관측 빈도와 기대 빈도 사이의 표준화된 차이를 합산합니다:
VAR-8.A.1 Expected counts of categorical data are counts consistent with the null hypothesis. In general, an expected count is a sample size times a probability.
The chi-square statistic measures the distance between observed and expected counts relative to expected counts.
Chi-square distributions have positive values and are skewed right. Within a family of density curves, the skew becomes less pronounced with increasing degrees of freedom.
Learning Objective VAR-8.B: Identify the null and alternative hypotheses in a test for a distribution of proportions in a set of categorical data. [Skill 1.F]
VAR-8.B.1 For a chi-square goodness-of-fit test, the null hypothesis specifies null proportions for each category, and the alternative hypothesis is that at least one of these proportions is not as specified in the null hypothesis.
Learning Objective VAR-8.C: Identify an appropriate testing method for a distribution of proportions in a set of categorical data. [Skill 1.E]
VAR-8.C.1 When considering a distribution of proportions for one categorical variable, the appropriate test is the chi-square test for goodness of fit.
Learning Objective VAR-8.D: Calculate expected counts for the chi-square test for goodness of fit. [Skill 3.A]
VAR-8.D.1 Expected counts for a chi-square goodness-of-fit test are (sample size)(null proportion).
Learning Objective VAR-8.E: Verify the conditions for making statistical inferences when testing goodness of fit for a chi-square distribution. [Skill 4.C]
VAR-8.E.1 In order to make statistical inferences for a chi-square test for goodness of fit we must check the following:
a. To check for independence:
i. Data should be collected using a random sample or randomized experiment.
ii. When sampling without replacement, check that $n \leq 10\%N$.
b. The chi-square test for goodness of fit becomes more accurate with more observations, so large counts should be used (shape).
i. A conservative check for large counts is that all expected counts should be greater than 5.
한국어
지속적 이해 (VAR-8): 카이제곱 분포는 변동성을 모델링하는 데 사용될 수 있다.
학습 목표 VAR-8.A: 카이제곱 분포를 설명한다. [스킬 3.C]
VAR-8.A.1 범주형 데이터의 기대값은 영가설과 일치하는 횟수이다. 일반적으로 기대값은 표본 크기에 확률을 곱한 값이다.
카이제곱 통계량은 관측값과 기대값 사이의 거리를 기대값에 대해 측정한다.
카이제곱 분포는 양의 값을 가지며 오른쪽으로 치우쳐 있다. 밀도 곡선 가족 내에서 자유도가 증가함에 따라 치우침이 덜 뚜렷해진다.
학습 목표 VAR-8.B: 범주형 데이터 세트에서의 비분포 검정에 대한 영가설 및 대안가설을 식별한다. [스킬 1.F]
VAR-8.B.1 카이제곱 적합도 검정에서 영가설은 각 범주에 대한 영비율을 지정하며, 대안가설은 이 비율 중 적어도 하나가 영가설에서 지정한 바와 다르다는 것이다.
학습 목표 VAR-8.C: 범주형 데이터 세트에서의 비분포 검정에 적합한 검정 방법을 식별한다. [스킬 1.E]
VAR-8.C.1 단일 범주형 변수에 대한 비분포를 고려할 때, 적절한 검정은 카이제곱 적합도 검정이다.
학습 목표 VAR-8.D: 카이제곱 적합도 검정을 위한 기대값을 계산한다. [스킬 3.A]
VAR-8.D.1 카이제곱 적합도 검정의 기대값은 (표본 크기)(영비율)이다.
학습 목표 VAR-8.E: 카이제곱 분포에 대한 적합도 검정 시 통계적 추론을 할 수 있는 조건을 확인한다. [스킬 4.C]
VAR-8.E.1 카이제곱 적합도 검정에 대한 통계적 추론을 하기 위해 다음 사항을 확인해야 한다:
a. 독립성 확인:
i. 데이터는 무작위 표본 또는 무작위 배정 실험을 통해 수집되어야 한다.
ii. 무반복 표본 추출 시, $n \leq 10\%N$인지 확인합니다.
b. 카이제곱 적합도 검정은 관측치가 많아질수록 정확度가 높아지므로, 큰 횟수를 사용해야 한다(모양).
i. 큰 횟수에 대한 보수적 검증 기준은 모든 기대값이 5보다 커야 한다는 것이다.
Source: College Board AP Course and Exam Description · 출처: College Board AP Course and Exam Description
English
The chi-square (χ²) test
A goodness-of-fit (GOF) 拟合优度 test checks whether one categorical variable follows a claimed distribution (e.g. "the die is fair"). Hypotheses:
$$H_0:\text{the distribution is as claimed}\qquad H_a:\text{at least one proportion differs}.$$
Expected count for each category $=n\times(\text{claimed proportion})$. Conditions: random sample, all expected counts $\ge 5$, and the 10% condition.
한국어
카이제곱(χ²²) 검정
적합도(GOF) 검정은 한 범주형 변수가 주장된 분포(예:
$$H_0:\text{the distribution is as claimed}\qquad H_a:\text{at least one proportion differs}.$$
각 범주 $=n\times(\text{claimed proportion})$에 대한 기대 빈도. 조건: 무작위 표본, 모든 기대 빈도가 $\ge 5$, 그리고 10% 조건.
카이제곱 분포는 오른쪽으로 치우쳐 있습니다. 큰 통계량이 임계값을 넘은 그림자 표시 오른쪽 꼬리에 위치하면—that is where you reject the model.
VAR-8.F.2 The distribution of the test statistic assuming the null hypothesis is true (null distribution) can be either a randomization distribution or, when a probability model is assumed to be true, a theoretical distribution (chi-square).
Learning Objective VAR-8.G: Determine the $p$-value for chi-square test for goodness of fit significance test. [Skill 3.E]
VAR-8.G.1 The $p$-value for a chi-square test for goodness of fit for a number of degrees of freedom is found using the appropriate table or computer generated output.
Enduring Understanding (DAT-3): Significance testing allows us to make decisions about hypotheses within a particular context.
Learning Objective DAT-3.I: Interpret the $p$-value for the chi-square test for goodness of fit. [Skill 4.B]
DAT-3.I.1 An interpretation of the $p$-value for the chi-square test for goodness of fit is the probability, given the null hypothesis and probability model are true, of obtaining a test statistic as, or more, extreme than the observed value.
Learning Objective DAT-3.J: Justify a claim about the population based on the results of a chi-square test for goodness of fit. [Skill 4.E]
DAT-3.J.1 A decision to either reject or fail to reject the null hypothesis is based on comparison of the $p$-value to the significance level, $\alpha$.
DAT-3.J.2 The results of a chi-square test for goodness of fit can serve as the statistical reasoning to support the answer to a research question about the population that was sampled.
한국어
지속적 이해 (VAR-8): 카이제곱 분포는 변동성을 모델링하는 데 사용될 수 있다.
학습 목표 VAR-8.F: 카이제곱 적합도 검정에 적절한 통계량을 계산한다. [스킬 3.E]
VAR-8.F.2 영가설이 참일 때 검정 통계량의 분포(영분포)는 무작위 배정 분포이거나, 확률 모델을 참이라고 가정할 때는 이론적 분포(카이제곱)일 수 있다.
학습 목표 VAR-8.G: 카이제곱 적합도 검정 유의성 검정의 $p$-값을 결정한다. [스킬 3.E]
VAR-8.G.1 자유도의 수에 따른 카이제곱 적합도 검정의 $p$-값은 적절한 표나 컴퓨터 생성 출력물을 사용하여 찾는다.
지속적 이해 (DAT-3): 유의성 검정은 특정 맥락 내에서의 가설에 대한 의사결정을 가능하게 한다.
학습 목표 DAT-3.I: 카이제곱 적합도 검정의 $p$-값을 해석한다. [스킬 4.B]
DAT-3.I.1 카이제곱 적합도 검정의 $p$-값에 대한 해석은 영가설과 확률 모델이 참이라는 조건 하에서 관측된 값보다 같거나 더 극단적인 검정 통계량을 얻을 확률이다.
학습 목표 DAT-3.J: 카이제곱 적합도 검정 결과를 바탕으로 모집단에 대한 주장을 정당화한다. [스킬 4.E]
DAT-3.J.1 영가설을 기각하거나 기각할 수 없는 결정은 $p$-값과 유의수준 $\alpha$의 비교에 근거한다.
DAT-3.J.2 카이제곱 적합도 검정 결과는 표본된 모집단에 대한 연구 질문에 대한 답을 지지하는 통계적 추론으로 활용될 수 있다.
Source: College Board AP Course and Exam Description · 출처: College Board AP Course and Exam Description
English
Compute $\chi^2=\sum\dfrac{(O-E)^2}{E}$ with $df=(\text{number of categories})-1$. Find the $p$-value from the chi-square distribution (upper tail), compare to $\alpha$, and conclude in context. A large component of the sum points to the category that deviates most.
Worked example. A die rolled $60$ times gives counts $8,10,12,9,11,10$. If it is fair, each expected count is $60/6=10$, so
with $df=6-1=5$. Write out every category, including the two that match their expected count exactly and so add $0$ – the sum runs over all six categories, and $df$ counts categories, not just the ones that differ. This $\chi^2$ is small (a large $p$-value), so we fail to reject$H_0$ – no evidence the die is unfair.
한국어
$\chi^2=\sum\dfrac{(O-E)^2}{E}$를 $df=(\text{number of categories})-1$과 함께 계산하십시오. 카이제곱 분포에서 $p$-value를 구하고(오른쪽 꼬리), $\alpha$와 비교하여 문맥 속에서 결론을 내리십시오. 합산의 큰 구성 요소는 가장 편차가 큰 범주를 가리킵니다.
카이제곱은 관측된 빈도와 귀무가설 하에서 기대되는 빈도를 비교합니다
해설 예시. 주사위를 $60$회 굴렸을 때 빈도가 $8,10,12,9,11,10$입니다. 공평하다면 각 기대 빈도는 $60/6=10$이므로,
$df=6-1=5$를 사용하여. 모든 범위를 나열하고, 예상 개수와 정확히 일치하는 두 가지 범위를 포함하여 $0$를 더하십시오 – 합은 모든 6개 범위에 대해 이루어지며, $df$는 단순히 다른 범위가 아닌 모든 범위를 세는 것입니다. 이 $\chi^2$는 작습니다(큰 $p$-값), 따라서 우리는 $H_0$를 기각하지 못합니다 – 주사위가 불공정하다는 증거가 없습니다.
Explore · 탐색하기
Explore the chi-square distribution and its p-value · 카이제곱 분포와 그 p-value 탐색하기
The p-value is the area in the right tail beyond your test statistic, so a larger$\chi^2$ means a smaller p-value. Drag $\chi^2$ to watch that area shrink, and drag df to see the whole family change shape — strongly right-skewed at small df, more symmetric as df grows. · p-값은 검정 통계량 이상의 우측 꼬리 면적이므로, 더 큰$\chi^2$은 더 작은 p-값을 의미합니다. $\chi^2$을 드래그하여 면적이 줄어드는 것을 확인하고, df를 드래그하여 전체 집합의 모양 변화를 관찰할 수 있습니다. df가 작을 때는 우측 꼬리가 심하게 치우쳐 있으며, df가 커질수록 대칭성에 가까워집니다.
8.4
Expected Counts in Two-Way Tables · 2차원 표의 예상 개수
Syllabus
English
Enduring Understanding (VAR-8): The chi-square distribution may be used to model variation.
Learning Objective VAR-8.H: Calculate expected counts for two-way tables of categorical data. [Skill 3.A]
VAR-8.H.1 The expected count in a particular cell of a two-way table of categorical data can be calculated using the formula:
This is the count you would see if the row and column variables were unrelated.
Worked example. In a two-way table a cell's row total is $40$, its column total is $50$, and the grand total is $200$. Its expected count is $E=\dfrac{40\times50}{200}=10$. Repeating for every cell gives the expected table to compare against the observed one.
해설 예제. 2차원 표에서 한 셀의 행 합계가 $40$, 열 합계가 $50$이며, 전체 합계가 $200$라면, 그 셀의 예상 개수는 $E=\dfrac{40\times50}{200}=10$입니다. 이를 모든 셀에 대해 반복하면 관측된 표와 비교할 수 있는 예상 표를 얻을 수 있습니다.
카이제곱 검정 전 범주형 계수를 정리한 스프레드시트
8.5
Homogeneity or Independence? · 균일성 검정인지 독립성 검정인가?
Syllabus
English
Enduring Understanding (VAR-8): The chi-square distribution may be used to model variation.
Learning Objective VAR-8.I: Identify the null and alternative hypotheses for a chi-square test for homogeneity or independence. [Skill 1.F]
VAR-8.I.1 The appropriate hypotheses for a chi-square test for homogeneity are:
$H_0$: There is no difference in distributions of a categorical variable across populations or treatments.
$H_a$: There is a difference in distributions of a categorical variable across populations or treatments.
VAR-8.I.2 The appropriate hypotheses for a chi-square test for independence are:
$H_0$: There is no association between two categorical variables in a given population or the two categorical variables are independent.
$H_a$: Two categorical variables in a population are associated or dependent.
Learning Objective VAR-8.J: Identify an appropriate testing method for comparing distributions in two-way tables of categorical data. [Skill 1.E]
VAR-8.J.1 When comparing distributions to determine whether proportions in each category for categorical data collected from different populations are the same, the appropriate test is the chi-square test for homogeneity.
VAR-8.J.2 To determine whether row and column variables in a two-way table of categorical data might be associated in the population from which the data were sampled, the appropriate test is the chi-square test for independence.
Learning Objective VAR-8.K: Verify the conditions for making statistical inferences when testing a chi-square distribution for independence or homogeneity. [Skill 4.C]
VAR-8.K.1 In order to make statistical inferences for a chi-square test for two-way tables (homogeneity or independence), we must verify the following:
a. To check for independence:
i. For a test for independence: Data should be collected using a simple random sample.
ii. For a test for homogeneity: Data should be collected using a stratified random sample or randomized experiment.
iii. When sampling without replacement, check that $n \leq 10\%N$.
b. The chi-square tests for independence and homogeneity become more accurate with more observations, so large counts should be used (shape).
i. A conservative check for large counts is that all expected counts should be greater than 5.
한국어
지속적 이해 (VAR-8): 카이제곱 분포는 변동성을 모델링하는 데 사용될 수 있다.
학습 목표 VAR-8.I: 치제동질성 검정 또는 독립성 검정을 위한 귀무가설과 대안가설을 식별한다. [기술 1.F]
VAR-8.I.1 치제동질성 검정에 적합한 가설은 다음과 같다:
$H_0$: 모집단이나 처리 간 범주형 변수의 분포에는 차이가 없다.
$H_a$: 모집단이나 처리 간 범주형 변수의 분포에는 차이가 있다.
VAR-8.I.2 치제독립성 검정에 적합한 가설은 다음과 같다:
$H_0$: 주어진 모집단 내 두 범주형 변수 간에 연관성이 없거나 두 범주형 변수는 서로 독립이다.
$H_a$: 모집단 내 두 범주형 변수는 연관되어 있거나 종속적이다.
학습 목표 VAR-8.J: 범주형 데이터의 이차원 표에서 분포를 비교할 때 적절한 검정 방법을 식별한다. [기술 1.E]
VAR-8.J.1 서로 다른 모집단에서 수집한 범주형 데이터의 각 범주별 비례가 동일한지 확인하기 위해 분포를 비교할 때 적절한 검정은 치제동질성 검정이다.
VAR-8.J.2 범주형 데이터의 이차원 표에서 행 변수와 열 변수가 표본이 추출된 모집단 내에서 연관될 수 있는지를 확인하기 위해 적절한 검정은 치제독립성 검정이다.
학습 목표 VAR-8.K: 치제독립성 검정 또는 동질성 검정을 수행할 때 통계적 추론을 위한 조건을 검증한다. [기술 4.C]
VAR-8.K.1 이차원 표(동질성 또는 독립성)에 대한 치제검정의 통계적 추론을 하기 위해서는 다음을 검증해야 한다:
a. 독립성 확인:
i. 독립성 검정: 데이터는 단순 무작위 표본을 사용하여 수집되어야 한다.
ii. 동질성 검정: 데이터는 층화 무작위 표본 또는 무작위 실험을 사용하여 수집되어야 한다.
iii. 교체 없는抽样 시, $n \leq 10\%N$인지 확인한다.
b. 독립성 검정과 동질성 검정은 관측치가 많아질수록 정확해지므로, 큰 기대 빈도를 사용해야 한다(분포 형태).
i. 큰 횟수에 대한 보수적 검증 기준은 모든 기대값이 5보다 커야 한다는 것이다.
Source: College Board AP Course and Exam Description · 출처: College Board AP Course and Exam Description
English
Two tests use the same $\chi^2$ math but answer different questions:
Test for homogeneity 同质性: are the distributions of one categorical variable the same across several populations or groups (separate samples/treatments)?
Test for independence 独立性: are two categorical variables associated within a single population (one sample, two variables measured)?
The design (several samples vs one sample) decides which name and hypotheses to use.
한국어
두 검정은 동일한 $\chi^2$ 수식을 사용하지만 서로 다른 질문에 대한 답을 제공합니다:
균일성 검정: 하나의 범주형 변수의 분포가 여러 집단 또는 그룹(별개의 샘플/처치) 간에 동일한가?
독립성 검정: 두 범주형 변수가 단일 집단의 내부에서 연관되어 있는가(하나의 샘플, 두 변수 측정)?
연구 설계(여러 샘플 대 단일 샘플)에 따라 사용하는 이름과 가설이 결정됩니다.
8.6
Carrying Out a Test for Homogeneity or Independence · 균일성 또는 독립성 검정 수행
Syllabus
Enduring Understanding
Learning Objective
Essential Knowledge
VAR-8
The chi-square distribution may be used to model variation.
VAR-8.L
Calculate the appropriate statistic for a chi-square test for homogeneity or independence. [Skill 3.E]
VAR-8.L.1 The appropriate test statistic for a chi-square test for homogeneity or independence is the chi-square statistic:
Equation:$\chi^2 = \sum \dfrac{(Observed\ count - Expected\ count)^2}{Expected\ count}$, with degrees of freedom equal to: $(number\ of\ rows - 1)(number\ of\ columns - 1)$.
VAR-8.M
Determine the $p$-value for a chi-square significance test for independence or homogeneity. [Skill 3.E]
VAR-8.M.1 The $p$-value for a chi-square test for independence or homogeneity for a number of degrees of freedom is found using the appropriate table or technology.
VAR-8.M.2 For a test of independence or homogeneity for a two-way table, the $p$-value is the proportion of values in a chi-square distribution with appropriate degrees of freedom that are equal to or larger than the test statistic.
DAT-3
Significance testing allows us to make decisions about hypotheses within a particular context.
DAT-3.K
Interpret the $p$-value for the chi-square test for homogeneity or independence. [Skill 4.B]
DAT-3.K.1 An interpretation of the $p$-value for the chi-square test for homogeneity or independence is the probability, given the null hypothesis and probability model are true, of obtaining a test statistic as, or more, extreme than the observed value.
DAT-3.L
Justify a claim about the population based on the results of a chi-square test for homogeneity or independence. [Skill 4.E]
DAT-3.L.1 A decision to either reject or fail to reject the null hypothesis for a chi-square test for homogeneity or independence is based on comparison of the $p$-value to the significance level, $\alpha$.
DAT-3.L.2 The results of a chi-square test for homogeneity or independence can serve as the statistical reasoning to support the answer to a research question about the population that was sampled (independence) or the populations that were sampled (homogeneity).
Source: College Board AP Course and Exam Description · 출처: College Board AP Course and Exam Description
English
Compute expected counts, then $\chi^2=\sum\dfrac{(O-E)^2}{E}$ over all cells, with
$$df=(\text{rows}-1)(\text{columns}-1).$$
Conditions: random data, all expected counts $\ge 5$, 10% condition. Find the $p$-value, compare to $\alpha$, and conclude in context – evidence of a difference between groups (homogeneity) or of an association (independence).
한국어
예상 개수를 계산한 후, 모든 셀에 대해 $\chi^2=\sum\dfrac{(O-E)^2}{E}$를 계산하며,
$$df=(\text{rows}-1)(\text{columns}-1).$$
조건: 무작위 데이터, 모든 기대 빈도가 $\ge 5$, 10% 조건. $p$-값을 구하고 $\alpha$과 비교하여 문맥 속에서 결론을 내리십시오 – 그룹 간 차이(균등성)에 대한 증거이거나 상관관계(독립성)에 대한 증거입니다.
8.7
Choosing the Right Categorical Procedure · 적절한 범주형 절차 선택
Syllabus
English
This topic is intended to focus on the skill of selecting an appropriate inference procedure now that students have a range of options. Students should be given opportunities to practice when and how to apply all learning objectives relating to inference for categorical data.
한국어
이 단원은 학생들이 다양한 옵션을 갖추게 된 후 적절한 추론 절차를 선택하는 기술에 집중하는 것을 목적으로 한다. 학생들에게 범주형 데이터에 대한 추론과 관련된 모든 학습 목표를 언제 및 어떻게 적용할지 연습할 기회가 제공되어야 한다.
Source: College Board AP Course and Exam Description · 출처: College Board AP Course and Exam Description
English
Decide by the setup: one categorical variable against a claimed distribution $\Rightarrow$goodness-of-fit; one sample cross-classified by two variables $\Rightarrow$independence; several samples/groups compared $\Rightarrow$homogeneity. Comparing just two proportions can use either a two-proportion $z$-test or a chi-square test, but only for a two-tailed alternative, where they agree exactly ($\chi^2=z^2$). A chi-square test is always two-tailed, so it cannot give a directional conclusion: if $H_a$ is one-tailed (say $p_1>p_2$), use the $z$-test.
한국어
설정에 따라 결정: 하나의 범주형 변수와 주장된 분포 $\Rightarrow$적합도 검정; 하나의 표본이 두 변수로 교차 분류됨 $\Rightarrow$독립성 검정; 여러 표본/집단이 비교됨 $\Rightarrow$동질성 검정. 오직 두 비율을 비교할 때는 두 비율 $z$-검정 또는 카이제곱 검정을 사용할 수 있으나, 오직 양측 대안가설에서 정확히 일치함 ($\chi^2=z^2$). 카이제곱 검정은 항상 양측이므로 방향성을 가지는 결론을 내릴 수 없음: 만약 $H_a$가 일측(예 $p_1>p_2$)이라면, $z$-검정을 사용해야 함.
Explore · 탐색하기
Which chi-square test is this? · 이것은 어떤 카이제곱 검정입니까?
All three tests use the same $\chi^2$ arithmetic, so the marks are won by naming the right one. The design decides — how many samples were taken, and how many variables were measured on each unit. · 세 가지 검정 모두 같은 $\chi^2$ 연산을共用하므로, 정답을 올바르게 지목하는 것이 점수를 얻는 열쇠입니다. 검정의 설계가 이를 결정하는데, 몇 개의 표본을 취했는지, 그리고 각 단위당 몇 개의 변수를 측정했는지에 따라 달라집니다.
8.7
Exam tips · 시험 팁
English
Use $\chi^2=\sum\tfrac{(O-E)^2}{E}$ for categorical data; always divide by the expected count.
Pick the right test: goodness-of-fit (one variable), independence, or homogeneity (two-way table).
Compute expected counts as $\tfrac{\text{row total}\times\text{column total}}{\text{grand total}}$ and check each is $\ge5$.
A large $\chi^2$ (small p-value) means observed counts differ from expected by more than chance.
State degrees of freedom correctly (categories $-1$, or $(r-1)(c-1)$).
한국어
범주형 데이터에는 $\chi^2=\sum\tfrac{(O-E)^2}{E}$를 사용하고, 반드시 기대 빈도를 나눈다.
올바른 검정을 선택: 적합도 검정(한 변수), 독립성, 또는 동질성(이원 표).
기대 빈도를 $\tfrac{\text{row total}\times\text{column total}}{\text{grand total}}$로 계산하고 각 값이 $\ge5$인지 확인한다.
큰 $\chi^2$(작은 p-value)는 관측 빈도가 우연보다 기대 빈도와 더 크게 차이남을 의미함.
자유도를 올바르게 명시(카테고리 $-1$, 또는 $(r-1)(c-1)$).
9
Inference for Quantitative Data: Slopes · 정량 데이터에 대한 추론: 기울기
Enduring Understanding (VAR-1): Given that variation may be random or not, conclusions are uncertain.
Learning Objective VAR-1.K: Identify questions suggested by variation in scatter plots. [Skill 1.A]
VAR-1.K.1 Variation in points' positions relative to a theoretical line may be random or non-random.
한국어
지속적 이해 (VAR-1): 변동성이 우연일 수도 있고 그렇지 않을 수도 있으므로, 결론은 불확실할 수 있다.
학습 목표 VAR-1.K: 산점도에서의 변이에 의해 제안되는 질문을 식별한다. [기술 1.A]
VAR-1.K.1 이론적 선에 대한 점들의 위치 변동은 무작위이거나 비무작위일 수 있다.
Source: College Board AP Course and Exam Description · 출처: College Board AP Course and Exam Description
A sample scatterplot 散点图 gives a sample slope 样本斜率$b$ for the least-squares regression 回归 line – but a different sample would give a slightly different slope. So $b$ is a statistic with sampling variability 抽样变异性, estimating the true (population) slope 总体斜率$\beta$. This unit does inference 推断 for $\beta$: is there a real linear 线性 relationship, and how strong is it?
UNC-4
An interval of values should be used to estimate parameters, in order to account for uncertainty.
UNC-4.AC
Identify an appropriate confidence interval procedure for a slope of a regression model. [Skill 1.D]
UNC-4.AC.1 Consider a response variable, $y$, that is linearly related to an explanatory variable, $x$. For a simple random sample of $n$ observations, the sample regression line, $\hat{y} = a + bx$, is an estimate of the population regression line $\mu_y = \alpha + \beta x$. For a particular observation, $(x_i, y_i)$, the residual from the sample regression line, $y_i - \hat{y}_i = y_i - (a + bx_i)$, is an estimate of $y_i - (\alpha + \beta x_i)$, the deviation of the response variable from the population regression line. For all points $(x, y)$ in the population, the standard deviation of all of the deviations of the response variable from the population regression line, $\sigma$, can be estimated by the standard deviation of the residuals from the sample regression line, $s = \sqrt{\dfrac{\sum\left(y_i - \hat{y}_i\right)^2}{n-2}}$. (Note: This formula uses $n-2$ in the denominator instead of $n-1$ because two parameters, $\alpha$ and $\beta$, must be estimated to obtain the predicted values from the least-squares regression line.)
UNC-4.AC.2 For a simple random sample of $n$ observations, let $b$ represent the slope of a sample regression line. Then the mean of the sampling distribution for $b$ equals the population slope: $\mu_b = \beta$. The standard deviation of the sampling distribution for $b$ is $\sigma_b = \dfrac{\sigma}{\sigma_x \sqrt{n}}$, where $\sigma_x = \sqrt{\dfrac{\sum\left(x_i - \bar{x}\right)^2}{n}}$.
UNC-4.AC.3 The appropriate confidence interval for the slope of a regression model is a $t$-interval for the slope.
UNC-4.AD
Verify the conditions to calculate confidence intervals for the slope of a regression model. [Skill 4.C]
UNC-4.AD.1 In order to calculate a confidence interval to estimate the slope of a regression line, we must check the following:
a. The true relationship between $x$ and $y$ is linear. Analysis of residuals may be used to verify linearity.
b. The standard deviation for $y$, $\sigma_y$, does not vary with $x$. Analysis of residuals may be used to check for approximately equal standard deviations for all $x$.
c. To check for independence:
i. Data should be collected using a random sample or a randomized experiment.
ii. When sampling without replacement, check that $n \le 10\% N$.
d. For a particular value of $x$, the responses ($y$-values) are approximately normally distributed. Analysis of graphical representations of residuals may be used to check for normality.
i. If the observed distribution is skewed, $n$ should be greater than 30.
UNC-4.AE
Determine the given margin of error for the slope of a regression model. [Skill 3.D]
UNC-4.AE.1 For the slope of a regression line, the margin of error is the critical value $\left(t^*\right)$ times the standard error ($SE$) of the slope.
UNC-4.AE.2 The standard error for the slope of a regression line with sample standard deviation, $s$, is $SE = \dfrac{s}{s_x \sqrt{n-1}}$, where $s$ is the estimate of $\sigma$ and $s_x$ is the sample standard deviation of the $x$ values.
UNC-4.AF
Calculate an appropriate confidence interval for the slope of a regression model. [Skill 3.D]
UNC-4.AF.1 The point estimate for the slope of a regression model is the slope of the line of best fit, $b$.
UNC-4.AF.2 For the slope of a regression model, the interval estimate is $b \pm t^* \left(SE_b\right)$.
Source: College Board AP Course and Exam Description · 출처: College Board AP Course and Exam Description
A $t$ interval for the true slope $\beta$:
$$b\pm t^{*}\,SE_b,\qquad df=n-2,$$
where $b$ is the sample slope and $SE_b$ its standard error (read from computer output). Conditions (LINER): the true relationship is Linear, observations Independent, residuals Normal, and residuals have Equal spread (check the residual plot and a histogram of residuals), from Random data. Interpret the interval for $\beta$ in context, with units of $y$ per unit of $x$.
A random, patternless residual plot supports the conditions; a curve or a fan does not
The residual plot 残差图 is where you check Linear and Equal-spread: you want a formless cloud around zero. A curve means the relationship is not linear; a fan (spread growing with $x$) means the residuals do not have equal spread – both break a condition.
Worked example. Regression output gives slope $b=2.5$ with $SE_b=0.8$ from $n=20$ points. For a $95\%$ interval, $df=18$ gives $t^*=2.101$:
$$2.5\pm2.101(0.8)=2.5\pm1.68=(0.82,\ 4.18).$$
Because $0$ is not in the interval, there is evidence of a positive linear relationship.
Slope inference is based on the least-squares regression line through the pointsLeast-squares regression: the line that minimises the sum of squared residuals
Explore · 탐색하기
Inference for a regression slope · 회귀 기울기에 대한 추론
The sample slope varies from sample to sample; a confidence interval and t-test ask whether the true slope could be zero (no linear relationship). · 표본 기울기는 표본마다 달라지며, 신뢰구간과 t검정은 실제 기울기가 0(선형 관계 없음)일 수 있는지 묻습니다.
Enduring Understanding (UNC-4): An interval of values should be used to estimate parameters, in order to account for uncertainty.
Learning Objective UNC-4.AG: Interpret a confidence interval for the slope of a regression model. [Skill 4.B]
UNC-4.AG.1 In repeated random sampling with the same sample size, approximately C% of confidence intervals created will capture the slope of the regression model, i.e., the true slope of the population regression model.
UNC-4.AG.2 An interpretation for a confidence interval for the slope of a regression line should include a reference to the sample taken and details about the population it represents.
Learning Objective UNC-4.AH: Justify a claim based on a confidence interval for the slope of a regression model. [Skill 4.D]
UNC-4.AH.1 A confidence interval for the slope of a regression model provides an interval of values that may provide sufficient evidence to support a particular claim in context.
Learning Objective UNC-4.AI: Identify the effects of sample size on the width of a confidence interval for the slope of a regression model. [Skill 4.A]
UNC-4.AI.1 When all other things remain the same, the width of the confidence interval for the slope of a regression model tends to decrease as the sample size increases.
한국어
지속적 이해 (UNC-4): 불확실성을 고려하기 위해 모수를 추정하기 위해 값의 구간을 사용해야 한다.
학습 목표 UNC-4.AG: 회귀 모델의 기울기에 대한 신뢰구간을 해석하시오. [스킬 4.B]
UNC-4.AG.1 동일한 샘플 크기로 반복 무작위 표본을 취할 때, 생성되는 신뢰구간의 약 C%가 회귀 모델의 기울기, 즉 모집단 회귀 모델의 진짜 기울기를 포함할 것이다.
UNC-4.AG.2 회귀선의 기울기에 대한 신뢰구간의 해석에는 추출된 표본에 대한 언급과 그것이 대표하는 모집단에 대한 세부 사항이 포함되어야 한다.
학습 목표 UNC-4.AH: 회귀 모델의 기울기에 대한 신뢰구간에 근거하여 주장을 타당화하시오. [스킬 4.D]
UNC-4.AH.1 회귀 모델의 기울기에 대한 신뢰구간은 특정 문맥에서 particular claim을 지지할 충분한 증거가 될 수 있는 값들의 구간을 제공한다.
학습 목표 UNC-4.AI: 회귀 모델의 기울기에 대한 신뢰구간의 폭에 미치는 샘플 크기의 영향을 식별하시오. [스킬 4.A]
UNC-4.AI.1 다른 모든 조건이 동일할 때, 회귀 모델의 기울기에 대한 신뢰구간의 폭은 샘플 크기가 증가함에 따라 감소하는 경향이 있다.
Source: College Board AP Course and Exam Description · 출처: College Board AP Course and Exam Description
If the confidence interval for $\beta$ contains $0$, a slope of zero is plausible – no evidence of a linear relationship. If the interval is entirely positive or negative, there is evidence of a real (positive or negative) linear relationship. State the direction in context.
9.4
Setting Up a Test for a Slope
Syllabus
English
Enduring Understanding (VAR-7): The $t$-distribution may be used to model variation.
Learning Objective VAR-7.J: Identify the appropriate selection of a testing method for a slope of a regression model. [Skill 1.E]
VAR-7.J.1 The appropriate test for the slope of a regression model is a $t$-test for a slope.
Learning Objective VAR-7.K: Identify appropriate null and alternative hypotheses for a slope of a regression model. [Skill 1.F]
VAR-7.K.1 The null hypothesis for a $t$-test for a slope is: $H_0 : \beta = \beta_0$, where $\beta_0$ is the hypothesized value from the null hypothesis. The alternative hypothesis is $H_0 : \beta < \beta_0$ or $H_0 : \beta > \beta_0$, or $H_0 : \beta \neq \beta_0$.
Learning Objective VAR-7.L: Verify the conditions for the significance test for the slope of a regression model. [Skill 4.C]
VAR-7.L.1 In order to make statistical inferences when testing for the slope of a regression model, we must check the following:
a. The true relationship between $x$ and $y$ is linear. Analysis of residuals may be used to verify linearity.
b. The standard deviation for $y$, $\sigma_y$, does not vary with $x$. Analysis of residuals may be used to check for approximately equal standard deviations for all $x$.
c. To check for independence:
i. Data should be collected using a random sample or a randomized experiment.
ii. When sampling without replacement, check that $n \le 10\% N$.
d. For a particular value of $x$, the responses ($y$-values) are approximately normally distributed. Analysis of graphical representations of residuals may be used to check for normality.
i. If the observed distribution is skewed, $n$ should be greater than 30.
ii. If the sample size is less than 30, the distribution of the sample data should be free from strong skewness and outliers.
한국어
지속적 이해 (VAR-7):$t$ 분포는 변이를 모델링하는 데 사용될 수 있다.
학습 목표 VAR-7.J: 회귀 모델의 기울기에 대한 적절한 검정 방법 선택을 식별하시오. [스킬 1.E]
VAR-7.J.1 회귀 모델의 기울기에 대한 적절한 검정은 기울기에 대한 $t$-검정이다.
학습 목표 VAR-7.K: 회귀 모델의 기울기에 대한 적절한 영가설 및 대안가설을 식별하시오. [스킬 1.F]
VAR-7.K.1 기울기에 대한 $t$-검정의 영가설은 다음과 같다: $H_0 : \beta = \beta_0$, 여기서 $\beta_0$는 영가설에서 가정하는 값이다. 대안가설은 $H_0 : \beta < \beta_0$ 또는 $H_0 : \beta > \beta_0$, 또는 $H_0 : \beta \neq \beta_0$이다.
학습 목표 VAR-7.L: 회귀 모델의 기울기에 대한 유의성 검정을 위한 조건을 확인하시오. [스킬 4.C]
VAR-7.L.1 회귀 모델의 기울기에 대한 검정을 수행하여 통계적 추론을 하기 위해서는 다음 사항을 확인해야 합니다:
a. $x$과 $y$ 사이의 진짜 관계가 선형이어야 한다. 잔차 분석을 사용하여 선형성을 검증할 수 있다.
b. $y$에 대한 표준편차 $\sigma_y$가 $x$에 따라 변하지 않아야 한다. 잔차 분석을 사용하여 모든 $x$에 대해 대략적인 동일 표준편차를 확인할 수 있다.
c. 독립성 여부를 확인하기 위해:
i. 데이터는 무작위 표본 또는 무작위 배정 실험을 통해 수집되어야 합니다.
ii. 무반복 표본 추출 시, $n \le 10\% N$인지 확인합니다.
d. 특정 $x$ 값에 대해 반응($y$ 값)은 대략적으로 정규분포를 따르며, 이 경우 잔차의 그래프 표현을 사용하여 정규성을 확인할 수 있다.
i. 관측된 분포가 치우쳐 있다면, $n$은 30보다 커야 한다.
ii. 표본 크기가 30 미만이면, 표본 데이터의 분포는 강한 치우침과 이단치(outlier)가 없어야 한다.
Source: College Board AP Course and Exam Description · 출처: College Board AP Course and Exam Description
The usual test asks whether there is any linear relationship:
$$H_0:\beta=0 \quad(\text{no linear relationship})\qquad H_a:\beta\neq 0 \ (\text{or } <,\,>).$$
Check the LINER conditions. This is a $t$-test on the slope.
Check residual plots before trusting a slope CI or test
9.5
Carrying Out a Test for a Slope
Syllabus
Enduring Understanding
Learning Objective
Essential Knowledge
VAR-7
The $t$-distribution may be used to model variation.
VAR-7.M
Calculate an appropriate test statistic for the slope of a regression model. [Skill 3.E]
VAR-7.M.1 The distribution of the slope of a regression model assuming all conditions are satisfied and the null hypothesis is true (null distribution) is a $t$-distribution.
VAR-7.M.2 For simple linear regression when random sampling from a population for the response that can be modeled with a normal distribution for each value of the explanatory variable, the sampling distribution of $t = \dfrac{b - \beta}{SE_b}$ has a $t$-distribution with degrees of freedom equal to $n - 2$. When testing the slope in a simple linear regression model with one parameter, the slope, the test for the slope has $df = n - 1$.
DAT-3
Significance testing allows us to make decisions about hypotheses within a particular context.
DAT-3.M
Interpret the $p$-value of a significance test for the slope of a regression model. [Skill 4.B]
DAT-3.M.1 An interpretation of the $p$-value of a significance test for the slope of a regression model should recognize that the $p$-value is computed by assuming that the null hypothesis is true, i.e., by assuming that the true population slope is equal to the particular value stated in the null hypothesis.
DAT-3.N
Justify a claim about the population based on the results of a significance test for the slope of a regression model. [Skill 4.E]
DAT-3.N.1 A formal decision explicitly compares the $p$-value to the significance $\alpha$. If the $p$-value $\le \alpha$, then reject the null hypothesis, $H_0 : \beta = \beta_0$. If the $p$-value $> \alpha$, then fail to reject the null hypothesis.
DAT-3.N.2 The results of a significance test for the slope of a regression model can serve as the statistical reasoning to support the answer to a research question about that sample.
Source: College Board AP Course and Exam Description · 출처: College Board AP Course and Exam Description
The slope $t$ statistic:
$$t=\frac{b-0}{SE_b},\qquad df=n-2.$$
Both $b$ and $SE_b$ come straight from the regression output. Find the $p$-value from the $t$-distribution, compare to $\alpha$, and conclude in context – evidence (or not) of a linear relationship between the two variables.
Watch the tails. Regression output always prints the two-tailed$p$-value (for $H_a:\beta\neq 0$). If your $H_a$ is one-tailed, halve it – and first check the sample slope really points the way $H_a$ claims; if it points the other way, the one-tailed $p$-value is above $0.5$ and you cannot reject $H_0$.
Worked example. For the same output ($b=2.5$, $SE_b=0.8$, $n=20$), test $H_0:\beta=0$:
$$t=\frac{2.5-0}{0.8}=3.13,\qquad df=18,$$
a small $p$-value ($<0.01$), so reject $H_0$ – convincing evidence of a linear relationship. This matches the interval, which excluded $0$.
9.6
Selecting the Right Procedure
Syllabus
English
This topic is intended to focus on the skill of selecting an appropriate inference procedure now that students have a range of options. Students should be given opportunities to practice when and how to apply all learning objectives relating to inference.
한국어
이 단원은 학생들이 다양한 선택지를 갖추게 되었으므로 적절한 추론 절차를 선택하는 기술에 집중하도록 설계되었다. 학생들에게 추론과 관련된 모든 학습 목표를 적용할 때와 어떻게 적용해야 하는지에 대한 연습 기회를 제공해야 한다.
Source: College Board AP Course and Exam Description · 출처: College Board AP Course and Exam Description
Across all of inference, identify: what is estimated or claimed (a proportion, a mean, a difference, a distribution of counts, or a slope), how many samples, and which design (independent or paired; sample or experiment). Then name the procedure, verify its conditions, carry it out, and communicate the conclusion with the statistic, the $p$-value or interval, and a plain-language answer in context. This selecting-and-communicating skill is what the investigative-task question rewards most.
9.6
Exam tips
Inference for a slope tests whether the true slope is $0$ (no linear relationship).
If a slope's confidence interval includes 0, you cannot conclude a real linear relationship – the variables may still be related in a curved way.
Read the slope, standard error, t-statistic, and p-value straight from computer output – but the printed p-value is two-tailed, so halve it for a one-tailed $H_a$.
Check the regression conditions (linearity, independence, roughly normal residuals, equal spread) via the residual plot.
Interpret the interval and test in context, tied to the true slope.