跳到主要内容

定量数据的推断:斜率

AP 统计学 · 知识点 9

本主题的视频课程 打开视频页面
7:59

定量数据的推断:斜率

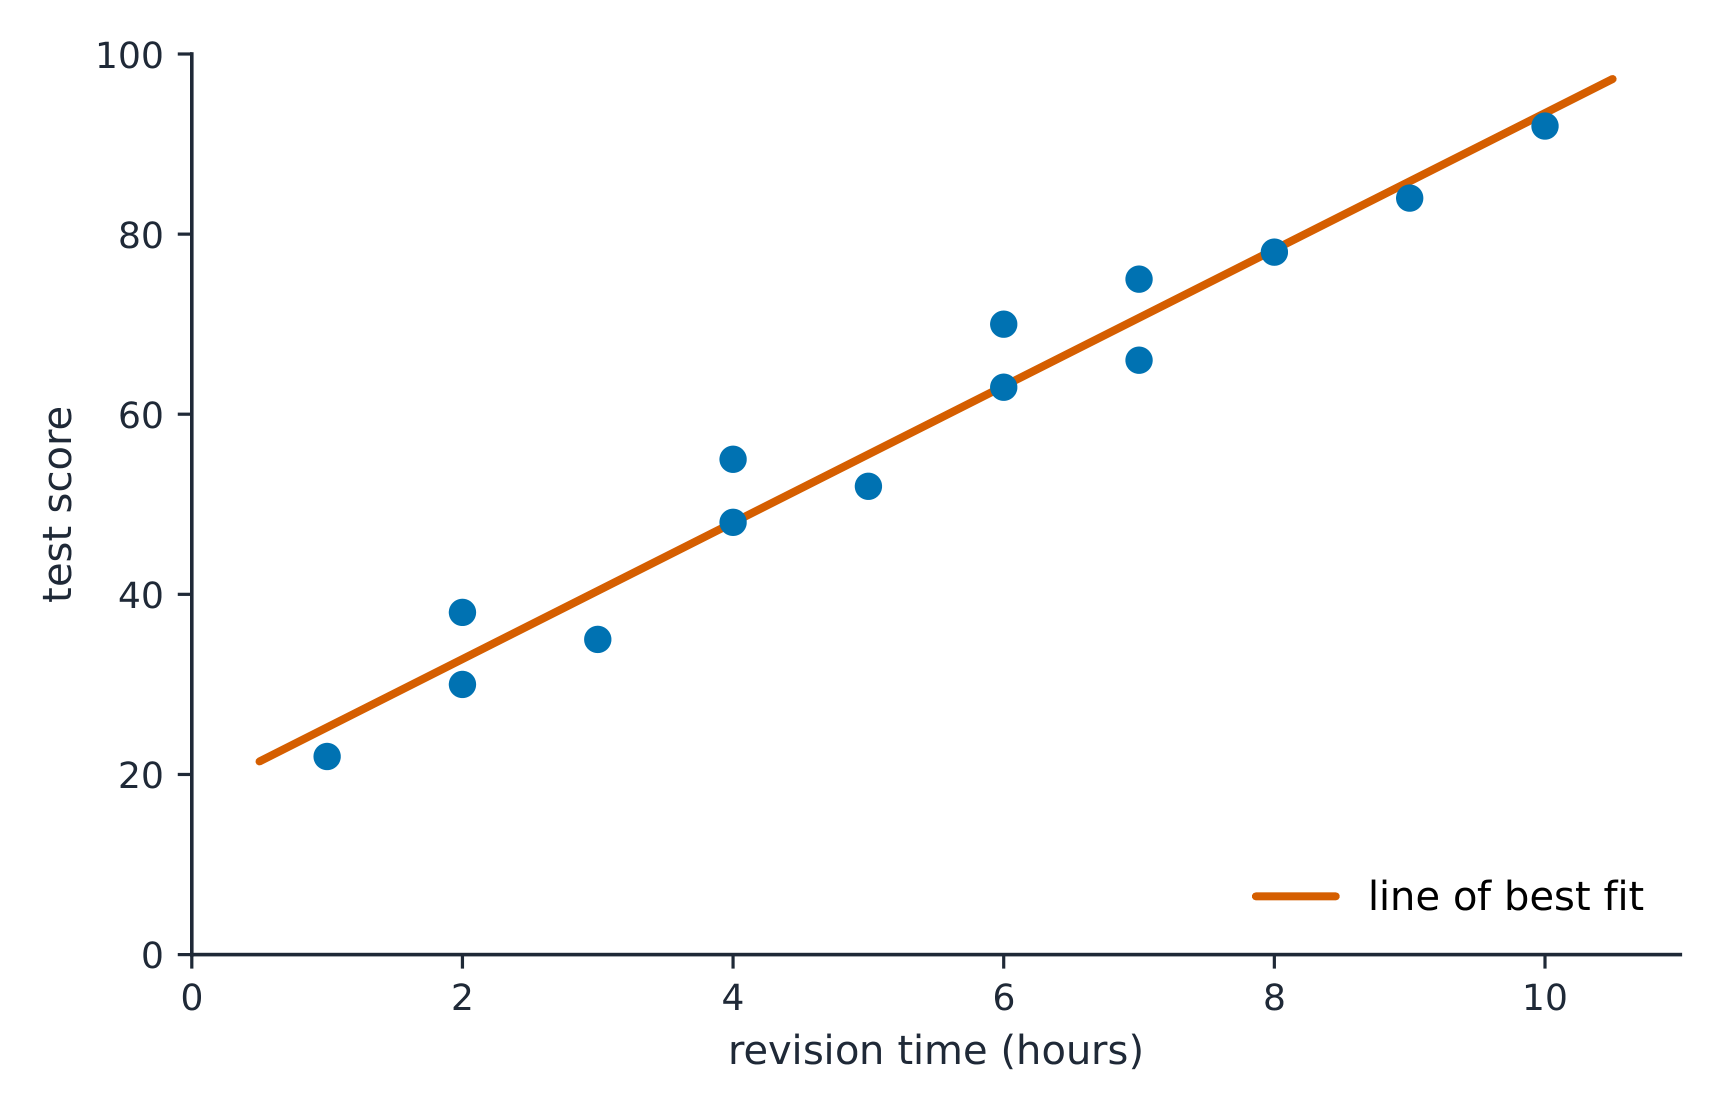
这是散点图上的一个班级:底部为复习小时数,侧面为考试分数。最佳拟合线呈上升趋势。但这只是一个班级。取一个…

英语旁白 · 英中内嵌字幕

9.1

统计学导论:这些点在一条线上吗?

教学大纲

持久理解(VAR-1): 鉴于变异可能是随机的或非随机的,结论具有不确定性。

学习目标 VAR-1.K: 识别散点图中变异所暗示的问题。[技能 1.A]

  • VAR-1.K.1 数据点相对于理论直线的分布变异可能是随机的,也可能是非随机的。

来源:College Board AP 课程与考试说明

English

Students who revise longer tend to score higher, on average, in one class's data. But a class is one sample. Would another class show the same upward slope, or could the trend be an accident of who happened to be in this one? Inference for a slope answers that, and it starts from the computer output you will be handed in the exam.

A sample scatterplot 散点图 gives a sample slope 样本斜率 $b$ for the least-squares regression line 最小二乘回归线 – but a different sample would give a slightly different slope. So $b$ is a statistic with sampling variability 抽样变异性, estimating the true (population) slope 总体斜率 $\beta$. This unit does inference 推断 for $\beta$: is there a real linear 线性 relationship, and how strong is it?

探索

拟合斜率随样本变动

每个样本的最小二乘线都有略微不同的斜率 b。

词汇 训练
English 中文 拼音
scatterplot/ˈskætəplɒt/ 散点图 sàn diǎn tú
sample slope/ˈsæmpl sləʊp/ 样本斜率 yàng běn xié lǜ
least-squares regression line/liːst skweəz rɪˈɡreʃn laɪn/ 最小二乘回归线 zuì xiǎo èr chéng huí guī xiàn
sampling variability/ˈsæmplɪŋ ˌveərɪəˈbɪlɪti/ 抽样变异性 chōu yàng biàn yì xìng
true (population) slope/truː sləʊp/ 总体斜率 zǒng tǐ xié lǜ
inference/ˈɪnfərəns/ 推断 tuī duàn
linear/ˈlɪnɪə/ 线性 xiàn xìng
9.2

回归模型斜率的置信区间

教学大纲

持久性理解 (UNC-4): 应使用数值区间来估计参数,以考虑不确定性。

学习目标 UNC-4.AC: 识别适用于回归模型斜率的适当置信区间程序。[技能 1.D]

  • UNC-4.AC.1 考虑一个响应变量 $y$,它与解释变量 $x$ 呈线性关系。对于包含 $n$ 个观测值的简单随机样本,样本回归线 $\hat{y} = a + bx$ 是总体回归线 $\mu_y = \alpha + \beta x$ 的估计值。对于特定观测值 $(x_i, y_i)$,来自样本回归线的残差 $y_i - \hat{y}_i = y_i - (a + bx_i)$ 是 $y_i - (\alpha + \beta x_i)$ 的估计值,即响应变量偏离总体回归线的偏差。对于总体中的所有点 $(x, y)$,所有响应变量偏离总体回归线的偏差的标准差 $\sigma$,可以通过样本回归线残差的标准差 $s = \sqrt{\dfrac{\sum\left(y_i - \hat{y}_i\right)^2}{n-2}}$ 来估计。(注:此公式分母使用 $n-2$ 而不是 $n-1$,因为需要从最小二乘回归线获得预测值,必须估计两个参数 $\alpha$ 和 $\beta$。)
  • UNC-4.AC.2 对于包含 $n$ 个观测值的简单随机样本,令 $b$ 表示样本回归线的斜率。那么 $b$ 的抽样分布均值等于总体斜率:$\mu_b = \beta$。$b$ 的抽样分布标准差为 $\sigma_b = \dfrac{\sigma}{\sigma_x \sqrt{n}}$,其中 $\sigma_x = \sqrt{\dfrac{\sum\left(x_i - \bar{x}\right)^2}{n}}$。
  • UNC-4.AC.3 回归模型斜率的适当置信区间是斜率的 $t$ 区间。

学习目标 UNC-4.AD: 验证计算回归模型斜率置信区间的条件。[技能 4.C]

  • UNC-4.AD.1 为了计算用于估计回归线斜率的置信区间,我们必须检查以下条件:
    • a. $x$ 与 $y$ 之间的真实关系是线性的。可以使用残差分析来验证线性。
    • b. $y$ 的标准差 $\sigma_y$ 不随 $x$ 变化。可以使用残差分析来检查所有 $x$ 的近似相等的标准差。
    • c. 为了检查独立性:
      • i. 数据应通过随机样本或随机化实验收集。
      • ii. 当无放回抽样时,检查 $n \le 10\% N$。
    • d. 对于 $x$ 的特定值,响应($y$ 值)大致服从正态分布。可以使用残差的图形表示来分析来检查正态性。
      • i. 如果观察到的分布偏斜,$n$ 应大于 30。

学习目标 UNC-4.AE: 确定给定回归模型斜率的误差范围。[技能 3.D]

  • UNC-4.AE.1 对于回归线的斜率,误差范围是临界值 $\left(t^*\right)$ 乘以斜率的标准误 ($SE$)。
  • UNC-4.AE.2 具有样本标准差 $s$ 的回归线斜率的标准误为 $SE = \dfrac{s}{s_x \sqrt{n-1}}$,其中 $s$ 是 $\sigma$ 的估计值,且 $s_x$ 是 $x$ 值的样本标准差。

学习目标 UNC-4.AF: 计算回归模型斜率的适当置信区间。[技能 3.D]

  • UNC-4.AF.1 回归模型斜率的点估计是最小二乘法拟合线(最佳拟合线)的斜率 $b$。
  • UNC-4.AF.2 对于回归模型的斜率,区间估计为 $b \pm t^* \left(SE_b\right)$。

来源:College Board AP 课程与考试说明

English

A $t$ interval for the true slope $\beta$:

$$b\pm t^{*}\,SE_b,\qquad df=n-2,$$
where $b$ is the sample slope and $SE_b$ its standard error 标准误 (read from computer output). Conditions 条件 (LINER): the true relationship is Linear, observations Independent, residuals 残差 Normal, and residuals have Equal spread (check the residual plot and a histogram 直方图 of residuals), from Random data. Interpret the interval for $\beta$ in context 结合情境, with units of $y$ per unit of $x$.

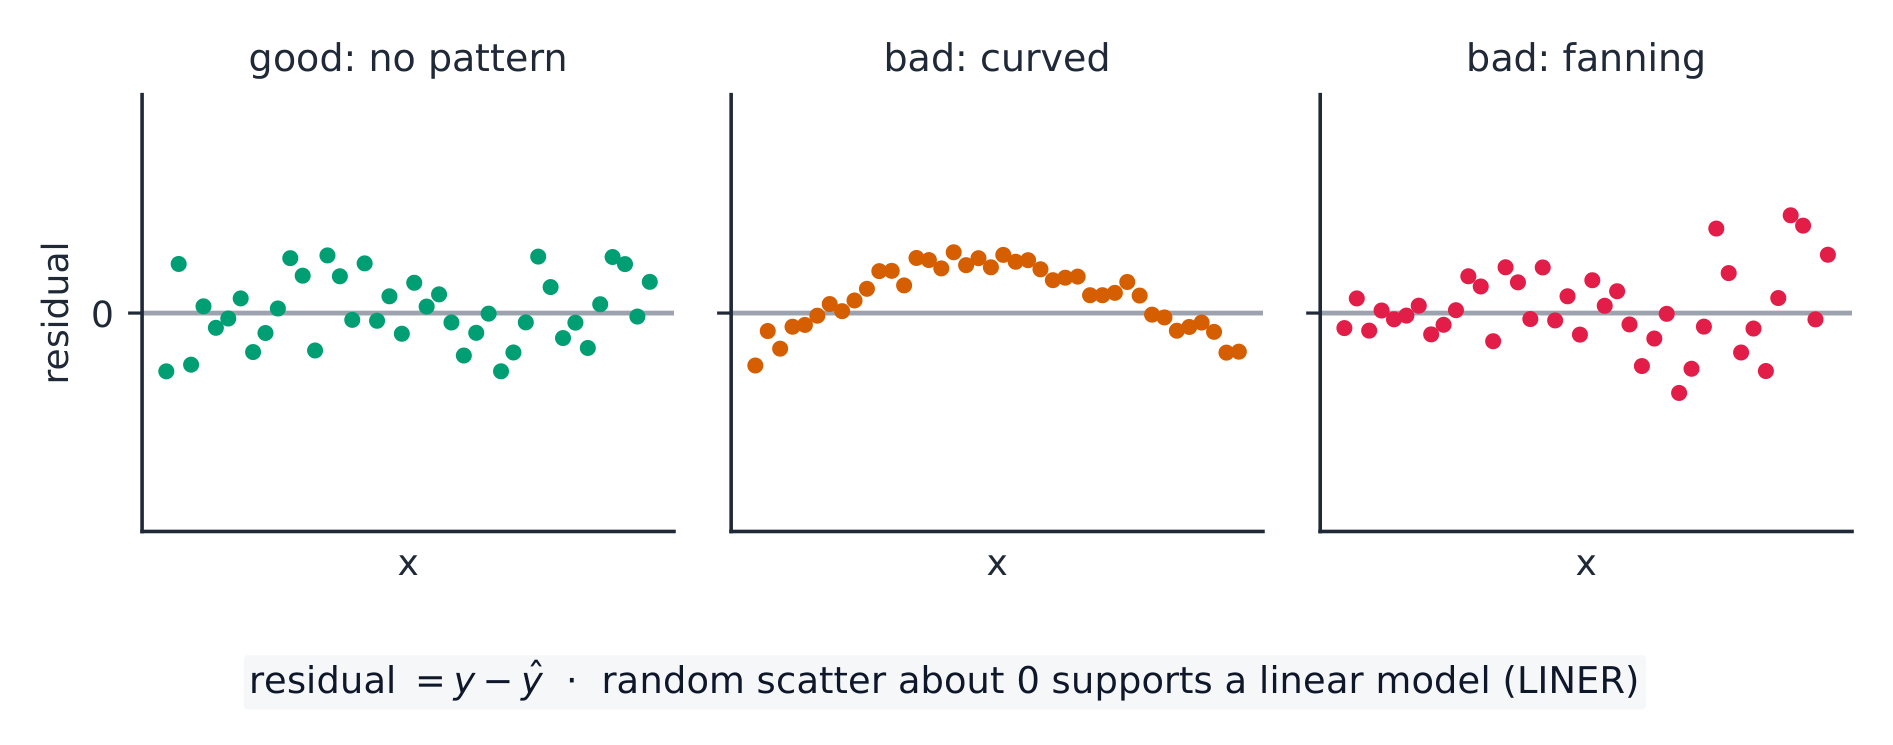
A random, patternless residual plot supports the conditions; a curve or a fan does not

The residual plot 残差图 is where you check Linear and Equal-spread: you want a formless cloud around zero. A curve 曲线 means the relationship is not linear; a fan 扇形 (spread growing with $x$) means the residuals do not have equal spread – both break a condition.

Worked example. Regression output gives slope $b=2.5$ with $SE_b=0.8$ from $n=20$ points. For a $95\%$ interval, $df=18$ gives $t^*=2.101$:
$$2.5\pm2.101(0.8)=2.5\pm1.68=(0.82,\ 4.18).$$
Because $0$ is not in the interval, there is evidence of a positive linear relationship.

Slope inference is based on the least-squares regression line through the points
Least-squares regression: the line that minimises the sum of squared residuals
A confidence interval gives the plausible values of the population slope
探索

回归斜率的推断

样本斜率因样本而异;置信区间和 t 检验询问真实斜率是否可能为零(无线性关系)。

词汇 训练
English 中文 拼音
standard error/ˈstændəd ˈerə/ 标准误 biāo zhǔn wù
Conditions/kənˈdɪʃnz/ 条件 tiáo jiàn
residuals/rɪˈsɪdʒuːəlz/ 残差 cán chà
histogram/ˈhɪstəɡræm/ 直方图 zhí fāng tú
in context 结合情境 jié hé qíng jìng
residual plot/rɪˈsɪdʒuːəl plɒt/ 残差图 cán chà tú
curve 曲线 qū xiàn
fan 扇形 shàn xíng
9.3

基于置信区间论证关于回归模型斜率的结论

教学大纲

持久理解 (UNC-4): 应使用数值区间来估计参数,以考虑不确定性。

学习目标 UNC-4.AG: 解释回归模型斜率的置信区间。[技能 4.B]

  • UNC-4.AG.1 在重复随机抽样且样本量相同的情况下,大约 C% 的置信区间将包含回归模型的斜率,即总体回归模型的真实斜率。
  • UNC-4.AG.2 对回归线斜率置信区间的解释应包括对所抽取样本的引用以及关于其所代表总体的详细信息。

学习目标 UNC-4.AH: 基于回归模型斜率的置信区间论证断言。[技能 4.D]

  • UNC-4.AH.1 回归模型斜率的置信区间提供了一个数值范围,该范围可能为支持特定情境下的断言提供充分证据。

学习目标 UNC-4.AI: 识别样本大小对回归模型斜率置信区间宽度的影响。[技能 4.A]

  • UNC-4.AI.1 当其他条件保持不变时,随着样本量的增加,回归模型斜率的置信区间的宽度往往会减小。

来源:College Board AP 课程与考试说明

English

If the confidence interval 置信区间 for $\beta$ contains $0$, a slope of zero is plausible 可信 – no evidence of a linear relationship. If the interval is entirely positive or negative, there is evidence of a real (positive or negative) linear relationship. State the direction in context.

If 0 is outside the interval for β there is convincing evidence of a linear relationship
探索

斜率与零不同吗?

斜率为 0(平线)意味着没有线性关系。

词汇 训练
English 中文 拼音
confidence interval/ˈkɒnfɪdəns ˈɪntəvl/ 置信区间 zhì xìn qū jiān
plausible/ˈplɔːzɪbl/ 可信 kě xìn
9.4

建立回归模型斜率的检验

教学大纲

持久性理解 (VAR-7): $t$分布可用于模拟变异。

学习目标 VAR-7.J: 识别用于回归模型斜率检验的适当方法选择。[技能 1.E]

  • VAR-7.J.1 回归模型斜率的适当检验是斜率的 $t$检验。

学习目标 VAR-7.K: 为回归模型斜率识别适当的零假设和备择假设。[技能 1.F]

  • VAR-7.K.1 斜率 $t$检验的零假设为:$H_0 : \beta = \beta_0$,其中 $\beta_0$ 是零假设中的假设值。备择假设为 $H_0 : \beta < \beta_0$ 或 $H_0 : \beta > \beta_0$,或 $H_0 : \beta \neq \beta_0$。

学习目标 VAR-7.L: 验证回归模型斜率显著性检验的条件。[技能 4.C]

  • VAR-7.L.1 为了在检验回归模型斜率时进行统计推断,我们必须检查以下内容:
    • a. $x$ 与 $y$ 之间的真实关系是线性的。残差分析可用于验证线性。
    • b. $y$、$\sigma_y$ 的标准差不随 $x$ 变化。残差分析可用于检查所有 $x$ 的大致相等的标准差。
    • c. 为了检查独立性:
      • i. 数据应通过随机样本或随机实验收集。
      • ii. 在不放回抽样时,检查 $n \le 10\% N$。
    • d. 对于 $x$ 的特定值,响应($y$ 值)大致呈正态分布。残差的图形表示分析可用于检查正态性。
      • i. 如果观察到的分布偏斜,$n$ 应大于 30。
      • ii. 如果样本量小于 30,样本数据的分布应无强偏度和异常值。

来源:College Board AP 课程与考试说明

English

The usual test asks whether there is any linear relationship:

$$H_0:\beta=0 \quad(\text{no linear relationship})\qquad H_a:\beta\neq 0 \ (\text{or } <,\,>).$$
Check the LINER conditions. This is a $t$-test on the slope.

9.5

执行回归模型斜率的检验

教学大纲

持久理解 (VAR-7): $t$-分布可用于模拟变异。

学习目标 VAR-7.M: 计算回归模型斜率的适当检验统计量。[技能 3.E]

  • VAR-7.M.1 在满足所有条件且原假设为真的前提下,回归模型斜率的分布(零分布)为 $t$-分布。
  • VAR-7.M.2 对于简单线性回归,当从响应变量的总体中随机抽样,且解释变量每个取值对应的响应变量均可建模为正态分布时,检验统计量 $t = \dfrac{b - \beta}{SE_b}$ 的抽样分布服从自由度为 $n - 2$ 的 $t$-分布。在对仅含一个参数(即斜率)的简单线性回归模型进行斜率检验时,该斜率检验的自由度为 $df = n - 1$。

持久理解 (DAT-3): 显著性检验使我们能够在特定背景下对假设做出决策。

学习目标 DAT-3.M: 解释回归模型斜率显著性检验的 $p$-值。[技能 4.B]

  • DAT-3.M.1 对回归模型斜率显著性检验的 $p$-值的解释应认识到:$p$-值是在假设原假设为真的前提下计算得出的,即假设真实的总体斜率等于原假设中指定的特定值。

学习目标 DAT-3.N: 基于回归模型斜率显著性检验的结果,论证关于总体的主张。[技能 4.E]

  • DAT-3.N.1 正式决策需明确将 $p$-值与显著性水平 $\alpha$ 进行比较。若 $p$-值 $\le \alpha$,则拒绝原假设 $H_0 : \beta = \beta_0$;若 $p$-值 $> \alpha$,则不拒绝原假设。
  • DAT-3.N.2 回归模型斜率显著性检验的结果可作为统计推理依据,以支持针对该样本的研究问题的答案。

来源:College Board AP 课程与考试说明

English

The slope $t$ statistic:

$$t=\frac{b-0}{SE_b},\qquad df=n-2.$$
Both $b$ and $SE_b$ come straight from the regression 回归 output. Find the $p$-value P值 from the $t$-distribution, compare to $\alpha$, and conclude in context – evidence (or not) of a linear relationship between the two variables.

Watch the tails. Regression output always prints the two-tailed $p$-value (for $H_a:\beta\neq 0$). If your $H_a$ is one-tailed, halve it – and first check the sample slope really points the way $H_a$ claims; if it points the other way, the one-tailed $p$-value is above $0.5$ and you cannot reject $H_0$.

Worked example. For the same output ($b=2.5$, $SE_b=0.8$, $n=20$), test $H_0:\beta=0$:

$$t=\frac{2.5-0}{0.8}=3.13,\qquad df=18,$$
a small $p$-value ($<0.01$), so reject $H_0$ – convincing evidence 有力证据 of a linear relationship. This matches the interval, which excluded $0$.

The t statistic for the slope and its two-sided p-value
词汇 训练
English 中文 拼音
regression/rɪˈɡreʃn/ 回归 huí guī
p-value/piː ˈvæljuː/ P值 P zhí
convincing evidence 有力证据 yǒu lì zhèng jù
9.5

Reading regression output

English

Free-response questions print output like this, from a random sample of 24 students, with $x$ = hours of revision and $y$ = test score:

Predictor Coef SE Coef T P
Constant 48.2 4.10 11.76 0.000
Hours 3.05 0.92 3.32 0.003

$S=6.84$ and $R\text{-}Sq=33.3\%$.

  • The line: predicted score $=48.2+3.05\,(\text{hours})$. The slope row, labelled with the $x$ variable, is the one that matters for inference.
  • The interval: $df=24-2=22$ and $t^*=2.074$, so $3.05\pm2.074(0.92)=3.05\pm1.91$, giving $(1.14,\ 4.96)$. We are $95\%$ confident that, for each extra hour of revision, the predicted score rises by between $1.1$ and $5.0$ points, on average, for students like these.
  • The test: $t=3.05/0.92=3.32$ and the printed $p=0.003$ (two-sided 双侧). That is convincing evidence of a linear relationship between revision hours and score.
  • $S$ is the typical size of a residual: predictions miss by about $6.8$ points. $R^2$: $33.3\%$ of the variation in scores is explained by the linear relationship with hours. The rest comes from everything else.

This was an observational 观察性的 sample, not an experiment 实验. The evidence shows an association 关联, not that revising causes higher scores: more motivated students might both revise longer and score higher.

Common mistakes. Reading the Constant row instead of the slope row; using $df=n-1$ instead of $n-2$; taking $S=6.84$ as the standard error of the slope (that is $SE_b=0.92$, in the SE Coef column); writing hypotheses about $b$ (the sample slope) instead of $\beta$; and halving the printed $p$-value when $H_a$ is two-sided.

词汇 训练
English 中文 拼音
two-sided 双侧 shuāng cè
observational 观察性的 guān chá xìng de
experiment/ekˈsperɪmənt/ 实验 shí yàn
association/əˌsəʊsɪˈeɪʃn/ 关联 guān lián
9.6

技能聚焦:选择合适的推断方法

教学大纲

本主题旨在帮助学生掌握选择合适推断程序的技能,此时学生已具备多种选项。应为学生提供练习机会,使其能够熟练运用所有与推断相关的学习目标,明确在何种情境下及如何应用这些方法。

来源:College Board AP 课程与考试说明

English

Across all of inference, identify: what is estimated or claimed (a proportion, a mean, a difference, a distribution of counts, or a slope), how many samples, and which design (independent or paired 配对; sample or experiment). Then name the procedure 检验方法, verify its conditions, carry it out, and communicate the conclusion with the statistic, the $p$-value or interval, and a plain-language answer in context. This selecting-and-communicating skill is what the investigative-task question rewards most.

Choosing any inference procedure: type of data, number of groups, then estimate or test
词汇 训练
English 中文 拼音
paired/peəd/ 配对 pèi duì
procedure/prəˈsiːdʒə/ 检验方法 jiǎn yàn fāng fǎ
9.6

Practice

English

Answer each before reading the answers below. Use the output in "Reading regression output".

  1. Write the equation of the least-squares line in context.
  2. Predict the score of a student who revises for 6 hours.
  3. Another sample of 15 points gives slope $b=-1.8$ with $SE_b=0.6$. Find the test statistic 检验统计量 and degrees of freedom 自由度 for $H_0:\beta=0$.
  4. A residual plot shows a clear U-shaped curve. Which condition fails, and what does that mean for inference?
  5. A student concludes from $p=0.003$: “Revising longer causes higher test scores.” Correct the student.
词汇 训练
English 中文 拼音
test statistic/test stəˈtɪstɪk/ 检验统计量 jiǎn yàn tǒng jì liàng
degrees of freedom/dɪˈɡriːz ɒv ˈfriːdəm/ 自由度 zì yóu dù
9.6

答案

English
  1. Predicted score $=48.2+3.05\,(\text{hours of revision})$.
  2. $48.2+3.05(6)=66.5$ points.
  3. $t=\dfrac{-1.8-0}{0.6}=-3.0$, with $df=15-2=13$.
  4. The Linear condition fails: the true relationship is curved, so a slope interval or test for a straight line is not valid. A transformation or a different model is needed first.
  5. The students were sampled, not randomly assigned to revise for different times, so this is observational data. The small $p$-value is convincing evidence of an association only. A confounding variable such as motivation could explain both.
9.6

考试技巧

English
  • Inference for a slope tests whether the true slope is $0$ (no linear relationship).
  • If a slope's confidence interval includes 0, you cannot conclude a real linear relationship – the variables may still be related in a curved way.
  • Read the slope, standard error, t-statistic, and p-value from the regression output. For a one-sided alternative, halve the usual two-sided p-value only when the observed slope points in the alternative's direction; otherwise use one minus half that p-value.
  • Check the regression conditions (linearity, independence, roughly normal residuals, equal spread) via the residual plot.
  • Interpret the interval and test in context, tied to the true slope.

该知识点的互动课程

逐步完成,配合即时检查练习。

历年真题

更多 AP 统计学 知识点

登录或创建账户

IGCSE, A-Level & AP