English
This handout covers Topic 6: Probability & Statistics 概率统计 2. It adds the Poisson model, combining random variables, continuous distributions, and the ideas of estimation and testing.
A-Level 数学 · 知识点 6
 10:06
概率与统计2
剑桥,一九二十年代。在一次花园派对上,一位女士说了些惊人的话。她声称能尝出牛奶是先倒进杯子里还是先倒进茶壶里……
英语旁白 · 英中内嵌字幕
This handout covers Topic 6: Probability & Statistics 概率统计 2. It adds the Poisson model, combining random variables, continuous distributions, and the ideas of estimation and testing.

| 考生应能: | 注释与示例 |
|---|---|
| • 使用公式计算 $\text{Po}(\lambda)$ 分布的概率 | |
| • 利用若 $X \sim \text{Po}(\lambda)$,则 $X$ 的均值和方差均等于 $\lambda$ 这一事实 | 无需证明。 |
| • 理解泊松分布与随机事件分布的相关性,并将其作为模型使用 | |
| • 在适当情况下,将泊松分布作为二项分布的近似 | 应知晓 $n$ 较大且 $p$ 较小的条件;通常约为 $n > 50$ 且 $np < 5$。 |
| • 在适当情况下,使用带连续性修正的正态分布作为泊松分布的近似。 | 应知晓 $\lambda$ 较大的条件;通常约为 $\lambda > 15$。 |
来源:Cambridge International 教学大纲
The Poisson distribution 泊松分布 $X \sim \mathrm{Po}(\lambda)$ models the number of random events in a fixed interval, when events occur independently at a steady average rate, with mean $\lambda$ in that interval:
Worked example. $X \sim \mathrm{Po}(3)$. Find $P(X = 2)$.
Worked example: changing the interval. Calls reach a help desk at random, at an average rate of $3$ per hour. Find the probability of at least $2$ calls in a $2$-hour period.
Scale the rate to the interval first: in $2$ hours the mean is $2 \times 3 = 6$, so $X \sim \mathrm{Po}(6)$. "At least 2" is easiest from the complement:
Worked example: approximating a binomial. $1.5\%$ of items from a machine are faulty. Use a suitable approximation to find the probability that a box of $200$ contains at most $1$ faulty item.
$X \sim B(200, 0.015)$, with $n$ large and $p$ small, so use $\mathrm{Po}(np) = \mathrm{Po}(3)$:
(The exact binomial value is $0.197$, so the approximation is good.)
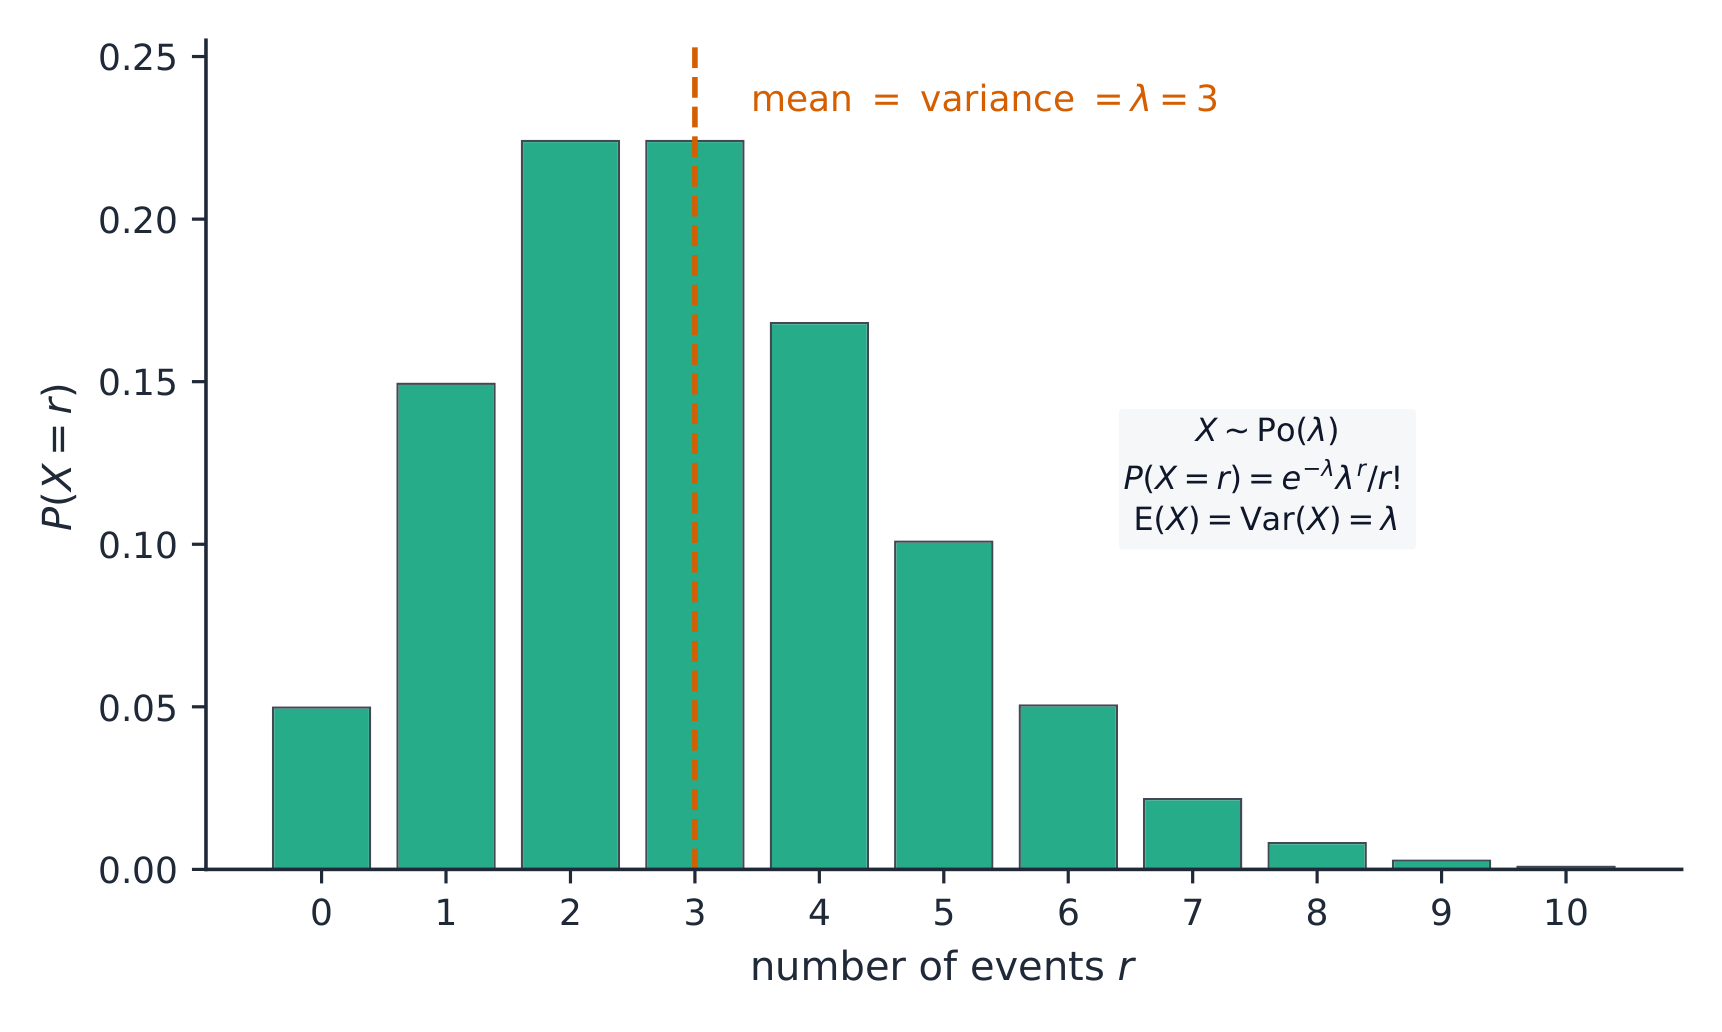
改变均值 λ。泊松分布建模固定间隔内随机事件的数量——罕见事件导致偏态分布。
| English | 中文 | 拼音 |
|---|---|---|
| Poisson distribution/ˈpɔɪsn ˌdɪstrɪˈbjuːʃn/ | 泊松分布 | pō sōng fēn bù |
| approximation/əˌprɒksɪˈmeɪʃn/ | 近似 | jìn sì |
| 考生应能: | 注释与示例 |
|---|---|
| • 在解决问题时,运用以下结果:– $\text{E}(aX + b) = a\text{E}(X) + b$ 和 $\text{Var}(aX + b) = a^2\text{Var}(X)$ – $\text{E}(aX + bY) = a\text{E}(X) + b\text{E}(Y)$ – $\text{Var}(aX + bY) = a^2\text{Var}(X) + b^2\text{Var}(Y)$(其中 $X$ 和 $Y$ 相互独立) – 若 $X$ 服从正态分布,则 $aX + b$ 也服从正态分布 – 若 $X$ 和 $Y$ 服从独立的正态分布,则 $aX + bY$ 服从正态分布 – 若 $X$ 和 $Y$ 服从独立的泊松分布,则 $X + Y$ 服从泊松分布。 | 无需证明上述结果。 |
来源:Cambridge International 教学大纲
When you change a variable by a linear rule, the expectation 期望 (mean) and variance 方差 follow these rules:
Worked example. $X$ has mean $5$ and variance $4$. Find $E(3X - 1)$ and $\mathrm{Var}(3X - 1)$.
Worked example: a difference. The time for Ann to finish a task is $X \sim N(70, 16)$ and for Ben is $Y \sim N(60, 9)$, in minutes, independently. Find the probability that Ann takes longer than Ben.
Let $D = X - Y$. Then $E(D) = 70 - 60 = 10$ and $\mathrm{Var}(D) = 16 + 9 = 25$ (the variances add, even for a difference). So $D \sim N(10, 25)$ and
Common mistake. $\mathrm{Var}(X_1 + X_2) = 2\,\mathrm{Var}(X)$ for two independent items with the same variance, but $\mathrm{Var}(2X) = 4\,\mathrm{Var}(X)$ for one item doubled. Read which one the question describes.
E(aX + b) = aE(X) + b
改变缩放因子并观察期望值如何缩放。
| English | 中文 | 拼音 |
|---|---|---|
| expectation/ekspɪkˈteɪʃn/ | 期望 | qī wàng |
| variance/ˈveərɪəns/ | 方差 | fāng chà |
| normal distribution/ˈnɔːml ˌdɪstrɪˈbjuːʃn/ | 正态分布 | zhèng tài fēn bù |
| 考生应具备的能力: | 备注与示例 |
|---|---|
| • 理解连续型随机变量的概念,并回忆及运用概率密度函数的性质 | 仅针对定义在单个区间上的密度函数;定义域可以是无限的,例如当 $x \geqslant 1$ 时,$\frac{3}{x^4}$。 |
| • 使用概率密度函数解决涉及概率的问题,并计算分布的均值和方差。 | 包括通过直接考虑密度函数下的面积来求分布的中位数或其他百分位数的位置。不要求掌握累积分布函数的具体知识。 |
来源:Cambridge International 教学大纲
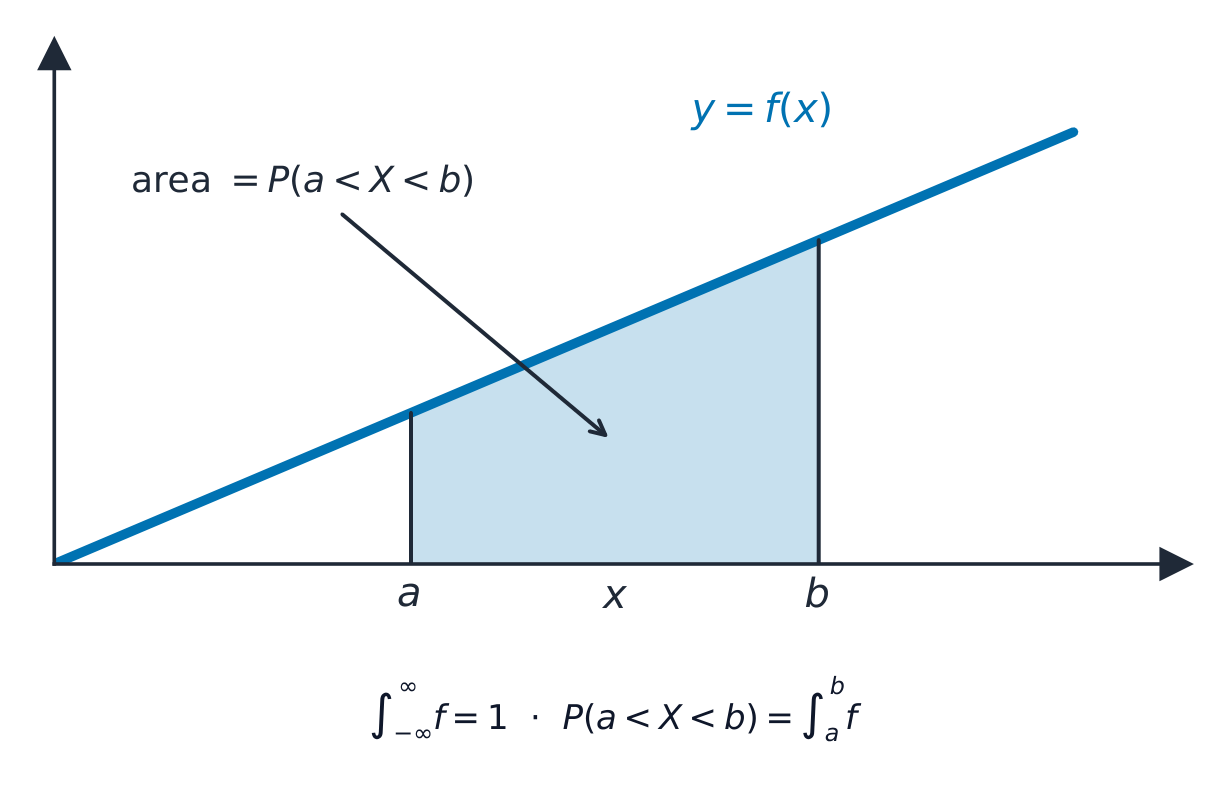
A continuous random variable 连续型随机变量 can take any value in a range. Its probabilities come from a probability density function 概率密度函数 $f(x)$, with two key properties:
The cumulative distribution function 累积分布函数 is $F(x) = P(X \leqslant x) = \int_{-\infty}^{x} f(t)\,dt$; the median 中位数 solves $F(m) = 0.5$, and other percentiles 百分位数 solve $F(x) = p$.
Worked example. A continuous variable has $f(x) = \tfrac12 x$ for $0 \leqslant x \leqslant 2$ (and $0$ elsewhere). Find $E(X)$.
The variance uses the same idea, $\mathrm{Var}(X)=\displaystyle\int_{-\infty}^{\infty}x^2 f(x)\,dx-\big(E(X)\big)^2$. For the same $f(x)=\tfrac12 x$ on $[0,2]$: $\displaystyle\int_0^2 x^2\cdot\tfrac12 x\,dx=\left[\tfrac{x^4}{8}\right]_0^2=2$, so $\mathrm{Var}(X)=2-\left(\tfrac43\right)^2=2-\tfrac{16}{9}=\tfrac{2}{9}$.
For the median of the same variable, find $F(x) = \displaystyle\int_0^x \tfrac12 t\,dt = \tfrac14 x^2$ and solve $\tfrac14 m^2 = 0.5$: $m = \sqrt2 = 1.41$. It is above the mean ($1.33$) because more of the area lies towards $x = 2$.
P(a < X < b) = ∫ f(x) dx
对一个连续变量,概率是密度曲线下两个值之间的面积。
| English | 中文 | 拼音 |
|---|---|---|
| continuous random variable/kənˈtɪnjuːəs ˈrændəm ˈveərɪəbl/ | 连续型随机变量 | lián xù xíng suí jī biàn liàng |
| probability density function/ˌprɒbəˈbɪlɪti ˈdensɪti ˈfʌŋkʃn/ | 概率密度函数 | gài lǜ mì dù hán shù |
| cumulative distribution function/ˈkjuːmjʊlətɪv ˌdɪstrɪˈbjuːʃn ˈfʌŋkʃn/ | 累积分布函数 | lěi jī fēn bù hán shù |
| median/ˈmiːdiːən/ | 中位数 | zhōng wèi shù |
| percentiles/pəˈsentaɪlz/ | 百分位数 | bǎi fēn wèi shù |

| 考生应能: | 注释与示例 |
|---|---|
| • 理解样本与总体的区别,并认识到选择样本时随机性的必要性 | |
| • 用简单的术语解释为何某种特定的抽样方法可能令人不满意 | 包括对使用随机数生成随机样本的初步理解。不要求掌握配额抽样或分层抽样等特定抽样方法的知识。 |
| • 认识到样本均值可被视为一个随机变量,并利用事实 $\text{E}(\overline{X}) = \mu$ 以及 $\text{Var}(\overline{X}) = \frac{\sigma^2}{n}$ | |
| • 利用若 $X$ 服从正态分布,则 $\overline{X}$ 也服从正态分布这一事实 | |
| • 在适当情况下使用中心极限定理 | 仅要求对中心极限定理(CLT)有非正式的理解;对于大样本量,样本均值的分布近似为正态分布。 |
| • 根据原始数据或汇总数据,计算总体的均值和方差的无偏估计值 | 仅要求对该术语“无偏”有简单理解,例如:虽然单个估计值会有所不同,但该方法在“平均”意义上能给出准确的结果。 |
| • 在总体服从正态分布且方差已知,或使用大样本的情况下,确定并解释总体均值的置信区间 | |
| • 根据大样本,确定总体比例的近似置信区间。 |
来源:Cambridge International 教学大纲
A sample 样本 is a small group chosen from the whole population 总体. A random sample needs randomness 随机性, so that every member has a fair chance of being chosen.
Some methods are unsatisfactory because they are biased 有偏: sampling only volunteers, or the first 20 people to arrive, over-represents certain kinds of people. A genuinely random sample uses random numbers – number every member of the population, then draw numbers (from a table or a generator) to decide who is in the sample.
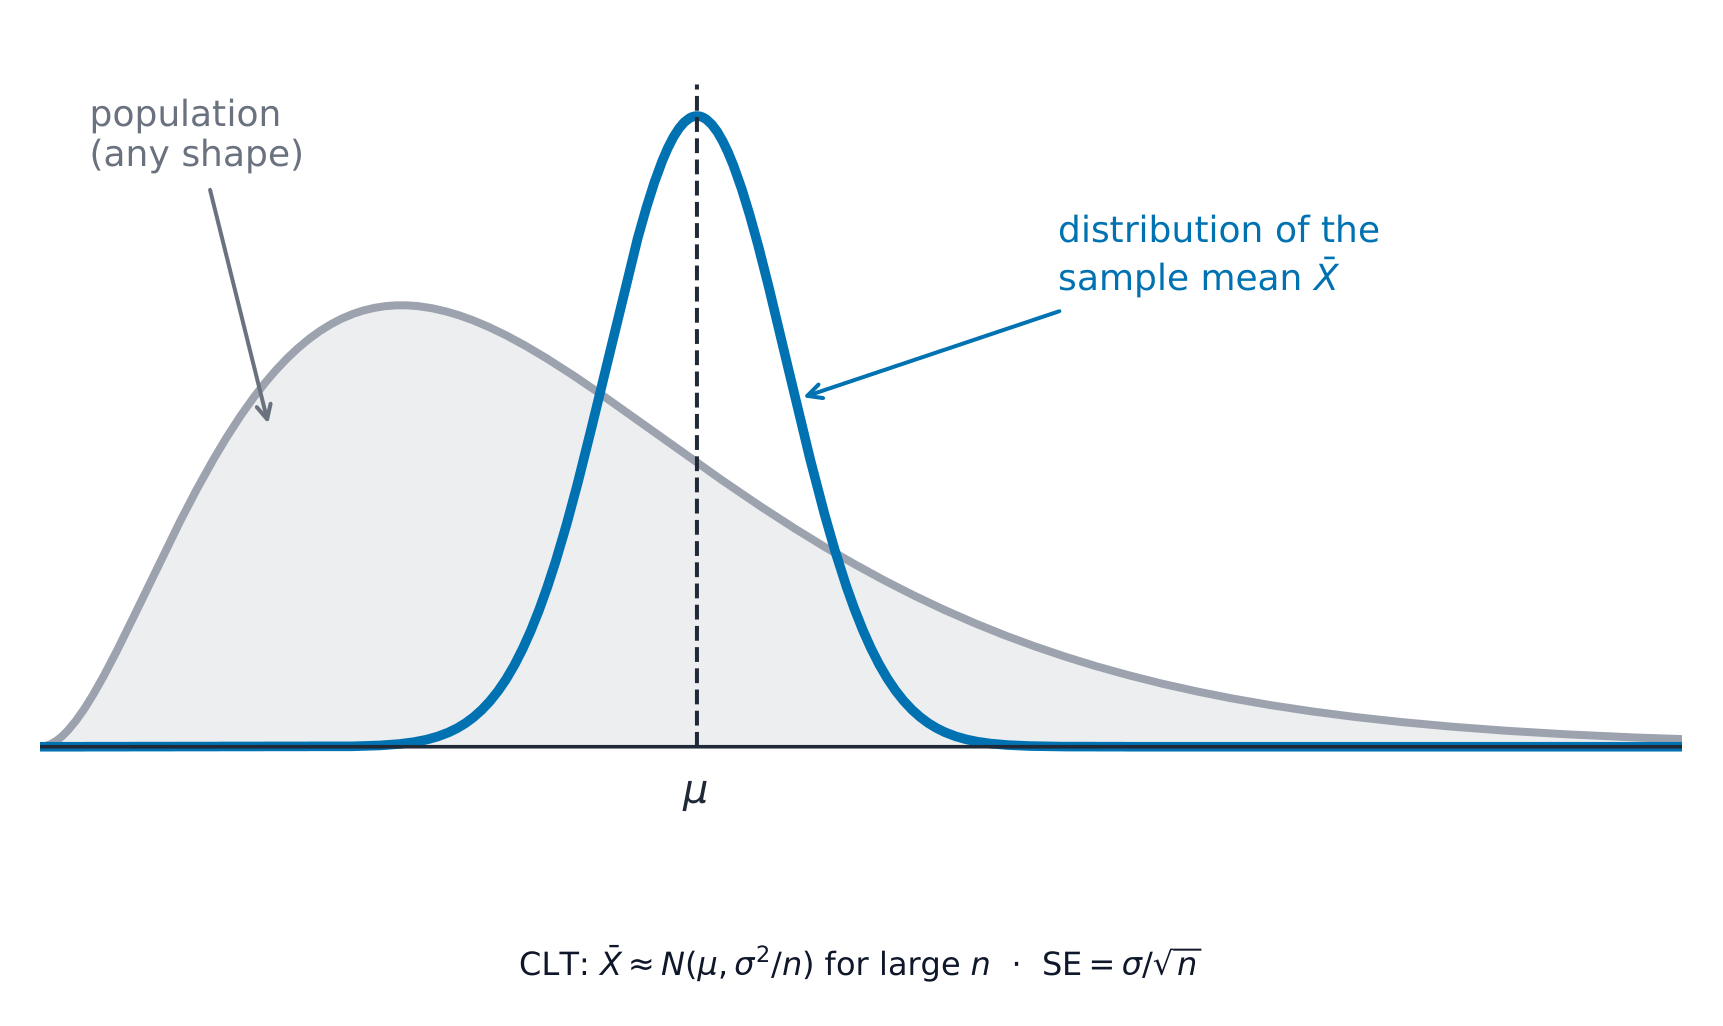
For independent observations from a population with finite mean $\mu$ and variance $\sigma^2$, the sample mean $\bar{X}$ is itself a random variable, with
From a sample you can find unbiased estimates 无偏估计 of the population mean and variance. A confidence interval 置信区间 uses a method that contains the fixed population mean in the stated fraction of repeated samples. A particular computed interval either contains that mean or does not. When the population is normal with known $\sigma$ (or the sample is large), a $95\%$ interval is

You can also find a confidence interval for a population proportion 总体比例 from a large sample.
Worked example. A sample of $n = 64$ has mean $\bar{x} = 50$, from a population with $\sigma = 8$. Find a $95\%$ confidence interval for the population mean.
When $\sigma$ is not known, estimate it from the sample. The unbiased estimate of the population variance divides by $n - 1$, not $n$:
For example, $n = 10$, $\sum x = 50$ and $\sum x^2 = 300$ give $\bar x = 5$ and $s^2 = \dfrac{300 - 250}{9} = 5.56$. Dividing by $10$ instead would give $5$, which is too small on average.
$E(\bar X)=\mu,\quad \mathrm{SD}(\bar X)=\sigma/\sqrt n$
总体保持不变,而样本均值的分布随样本量变化。这里使用示意性的独立抽样模型;增大n并不会使原始数据变为正态。
| English | 中文 | 拼音 |
|---|---|---|
| sample/ˈsæmpl/ | 样本 | yàng běn |
| population/ˌpɒpjʊˈleɪʃn/ | 总体 | zǒng tǐ |
| randomness/ˈrændəmnəs/ | 随机性 | suí jī xìng |
| biased/ˈbaɪəst/ | 有偏 | yǒu piān |
| Central Limit Theorem/ˈsentrəl ˈlɪmɪt ˈθɪərəm/ | 中心极限定理 | zhōng xīn jí xiàn dìng lǐ |
| unbiased estimates/ʌnˈbaɪəst ˈestɪməts/ | 无偏估计 | wú piān gū jì |
| confidence interval/ˈkɒnfɪdəns ˈɪntəvl/ | 置信区间 | zhì xìn qū jiān |
| population proportion/ˌpɒpjʊˈleɪʃn prəˈpɔːʃn/ | 总体比例 | zǒng tǐ bǐ lì |
| 考生应能: | 注释与示例 |
|---|---|
| • 理解假设检验的性质,区分单尾检验和双尾检验,并掌握零假设、备择假设、显著性水平、拒绝域(或临界区域)、接受域以及检验统计量等术语的含义 | 假设检验的结果预期需结合题目设定的实际背景进行解释。 |
| • 针对来自具有二项分布或泊松分布总体的单次观测值,建立假设并进行假设检验,方法包括——直接计算概率;在适用情况下,使用正态近似法对二项分布或泊松分布进行近似 | |
| • 在总体服从正态分布且方差已知,或使用大样本的情况下,就总体均值建立假设并进行假设检验 | |
| • 理解第一类错误和第二类错误在假设检验中的含义 | |
| • 在涉及基于正态分布的检验或直接评估二项/泊松概率的具体情境中,计算犯第一类错误和第二类错误的概率。 |
来源:Cambridge International 教学大纲
A hypothesis test 假设检验 uses sample data to judge a claim. You set up two statements: the null hypothesis 原假设 $H_0$ (the claim being tested, usually "no change") and the alternative hypothesis 备择假设 $H_1$ (what you suspect instead). The test is one-tailed 单尾 if $H_1$ points one way (e.g. $\mu > 50$) and two-tailed 双尾 if it allows both ways ($\mu \neq 50$).
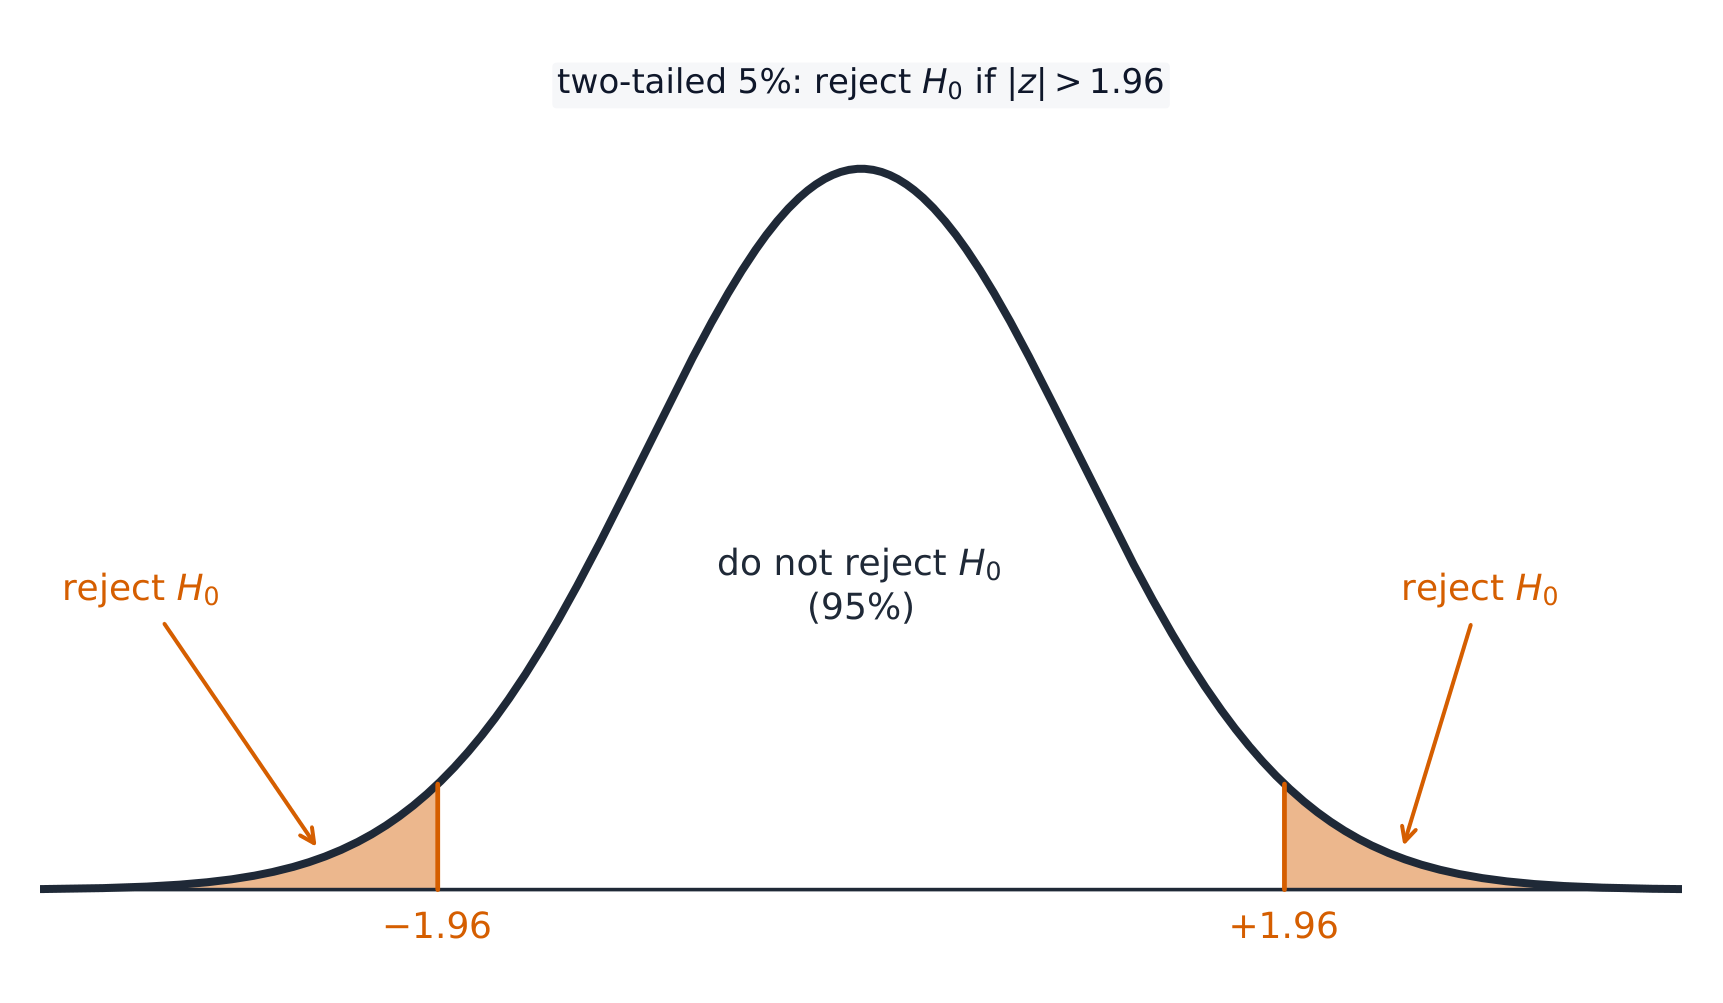
You fix a significance level 显著性水平 (often $5\%$), work out a test statistic 检验统计量 from the data, and see whether it lands in the rejection region 拒绝域 (also called the critical region); if it does you reject $H_0$, otherwise the statistic is in the acceptance region, meaning that you fail to reject $H_0$; this does not prove it true.
Two mistakes are possible: a Type I error 第一类错误 is rejecting $H_0$ when it is actually true; a Type II error 第二类错误 is failing to reject $H_0$ when it is actually false. You can find their probabilities from the rejection region: $P(\text{Type I})=P(\text{statistic in the rejection region}\mid H_0)$ – for a normal test this equals the significance level, but for a binomial or Poisson test it is the actual tail probability, which is at most the significance level – and $P(\text{Type II})=P(\text{statistic in the acceptance region}\mid H_1$ true for a stated value$)$, computed from the binomial, Poisson, or normal distribution.
Worked example. A population is claimed to have mean $50$, with $\sigma = 8$. A sample of $n = 64$ gives $\bar{x} = 52$. Test at the $5\%$ level whether the mean has changed.
$H_0\!: \mu = 50$ and $H_1\!: \mu \neq 50$ (two-tailed). The test statistic is
Worked example: a binomial test. A coin is claimed fair but suspected of landing heads too rarely: $H_0\!:p=0.5$, $H_1\!:p<0.5$. In $n=30$ tosses you see $X=9$ heads. Under $H_0$, $X\sim B(30,0.5)$, so the one-tailed tail probability is
Worked example: a Poisson test and its errors. A shop usually sells $4$ umbrellas a day on average. After an advert, the manager tests at the $5\%$ level whether sales have increased, using one day's sales $X$. Find the rejection region and the probabilities of Type I and Type II errors, given that the true mean after the advert is $7$.
$H_0\!: \lambda = 4$ and $H_1\!: \lambda > 4$. Under $H_0$, $X \sim \mathrm{Po}(4)$. Find the smallest $c$ with $P(X \geqslant c) < 0.05$:
So the rejection region is $X \geqslant 9$, and $P(\text{Type I}) = 0.0214$. A Type II error means $X \leqslant 8$ when really $X \sim \mathrm{Po}(7)$: $P(\text{Type II}) = P(X \leqslant 8 \mid \lambda = 7) = 0.729$. With only one day of data, the test misses a real rise most of the time.
reject H₀ if z < −z*
阴影的尾部是拒绝域——如果检验统计量落在那里,就拒绝 H₀。
| English | 中文 | 拼音 |
|---|---|---|
| hypothesis test/haɪˈpɒθəsɪs test/ | 假设检验 | jiǎ shè jiǎn yàn |
| null hypothesis/nʌl haɪˈpɒθəsɪs/ | 原假设 | yuán jiǎ shè |
| alternative hypothesis/ɔːlˈtɜːnətɪv haɪˈpɒθəsɪs/ | 备择假设 | bèi zé jiǎ shè |
| one-tailed/wʌn teɪld/ | 单尾 | dān wěi |
| two-tailed/tuː teɪld/ | 双尾 | shuāng wěi |
| significance level/sɪɡˈnɪfɪkəns ˈlevl/ | 显著性水平 | xiǎn zhù xìng shuǐ píng |
| test statistic/test stəˈtɪstɪk/ | 检验统计量 | jiǎn yàn tǒng jì liàng |
| rejection region/rɪˈdʒekʃn ˈriːdʒn/ | 拒绝域 | jù jué yù |
| Type I error/taɪp aɪ ˈerə/ | 第一类错误 | dì yī lèi cuò wù |
| Type II error/taɪp ˈtuː ˈerə/ | 第二类错误 | dì èr lèi cuò wù |
| Probability & Statistics/ˌprɒbəˈbɪlɪti ænd stəˈtɪstɪks/ | 概率统计 | gài lǜ tǒng jì |
逐步完成,配合即时检查练习。
正在加载学科…