- 描述核苷酸的结构,包括磷酸化的核苷酸ATP(不要求掌握结构式)
- 说明碱基腺嘌呤和鸟嘌呤是带有双环结构的嘌呤,而碱基胞嘧啶、胸腺嘧啶和尿嘧啶是带有单环结构的嘧啶(不要求掌握碱基的结构式)
- 描述DNA分子作为双螺旋的结构,包括: • 互补碱基配对在5′到3′链与3′到5′链之间的重要性(即反向平行链) • C–G碱基对与A–T碱基对之间氢键的差异 • 核苷酸通过磷酸二酯键连接
- 描述细胞周期S期期间DNA的半保留复制,包括: • DNA聚合酶和DNA连接酶的作用(不要求掌握细胞中DNA复制的其他酶及不同类型的DNA聚合酶) • 由于DNA聚合酶只能沿5′到3′方向添加核苷酸,导致前导链与后随链复制之间的差异
- 描述RNA分子的结构,以**信使RNA (mRNA)**为例
核酸与蛋白质合成
A-Level 生物 · 知识点 6
 9:37
DNA与蛋白质合成
几乎每个细胞内都藏着一根长约两米的分子,折叠得如此紧密以至于看不见。这是DNA,其书写遵循特定的…
英语旁白 · 英中内嵌字幕
6.1
核酸的结构与DNA的复制

教学大纲
来源:Cambridge International 教学大纲
English
Nucleic acids 核酸 (DNA and RNA) are polymers of small units called nucleotides 核苷酸. Each nucleotide is made of three parts joined together:
- a phosphate 磷酸 group,
- a sugar (a 5-carbon sugar),
- a nitrogen-containing base 碱基.
ATP is a special nucleotide. It has the base adenine 腺嘌呤, the sugar ribose 核糖, and three phosphate groups. Breaking off the last phosphate releases energy 能量 for the cell.

There are five bases, in two groups:
- purines 嘌呤 have a double ring (two rings): adenine and guanine 鸟嘌呤.
- pyrimidines 嘧啶 have a single ring (one ring): cytosine 胞嘧啶, thymine 胸腺嘧啶 and uracil 尿嘧啶.

词汇
训练
| English | 中文 | 拼音 |
|---|---|---|
| nucleotide/ˈnjuːklɪɒtaɪd/ | 核苷酸 | hé gān suān |
| nucleic acid/njuːˈklɪɪk ˈæsɪd/ | 核酸 | hé suān |
| phosphate/ˈfɒsfeɪt/ | 磷酸 | lín suān |
| base/beɪs/ | 碱基 | jiǎn jī |
| adenine/ˈædəniːn/ | 腺嘌呤 | xiàn piào líng |
| ribose/ˈrɪbəʊs/ | 核糖 | hé táng |
| energy/ˈenədʒi/ | 能量 | néng liàng |
| purine/ˈpjʊəriːn/ | 嘌呤 | piào líng |
| guanine/ˈɡwɑːnaɪn/ | 鸟嘌呤 | niǎo piào líng |
| pyrimidine/ˈpɪrɪmɪdiːn/ | 嘧啶 | mì dìng |
| cytosine/ˈsaɪtəsaɪn/ | 胞嘧啶 | bāo mì dìng |
| thymine/ˈθaɪmaɪn/ | 胸腺嘧啶 | xiōng xiàn mì dìng |
| uracil/ˈjʊərəsɪl/ | 尿嘧啶 | niào mì dìng |
6.1
DNA 的结构
English
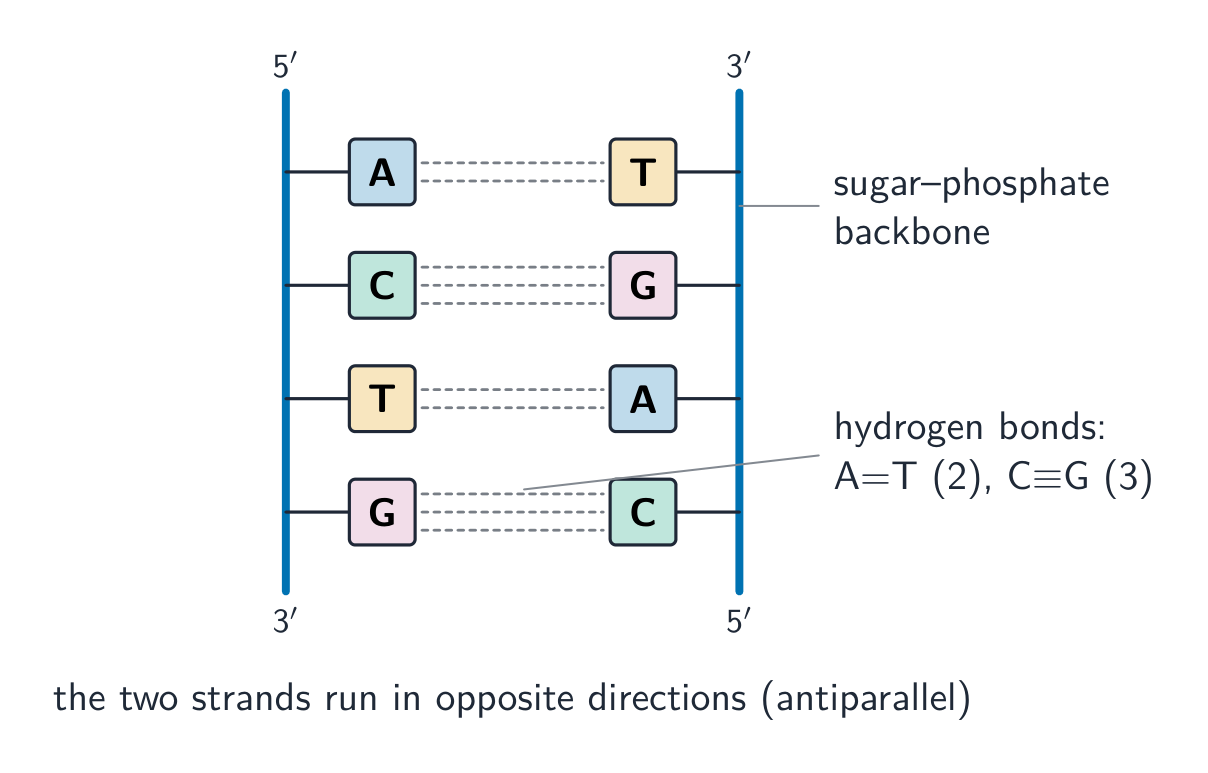
A DNA molecule is two strands twisted together into a double helix 双螺旋.
Each strand 链 has a backbone of alternating sugar (here the sugar is deoxyribose 脱氧核糖) and phosphate. The sugar of one nucleotide is joined to the phosphate of the next by a phosphodiester bond 磷酸二酯键.
The two strands are held together by their bases, which meet in the middle. The pairing is exact — this is complementary base pairing 碱基互补配对:
- A always pairs with T, held by two hydrogen bonds 氢键.
- C always pairs with G, held by three hydrogen bonds (so a C–G base pair 碱基对 is harder to separate).
The two strands run in opposite directions: one goes 5′ to 3′ while the other goes 3′ to 5′. We say they are antiparallel 反平行.
The flat ladder above is twisted into a spiral. This space-filling model, where every atom is a ball, shows the real shape of the double helix:

探索
探索 DNA 梯子
点击双螺旋的每个部分——两条反平行的骨架,互补碱基对作为梯级。
词汇
训练
| English | 中文 | 拼音 |
|---|---|---|
| double helix/ˈdʌbl ˈhiːlɪks/ | 双螺旋 | shuāng luó xuán |
| strand/strænd/ | 链 | liàn |
| deoxyribose/diːˈɒksɪrɪbəʊs/ | 脱氧核糖 | tuō yǎng hé táng |
| phosphodiester bond/ˈfɒsfəʊdɪstə bɒnd/ | 磷酸二酯键 | lín suān èr zhǐ jiàn |
| complementary base pairing/ˌkɒmplɪˈmentəri beɪs ˈpeərɪŋ/ | 碱基互补配对 | jiǎn jī hù bǔ pèi duì |
| hydrogen bond/ˈhaɪdrədʒn bɒnd/ | 氢键 | qīng jiàn |
| base pair/beɪs peə/ | 碱基对 | jiǎn jī duì |
| antiparallel/ˌæntɪˈpærəlel/ | 反平行 | fǎn píng xíng |
6.1
DNA 复制

English
DNA replication 复制 (copying) happens during the S phase of the cell cycle. It is semi-conservative 半保留复制: each new molecule keeps one old strand and one new strand. The steps are:
- the double helix unwinds and the hydrogen bonds break, so the two strands separate.
- each old strand acts as a template. Free nucleotides pair with the exposed bases by complementary base pairing.
- the enzyme 酶 DNA polymerase 聚合酶 joins the new nucleotides into a strand. It can only add nucleotides in the 5′ to 3′ direction.
Because of that 5′ to 3′ rule, the two new strands are made differently:
- the leading strand 前导链 is built continuously, following the unwinding.
- the lagging strand 后随链 is built in short pieces, working away from the unwinding point. The enzyme DNA ligase 连接酶 then joins these pieces together.
探索
半保留复制
一步步走过复制 DNA。螺旋解开,每条旧链作为模板复制一条新链,你最后得到两个相同的分子。
词汇
训练
| English | 中文 | 拼音 |
|---|---|---|
| replication/ˌreplɪˈkeɪʃn/ | 复制 | fù zhì |
| enzyme/ˈenzaɪm/ | 酶 | méi |
| polymerase/ˌpɒlɪməˈreɪz/ | 聚合酶 | jù hé méi |
| leading strand/ˈliːdɪŋ strænd/ | 前导链 | qián dǎo liàn |
| lagging strand/ˈlæɡɪŋ strænd/ | 后随链 | hòu suí liàn |
| ligase/ˈlɪɡeɪs/ | 连接酶 | lián jiē méi |
6.1
RNA

English
RNA is also made of nucleotides, but it is a single strand, its sugar is ribose, and it uses uracil in place of thymine. The most important type here is messenger RNA (mRNA), which carries a copy of a gene's instructions out of the nucleus to be used.
6.2
蛋白质合成
教学大纲
- 说明 多肽 由 基因 编码,且基因是构成 DNA 分子一部分的核苷酸序列
- 描述 通用遗传密码 的原理,即不同的 DNA 碱基 三联体 要么编码特定的氨基酸,要么对应 起始和终止密码子
- 描述在 转录 和 翻译 过程中如何利用 DNA 中的信息来构建多肽,包括以下各组分的角色: • RNA 聚合酶 • 信使 RNA (mRNA) • 密码子 • 转运 RNA (tRNA) • 反密码子 • 核糖体
- 说明 DNA 分子中用于转录的链被称为转录或 模板链,而另一条链被称为 非转录链
- 解释在真核生物中,转录后形成的 RNA 分子(初级转录产物)通过去除非编码序列 (内含子) 并连接编码序列 (外显子) 来修饰为 mRNA
- 说明 基因突变 是 DNA 分子中碱基对序列的改变,可能导致多肽发生改变
- 解释基因突变是 DNA 中核苷酸的 替换、缺失 或 插入 的结果,并概述每种类型的突变如何影响所产生的多肽
来源:Cambridge International 教学大纲
English
A gene 基因 is a sequence of DNA nucleotides that codes for one polypeptide 多肽.
The code is read in triplets 三联体 — groups of three bases. Each triplet either codes for one specific amino acid 氨基酸, or acts as a start or stop signal. The code is universal: nearly all living things use the same triplets for the same amino acids.
There are 64 possible triplets but only 20 common amino acids, so most amino acids are coded by more than one triplet.
探索
从基因到蛋白质
一步步走过中心法则:DNA 模板通过碱基配对(A→U、T→A、G→C、C→G)转录成 mRNA,然后以密码子读取并翻译成一条氨基酸链。
词汇
训练
| English | 中文 | 拼音 |
|---|---|---|
| gene/dʒiːn/ | 基因 | jī yīn |
| polypeptide/ˌpɒlɪˈpeptaɪd/ | 多肽 | duō tài |
| triplet/ˈtrɪplɪt/ | 三联体 | sān lián tǐ |
| amino acid/əˈmiːnəʊ ˈæsɪd/ | 氨基酸 | ān jī suān |
6.2
蛋白质合成:转录与翻译

English
Transcription (in the nucleus)
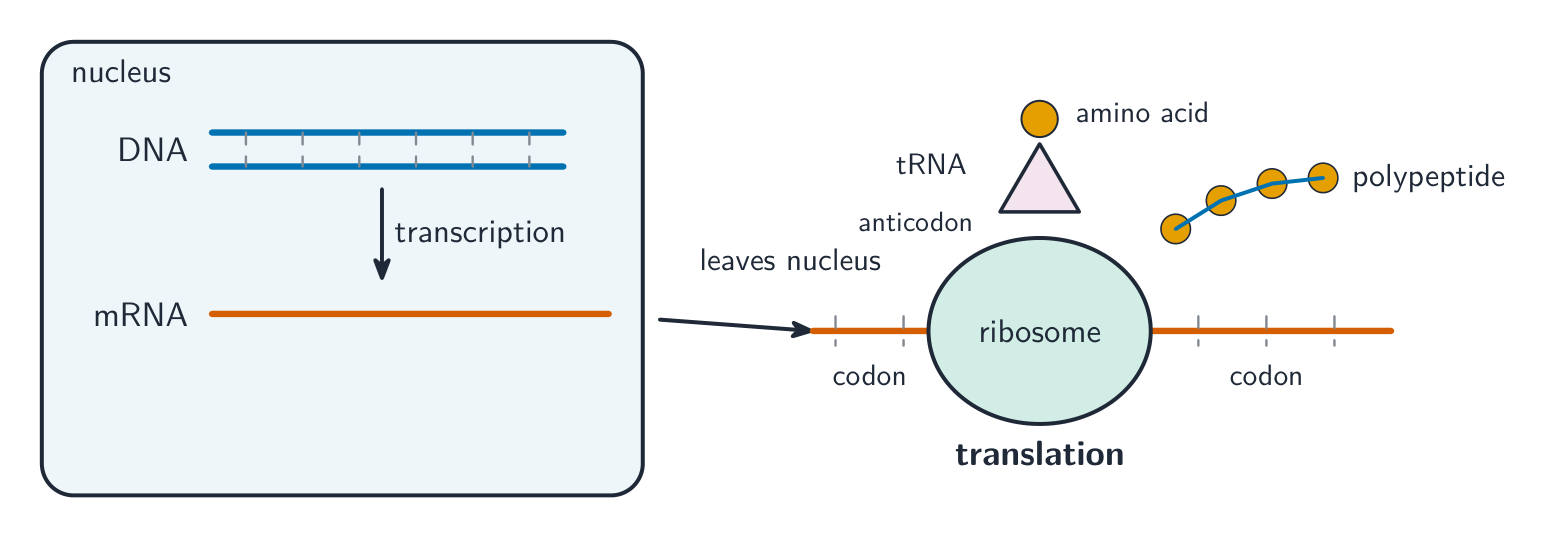
The DNA gene is copied into mRNA. This is transcription 转录.
- the strand of DNA that is copied is the template strand 模板链; the partner strand is the non-transcribed strand 非转录链.
- the enzyme RNA polymerase joins RNA nucleotides that pair with the template bases (with uracil pairing to adenine).
- in eukaryotes the first RNA made (the primary transcript 初级转录本) contains coding parts called exons 外显子 and non-coding parts called introns 内含子. The introns are cut out and the exons joined together to form the finished mRNA.
Translation (at the ribosome)
The mRNA leaves the nucleus and attaches to a ribosome 核糖体. Building the polypeptide from the mRNA code is translation 翻译.
- the mRNA is read in codons 密码子 (each codon is one triplet of mRNA bases).
- molecules of transfer RNA (tRNA) bring amino acids to the ribosome. Each tRNA has an anticodon 反密码子 that pairs with a matching codon.
- as the codons are read in order, the ribosome joins the amino acids with peptide bonds 肽键, building the polypeptide.
Worked example. A DNA template strand reads TAC GGA CTT. Give the mRNA codons, and say how many amino acids this part of the gene codes for. Transcribe by complementary base pairing, remembering that RNA uses uracil in place of thymine: TAC gives AUG, GGA gives CCU, CTT gives GAA. So the mRNA reads AUG CCU GAA. Each codon codes for one amino acid, so this part codes for three: methionine (AUG, which is also the start codon), proline (CCU) and glutamic acid (GAA). Two errors cost most of the marks here: pairing A with T instead of U when writing mRNA, and transcribing the coding strand instead of the template strand. The mRNA is complementary to the template, and identical to the coding strand apart from U replacing T.
探索
从基因到蛋白质
一步步走过中心法则:DNA 模板通过碱基配对(A→U、T→A、G→C、C→G)转录成 mRNA,然后以密码子读取并翻译成一条氨基酸链。
探索
从基因到蛋白质
逐步了解基因如何变成蛋白质。转录将 DNA 复制为 mRNA;翻译读取 mRNA 以构建多肽链。
词汇
训练
| English | 中文 | 拼音 |
|---|---|---|
| transcription/trænˈskrɪpʃn/ | 转录 | zhuǎn lù |
| template strand/ˈtempleɪt strænd/ | 模板链 | mú bǎn liàn |
| non-transcribed strand/nɒn trænˈskraɪbd strænd/ | 非转录链 | fēi zhuǎn lù liàn |
| primary transcript/ˈpraɪməri ˈtrænskrɪpt/ | 初级转录本 | chū jí zhuǎn lù běn |
| exon/eɡˈzɒn/ | 外显子 | wài xiǎn zi |
| intron/ɪnˈtrɒn/ | 内含子 | nèi hán zi |
| ribosome/ˈriːbəʊsəʊm/ | 核糖体 | hé táng tǐ |
| translation/trænˈsleɪʃn/ | 翻译 | fān yì |
| codon/ˈkəʊdɒn/ | 密码子 | mì mǎ zǐ |
| anticodon/ˌæntɪˈkəʊdɒn/ | 反密码子 | fǎn mì mǎ zǐ |
| peptide bond/ˈpeptaɪd bɒnd/ | 肽键 | tài jiàn |
6.2
基因突变

English
A gene mutation 突变 is a change in the base sequence of a DNA molecule. It may change the polypeptide made. There are three types:
- substitution 替换 — one base is swapped for a different base. This changes only one triplet: usually one amino acid changes, sometimes none (because most amino acids have more than one triplet), and if the new triplet is a stop codon the polypeptide is cut short.
- deletion 缺失 — a base is removed.
- insertion 插入 — an extra base is added.
A deletion or insertion shifts how every later triplet is read, so it usually changes many amino acids after that point and has a large effect on the polypeptide.
Common mistakes.
- Saying DNA polymerase forms the hydrogen bonds between bases. The bases pair by themselves (complementary base pairing); DNA polymerase forms the phosphodiester bonds along the new strand.
- Saying DNA ligase joins base pairs. It joins the pieces of the lagging strand, along the sugar-phosphate backbone.
- Pairing A with T when writing mRNA. In RNA, A pairs with U.
- Saying the tRNA anticodon "codes for" the amino acid. The codon on the mRNA codes; the anticodon only makes sure the right tRNA binds.
- Saying every substitution changes the protein. Because the code is degenerate 简并 (most amino acids have more than one triplet), some substitutions change no amino acid at all.
探索
突变类型实验
比较替换、插入和缺失对⟦code⟧的影响。
词汇
训练
| English | 中文 | 拼音 |
|---|---|---|
| mutation/mjuːˈteɪʃn/ | 突变 | tū biàn |
| substitution/ˌsʌbstɪˈtjuːʃn/ | 替换 | tì huàn |
| deletion/dɪˈliːʃn/ | 缺失 | quē shī |
| insertion/ɪnˈsɜːʃn/ | 插入 | chā rù |
| degenerate/dɪˈdʒenəreɪt/ | 简并 | jiǎn bìng |
| semi-conservative replication/ˈsemi kənˈsɜːvətɪv ˌreplɪˈkeɪʃn/ | 半保留复制 | bàn bǎo liú fù zhì |
6.2
考试技巧
English
- DNA is antiparallel, held by hydrogen bonds (A=T two, C≡G three); replication is semi-conservative (each product keeps one old strand).
- State where and what: transcription (nucleus → mRNA), translation (ribosome, mRNA + tRNA → polypeptide).
- Describe the code with all four terms: triplet, non-overlapping, degenerate, universal.
- For a gene mutation (substitution, insertion, deletion) explain the effect on the protein — and why a substitution can be silent (degeneracy).
该知识点的互动课程
逐步完成,配合即时检查练习。