English
This handout covers Topic 4: Further Probability & Statistics 进阶概率统计. It adds continuous distributions, small-sample inference, the chi-squared and non-parametric tests, and probability generating functions.
A-Level 进阶数学 · 知识点 4
 8:08
进阶概率与统计
都柏林,一九〇八年。在吉尼斯啤酒厂内,一位名叫威廉·戈塞特的年轻化学家面临一个非常实际的问题。他只能测试少数几批……
英语旁白 · 英中内嵌字幕
This handout covers Topic 4: Further Probability & Statistics 进阶概率统计. It adds continuous distributions, small-sample inference, the chi-squared and non-parametric tests, and probability generating functions.
| 考生应能: | 注释与示例 |
|---|---|
| 使用可能分段定义的概率密度函数 | |
| 利用一般公式 $\text{E}(g(X)) = \int f(x)g(x) \, \mathrm{d}x$,其中 $f(x)$ 是连续型随机变量 $X$ 的概率密度函数,$g(X)$ 是 $X$ 的函数 | |
| 理解并运用概率密度函数(PDF)与累积分布函数(CDF)之间的关系,并利用其中任一函数来求概率或百分位数 | |
| 在简单情形下,利用相关变量的累积分布函数(CDF)。 | 例如:已知变量 $X$ 的 CDF,求相关变量 $Y$ 的 CDF,进而求出其 PDF,例如当 $Y = X^3$ 时。 |
来源:Cambridge International 教学大纲
A continuous variable $X$ is described by a probability density function 概率密度函数 $f(x)$, which may be defined piecewise. The probability over a range is the area under $f$, and the mean of any function of $X$ is
The cumulative distribution function 累积分布函数 $F(x) = P(X \leqslant x)$ is the running total: $F(x) = \displaystyle\int_{-\infty}^{x} f(t)\,dt$, and $f(x) = F'(x)$ wherever the density is continuous. Use $F$ to find probabilities and percentiles 百分位数 (for example, the median 中位数 solves $F(x) = 0.5$).
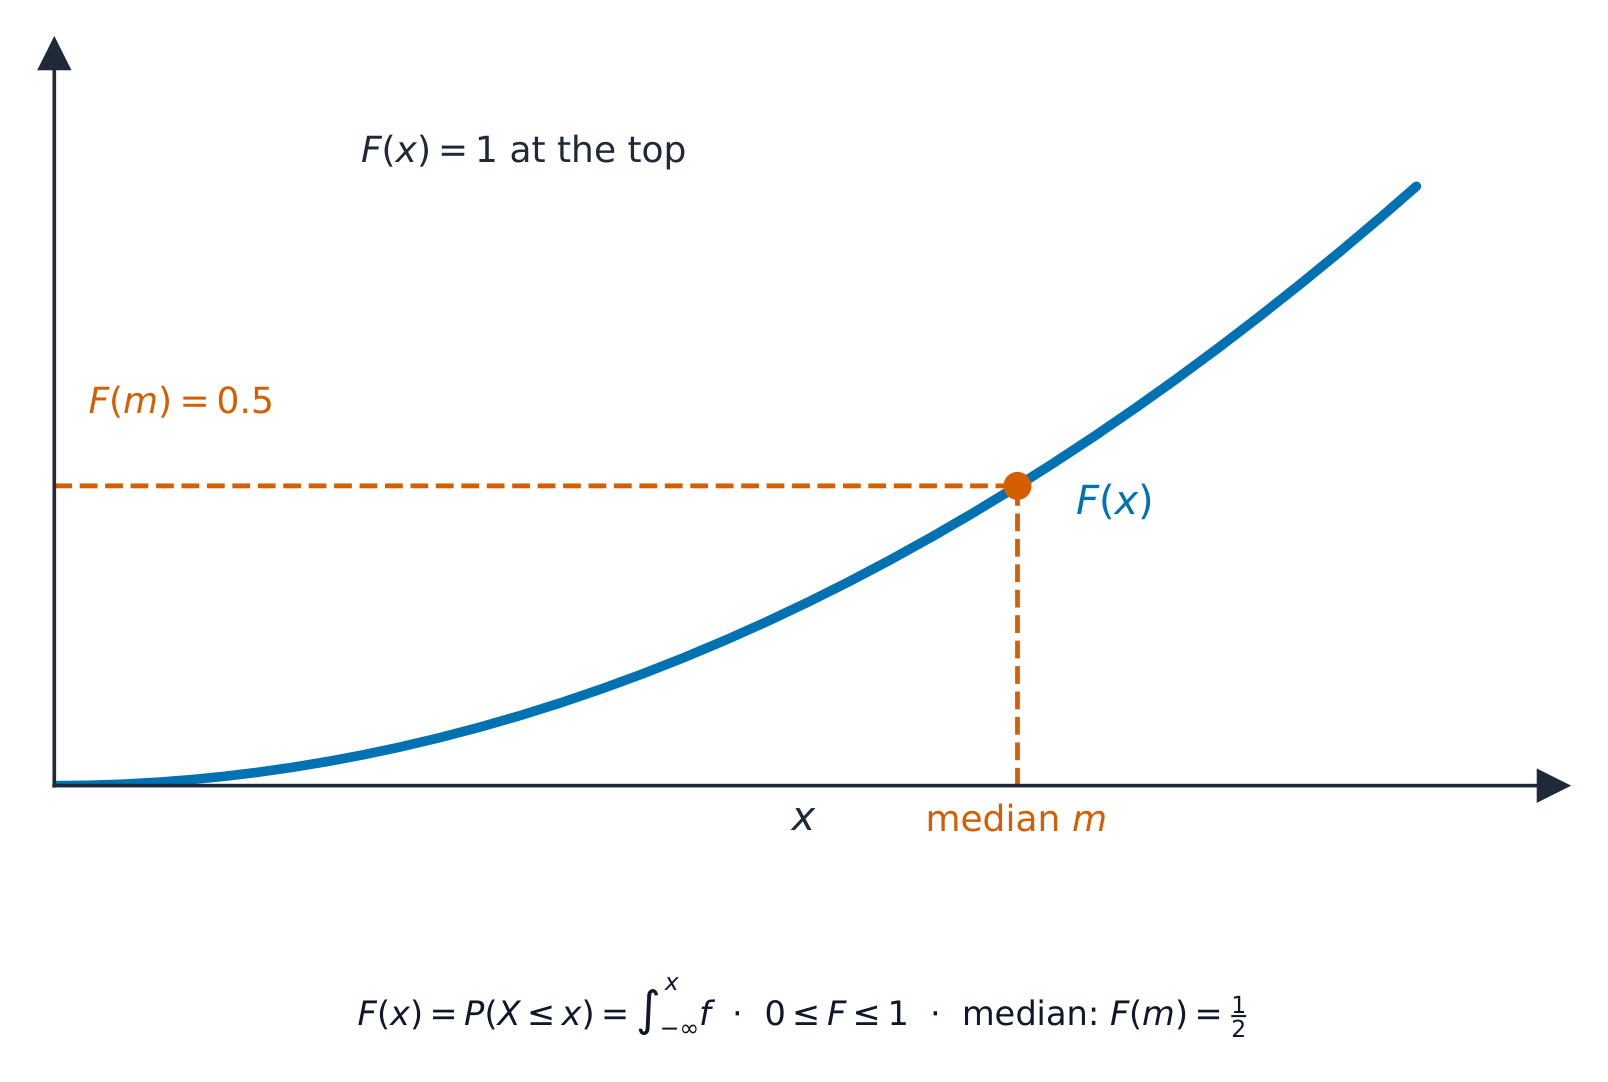
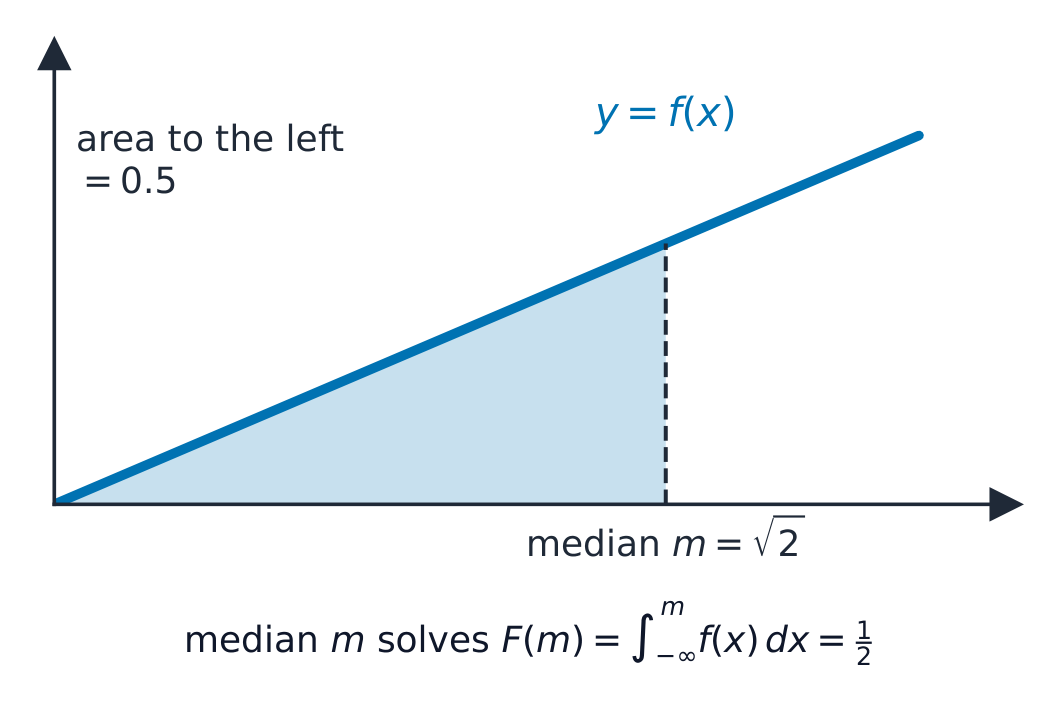
Worked example. A variable has $f(x) = \tfrac12 x$ for $0 \leqslant x \leqslant 2$. Find the median.
The cumulative distribution function is $F(x) = \displaystyle\int_0^x \tfrac12 t\,dt = \tfrac14 x^2$. Set $F(m) = 0.5$:
Worked example: mean, variance and $E(g(X))$. For the same $f(x)=\tfrac12 x$ on $[0,2]$:
The same rule handles any $g$: $E\!\left(\tfrac1X\right)=\displaystyle\int_0^2 \frac1x\cdot\tfrac12 x\,dx=\int_0^2\tfrac12\,dx=1$. Note that $E\!\left(\tfrac1X\right)=1$ is not $\dfrac{1}{E(X)}=\tfrac34$.
The distribution of a related variable. If $Y=g(X)$, find $Y$'s distribution through its cumulative function. For $Y=X^2$: $F_Y(y)=P(X^2\leqslant y)=P(-\sqrt y\leqslant X\leqslant\sqrt y)=F_X(\sqrt y)-F_X(-\sqrt y)$, then differentiate for $f_Y=F_Y'$. When $g$ is monotonic increasing there is a shortcut, $F_Y(y)=F_X\big(g^{-1}(y)\big)$.
Worked example. With $f_X(x)=\tfrac12 x$ on $[0,2]$ (so $F_X(x)=\tfrac14 x^2$), let $Y=X^2$. For $0\leqslant y\leqslant 4$, $F_Y(y)=F_X(\sqrt y)=\tfrac14 y$, so $f_Y(y)=F_Y'(y)=\tfrac14$ – that is, $Y$ is uniform on $[0,4]$.
For $Y=X^3$ (the syllabus example) the range becomes $0\leqslant y\leqslant 8$, and $F_Y(y)=F_X\big(y^{1/3}\big)=\tfrac14 y^{2/3}$, so $f_Y(y)=\tfrac16 y^{-1/3}$. Always state the new range of $Y$ first.
$f(x)=2x/b^2,\quad F(x)=x^2/b^2\ (0\le x\le b)$
把[0,2]上的上升密度与累积概率联系起来。边界确定面积,百分位数则由面积反求边界。
| English | 中文 | 拼音 |
|---|---|---|
| probability density function/ˌprɒbəˈbɪlɪti ˈdensɪti ˈfʌŋkʃn/ | 概率密度函数 | gài lǜ mì dù hán shù |
| cumulative distribution function/ˈkjuːmjʊlətɪv ˌdɪstrɪˈbjuːʃn ˈfʌŋkʃn/ | 累积分布函数 | lěi jī fēn bù hán shù |
| percentiles/pəˈsentaɪlz/ | 百分位数 | bǎi fēn wèi shù |
| median/ˈmiːdiːən/ | 中位数 | zhōng wèi shù |

| 考生应能够: | 注释与示例 |
|---|---|
| 针对来自方差未知的正态总体的小样本,利用t检验制定假设并对总体均值进行假设检验 | |
| 根据两个样本计算总体方差的合并估计值 | 可能需要基于原始数据或汇总数据进行计算。 |
| 针对总体均值之差制定假设,并酌情应用以下方法: - 两样本t检验 - 配对样本t检验 - 使用正态分布的检验 | 要求考生具备根据问题情境选择合适的检验方法的能力。 |
| 针对来自方差未知的正态总体的小样本,利用t分布确定总体均值的置信区间 | |
| 酌情利用t分布或正态分布确定总体均值之差的置信区间。 |
来源:Cambridge International 教学大纲
For an independent random sample from a normal population with unknown variance, base your hypothesis test 假设检验 for the mean on the $t$-distribution. This assumption is especially important for a small sample. The same idea gives a confidence interval 置信区间 for the mean:

Worked example. An independent random sample of $n = 10$ from a normal population has mean $\bar{x} = 50$ and sample standard deviation $s = 4$ (using the $n-1$ divisor). Find a $95\%$ confidence interval for the mean (use $t = 2.262$ for $9$ degrees of freedom).
Worked example: one-sample $t$-test. The same sample is used to test a claim that the population mean is $52$, at the $5\%$ level, assuming the population is normal. $H_0:\mu=52$, $H_1:\mu\neq52$.
The critical values are $\pm2.262$ ($9$ degrees of freedom, two-tailed $5\%$). Since $|-1.58|<2.262$, do not reject $H_0$: there is insufficient evidence that the mean differs from $52$. This agrees with the interval, which contains $52$.
Worked example: two-sample $t$-test with a pooled variance. Two independent samples from normal populations with a common variance: sample A has $n_A=8$, $\bar x_A=24.5$, $s_A^2=4.2$; sample B has $n_B=10$, $\bar x_B=22.1$, $s_B^2=5.0$ (unbiased estimates). Test $H_0:\mu_A=\mu_B$ against $H_1:\mu_A\neq\mu_B$ at the $5\%$ level.
The pooled estimate weights each variance by its degrees of freedom:
With $16$ degrees of freedom the two-tailed $5\%$ critical value is $2.120$. Since $2.35>2.120$, reject $H_0$: there is evidence that the population means differ. The matching $95\%$ confidence interval for $\mu_A-\mu_B$ is $2.4\pm2.120(1.023)$, which is $(0.23,\ 4.57)$, and it excludes $0$.
Worked example: paired $t$-test. Six runners are timed before and after a training plan. The improvements (before minus after, in seconds) are $1.2$, $0.8$, $-0.3$, $1.5$, $0.9$, $0.6$. The same runners appear twice, so work with the differences as one sample: $\bar d=0.783$ and $s_d=0.618$. With $H_0:\mu_d=0$ and $H_1:\mu_d>0$,
The one-tailed $5\%$ critical value for $5$ degrees of freedom is $2.015$. Since $3.11>2.015$, reject $H_0$: there is evidence that the plan improves times, assuming the differences are normally distributed. A two-sample test here would be wrong, because the two sets of times are not independent.
Choosing the test. Same individuals measured twice → paired $t$. Two independent small samples from normal populations with a common variance → pooled two-sample $t$. Large samples (or known variances) → a test using the normal distribution, with $\sqrt{\tfrac{s_A^2}{n_A}+\tfrac{s_B^2}{n_B}}$ for independent large samples. If the population variances are known, use those variances in place of the sample estimates; exact small-sample normal inference also needs normal populations.
当有 $\sigma$ 个未知数时,使用 $t$,且 $t$ 的尾部比正态分布(虚线绘制在其后方)更厚——因此其临界值更大,区间也更宽。在例题的 $9$ 自由度下,小部件读数为 $t^* = 2.262$,正好与上述使用的表值一致。将 df 向上扫过,$t$ 会收敛到正态分布。
阴影尾部以找到概率——置信区间和假设检验的基础。
| English | 中文 | 拼音 |
|---|---|---|
| hypothesis test/haɪˈpɒθəsɪs test/ | 假设检验 | jiǎ shè jiǎn yàn |
| confidence interval/ˈkɒnfɪdəns ˈɪntəvl/ | 置信区间 | zhì xìn qū jiān |
| pooled estimate/puːld ˈestɪmət/ | 合并估计 | hé bìng gū jì |

| 考生应能: | 注释与示例 |
|---|---|
| 根据给定假设,将理论分布拟合到给定数据中 | 试题不涉及繁琐的计算。 |
| 使用具有适当自由度的 $\chi^2$ 检验,进行相应的拟合优度分析 | 应将类别合并,使得每个期望频数至少为 5。 |
| 使用具有适当自由度的 $\chi^2$ 检验,对列联表中的独立性进行检验 | 不需要耶茨校正(Yates' correction)。在适当的情况下,应合并行或列,使得每个单元格中的期望频数至少为 5。 |
来源:Cambridge International 教学大纲
A $\chi^2$-test (chi-squared test 卡方检验) compares observed counts $O$ with expected counts $E$ from a theoretical distribution 理论分布:
Worked example. Four equally likely categories give observed counts $20, 30, 25, 25$ (so each expected count is $25$). Test the fit at the $5\%$ level.
Worked example: fitting a prescribed distribution. $80$ families with three children are counted by number of girls. Test, at the $5\%$ level, whether $B(3,\,0.5)$ fits.
| Girls | $0$ | $1$ | $2$ | $3$ |
|---|---|---|---|---|
| $O$ | $6$ | $28$ | $34$ | $12$ |
| $E=80\times P$ | $80\times\tfrac18=10$ | $80\times\tfrac38=30$ | $30$ | $10$ |
All expected values are at least $5$, so no classes are combined. The degrees of freedom are $4-1=3$ (critical value $7.815$); since $2.67<7.815$, do not reject $B(3,\,0.5)$. If $p$ had been estimated from the data, one more degree of freedom is lost: $\nu=4-1-1=2$.
Worked example: contingency table. $100$ students are classified by course and by whether they passed.
| Pass | Fail | Total | |
|---|---|---|---|
| Course A | $30$ | $20$ | $50$ |
| Course B | $20$ | $30$ | $50$ |
| Total | $50$ | $50$ | $100$ |
Each expected value is $\dfrac{\text{row total}\times\text{column total}}{\text{grand total}}=\dfrac{50\times50}{100}=25$, so
There is $(2-1)(2-1)=1$ degree of freedom, and the $5\%$ critical value is $3.841$. Since $4>3.841$, reject $H_0$: there is evidence that the result is not independent of the course. (Yates' correction is not required in this syllabus.)
本页上的例题给出 $\chi^2 = 2$ 与 $3$ 自由度,对比表值为 $7.815$——该小部件重现了两者。拖动 df 以查看临界值为何随类别数量的变化而变化。
根据观测频数和期望频数做出检验决策。
| English | 中文 | 拼音 |
|---|---|---|
| chi-squared test/kaɪ skweəd test/ | 卡方检验 | kǎ fāng jiǎn yàn |
| theoretical distribution/θɪəˈretɪkl ˌdɪstrɪˈbjuːʃn/ | 理论分布 | lǐ lùn fēn bù |
| degrees of freedom/dɪˈɡriːz ɒv ˈfriːdəm/ | 自由度 | zì yóu dù |
| goodness of fit/ˈɡʊdnəs ɒv fɪt/ | 拟合优度 | nǐ hé yōu dù |
| independence/ˌɪndɪˈpendəns/ | 独立性 | dú lì xìng |
| contingency table/kənˈtɪndʒənsi ˈteɪbl/ | 列联表 | liè lián biǎo |

| 考生应能: | 注释与示例 |
|---|---|
| 理解非参数检验的概念,并了解此类检验适用的场景 | 例如:当从无法假定为正态分布的总体中抽样时。 |
| 理解符号检验、威尔科克森符号秩检验和威尔科克森秩和检验的原理 | 包括知晓威尔科克森检验仅适用于对称分布。 |
| 运用单样本符号检验和单样本威尔科克森符号秩检验对总体中位数进行假设检验 | 包括在适当情况下使用正态近似法。试题不会涉及结(tied ranks)或与待检验总体中位数相等的观测值。 |
| 根据情况选用配对样本符号检验、威尔科克森配对符号秩检验及威尔科克森秩和检验来检验总体的一致性 | 包括在适当情况下使用正态近似法。试题不会涉及结或差值为零的配对。 |
来源:Cambridge International 教学大纲
A non-parametric test 非参数检验 does not require a normal population, but still has sampling assumptions; the signed-rank test also needs a symmetric distribution of differences to test its centre. The basic ones are:
Worked example. Test whether a median is $5$. In a sample of $10$ values (none equal to $5$), $9$ lie above $5$ and $1$ lies below. Test at the $5\%$ level (two-tailed).
Under $H_0$ (median $= 5$) the number above follows $B(10, 0.5)$. The observed result ($9$ above) is extreme, so find $P(X \geq 9) = \binom{10}{9}(0.5)^{10} + (0.5)^{10} = \dfrac{11}{1024} = 0.0107$. For a two-tailed test compare with $\tfrac{1}{2}(5\%) = 0.025$. Since $0.0107 < 0.025$, reject $H_0$: there is evidence the median is not $5$.
Worked example: Wilcoxon signed-rank test. A machine is set so that the median mass of a bag is $20$ g. Eight bags have masses $23.1$, $18.4$, $26.0$, $21.7$, $19.5$, $27.3$, $24.8$, $22.2$ g. Test at the $5\%$ level whether the median is greater than $20$ g, assuming the distribution is symmetric.
Subtract $20$, then rank the differences by size, ignoring sign:
| Difference | $-0.5$ | $-1.6$ | $1.7$ | $2.2$ | $3.1$ | $4.8$ | $6.0$ | $7.3$ |
|---|---|---|---|---|---|---|---|---|
| Rank | $1$ | $2$ | $3$ | $4$ | $5$ | $6$ | $7$ | $8$ |
The sum of the negative ranks is $P_-=1+2=3$; the positive ranks sum to $36-3=33$. Under $H_1$ (median $>20$) negative differences should be rare, so the test statistic is $T=3$. For $n=8$ the one-tailed $5\%$ critical value is $5$, and $3\leqslant5$, so reject $H_0$: there is evidence that the median mass is above $20$ g. A sign test on the same data ($6$ of $8$ above) gives $P(X\geqslant6)=0.145$ and would not reject: using the sizes can give the Wilcoxon test greater power under its symmetry assumption; this one sample does not establish a general power comparison.
For $n$ larger than the tables, a sum of positive ranks (or a sum of negative ranks) has the following approximate normal distribution under the null, when there are no zero differences or tied absolute differences. Use a continuity correction; ties need adjusted variance. The minimum of both rank sums is not itself distributed this way:
Worked example: Wilcoxon rank-sum test. Two independent samples of reaction times (ms). A: $12$, $15$, $18$, $21$, $25$. B: $14$, $19$, $22$, $26$, $28$, $30$. Test at the $5\%$ level (two-tailed) whether the populations are identical.
Rank all $11$ values together: $12(1)$, $14(2)$, $15(3)$, $18(4)$, $19(5)$, $21(6)$, $22(7)$, $25(8)$, $26(9)$, $28(10)$, $30(11)$. The smaller sample is A ($m=5$, $n=6$); its rank sum is $R_m=1+3+4+6+8=22$. Also find $m(m+n+1)-R_m=5(12)-22=38$, and take the smaller: $W=22$.
For $m=5$, $n=6$ the two-tailed $5\%$ critical value is $18$. Since $22>18$, do not reject $H_0$: there is insufficient evidence of a difference between the populations.
选择与数据情况匹配的基于秩的检验。
| English | 中文 | 拼音 |
|---|---|---|
| non-parametric test/nɒn ˌpærəˈmetrɪk test/ | 非参数检验 | fēi cān shù jiǎn yàn |
| sign test/saɪn test/ | 符号检验 | fú hào jiǎn yàn |
| Wilcoxon signed-rank test/ˈwɪlkɒksn saɪnd ræŋk test/ | 威尔科克森符号秩检验 | wēi ěr kē kè sēn fú hào zhì jiǎn yàn |
| Wilcoxon rank-sum test/ˈwɪlkɒksn ræŋk sʌm test/ | 威尔科克森秩和检验 | wēi ěr kē kè sēn zhì hé jiǎn yàn |

| 考生应能: | 注释与示例 |
|---|---|
| 理解概率生成函数(PGF)的概念,并为给定分布构造和使用 PGF | 包括离散均匀分布、二项分布、几何分布和泊松分布。 |
| 使用以 PGF 表示的离散随机变量的均值和方差公式,并利用这些公式计算给定概率分布的均值和方差 | |
| 利用“独立随机变量之和的概率生成函数等于各随机变量概率生成函数的乘积”这一结论。 |
来源:Cambridge International 教学大纲
The probability generating function 概率母函数 of a non-negative integer-valued variable $X$ is
Worked example. $X$ has $P(X=0) = 0.5$, $P(X=1) = 0.3$, $P(X=2) = 0.2$. Find $E(X)$ using the PGF.
Here $G(t) = 0.5 + 0.3t + 0.2t^2$, so $G'(t) = 0.3 + 0.4t$ and
Differentiate again for the variance: $G''(t)=0.4$, so
(Check directly: $E(X^2)=0.3+0.8=1.1$ and $1.1-0.7^2=0.61$.)
Standard PGFs (with $q=1-p$): discrete uniform on $1,\dots,n$: $\dfrac{t(1-t^n)}{n(1-t)}$; binomial $B(n,p)$: $(q+pt)^n$; geometric $\mathrm{Geo}(p)$ on $1,2,\dots$: $\dfrac{pt}{1-qt}$; Poisson $\mathrm{Po}(\lambda)$: $e^{\lambda(t-1)}$.
Worked example: Poisson mean and variance. For $G(t)=e^{\lambda(t-1)}$: $G'(t)=\lambda e^{\lambda(t-1)}$ and $G''(t)=\lambda^2 e^{\lambda(t-1)}$, so $G'(1)=\lambda$ and $G''(1)=\lambda^2$. Then $E(X)=\lambda$ and $\mathrm{Var}(X)=\lambda^2+\lambda-\lambda^2=\lambda$.
Worked example: sum of independent variables. $X_1$ and $X_2$ are independent copies of the variable above. The PGF of $Y=X_1+X_2$ is the product:
So, for example, $P(Y=2)=0.29$: the $t^2$ coefficient collects $0.5\times0.2$ twice and $0.3\times0.3$ once. The coefficients add to $1$, a quick check.
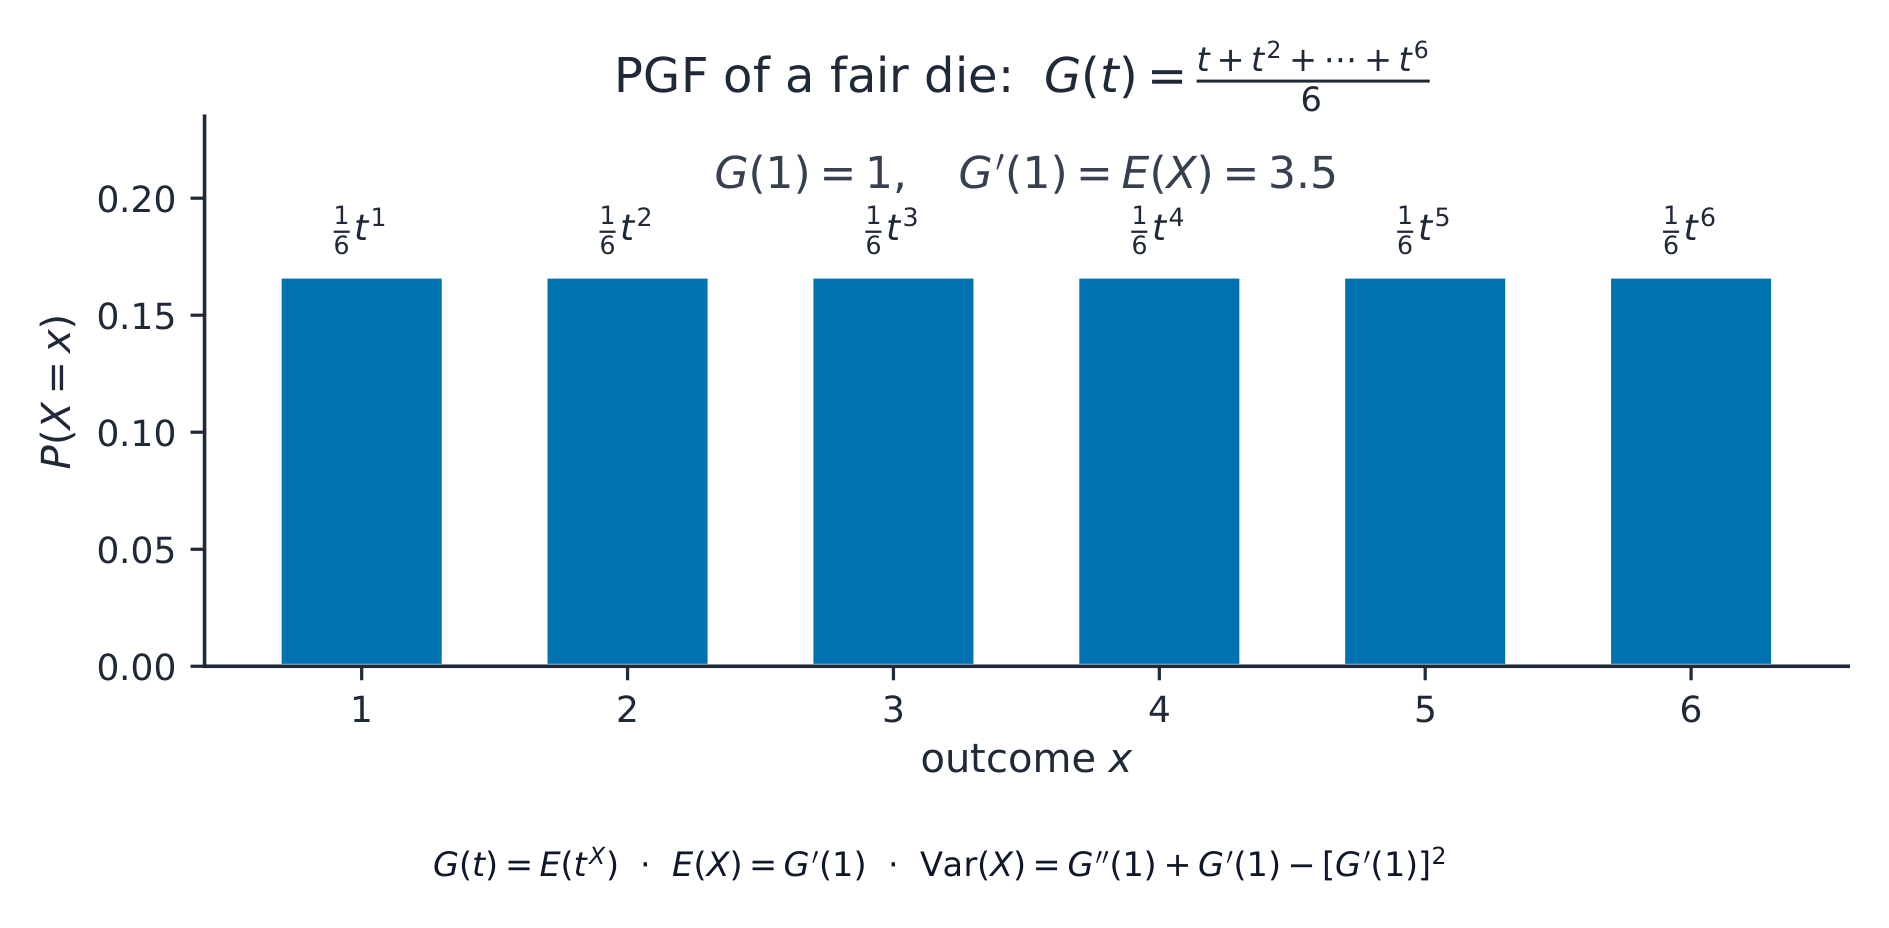
G(x) = p0 + p1 x + p2 x^2 + ...
改变 x 并观察 PGF 如何将概率存储在 x 的幂次中。
| English | 中文 | 拼音 |
|---|---|---|
| probability generating function/ˌprɒbəˈbɪlɪti ˈdʒenəreɪtɪŋ ˈfʌŋkʃn/ | 概率母函数 | gài lǜ mǔ hán shù |
| Further Probability & Statistics/ˈfɜːðə ˌprɒbəˈbɪlɪti ænd stəˈtɪstɪks/ | 进阶概率统计 | jìn jiē gài lǜ tǒng jì |
逐步完成,配合即时检查练习。
正在加载学科…