| English | 意味 |
|---|---|
| Unicode/ˈjuːnɪkəʊd/ | ユニコード |
| character set/ˈkærɪktə set/ | 文字集合 |
| ASCII/ˈæski/ | ASCIIコード |
| encoding/enˈkəʊdɪŋ/ | エンコーディング |
| code point/kəʊd pɔɪnt/ | コードポイント |
| UTF-8/ˌjuː tiː ˈef eɪt/ | UTF-8符号体系 |
The email that arrived as gibberish
- Through the 1990s, a message typed in Warsaw and read in Tokyo often arrived as a wall of nonsense. Both computers stored eight bits per character. They simply disagreed about what the top 128 patterns meant.
- Poland's code page put Polish letters there. Japan's put its own characters there. Nothing was corrupted in transit: the bytes arrived intact and were read against a different table.
- The fix was to stop having tables per country and give every character in every script one number, for ever. That is Unicode 统一码, and it is why the emoji you send arrives as the same picture.
- This lesson is how text becomes numbers: character sets 字符集, ASCII, Unicode, and the encodings that store them.
A character set gives each character a number
- A computer stores no letters, only numbers. A character set is the set of characters a computer can represent, each with its own binary code.
- The number for one character is its code point 码点.
Ais 65,ais 97,0the digit is 48. - The code point is not the character's meaning; it is an agreed label. Text is readable only because both machines use the same character set.
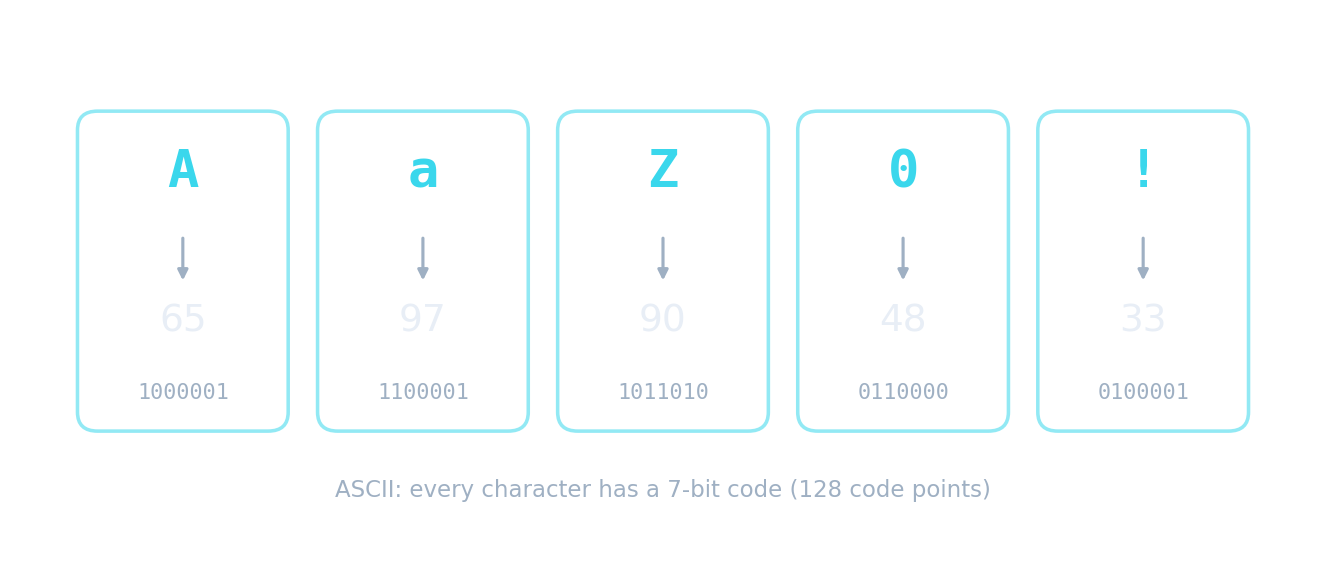
The letter is the picture; the byte is the number
A character is stored as a number
Each character has a code number — 'A' is 65. Flip the bits to see that code in binary and hex, exactly how the computer holds it.
A character set such as ASCII defines:
難易度 1/5 · 100 コイン + 今日初回完了時に小ボーナス付与
A character set maps each character to a number (its code point), which is what the computer actually stores.
ASCII
- ASCII ASCII码, the American Standard Code for Information Interchange, uses 7 bits, giving $2^7 = 128$ code points: the basic Latin letters, digits, punctuation, and 32 control codes such as carriage return.
- Extended ASCII uses 8 bits, giving 256 code points. The lower 128 are identical to ASCII; the upper 128 vary by region, which is exactly what broke that email.
- You are never asked to memorise a code, but you are asked for the counts: 7 bits, 128; 8 bits, 256.
How many different code points does 7-bit ASCII have?
難易度 2/5 · 140 コイン + 今日初回完了時に小ボーナス付与
7 bits give $2^7 = 128$ code points.
How many different code points does extended ASCII have?
難易度 2/5 · 140 コイン + 今日初回完了時に小ボーナス付与
Eight bits give 2^8 = 256. The lower 128 match plain 7-bit ASCII; the upper 128 vary by region.
Unicode
- Unicode is a universal character set: one code point for almost every character in every script alive or dead, plus symbols and emoji, over 149,000 of them.
- The code point is separate from how it is stored. An encoding 编码 turns a code point into bytes.
- UTF-8 UTF-8编码 uses 1 to 4 bytes per character and is ASCII-compatible: the first 128 code points are one byte, identical to ASCII. UTF-16 uses 2 or 4 bytes; UTF-32 uses a fixed 4.
Which is true of UTF-8?
難易度 1/5 · 100 コイン + 今日初回完了時に小ボーナス付与
UTF-8 is a variable-length Unicode encoding (1–4 bytes); its first 128 code points match ASCII, so plain ASCII text is valid UTF-8.
What is the relationship between Unicode and UTF-8?
難易度 1/5 · 100 コイン + 今日初回完了時に小ボーナス付与
The set assigns the numbers; the encoding decides how many bytes each number takes. UTF-16 and UTF-32 are other encodings of the same set.
Worked example: compare ASCII and Unicode
- Give one advantage and one disadvantage of using Unicode instead of ASCII. [2]
- Advantage: Unicode represents far more characters, so text in any script, Chinese, Arabic, Greek, and emoji can be stored, and a single document can mix languages; files are portable because there is no per-country code page to disagree about.
- Disadvantage: for English-only text a Unicode file is usually larger, because a character may take more than one byte.
- Both halves are needed. "It has more characters" alone is one mark of two.
A key advantage of Unicode over ASCII is that it:
難易度 1/5 · 100 コイン + 今日初回完了時に小ボーナス付与
Unicode covers nearly every writing system plus symbols and emoji — far beyond ASCII's basic English set.
For English-only text, a Unicode file is usually larger than the same text in ASCII.
難易度 1/5 · 100 コイン + 今日初回完了時に小ボーナス付与
Unicode encodings can use more bytes per character, so plain English text is usually larger than in 7-bit ASCII — the trade-off for universal coverage.
Which are advantages of Unicode over ASCII? Select all that apply.
難易度 2/5 · 140 コイン + 今日初回完了時に小ボーナス付与
Size is the trade-off, not a benefit: for plain English a Unicode file is usually larger.
Worked example: the size of a text file
- A message of 500 characters is stored in extended ASCII. How large is the file in bytes?
- Extended ASCII uses 8 bits, one byte, per character, so $500 \times 1 = 500$ bytes, or $500 \times 8 = 4000$ bits.
- The same message in UTF-32? Four bytes per character, so 2000 bytes.
- Show the bits-per-character, multiply, then convert once. Mixing bits and bytes halfway through is the usual lost mark.
A 500-character message is stored in extended ASCII. How many bytes does it need (ignore any header)?
難易度 2/5 · 140 コイン + 今日初回完了時に小ボーナス付与
Eight bits, one byte, per character: 500 x 1 = 500 bytes, or 4000 bits. In UTF-32 the same text needs 2000 bytes.
Reading a character in binary and hex
- Because a code point is just a number, it converts like any other.
Ais 65, which is0100 0001in binary and41in hexadecimal. - Two useful patterns: the digits
0to9run from 48, and lower case is 32 more than upper case, soa(97) isA(65) plus 32. That difference is a single bit. - A question that gives you
A= 65 and asks forEwants $65 + 4 = 69$, not a memorised table.
The ASCII code for A is 65. What is the ASCII code for E?
難易度 1/5 · 100 コイン + 今日初回完了時に小ボーナス付与
The letters are consecutive, so E is four after A. Nothing has to be memorised beyond one anchor value.
Marks that slip away
- ASCII is 7 bits and 128 code points; extended ASCII is 8 bits and 256. Do not write 8 bits for plain ASCII.
- Unicode is a character set; UTF-8 is an encoding of it. They are not two rival sets.
- UTF-8 is variable length, 1 to 4 bytes, not always one byte and not always four.
- The disadvantage of Unicode is file size for plain English, not "it is slower" or "it is harder to read".
You've got it
- a character set gives each character a code point; text is numbers plus an agreement about how to read them
- ASCII: 7 bits, 128 code points, English only · extended ASCII: 8 bits, 256, the top half varies by region
- Unicode: one code point for every script and emoji, stored by an encoding; UTF-8 is 1 to 4 bytes and ASCII-compatible
- Unicode gains characters, portability and mixed languages; it costs file size on plain English text